Learning to Branch
Maria-Florina Balcan, Travis Dick, Tuomas Sandholm, and Ellen Vitercik

TL;DR
This paper introduces a machine learning approach to optimize tree search algorithms by learning the best combination of partitioning procedures, significantly reducing tree size and improving efficiency with theoretical guarantees.
Contribution
It presents the first theoretical sample complexity guarantees for tree search algorithm configuration and demonstrates a practical learning method to optimize branching.
Findings
Learning optimal partitioning weights reduces tree size dramatically.
The reduction in tree size can be exponential.
The approach is both theoretically sound and practically effective.
Abstract
Tree search algorithms, such as branch-and-bound, are the most widely used tools for solving combinatorial and nonconvex problems. For example, they are the foremost method for solving (mixed) integer programs and constraint satisfaction problems. Tree search algorithms recursively partition the search space to find an optimal solution. In order to keep the tree size small, it is crucial to carefully decide, when expanding a tree node, which question (typically variable) to branch on at that node in order to partition the remaining space. Numerous partitioning techniques (e.g., variable selection) have been proposed, but there is no theory describing which technique is optimal. We show how to use machine learning to determine an optimal weighting of any set of partitioning procedures for the instance distribution at hand using samples from the distribution. We provide the first sample…
Click any figure to enlarge with its caption.
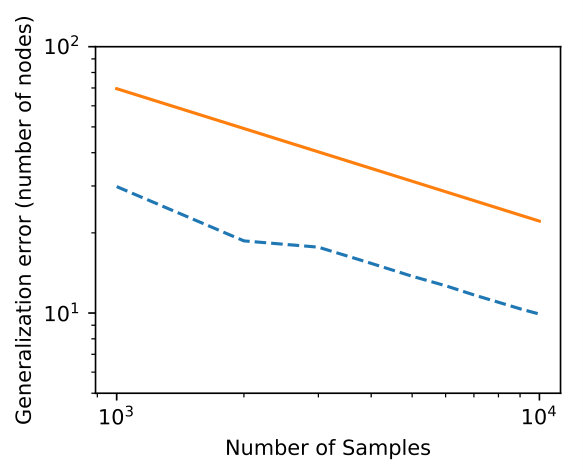 Figure 1
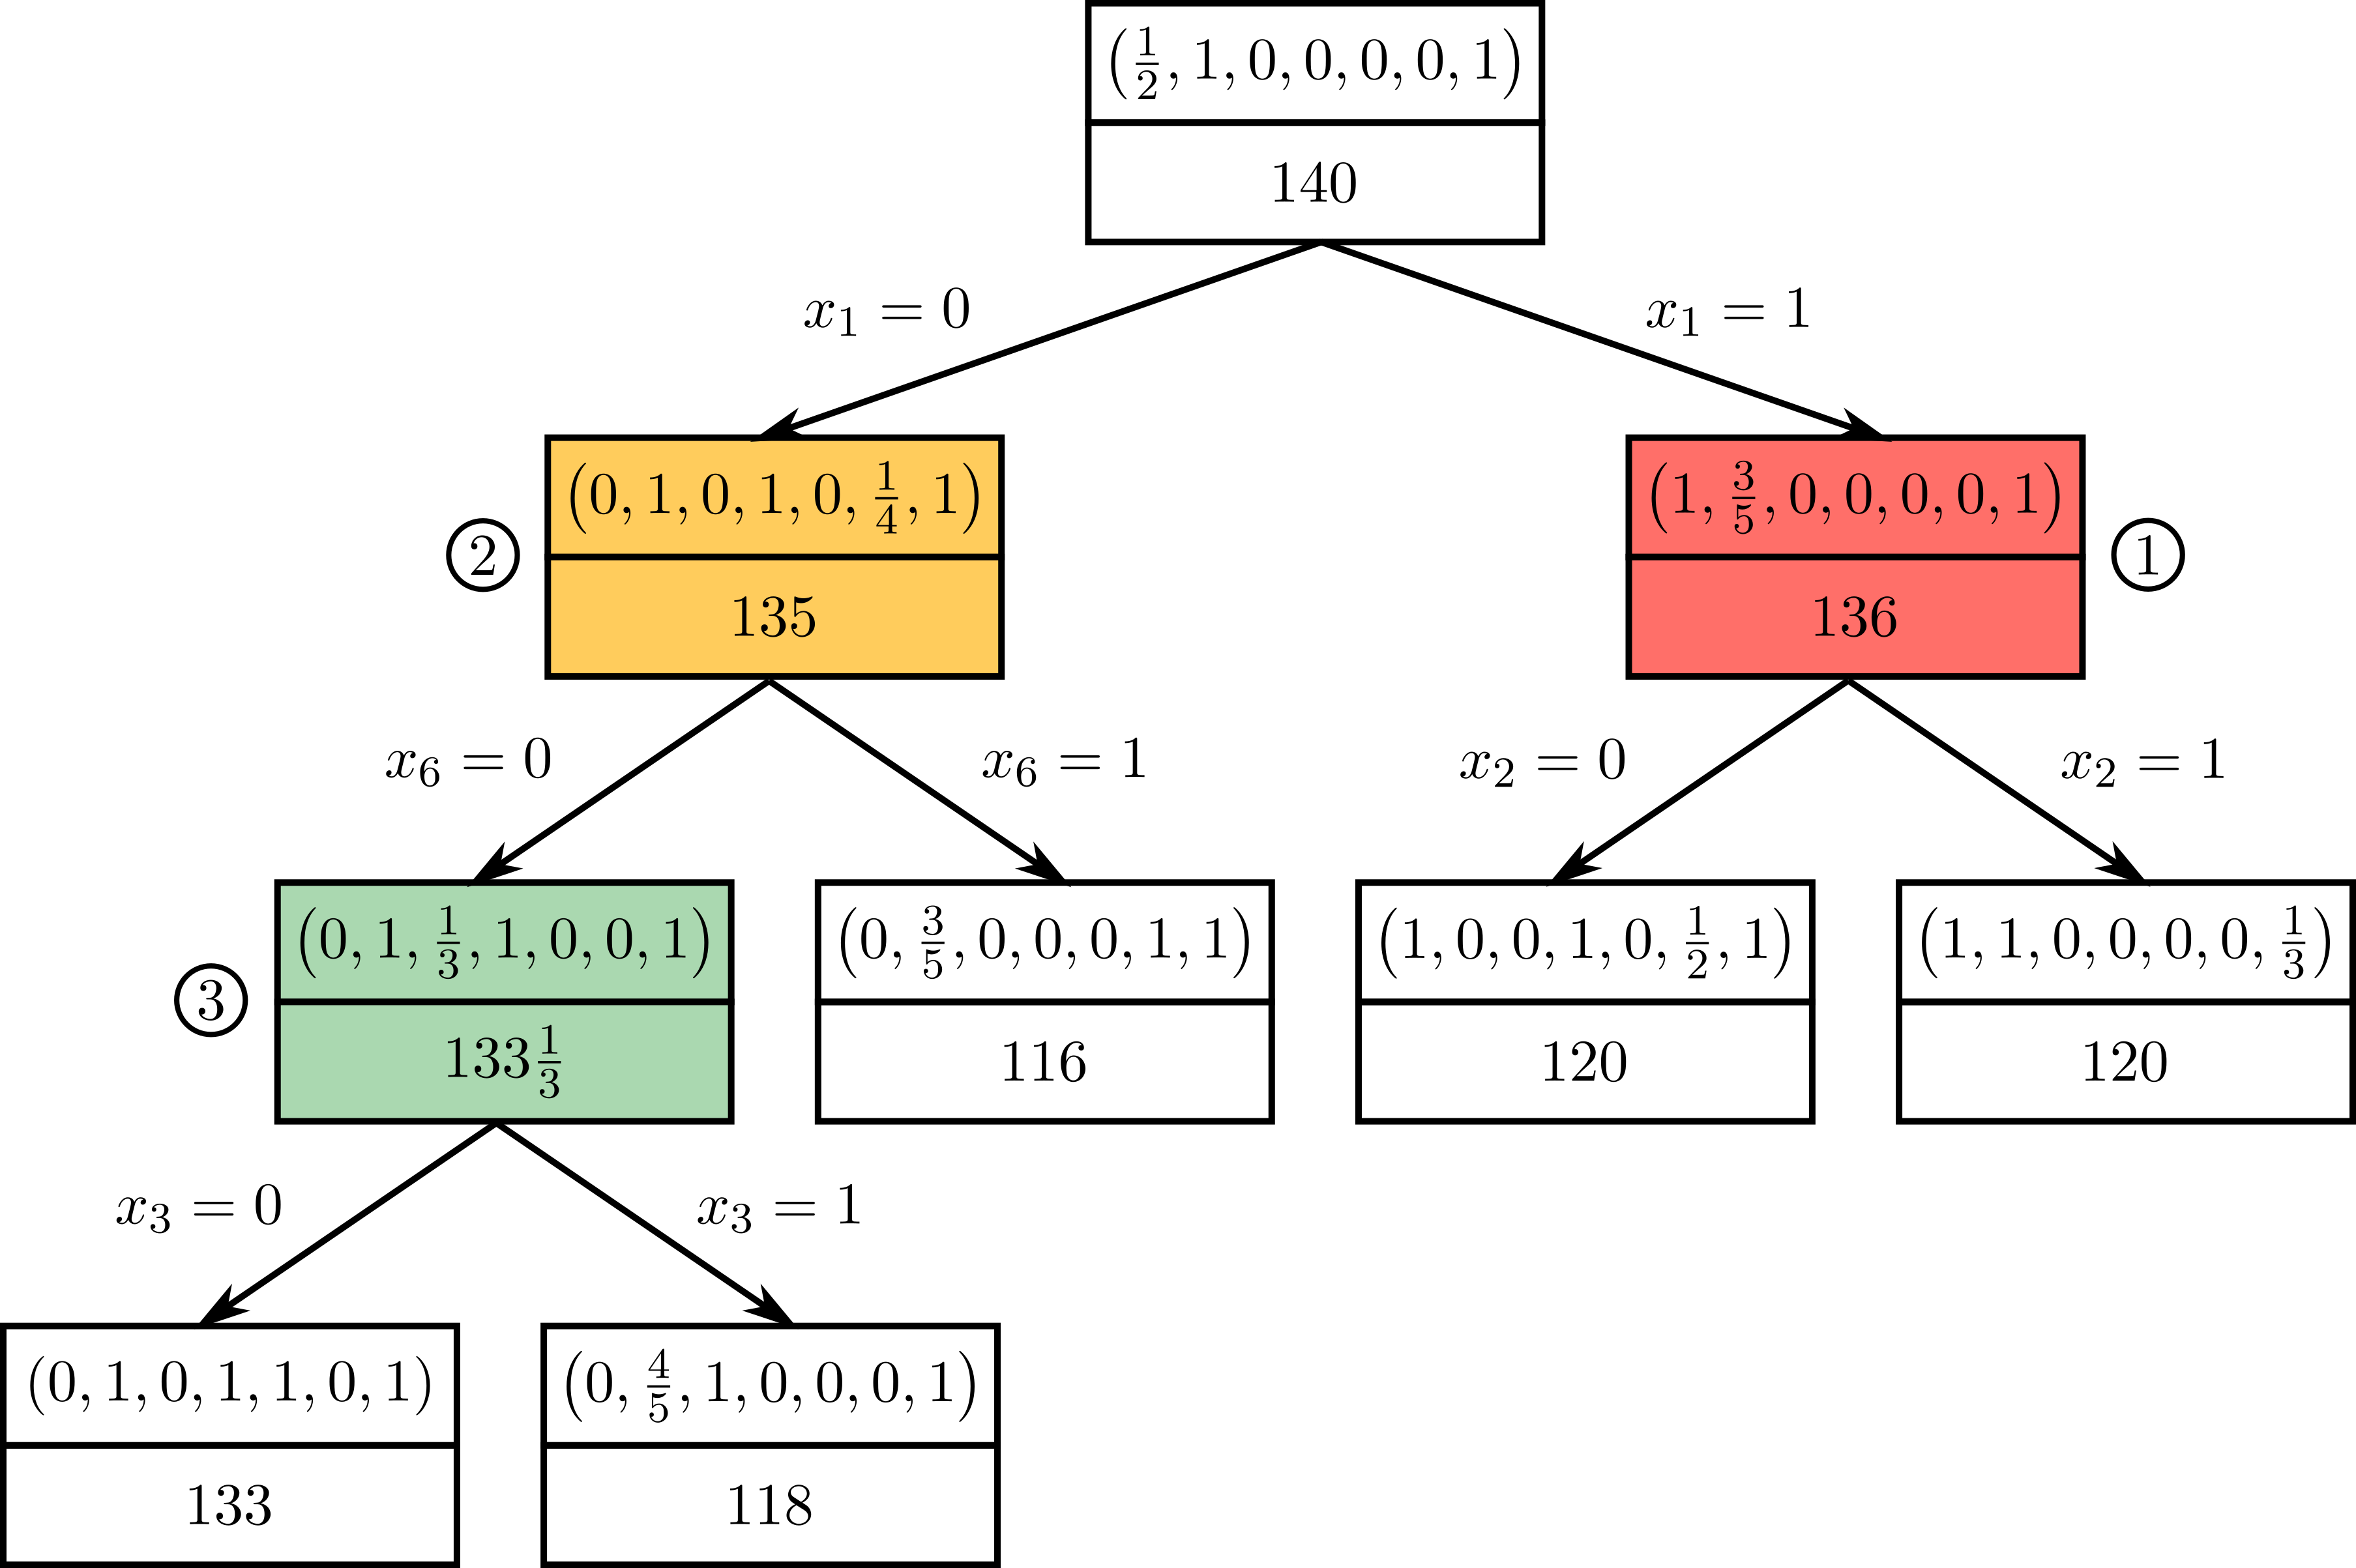 Figure 2
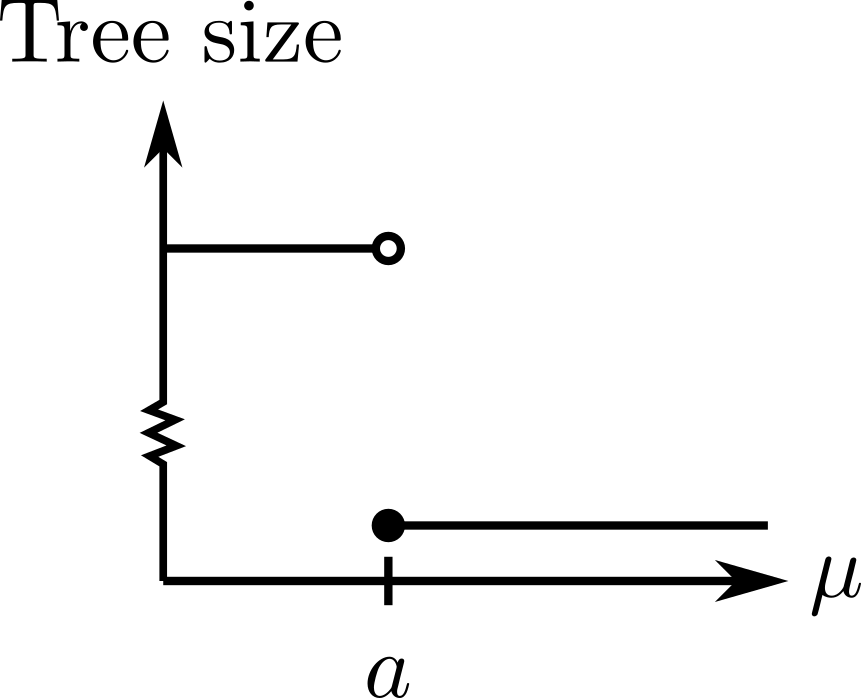 Figure 3
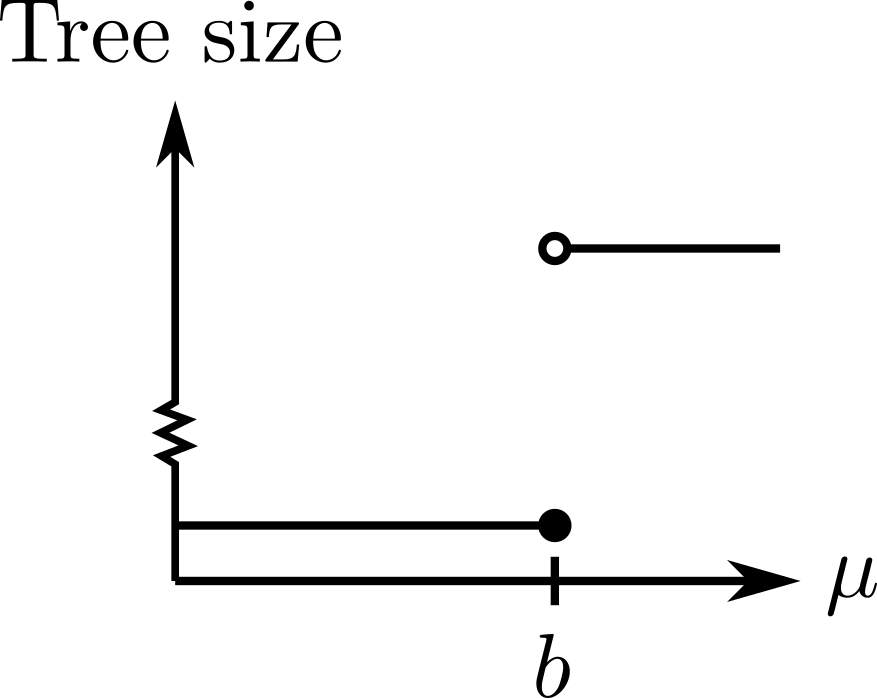 Figure 4
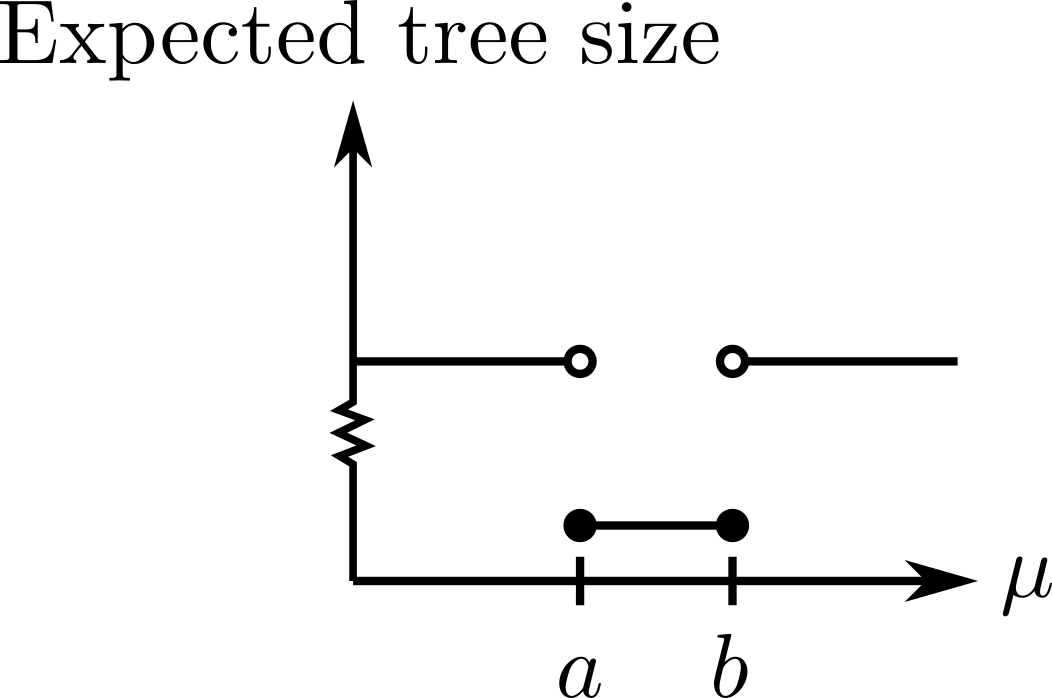 Figure 5
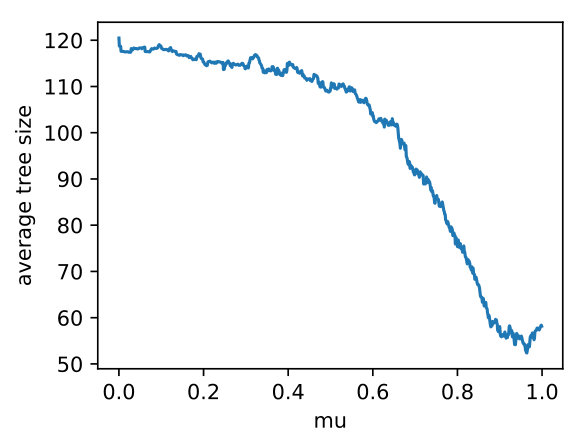 Figure 6
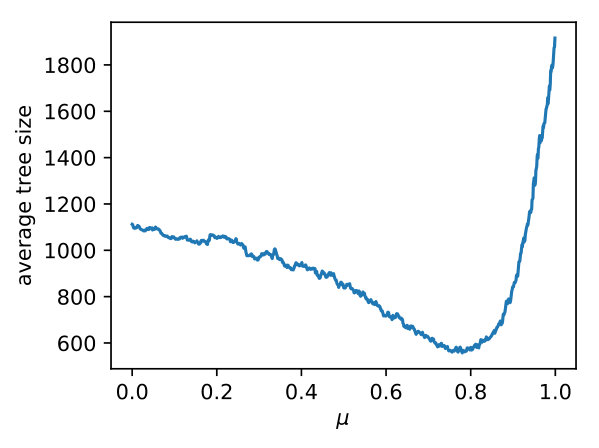 Figure 7
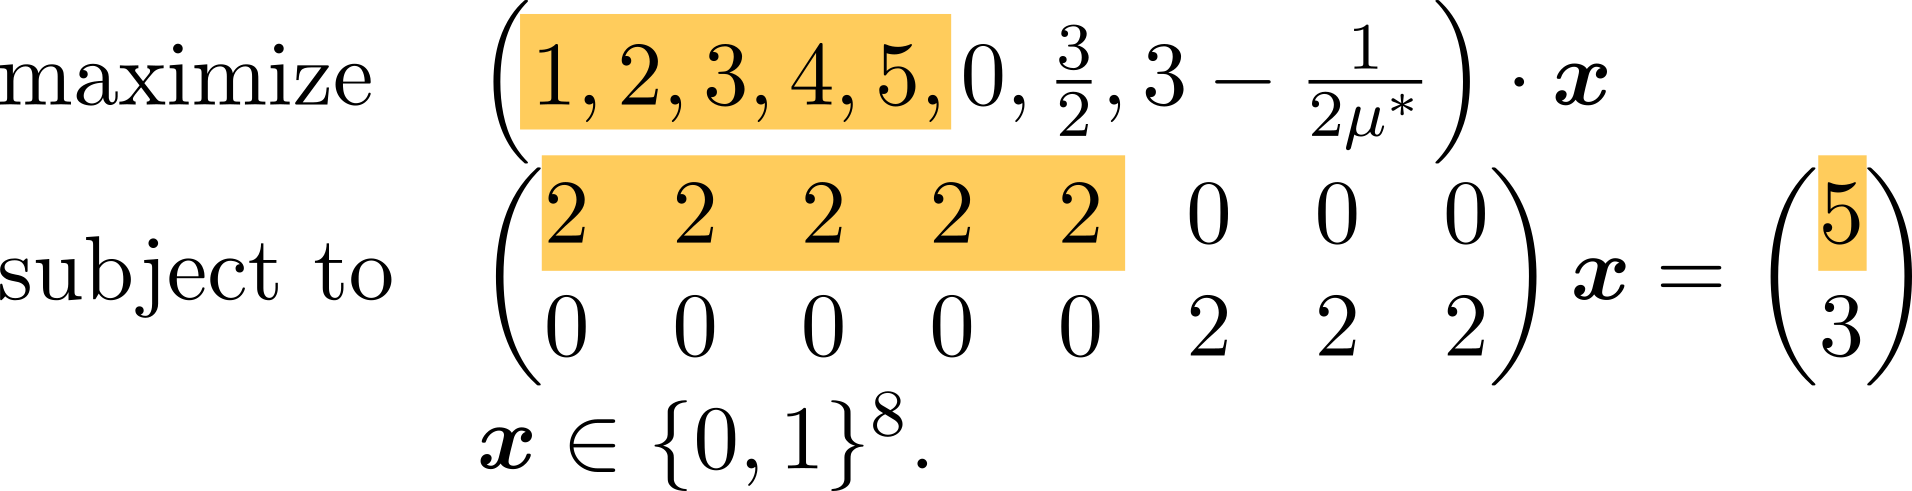 Figure 8
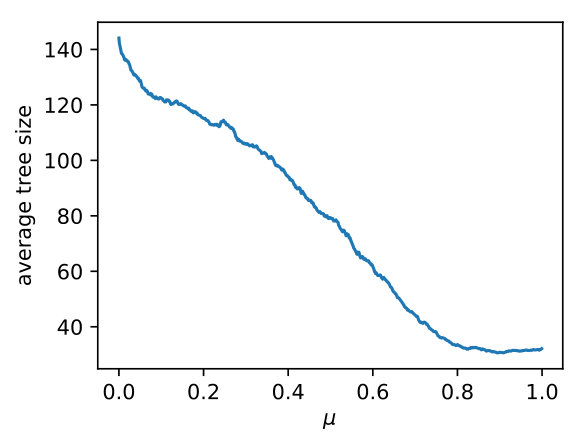 Figure 9
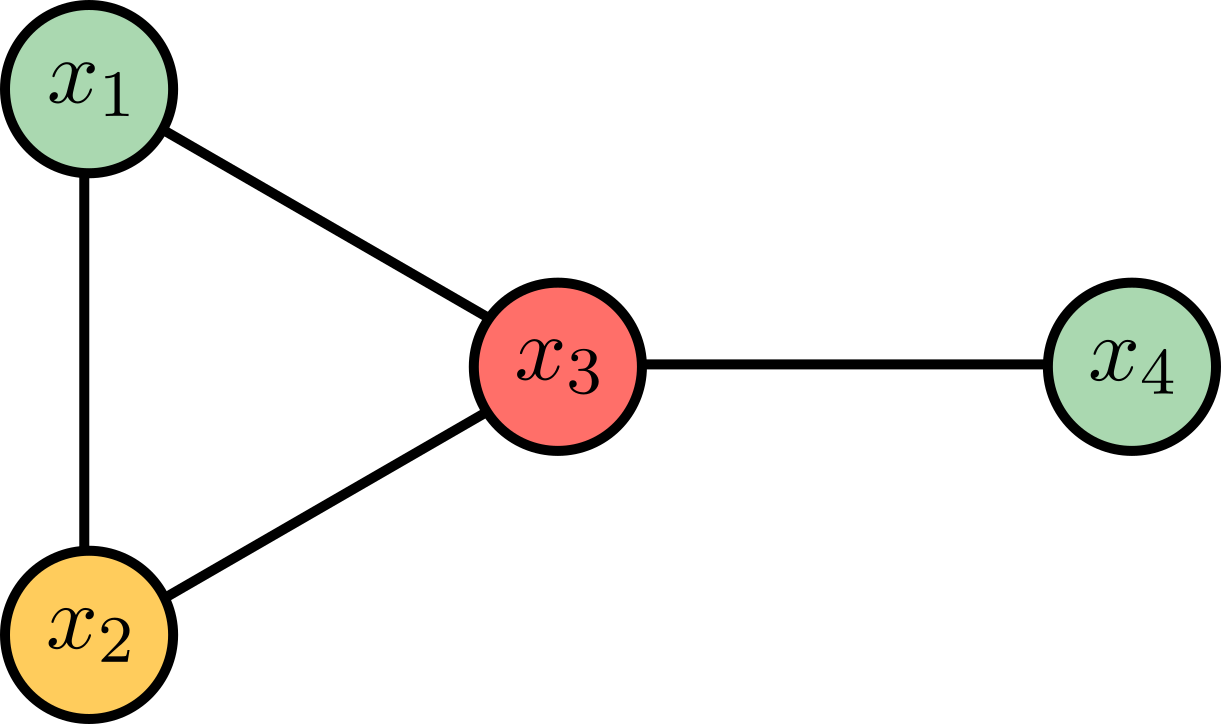 Figure 10
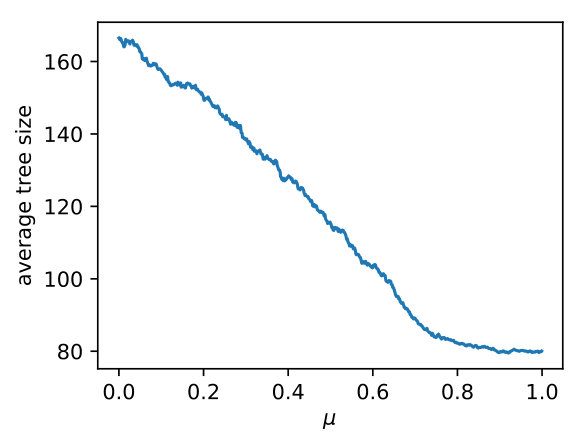 Figure 11
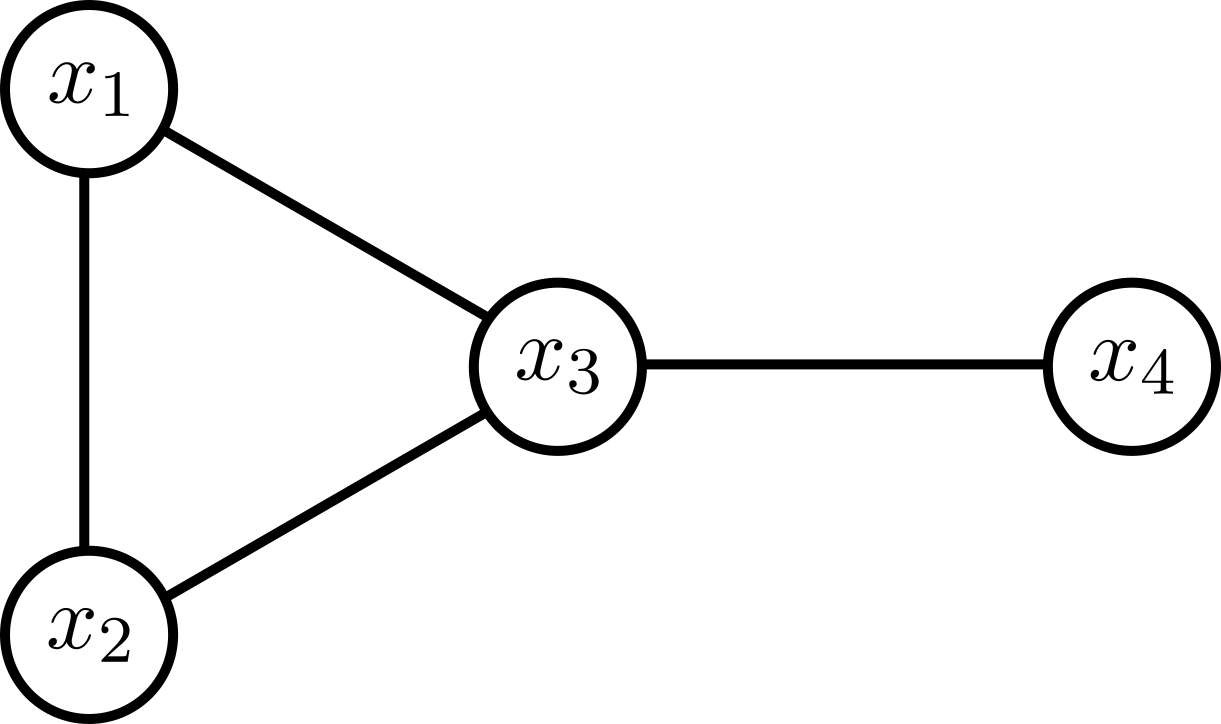 Figure 12
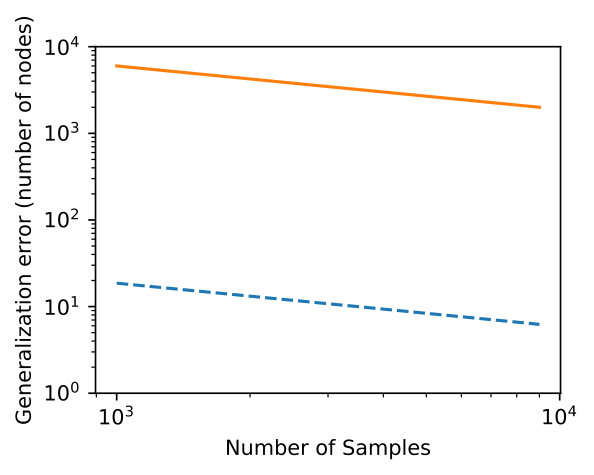 Figure 13
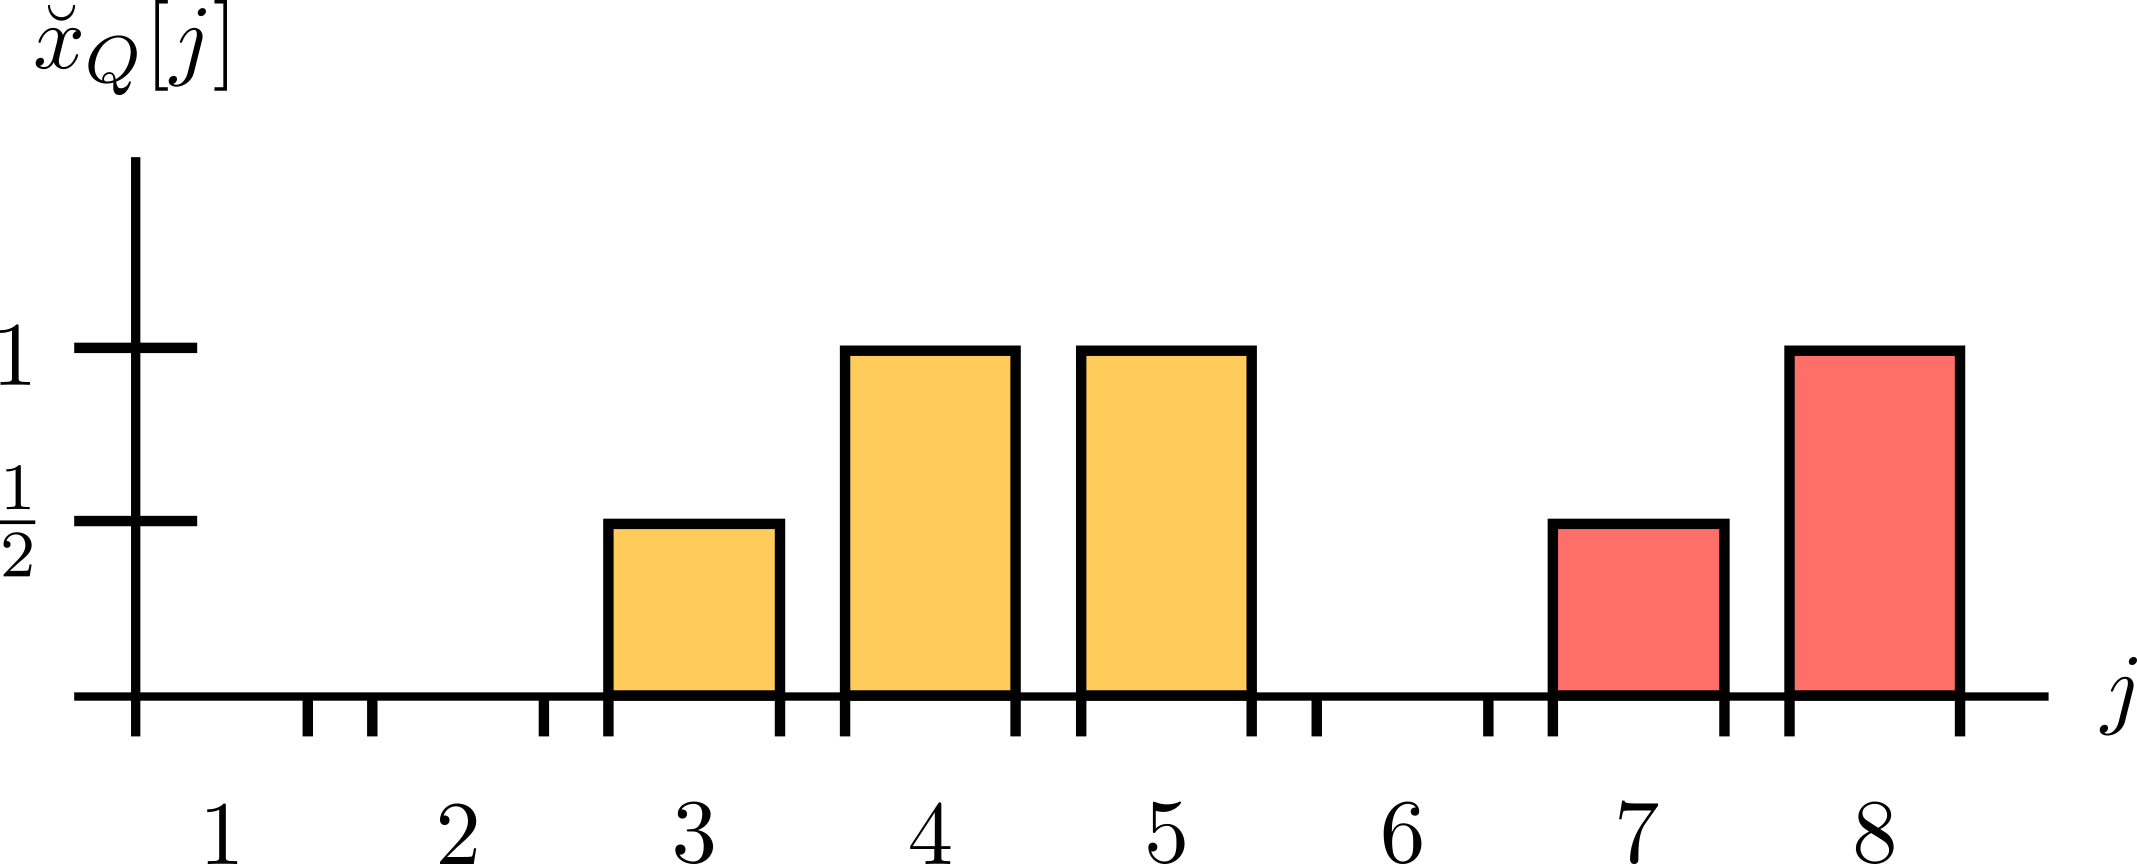 Figure 14
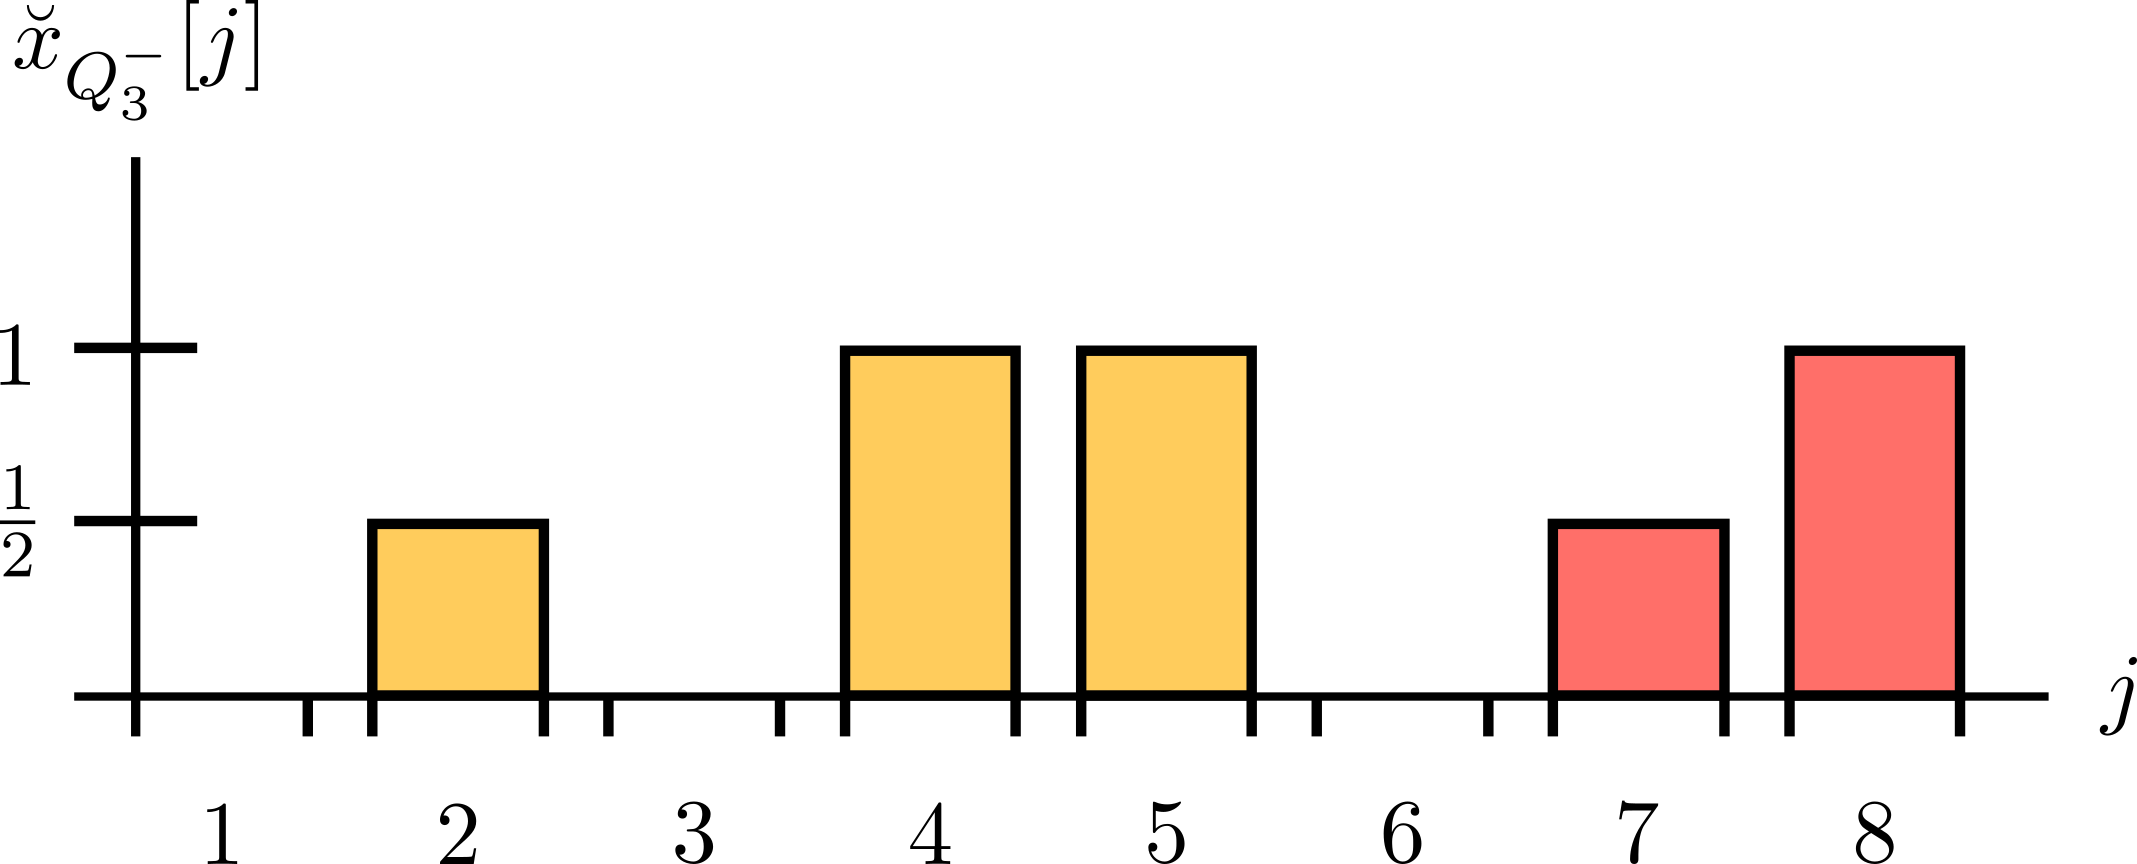 Figure 15
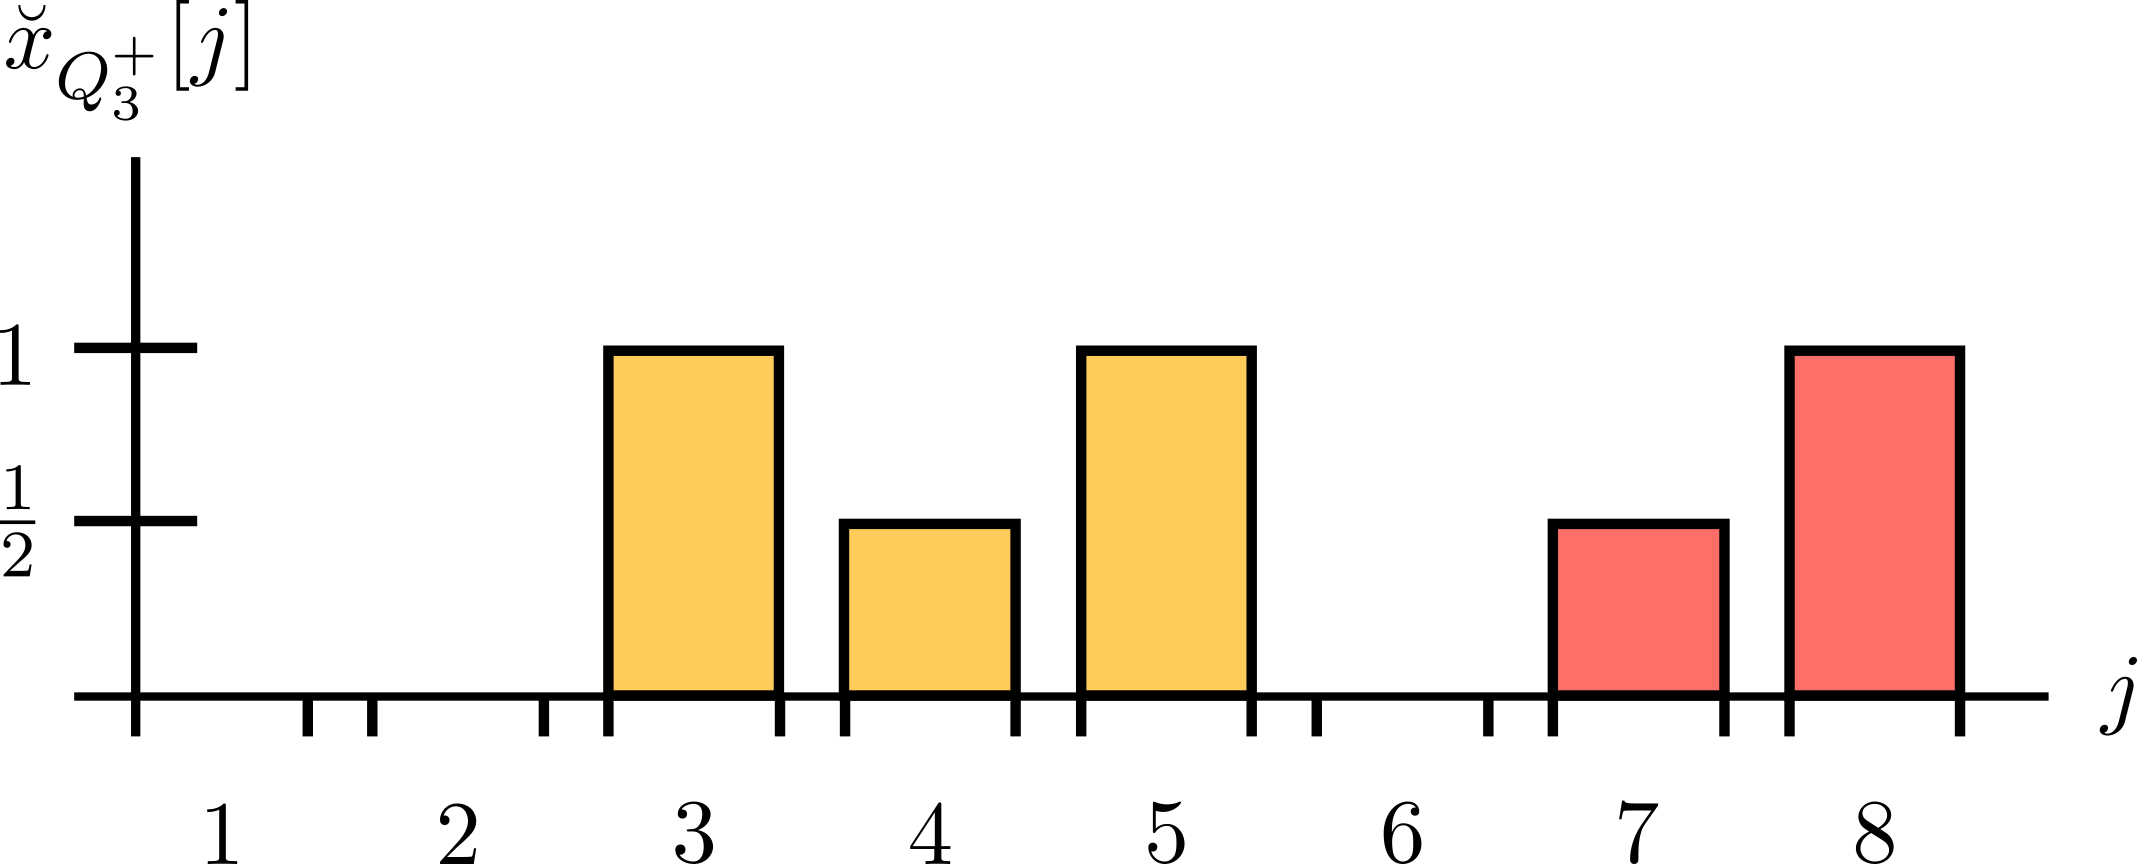 Figure 16
 Figure 17
 Figure 18
 Figure 19
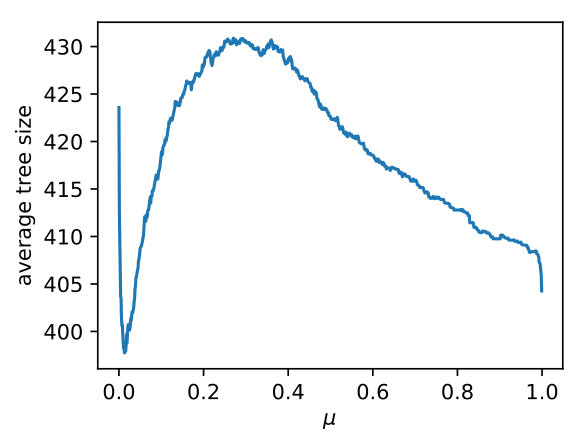 Figure 20
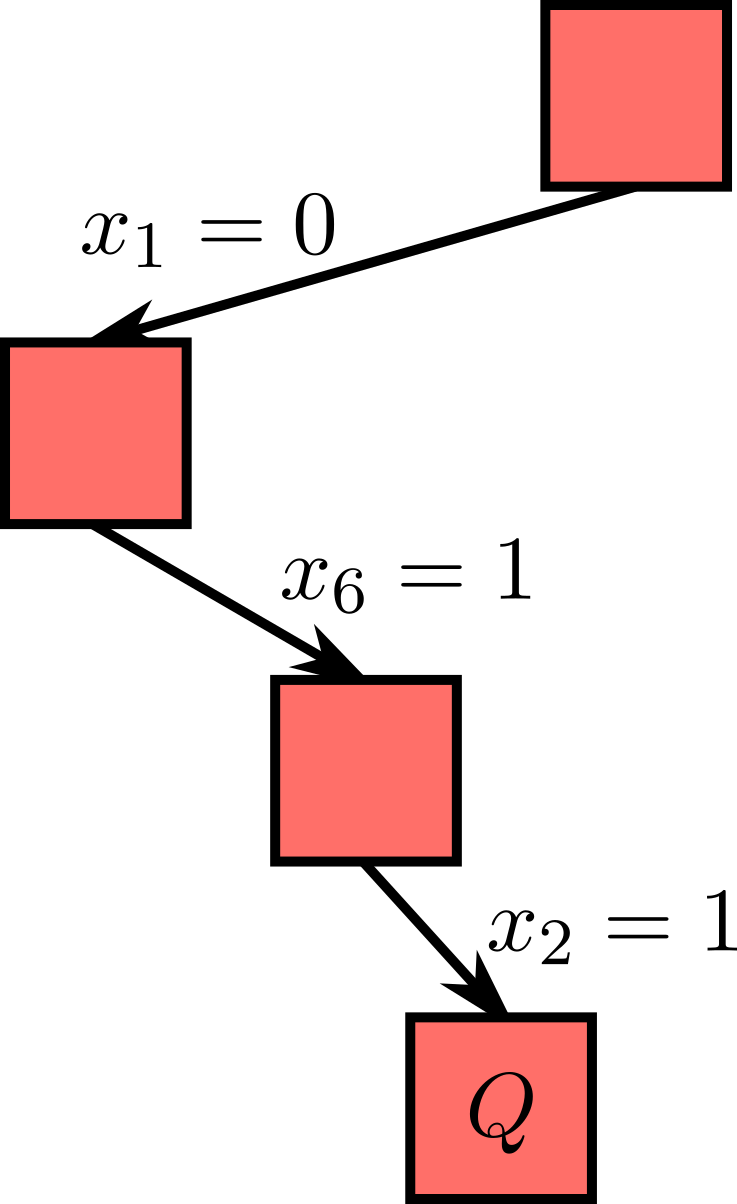 Figure 21
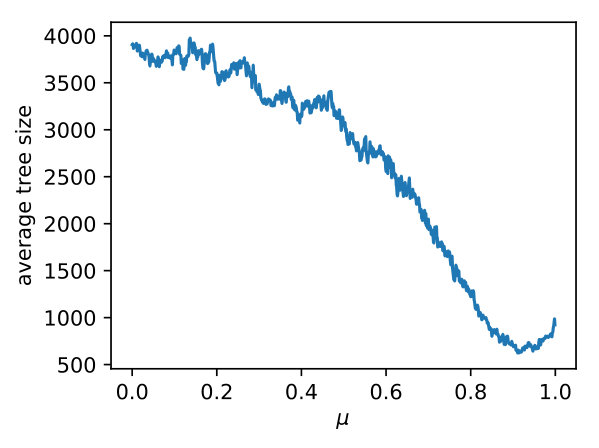 Figure 22
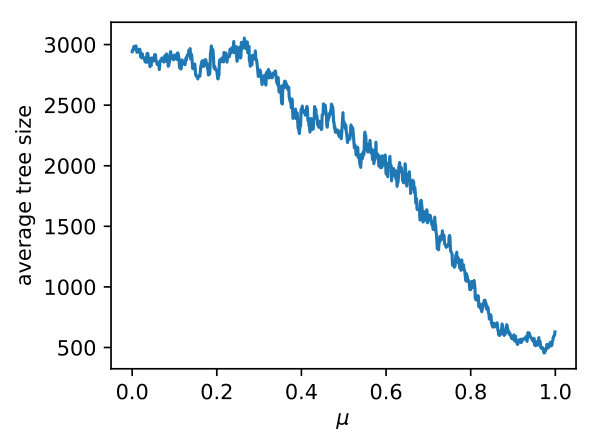 Figure 23
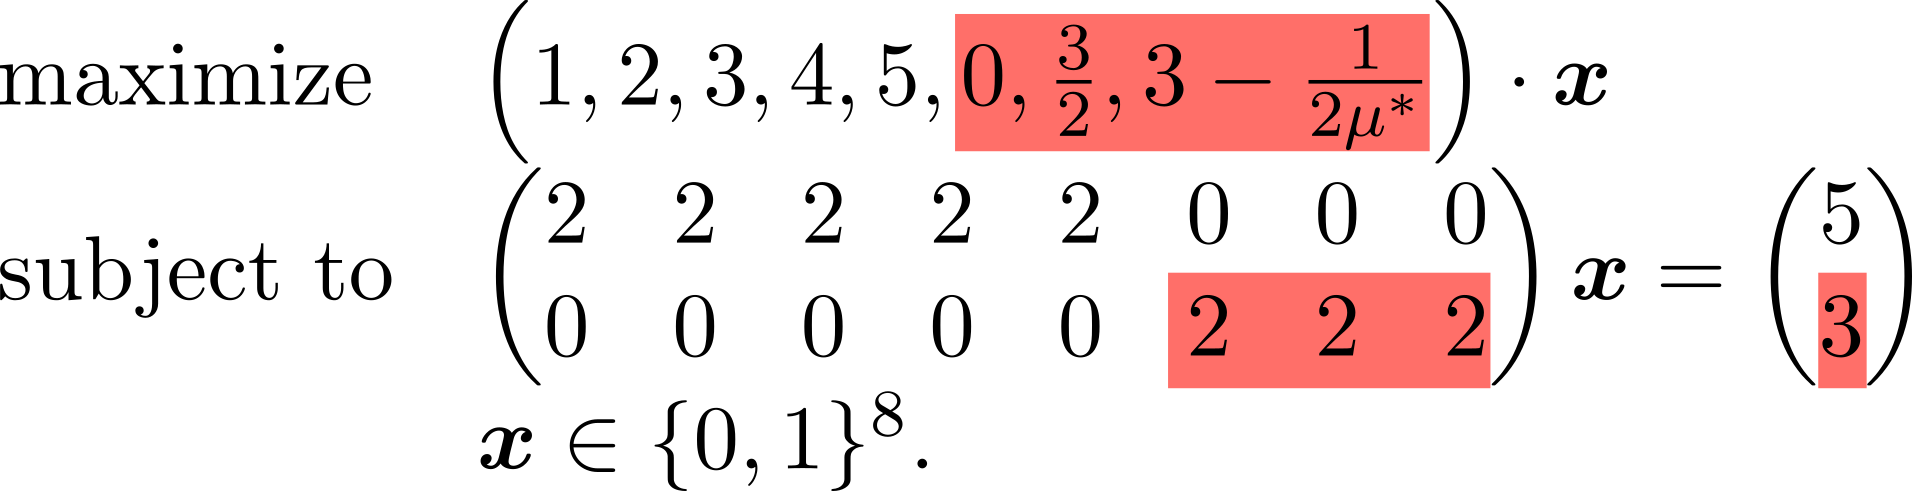 Figure 24
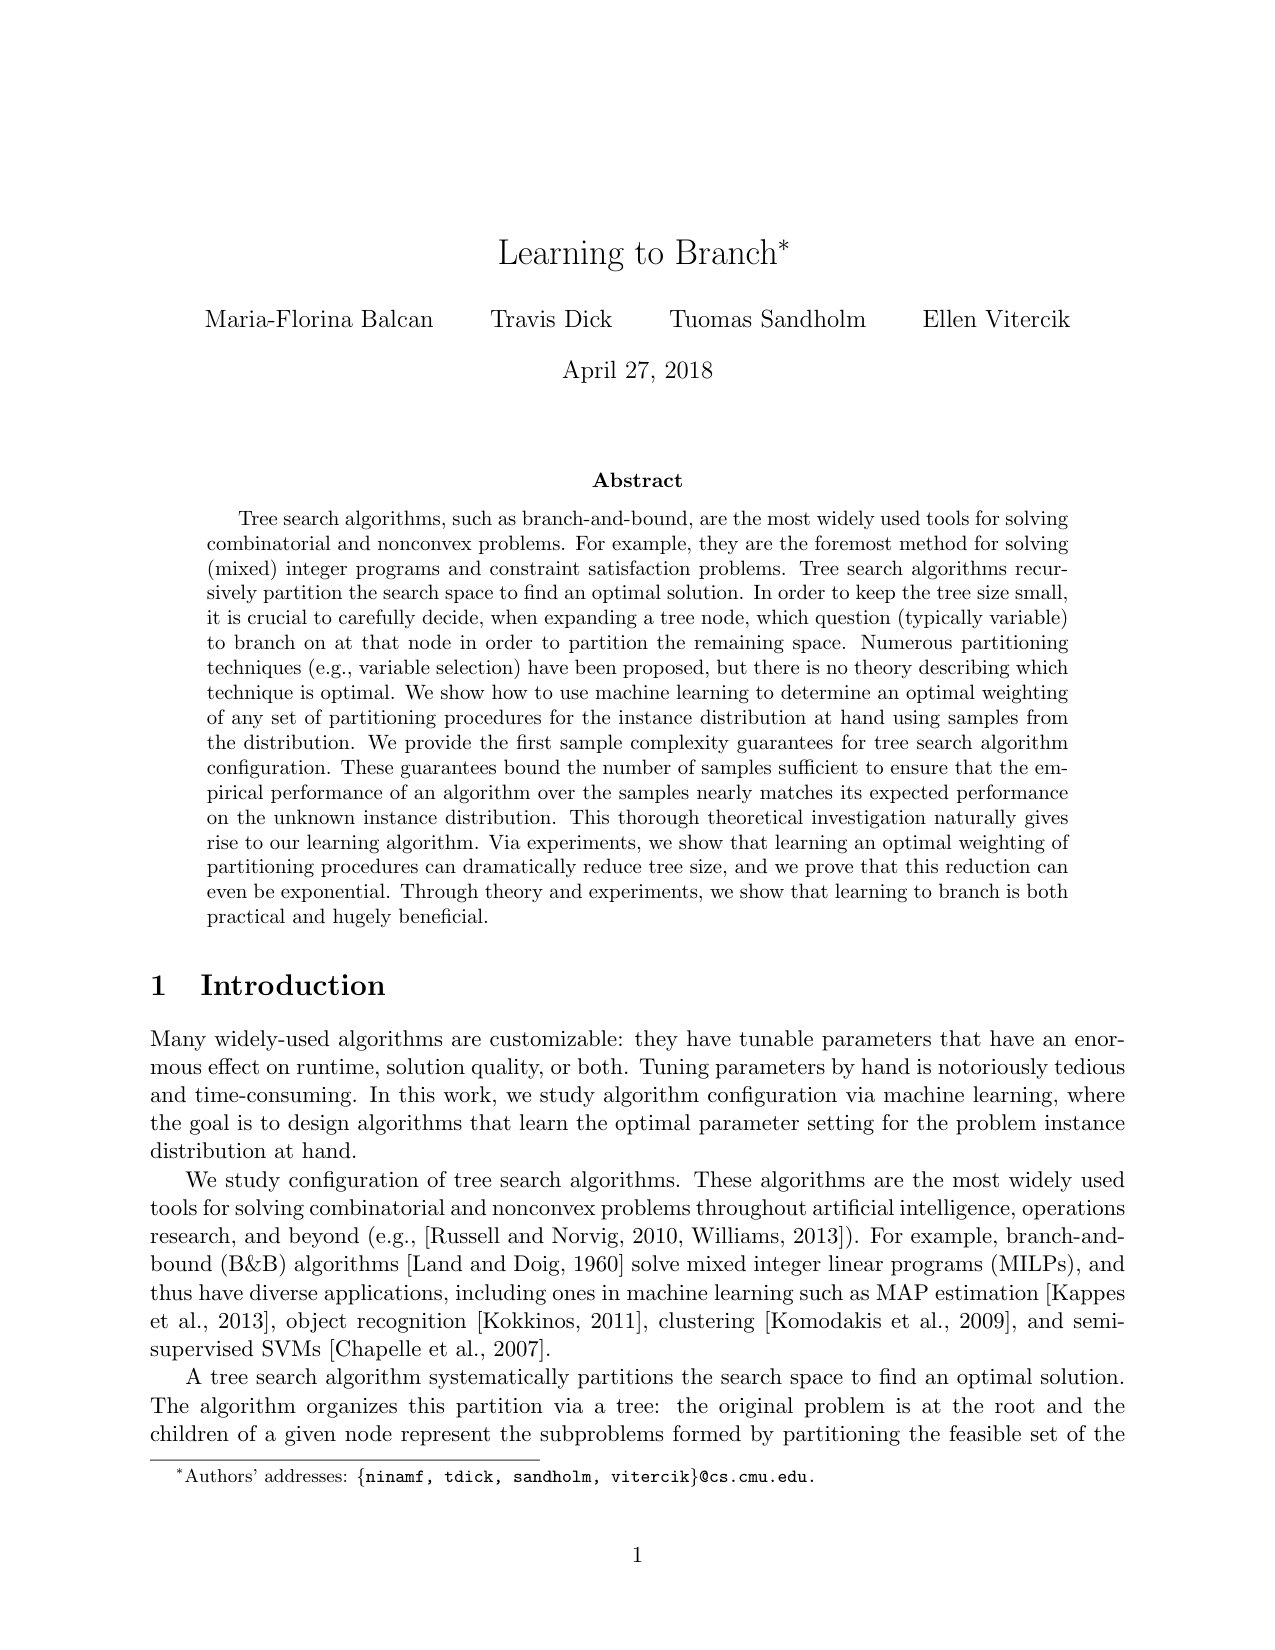 Figure 25
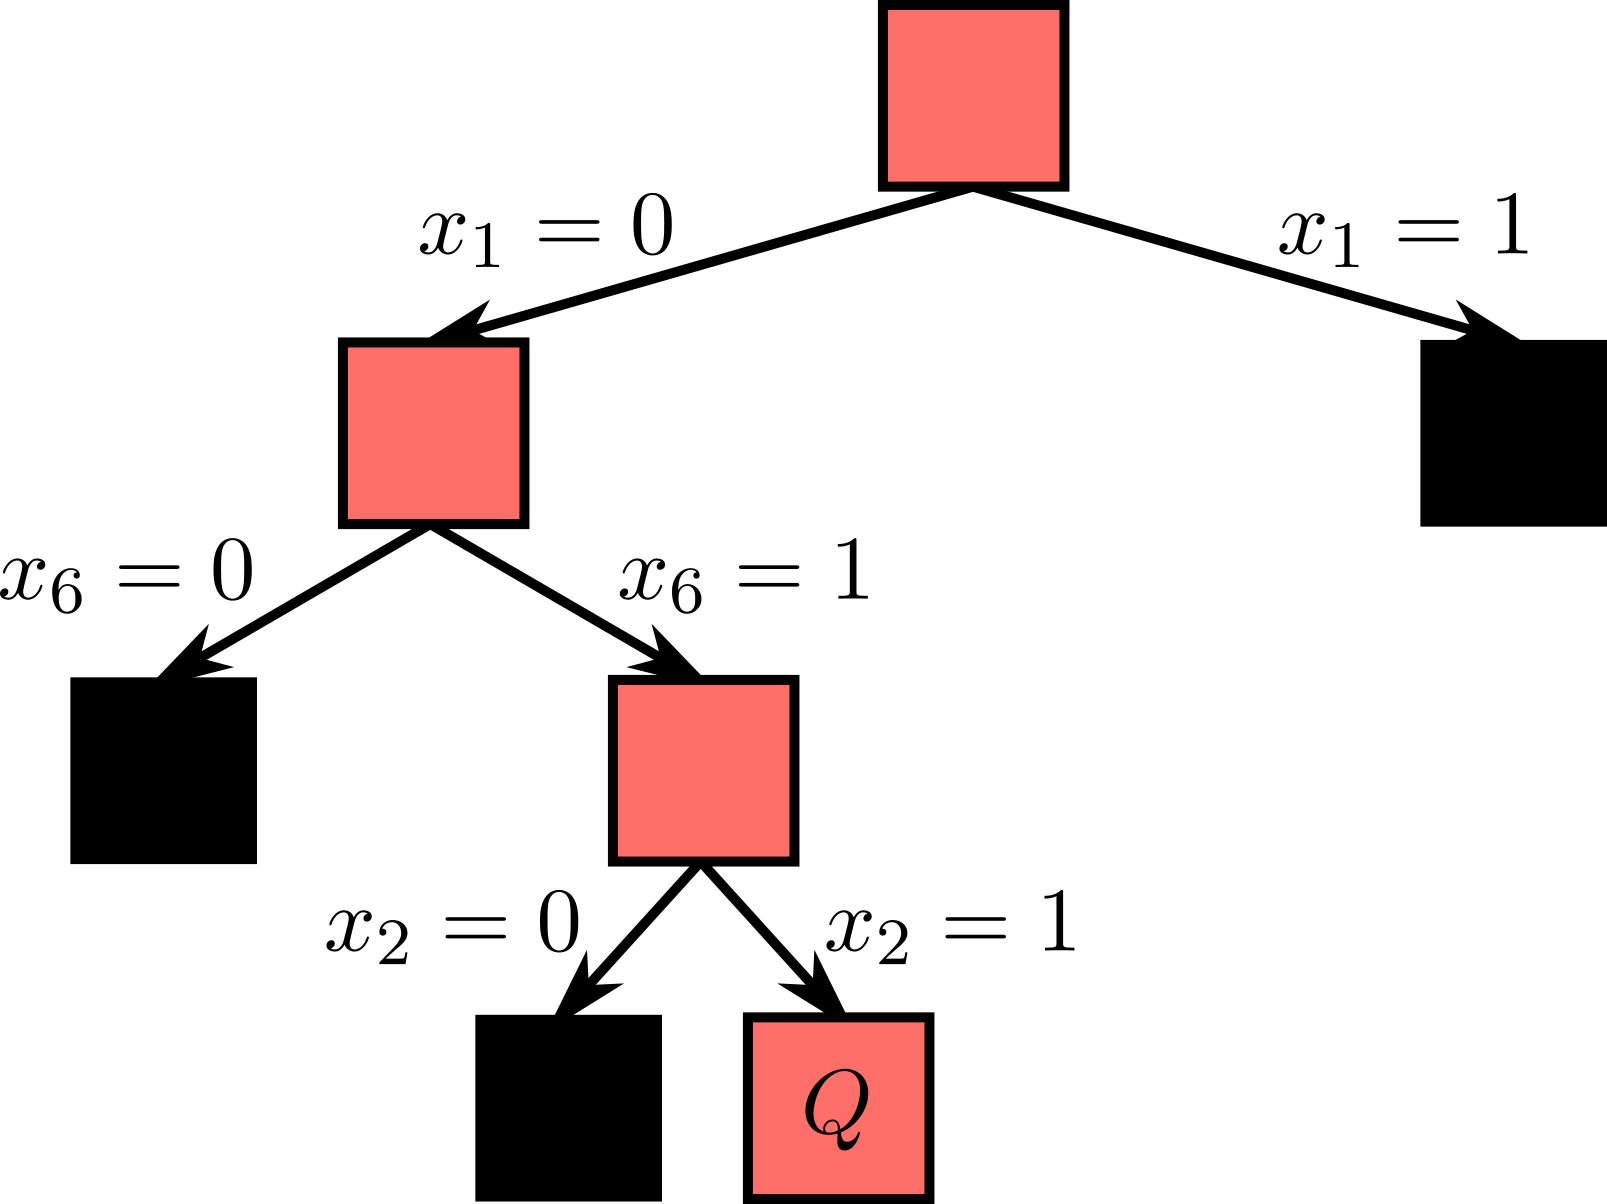 Figure 26
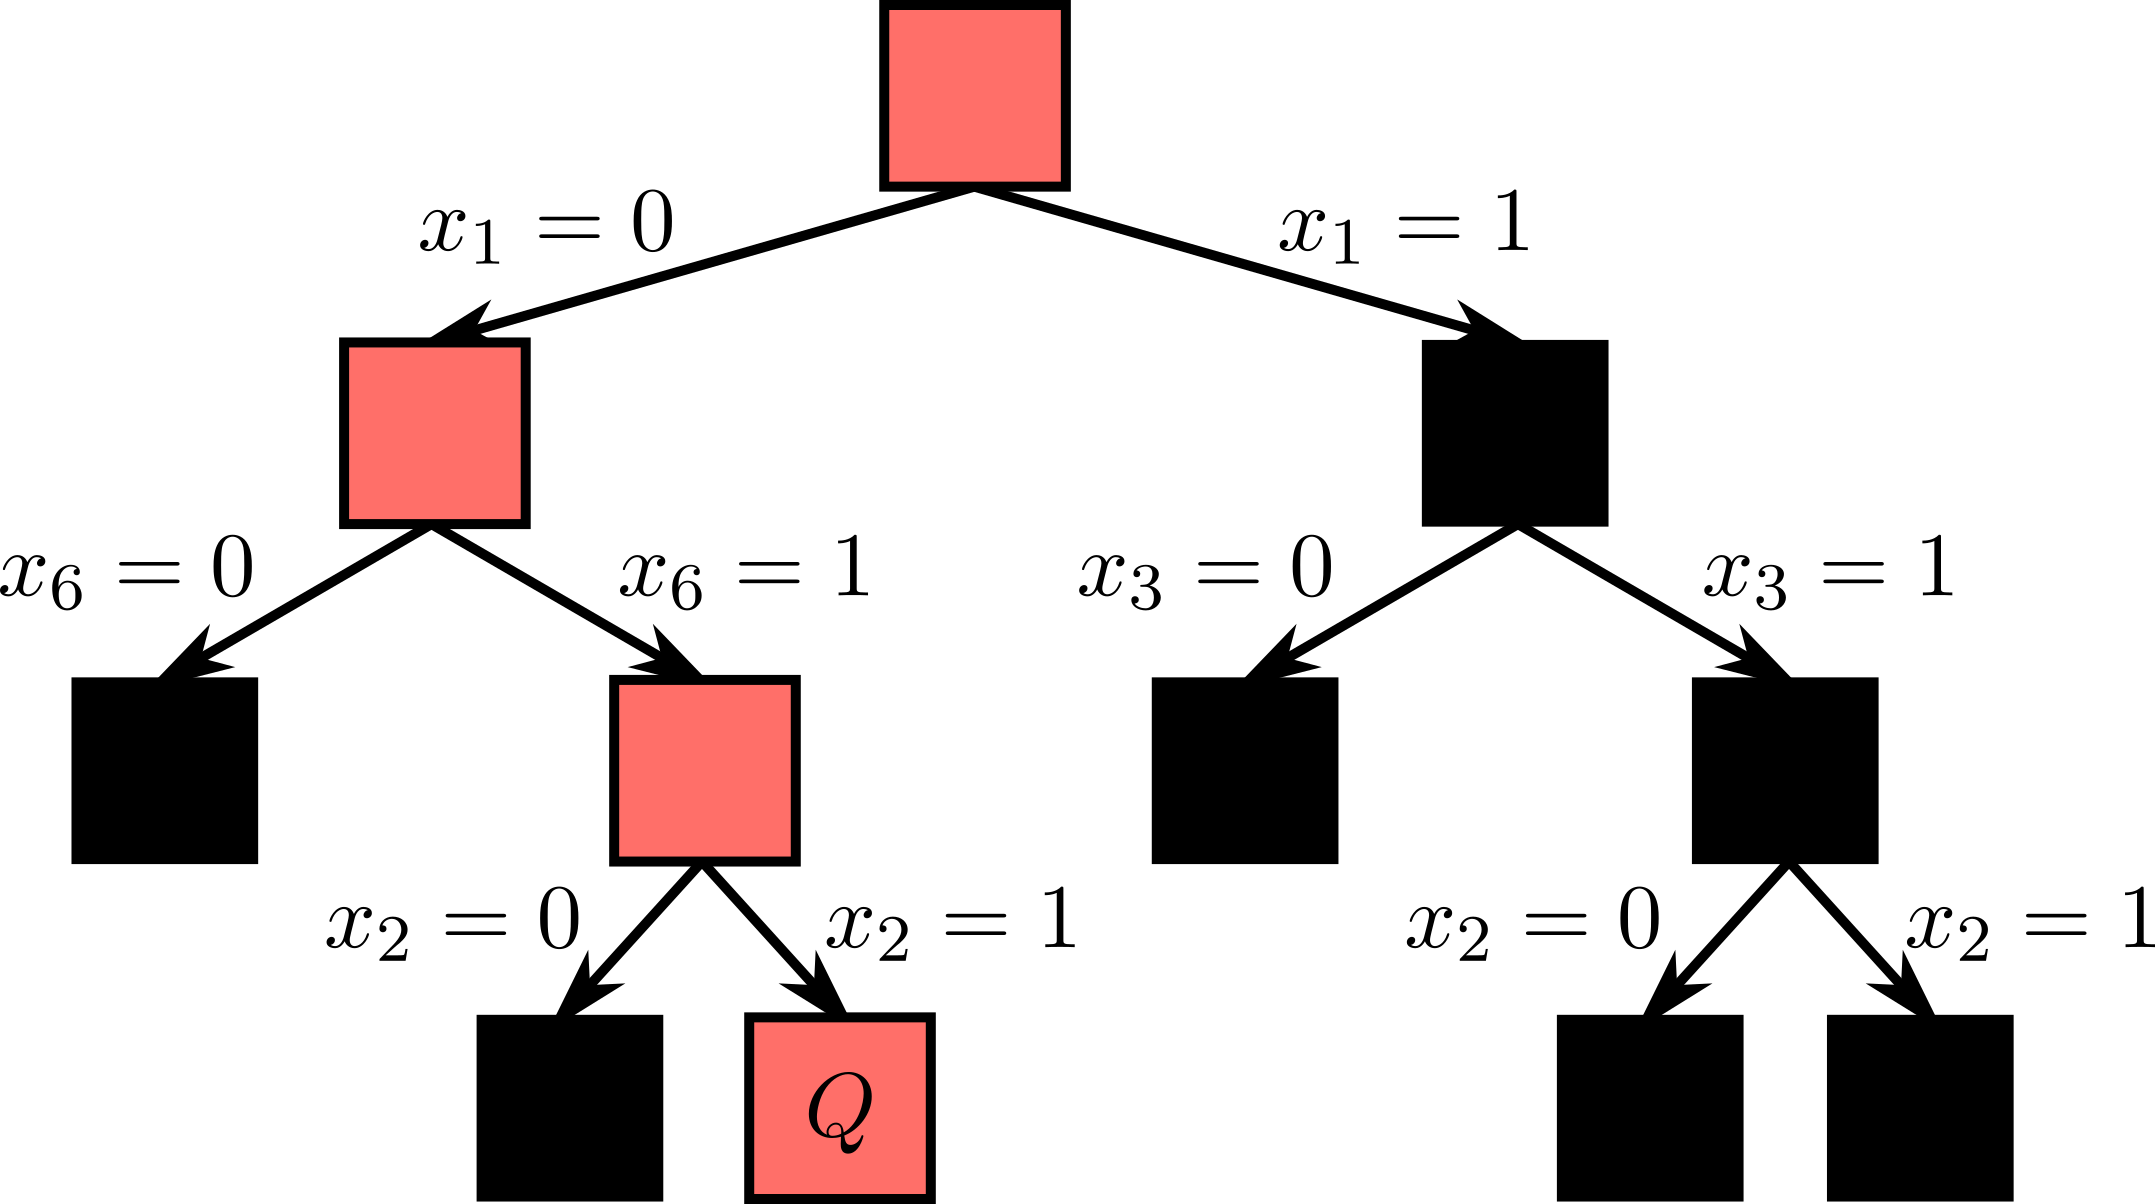 Figure 27
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
Taxonomy
TopicsConstraint Satisfaction and Optimization · Complexity and Algorithms in Graphs · Bayesian Modeling and Causal Inference
Learning to Branch111Authors’ addresses: {ninamf, tdick, sandholm, vitercik}@cs.cmu.edu.
Maria-Florina Balcan
Travis Dick
Tuomas Sandholm
Ellen Vitercik
Abstract
Tree search algorithms, such as branch-and-bound, are the most widely used tools for solving combinatorial and nonconvex problems. For example, they are the foremost method for solving (mixed) integer programs and constraint satisfaction problems. Tree search algorithms recursively partition the search space to find an optimal solution. In order to keep the tree size small, it is crucial to carefully decide, when expanding a tree node, which question (typically variable) to branch on at that node in order to partition the remaining space. Numerous partitioning techniques (e.g., variable selection) have been proposed, but there is no theory describing which technique is optimal. We show how to use machine learning to determine an optimal weighting of any set of partitioning procedures for the instance distribution at hand using samples from the distribution. We provide the first sample complexity guarantees for tree search algorithm configuration. These guarantees bound the number of samples sufficient to ensure that the empirical performance of an algorithm over the samples nearly matches its expected performance on the unknown instance distribution. This thorough theoretical investigation naturally gives rise to our learning algorithm. Via experiments, we show that learning an optimal weighting of partitioning procedures can dramatically reduce tree size, and we prove that this reduction can even be exponential. Through theory and experiments, we show that learning to branch is both practical and hugely beneficial.
1 Introduction
Many widely-used algorithms are customizable: they have tunable parameters that have an enormous effect on runtime, solution quality, or both. Tuning parameters by hand is notoriously tedious and time-consuming. In this work, we study algorithm configuration via machine learning, where the goal is to design algorithms that learn the optimal parameter setting for the problem instance distribution at hand.
We study configuration of tree search algorithms. These algorithms are the most widely used tools for solving combinatorial and nonconvex problems throughout artificial intelligence, operations research, and beyond (e.g., (Russell and Norvig, 2010; Williams, 2013)). For example, branch-and-bound (B&B) algorithms (Land and Doig, 1960) solve mixed integer linear programs (MILPs), and thus have diverse applications, including ones in machine learning such as MAP estimation (Kappes et al., 2013), object recognition (Kokkinos, 2011), clustering (Komodakis et al., 2009), and semi-supervised SVMs (Chapelle et al., 2007).
A tree search algorithm systematically partitions the search space to find an optimal solution. The algorithm organizes this partition via a tree: the original problem is at the root and the children of a given node represent the subproblems formed by partitioning the feasible set of the parent node. A branch is pruned if it is infeasible or it cannot produce a better solution than the best one found so far by the algorithm. Typically the search space is partitioned by adding an additional constraint on some variable. For example, suppose the feasible set is defined by the constraint , with . A tree search algorithm might partition this feasible set into two sets, one where , , and , and another where , , and , in which case the algorithm has branched on . A crucial question in tree search algorithm design is determining which variable to branch on at each step. An effective variable selection policy can have a tremendous effect on the size of the tree. Currently, there is no known optimal strategy and the vast majority of existing techniques are backed only by empirical comparisons. In the worst-case, finding an approximately optimal branching variable, even at the root of the tree alone, is NP-hard. This is true even in the case of satisfiability, which is a special case of constraint satisfaction and of MILP (Liberatore, 2000).
In this work, rather than attempt to characterize a branching strategy that is universally optimal, we show empirically and theoretically that it is possible to learn high-performing branching strategies for a given application domain. We model an application domain as a distribution over problem instances, such as a distribution over scheduling problems that an airline solves on a day-to-day basis. This model is standard throughout the algorithm configuration literature (e.g., (Hutter et al., 2009, 2011; Dai et al., 2017; Kleinberg et al., 2017)). The approach has also been used on large-scale problems in industry to configure and select winner determination algorithms for clearing tens of billions of dollars of combinatorial auctions (Sandholm, 2013). The algorithm designer does not know the underlying distribution over problem instances, but has sample access to the distribution. We show how to use samples from the distribution to learn a variable selection policy that will result in as small a search tree as possible in expectation over the underlying distribution.
Our learning algorithm adaptively partitions the parameter space of the variable selection policy into regions where for any parameter in a given region, the resulting tree sizes across the training set are invariant. The learning algorithm returns the empirically optimal parameter over the training set, and thus performs empirical risk minimization (ERM). We prove that the adaptive nature of our algorithm is necessary: performing ERM over a data-independent discretization of the parameter space can be disastrous. In particular, for any discretization of the parameter space, we provide an infinite family of distributions over MILP instances such that every point in the discretization results in a B&B tree with exponential size in expectation, but there exist infinitely-many parameters outside of the discretized points that result in a tree with constant size with probability 1. A small change in parameters can thus cause a drastic change in the algorithm’s behavior. This fact contradicts conventional wisdom. For example, SCIP, the best open-source MILP solver, sets one of the parameters we investigate to 5/6, regardless of the input MILP’s structure. Achterberg (2009) wrote that 5/6 was empirically optimal when compared against four other data-independent values. In contrast, our analysis shows that a data-driven approach to parameter tuning can have an enormous benefit.
The sensitivity of tree search algorithms to small changes in their parameters is a key challenge that differentiates our sample complexity analysis from those typically found in machine learning. For many well-understood function classes in machine learning, there is a close connection between the distance in parameter space between two parameter vectors and the distance in function space between the two corresponding functions. Understanding this connection is a necessary prerequisite to analyzing how many significantly different functions there are in the class, and thereby quantifying the class’s intrinsic complexity. Intrinsic complexity typically translates to VC dimension, Rademacher complexity, or some other metric which allows us to derive learnability guarantees. Since the tree size of a search algorithm as a function of its parameters does not exhibit this predictable behavior, we must carefully analyze the way in which the parameters influence each step of the procedure in order to derive learning algorithms with strong guarantees. In doing so, we present the first sample complexity guarantees for automated configuration of tree search algorithms. We provide worst-case bounds proving that a surprisingly small number of samples are sufficient for strong learnability guarantees: the sample complexity bound grows quadratically in the size of the problem instance, despite the complexity of the algorithms we study.
In our experiments section, we show that on many datasets based on real-world NP-hard problems, different parameters can result in B&B trees of vastly different sizes. Using an optimal parameter for one distribution on problems from a different distribution can lead to a dramatic tree size blowup. We also provide data-dependent generalization guarantees that allow the algorithm designer to use far fewer samples than in the worst case if the data is well-structured.
1.1 Related work
Several works have studied the use of machine learning techniques in the context of B&B; for an overview, see the summary by Lodi and Zarpellon (2017).
As in this work, Khalil et al. (2016) study variable selection policies. Their goal is to find a variable selection strategy that mimics the behavior of the classic branching strategy known as strong branching while running faster than strong branching. Alvarez et al. (2017) study a similar problem, although in their work, the feature vectors in the training set describe nodes from multiple MILP instances. Neither or these works come with any theoretical guarantees, unlike our work.
Several other works study data-driven variable selection from a purely experimental perspective. Di Liberto et al. (2016) devise an algorithm that learns how to dynamically switch between different branching heuristics along the branching tree. Karzan et al. (2009) propose techniques for choosing problem-specific branching rules based on a partial B&B tree. Ideally, these branching rules will choose variables that will lead to fast fathoming. They do not rely on any techniques from machine learning. In the context of CSP tree search, Xia and Yap (2018) apply existing multi-armed bandit algorithms to learning variable selection policies during tree search and Balafrej et al. (2015) use a bandit approach to select different levels of propagation during search.
Other works have explored the use of machine learning techniques in the context of other aspects of B&B beyond variable selection. For example, He et al. (2014) use machine learning to speed up branch-and-bound, focusing on speeding up the node selection policy. Their work does not provide any learning-theoretic guarantees. Other works that have studied machine learning techniques for branch-and-bound problems other than variable selection include Sabharwal et al. (2017), who also study how to devise node selection policies, Hutter et al. (2009), who study how to set CPLEX parameters, Kruber et al. (2017), who study how to detect decomposable model structure, and Khalil et al. (2017), who study how to determine when to run heuristics.
From a theoretical perspective, Le Bodic and Nemhauser (2017) present a theoretical model for the selection of branching variables. It is based upon an abstraction of MIPs to a simpler setting in which it is possible to analytically evaluate the dual bound improvement of choosing a given variable. Based on this model, they present a new variable selection policy which has strong performance on many MIPLIB instances. Unlike our work, this paper is unrelated to machine learning.
The learning-theoretic model of algorithm configuration that we study in this paper was introduced to the theoretical computer science community by Gupta and Roughgarden (2017). Under this model, an application domain is modeled as a distribution over problem instances and the goal is to PAC-learn an algorithm that is nearly optimal over the distribution. This model was later studied by Balcan et al. (2017) as well. These papers were purely theoretical. In contrast, we show that the techniques proposed in this paper are practical as well, and provide significant benefit.
We provide a more detailed description of several of these papers in Appendix A.
2 Tree search
Tree search is a broad family of algorithms with diverse applications. To exemplify the specifics of tree search, we present a vast family of NP-hard problems — (mixed) integer linear programs — and describe how tree search finds optimal solutions to problems from this family. Later on in Section 5, we provide another example of tree search for constraint satisfaction problems. In Appendix E, we provide a formal, more abstract definition of tree search and generalize our results to this more general algorithm.
2.1 Mixed integer linear programs
We study mixed integer linear programs (MILPs) where the objective is to maximize subject to and where some of the entries of are constrained to be in . Given a MILP , we denote an optimal solution to the LP relaxation of as . Throughout this work, given a vector , we use the notation to denote the component of . We also use the notation to denote the optimal objective value of the LP relaxation of . In other words, .
Example 2.1** (Winner determination).**
Suppose there is a set of items for sale and a set of buyers. In a combinatorial auction, each buyer submits bids for any number of bundles . The goal of the winner determination problem is to allocate the goods among the bidders so as to maximize social welfare, which is the sum of the buyers’ values for the bundles they are allocated. We can model this problem as a MILP by assigning a binary variable for every buyer and every bundle they submit a bid on. The variable is equal to 1 if and only if buyer receives the bundle . Let be the set of all bundles that buyer submits a bid on. An allocation is feasible if it allocates no item more than once ( for all ) and if each bidder receives at most one bundle ( for all ). Therefore, the MILP is:
[TABLE]
2.1.1 MILP tree search
MILPs are typically solved using a tree search algorithm called branch-and-bound (B&B). Given a MILP problem instance, B&B relies on two subroutines that efficiently compute upper and lower bounds on the optimal value within a given region of the search space. The lower bound can be found by choosing any feasible point in the region. An upper bound can be found via a linear programming relaxation. The basic idea of B&B is to partition the search space into convex sets and find upper and lower bounds on the optimal solution within each. The algorithm uses these bounds to form global upper and lower bounds, and if these are equal, the algorithm terminates, since the feasible solution corresponding to the global lower bound must be optimal. If the global upper and lower bounds are not equal, the algorithm refines the partition and repeats.
In more detail, suppose we want to use B&B to solve a MILP . B&B iteratively builds a search tree with the original MILP at the root. In the first iteration, consists of a single node containing the MILP . At each iteration, B&B uses a node selection policy (which we expand on later) to select a leaf node of the tree , which corresponds to a MILP . B&B then uses a variable selection policy (which we expand on in Section 2.1.2) to choose a variable of the MILP to branch on. Specifically, let (resp., ) be the MILP except with the additional constraint that (resp., ). B&B sets the right (resp., left) child of in to be a node containing the MILP (resp., ). B&B then tries to “fathom” these leafs: the leaf containing (resp., ) is fathomed if:
The optimal solution to the LP relaxation of (resp., ) satisfies the constraints of the original MILP . 2. 2.
The relaxation of (resp., ) is infeasible, so (resp., ) must be infeasible as well. 3. 3.
The objective value of the LP relaxation of (resp., ) is smaller than the objective value of the best known feasible solution, so the optimal solution to (resp., ) is no better than the best known feasible solution.
B&B terminates when every leaf has been fathomed. It returns the best known feasible solution, which is optimal. See Algorithm 1 for the pseudocode.
The most common node selection policy is the best bound policy. Given a B&B tree, it selects the unfathomed leaf containing the MILP with the maximum LP relaxation objective value. Another common policy is the depth-first policy, which selects the next unfathomed leaf in the tree in depth-first order.
Example 2.2**.**
In Figure 1, we show the search tree built by B&B given as input the following MILP (Kolesar, 1967):
[TABLE]
Each rectangle denotes a node in the B&B tree. Given a node , the top portion of its rectangle displays the optimal solution to the LP relaxation of , which is the MILP (1) with the additional constraints labeling the edges from the root to . The bottom portion of the rectangle corresponding to displays the objective value of the optimal solution to this LP relaxation, i.e., . In this example, the node selection policy is the best bound policy and the variable selection policy selects the “most fractional” variable: the variable such that is closest to , i.e., .
In Figure 1, the algorithm first explores the root. At this point, it has the option of exploring either the left or the right child. Since the optimal objective value of the right child (136) is greater than the optimal objective value of the left child (135), B&B will next explore the pink node (marked
1
). Next, B&B can either explore either of the pink node’s children or the orange node (marked
2
). Since the optimal objective value of the orange node (135) is greater than the optimal objective values of the pink node’s children (120), B&B will next explore the orange node. After that B&B can explore either of the orange node’s children or either of the pink node’s children. The optimal objective value of the green node (marked
3
) is higher than the optimal objective values of the orange node’s right child (116) and the pink node’s children (120), so B&B will next explore the green node. At this point, it finds an integral solution, which satisfies all of the constraints of the original MILP (1). This integral solution has an objective value of 133. Since all of the other leafs have smaller objective values, the algorithm cannot find a better solution by exploring those leafs. Therefore, the algorithm fathoms all of the leafs and terminates.
2.1.2 Variable selection in MILP tree search
Variable selection policies typically depend on a real-valued score per variable .
Definition 2.1** (Score-based variable selection policy).**
Let score be a deterministic function that takes as input a partial search tree , a leaf of that tree, and an index and returns a real value (). For a leaf of a tree , let be the set of variables that have not yet been branched on along the path from the root of to . A score-based variable selection policy selects the variable to branch on at the node .
We list several common definitions of the function score below. Recall that for a MILP with objective function , we denote an optimal solution to the LP relaxation of as . We also use the notation to denote the objective value of the optimal solution to the LP relaxation of , i.e., . Finally, we use the notation (resp., ) to denote the MILP with the additional constraint that (resp., ). If (resp., ) is infeasible, then we set (resp., ) to be some large number greater than .
Most fractional.
In this case, The variable that maximizes is the “most fractional” variable, since it is the variable such that is closest to .
Linear scoring rule (Linderoth and Savelsbergh, 1999).
In this case, where is a user-specified parameter. This parameter balances an “optimistic” and a “pessimistic” approach to branching: An optimistic approach would choose the variable that maximizes , which corresponds to , and a pessimistic approach would choose the variable that maximizes , which corresponds to .
Product scoring rule (Achterberg, 2009).
In this case, where . Comparing and to allows the algorithm to compare two variables even if or . After all, suppose the scoring rule simply calculated the product without comparing to . If , then the score equals 0, canceling out the value of and thus losing the information encoded by this difference.
Entropic lookahead scoring rule (Gilpin and Sandholm, 2011).
Let
[TABLE]
Set
Alternative definitions of the linear and product scoring rules.
In practice, it is often too slow to compute the differences and for every variable, since it requires solving as many as LPs. A faster option is to partially solve the LP relaxations of and , starting at and running a small number of simplex iterations. Denoting the new objective values as and , we can revise the linear scoring rule to be and we can revise the product scoring rule to be . Other popular alternatives to computing and that fit within our framework are pseudo-cost branching (Bénichou et al., 1971; Gauthier and Ribière, 1977; Linderoth and Savelsbergh, 1999) and reliability branching (Achterberg et al., 2005).
3 Guarantees for data-driven learning to branch
In this section, we begin with our formal problem statement. We then present worst-case distributions over MILP instances demonstrating that learning over any data-independent discretization of the parameter space can be inadequate. Finally, we present sample complexity guarantees and a learning algorithm. Throughout the remainder of this paper, we assume that all aspects of the tree search algorithm except the variable selection policy, such as the node selection policy, are fixed.
3.1 Problem statement
Let be a distribution over MILPs . For example, could be a distribution over clustering problems a biology lab solves day to day, formulated as MILPs. Let be a set of variable selection scoring rules, such as those in Section 2.1.2. Our goal is to learn a convex combination of the scoring rules that is nearly optimal in expectation over . More formally, let cost be an abstract cost function that takes as input a problem instance and a scoring rule score and returns some measure of the quality of B&B using score on input . For example, might be the number of nodes produced by running B&B using score on input . We say that an algorithm -learns a convex combination of the scoring rules if for any distribution , with probability at least over the draw of a sample , the algorithm returns a convex combination such that \mathbb{E}_{Q\sim\mathcal{D}}\bigl{[}\texttt{cost}(Q,\texttt{score})\bigr{]}-\mathbb{E}_{Q\sim\mathcal{D}}\bigl{[}\texttt{cost}(Q,\texttt{score}^{*})\bigr{]}\leq\epsilon, where is the convex combination of with minimal expected cost. In this work, we prove that only a small number of samples is sufficient to ensure -learnability.
Following prior work (e.g., (Hutter et al., 2009; Kleinberg et al., 2017)), we assume that there is some cap on the range of the cost function cost. For example, if cost is the size of the search tree, we may choose to terminate the algorithm when the tree size grows beyond some bound . We also assume that the problem instances in the support of are over binary variables, for some .
Our results hold for cost functions that are tree-constant, which means that for any problem instance , so long as the scoring rules and result in the same search tree, . For example, the size of the search tree is tree-constant.
3.2 Impossibility results for data-independent approaches
In this section, we focus on MILP tree search and prove that it is impossible to find a nearly optimal B&B configuration using a data-independent discretization of the parameters. Specifically, suppose and and suppose the cost function measures the size of the tree produced by B&B when using a fixed but arbitrary node selection policy. We would like to learn a nearly optimal convex combination of these two rules with respect to cost. Gauthier and Ribière (1977) proposed setting , Bénichou et al. (1971) and Beale (1979) suggested setting , and Linderoth and Savelsbergh (1999) found that performs well. Achterberg (2009) found that experimentally, performed best when comparing among .
We show that for any discretization of the parameter space [0, 1], there exists an infinite family of distributions over MILP problem instances such that for any parameter in the discretization, the expected tree size is exponential in . Yet, there exists an infinite number of parameters such that the tree size is just a constant (with probability 1). The proof is in Appendix C.
Theorem 3.1**.**
Let
[TABLE]
and be the size of the tree produced by B&B. For every such that and for all even , there exists an infinite family of distributions over MILP instances with variables such that if , then
[TABLE]
and if , then with probability 1, This holds no matter which node selection policy B&B uses.
Proof sketch.
We populate the support of the distribution by relying on two helpful theorems: Theorem 3.2 and C.4. In Theorem 3.2, we prove that for all , there exists an infinite family of MILP instances such that for any , if , then the scoring rule results in a B&B tree with nodes and if , the scoring rule results a tree with nodes. Conversely, in Theorem C.4, we prove that there exists an infinite family of MILP instances such that for any , if , then the scoring rule results in a B&B tree with nodes and if , the scoring rule results a tree with nodes. Now, let be an arbitrary instance in and let be an arbitrary instance in . The theorem follows by letting be a distribution such that See Figure 2 for an illustration.
Throughout the proof of this theorem, we assume the node selection policy is depth-first search. We then prove that for any infeasible MILP, if NSP and NSP’ are two node selection policies and for any , then tree B&B builds using NSP and score equals the tree it builds using NSP’ and score (see Theorem C.9). Thus, the theorem holds for any node selection policy. ∎
We now provide a proof sketch of Theorem 3.2, which helps us populate the support of the worst-case distributions in Theorem 3.1. The full proof is in Appendix C.
Theorem 3.2**.**
Let
[TABLE]
and be the size of the tree produced by B&B. For all even and all , there exists an infinite family of MILP instances such that for any , if , then the scoring rule results in a B&B tree with nodes and if , the scoring rule results a tree with nodes.
Proof sketch.
The MILP instances in are inspired by a worst-case B&B instance introduced by Jeroslow (1974). He proved that for any odd , every B&B algorithm will build a tree with nodes before it determines that for any , the following MILP is infeasible:
[TABLE]
We build off of this MILP to create the infinite family . Each MILP in combines a hard version of Jeroslow’s instance on variables and an easy version on 3 variables . Branch-and-bound only needs to determine that one of these problems is infeasible in order to terminate. The key idea of this proof is that if B&B branches on all variables in first, it will terminate upon making a small tree. However, if B&B branches on all variables in first, it will create a tree with exponential size before it terminates. The challenge is to design an objective function that enforces the first behavior when and the second behavior when . Proving this is the bulk of the work.
In a bit more detail, every instance in is defined as follows. For any constant , let and let . Let be the concatenation of and . Let be the MILP
[TABLE]
We define
For example, if and , then is
[TABLE]
As is illustrated in Figure 3, we have essentially “glued together” two disjoint versions of Jeroslow’s instance: the first five variables of correspond to a “big” version of Jeroslow’s instance and the last three variables correspond to a small version. Since the goal is maximization, the solution to the LP relaxation of will try to obtain as much value from the first five variables as it can, but it is constrained to ensure that . Therefore, the first five variables will be set to . Similarly, the solution to the LP relaxation of will set because under our assumption that . Thus, the solution to the LP relaxation of is . There are only two fractional variables that B&B might branch on: and . Straightforward calculations show that if is the B&B tree so far, which just consists of the root node, and This means that B&B will branch first on variable , which corresponds to the small version of Jeroslow’s instance (see Figure 3(b)) if and only if , which occurs if and only if . We show that this first branch sets off a cascade: if B&B branches first on variable , then it will proceed to branch on all variables in , thus terminating upon making a small tree. Meanwhile, if it branches on variable first, it will then only branch on variables in , creating a larger tree.
In the full proof, we generalize beyond eight variables to , and expand the large version of Jeroslow’s instance (as depicted in Figure 3(a)) from five variables to . When , we simply track B&B’s progress to make sure it only branches on variables from the small version of Jeroslow’s instance () before figuring out the MILP is infeasible. Therefore, the tree will have constant size. When , we prove by induction that if B&B has only branched on variables from the big version of Jeroslow’s instance (), it will continue to only branch on those variables. We also prove it will branch on about half of these variables along each path of the B&B tree. The tree will thus have exponential size. ∎
3.3 Sample complexity guarantees
We now provide worst-case guarantees on the number of samples sufficient to -learn a convex combination of scoring rules. These results bound the number of samples sufficient to ensure that for any convex combination of scoring rules, the empirical cost of tree search using score is close to its expected cost. Therefore, the algorithm designer can optimize over the samples without any further knowledge of the distribution. Moreover these sample complexity guarantees apply for any procedure the algorithm designer uses to tune , be it an approximation, heuristic, or optimal algorithm. She can use our guarantees to bound the number of samples she needs to ensure that performance on the sample generalizes to the distribution.
In Section 3.3.1 we provide generalization guarantees for a family of scoring rules we call path-wise, which includes many well-known scoring rules as special cases. In this case, the number of samples is surprisingly small given the complexity of these problems: it grows only quadratically with the number of variables. In Section 3.3.2, we provide guarantees that apply to any scoring rule, path-wise or otherwise.
3.3.1 Path-wise scoring rules
The guarantees in this section apply broadly to a class of scoring rules we call path-wise scoring rules. Given a node in a search tree , we denote the path from the root of to the node as . The path includes all nodes and edge labels from the root of to . For example, Figure 4(b) illustrates the path from the root of the tree in Figure 4(a) to the node labeled . We now state the definition of path-wise scoring rules.
Definition 3.1** (Path-wise scoring rule).**
The function score is a path-wise scoring rule if for all search trees , all nodes in , and all variables ,
[TABLE]
where is the path from the root of to .222Under this definition, the scoring rule can simulate B&B for any number of steps starting at any point in the tree and use that information to calculate the score, so long as Equality (2) always holds. See Figure 4 for an illustration.
Definition 3.1 requires that if the node appears at the end of the same path in two different B&B trees, then any path-wise scoring rule must assign every variable the same score with respect to in both trees.
Path-wise scoring rules include many well-studied rules as special cases, such as the most fractional, product, and linear scoring rules, as defined in Section 2.1.2. The same is true when B&B only partially solves the LP relaxations of and for every variable by running a small number of simplex iterations, as we describe in Section 2.1.2 and as is our approach in our experiments. In fact, these scoring rules depend only on the node in question, rather than the path from the root to the node. We present our sample complexity bound for the more general class of path-wise scoring rules because this class captures the level of generality the proof holds for. On the other hand, pseudo-cost branching (Bénichou et al., 1971; Gauthier and Ribière, 1977; Linderoth and Savelsbergh, 1999) and reliability branching (Achterberg et al., 2005), two widely-used branching strategies, are not path-wise, but our more general results from Section 3.3.2 do apply to those strategies.
In order to prove our generalization guarantees, we make use of the following key structure which bounds the number of search trees branch-and-bound will build on a given instance over the entire range of parameters. In essence, this is a bound on the intrinsic complexity of the algorithm class defined by the range of parameters, and this bound on algorithm class’s intrinsic complexity implies strong generalization guarantees.
Lemma 3.3**.**
Let cost be a tree-constant cost function, let and be two path-wise scoring rules, and let be an arbitrary problem instance over binary variables. There are intervals partitioning where for any interval , across all , the scoring rule results in the same search tree.
Proof.
We prove this lemma first by considering the actions of an alternative algorithm which runs exactly like B&B, except it only fathoms nodes if they are integral or infeasible. We then relate the behavior of to the behavior of B&B to prove the lemma.
First, we prove the following bound on the number of search trees will build on a given instance over the entire range of parameters. This bound matches that in the lemma statement.
Claim 3.4**.**
There are intervals partitioning where for any interval , the search tree builds using the scoring rule is invariant across all .333This claim holds even when and are members of the more general class of depth-wise scoring rules, which we define as follows. For any search tree of depth and any , let be the subtree of consisting of all nodes in of depth at most . We say that score is a depth-wise scoring rule if for all search trees , all , all nodes of depth , and all variables , .
Proof sketch of Claim 3.4.
We prove this claim by induction. For a tree , let be the nodes of depth at most . We prove that for , there are intervals partitioning where for any interval and any two parameters , if and are the trees builds using the scoring rules and , respectively, then . Suppose that this is indeed the case for some and consider an arbitrary interval and any two parameters . Consider an arbitrary node in (or equivalently, ) at depth . If is integral or infeasible, then it will be fathomed no matter which parameter the algorithm uses. Otherwise, for all , let be the state of the search tree builds using the scoring rule at the point when it branches on . By the inductive hypothesis, we know that across all , the path from the root to in is invariant, and we refer to this path as . Given a parameter , the variable will be branched on at node so long as or equivalently, so long as . In other words, the decision of which variable to branch on is determined by a convex combination of the constant values and no matter which parameter the algorithm uses. Here, we critically use the fact that the scoring rule is path-wise.
Since is a linear function of for all , there are at most intervals subdividing the interval such that the variable branched on at node is fixed.
Moreover, there are at most nodes at depth , and each node similarly contributes a subpartition of of size . If we merge all partitions, we have intervals partitioning where for any interval and any two parameters , if and are the trees builds using the scoring rules and , respectively, then . We can similarly subdivide each interval . The claim then follows from counting the number of subdivisions. ∎
Next, we explicitly relate the behavior of B&B to , proving that the search tree B&B builds is a rooted subtree of the search tree builds.
Claim 3.5**.**
Given a parameter , let and be the trees B&B and build respectively using the scoring rule . For any node of , let be the path from the root of to . Then is a rooted subtree of .
Proof of Claim 3.5.
The path can be labeled by a sequence of indices from and a sequence of variables from describing which variable is branched on and which value it takes on along the path . Let be this sequence of labels, where is the number of edges in . We can similarly label every edge in . We claim that there exists a path beginning at the root of with the labels .
For a contradiction, suppose no such path exists. Let be the earliest label in the sequence where there is a path beginning at the root of with the labels , but there is no way to continue the path using an edge labeled . There are exactly two reasons why this could be the case:
The node at the end of the path with labels was fathomed by . 2. 2.
The algorithm branched on a variable other than at the end of the path labeled .
In the first case, since only fathoms a node if it is integral or infeasible, we know that B&B will also fathom the node at the end of the path with labels . However, this is not the case since B&B next branches on the variable .
The second case is also not possible since the scoring rules are both path-wise. In a bit more detail, let be the node at the end of the path with labels . We refer to this path as . Let (respectively, ) be the state of the search tree B&B (respectively, ’) has built at the point it branches on . We know that is the path from the root to in both of the trees and . Therefore, for all variables , . This means that B&B and will choose the same variable to branch on at the node .
Therefore, we have reached a contradiction, so the claim holds. ∎
Next, we use Claims 3.4 and 3.5 to prove Lemma 3.3. Let be the intervals guaranteed to exist by Claim 3.4 and let be an arbitrary one of the intervals. Let and be two arbitrary parameters from . We will prove that the scoring rules and result in the same B&B search tree. For a contradiction, suppose that this is not the case. Consider the first iteration where B&B using the scoring rule differs from B&B using the scoring rule . By iteration, we mean lines 5 through 19 of Algorithm 1. Up until this iteration, B&B has built the same partial search tree . Since the node selection policy does not depend on or , B&B will choose the same leaf of the B&B search tree to branch on no matter which scoring rule it uses.
Suppose B&B chooses different variables to branch on in Step 6 of Algorithm 1 depending on whether it uses the scoring rule or . Let be the path from the root of to . By Claim 3.4, we know that the algorithm builds the same search tree using the two scoring rules. Let (respectively, ) be the state of the search tree has built using the scoring rule (respectively, ) by the time it branches on the node . By Claims 3.4 and 3.5, we know that is the path of from the root to of both and . By Claim 3.4, we know that will branch on the same variable at the node in both the trees and , so , or equivalently,
[TABLE]
and , or equivalently,
[TABLE]
Returning to the search tree that B&B is building, Equation (3) implies that
[TABLE]
and Equation (4) implies that . Therefore, B&B will branch on at the node no matter which scoring rule it uses.
Finally, since the trees B&B has built so far are identical, the choice of whether or not to fathom the children and does not depend on the scoring rule, so B&B will fathom the same nodes no matter whether it uses the scoring rule or . Therefore, we have reached a contradiction: the iterations were identical. We conclude that the lemma holds. ∎
We now show how this structure implies a generalization guarantee. We formulate our guarantees in terms of pseudo-dimension. By classic results from learning theory, pseudo-dimension immediately implies generalization guarantees. Pseudo-dimension is defined as follows.
Definition 3.2** (Pseudo-dimension (Pollard, 1984)).**
Let be a class of functions mapping an abstract domain to the set . Let be a subset of and let be a set of targets. We say that witness the shattering of by if for all , there exists some function such that for all , and for all , . If there exists some that witnesses the shattering of by , then we say that is shatterable by . Finally, the pseudo-dimension of , denoted , is the size of the largest set that is shatterable by .
Theorem 3.6 provides generalization bounds in terms of pseudo-dimension.
Theorem 3.6** (Pollard (1984)).**
For any distribution over , with probability at least over the draw of , for all ,
[TABLE]
Theorem 3.7**.**
Let cost be a tree-constant cost function, let and be two path-wise scoring rules, and let be the set of functions . Then
Proof.
Suppose that and let be a shatterable set of problem instances. We know there exists a set of targets that witness the shattering of by . This means that for every , there exists a parameter such that if , then . Otherwise . Let . We will prove that , and since , this means that (see Lemma C.10 in Appendix C).
To prove that , we rely on Lemma 3.3, which tells us that for any problem instance , there are intervals partitioning where for any interval , across all , the scoring rule results in the same search tree. If we merge all intervals for all samples in , we are left with intervals where for any interval and any , is constant for all . Therefore, at most one element of can come from each interval, meaning that , as claimed. ∎
3.3.2 General scoring rules
In this section, we provide generalization guarantees that apply to learning convex combinations of any set of scoring rules. Unlike the guarantees in Section 3.3.1, they depend on the size of the search trees B&B is allowed to build. For example, we may choose to terminate the algorithm when the tree size grows beyond some bound . The following lemma corresponds to Lemma 3.3 for this setting. For the full proof, see Lemma E.4 in Appendix E.2.1 which proves the lemma for a more general tree search algorithm.
Lemma 3.8**.**
Let cost be a tree-constant cost function, let be arbitrary scoring rules, and let be an arbitrary MILP over binary variables. Suppose we limit B&B to producing search trees of size . There is a set of at most hyperplanes such that for any connected component of , the search tree B&B builds using the scoring rule is invariant across all .
Proof sketch.
The proof has two steps. In Claim E.5, we show that there are at most different search trees that B&B might produce for the instance as we vary the mixing parameter vector . In Claim E.6, for each of the possible search trees that might be produced, we show that the set of parameter values which give rise to that tree lie in the intersection of halfspaces. Of course, each of these halfspaces is defined by a hyperplane. Let be the union of all hyperplanes over all trees. We know that for any connected component of , the search tree B&B builds using the scoring rule is invariant across all , so the lemma statement holds. ∎
In the same way Lemma 3.3 implies the pseudo-dimension bound in Theorem 3.7, Lemma 3.8 also implies a pseudo-dimension bound. The proof is similar to that of Theorem 3.7. See Theorem E.7 in Appendix E.2.1 which proves the theorem for a more general tree search algorithm.
Theorem 3.9**.**
Let cost be a tree-constant cost function and let be arbitrary scoring rules. Suppose we limit B&B to producing search trees of size . Let be the set of functions . Then
Naturally, if the function cost measures the size of the search tree B&B returns capped at some value as described in Section 3.1, we obtain the following corollary.
Corollary 3.10**.**
Let cost be a tree-constant cost function, let be arbitrary scoring rules, and let be an arbitrary tree size bound. Suppose that for any problem instance , equals the minimum of the following two values: 1) The number of nodes in the search tree B&B builds using the scoring rule on input ; and 2) . For any distribution over problem instances with at most variables, with probability at least over the draw for any ,
[TABLE]
3.3.3 Learning algorithm
For the case where we wish to learn the optimal tradeoff between two scoring rules, we provide an algorithm in Appendix C that finds the empirically optimal parameter given a sample of problem instances. By Theorems 3.7, 3.9, and 3.6, we know that so long as is sufficiently large, is nearly optimal in expectation. Our algorithm stems from the observation that for any tree-constant cost function cost and any problem instance , is simple: it is a piecewise-constant function of with a finite number of pieces. This is the same observation that we prove in Lemma 3.8. Given a sample of problem instances , our ERM algorithm constructs all piecewise-constant functions, takes their average, and finds the minimizer of that function. In practice, we find that the number of pieces making up this piecewise-constant function is small, so our algorithm can learn over a training set of many problem instances.
4 Experiments
In this section, we show that the parameter of the variable selection rule in B&B algorithms for MILP can have a dramatic effect on the average tree size generated for several domains, and no parameter value is effective across the multiple natural distributions.
Experimental setup.
We use the C API of IBM ILOG CPLEX 12.8.0.0 to override the default variable selection rule using a branch callback. Additionally, our callback performs extra book-keeping to determine a finite set of values for the parameter that give rise to all possible B&B trees for a given instance (for the given choice of branching rules that our algorithm is learning to weight). This ensures that there are no good or bad values for the parameter that get skipped; such skipping could be problematic according to our theory in Section 3.2. We run CPLEX exactly once for each possible B&B tree on each instance. Following Khalil et al. (2016); Fischetti and Monaci (2012), and Karzan et al. (2009), we disable CPLEX’s cuts and primal heuristics, and we also disable its root-node preprocessing. The CPLEX node selection policy is set to “best bound” (aka. in AI), which is the most typical choice in MILP. All experiments are run on a cluster of 64 c3.large Amazon AWS instances.
For each of the following application domains, Figure 6 shows the average B&B tree size produced for each possible value of the parameter for the linear scoring rule, averaged over independent samples from the distribution.
Combinatorial auctions.
We generate instances of the combinatorial auction winner determination problem under the OR-bidding language (Sandholm, 2002), which makes this problem equivalent to weighted set packing. The problem is NP-complete. We encode each instance as a binary MILP (see Example 2.1). We use the Combinatorial Auction Test Suite (CATS) (Leyton-Brown et al., 2000) to generate these instances. We use the “arbitrary” generator with 200 bids and 100 goods and “regions” generator with 400 bids and 200 goods.
Facility location.
Suppose there is a set of customers and a set of facilities that have not yet been built. The facilities each produce the same good, and each consumer demands one unit of that good. Consumer can obtain some fraction of the good from facility , which costs them . Moreover, it costs to construct facility . The goal is to choose a subset of facilities to construct while minimizing total cost. In Appendix D we show how to formulate facility location as a MILP. We generate instances with 70 facilities and 70 customers each. Each cost is uniformly sampled from and each cost is uniformly sampled from . This distribution has regularly been used to generate benchmark sets for facility location (Gilpin and Sandholm, 2011; Alekseeva et al., 2015; Goldengorin et al., 2011; Kochetov and Ivanenko, 2005; Homberger and Gehring, 2008).
Clustering.
Given points and pairwise distances between each pair of points and , the goal of -means clustering is to find centers such that the following objective function is minimized: In Appendix D, we show how to formulate this problem as a MILP. We generate instances with 35 points each and . We set for all and choose uniformly at random from for . These distances do not satisfy the triangle inequality and they are not symmetric (i.e., ), which tends to lead to harder MILP instances than using Euclidean distances between randomly chosen points in .
Agnostically learning linear separators.
Let be points in labeled by . Suppose we wish to learn a linear separator that minimizes 0-1 loss, i.e., . In Appendix D, we show how to formulate this problem as a MILP. We generate problem instances with 50 points from the 2-dimensional standard normal distribution. We sample the true linear separator from the 2-dimensional standard Gaussian distribution and label point by . We then choose random points and flip their labels so that there is no consistent linear separator.
Experimental results.
The relationship between the variable selection parameter and the average tree size varies greatly from application to application. This implies that the parameters should be tuned on a per-application basis, and that no parameter value is universally effective. In particular, the optimal parameter for the “regions” combinatorial auction problem, facility location, and clustering is close to 1. However, that value is severely suboptimal for the “arbitrary” combinatorial auction domain, resulting in trees that are three times the size of the trees obtained under the optimal parameter value.
Data-dependent guarantees.
We now explore data-dependent generalization guarantees. To prove our worst-case guarantee Theorem 3.7, we show in Lemma 3.3 that for any MILP instance over binary variables, there are intervals partitioning where for any interval , across all , the scoring rule results in the same B&B tree. Our generalization guarantees grow logarithmically in the number of intervals. In practice, we find that the number of intervals partitioning is much smaller than . In this section, we take advantage of this data-dependent simplicity to derive stronger generalization guarantees when the number of intervals partitioning is small. To do so, we move from pseudo-dimension to Rademacher complexity (Bartlett and Mendelson, 2002; Koltchinskii, 2001) since Rademacher complexity implies distribution-dependent guarantees whereas pseudo-dimension implies generalization guarantees that are worst-case over the distribution. We now define empirical Rademacher complexity.
Definition 4.1** (Empirical Rademacher complexity).**
Let be a class of functions mapping an abstract domain to the set . The empirical Rademacher complexity of with respect to a sample of size is defined as
[TABLE]
The following generalization guarantee based on Rademacher complexity is well-known.
Theorem 4.1**.**
For any distribution over , with probability at least over the draw of , for all ,
To obtain data-dependent generalization guarantees, we rely on the following theorem, which follows from truncating the proof of Massart’s finite lemma (Massart, 2000), as observed by Riondato and Upfal (2015). For a function class and a set , we use the notation to denote the set of vectors .
Theorem 4.2**.**
For a sample of size , suppose that is finite. Then
[TABLE]
Figure 7 shows a comparison of the worst-case versus data-dependent guarantees. The latter are significantly better. For ease of comparison, we compare the data-dependent bound provided by Theorem 4.2 with a variation of Theorem 3.7 in terms of Rademacher complexity. See Theorem D.1 in Appendix D for details.
5 Constraint satisfaction problems
In this section, we describe tree search for constraint satisfaction problems. The generalization guarantee from Section 3.3 also applies to tree search in this domain, as we describe in Appendix E.
A constraint satisfaction problem (CSP) is a tuple , where is a set of variables, is a set of domains where is the set of values variable can take on, and is a set of constraints between variables. Each constraint in is a pair where is a function mapping to for some and some . Given an assignment of the variables in , a constraint is satisfied if . The goal is to find an assignment that maximizes the number of satisfied constraints.
The degree of a variable , denoted , is the number of constraints involving . The dynamic degree of (an unassigned variable) given a partial assignment , denoted is the number of constraints involving and at least one other unassigned variable.
Example 5.1** (Graph -coloring).**
Given a graph, the goal of this problem is to color its vertices using at most colors such that no two adjacent vertices share the same color. This problem can be formulated as a CSP, as illustrated by the following example. Suppose we want to 3-color the graph in Figure 8(a) using pink, green, and orange. The four vertices correspond to the four variables . The domain . The only constraints on this problem are that no two adjacent vertices share the same color. Therefore we define to be the “not equal” relation mapping such that . Finally, we define the set of constraints to be
[TABLE]
See Figure 8(b) for a coloring that satisfies all constraints (
5.0.1 CSP tree search
CSP tree search begins by choosing a variable with domain and building branches, each one corresponding to one of the possible value assignments of . Next, a node of the tree is chosen, another variable is chosen, and branches from are built, each corresponding to the possible assignments of . The search continues and a branch is pruned if any of the constraints are not feasible given the partial assignment of the variables from the root to the leaf of that branch.
5.0.2 Variable selection in CSP tree search
As in MILP tree search, there are many variable selection policies researchers have suggested for choosing which variable to branch on at a given node. Typically, algorithms associate a score for branching on a given variable at node in the tree , as in B&B. The algorithm then branches on the variable with the highest score. We provide several examples of common variable selection policies below.
deg/dom and ddeg/dom (Bessiere and Régin, 1996):
deg/dom corresponds to the scoring rule and ddeg/dom corresponds to the scoring rule , where is the assignment of variables from the root of to .
Smallest domain (Haralick and Elliott, 1980):
In this case, .
Our theory is for tree search and applies to both MILPs and CSPs. It applies both to lookahead approaches that require learning the weighting of the two children (the more promising and less promising child) and to approaches that require learning the weighting of several different scoring rules.
6 Conclusions and broader applicability
In this work, we studied machine learning for tree search algorithm configuration. We showed how to learn a nearly optimal mixture of branching (e.g., variable selection) rules. Through experiments, we showed that using the optimal parameter for one application domain when solving problem instances from a different application domain can lead to a substantial tree size blow up. We proved that this blowup can even be exponential. We provided the first sample complexity guarantees for tree search algorithm configuration. With only a small number of samples, the empirical cost incurred by using any mixture of two scoring rules will be close to its expected cost, where cost is an abstract measure such as tree size. We showed that using empirical Rademacher complexity, these bounds can be significantly tightened further. Through theory and experiments, we showed that learning to branch is practical and hugely beneficial.
While we presented the theory in the context of tree search, it also applies to other tree-growing applications. For example, it could be used for learning rules for selecting variables to branch on in order to construct small decision trees that correctly classify training examples. Similarly, it could be used for learning to branch in order to construct a desirable taxonomy of items represented as a tree—for example for representing customer segments in advertising day to day.
Acknowledgments.
This work was supported in part by the National Science Foundation under grants CCF-1422910, CCF-1535967, IIS-1618714, IIS-1718457, IIS-1617590, CCF-1733556, a Microsoft Research Faculty Fellowship, an Amazon Research Award, a NSF Graduate Research Fellowship, and the ARO under award W911NF-17-1-0082.
Appendix A Additional related work
As in this work, Khalil et al. [2016] study variable selection policies. Their goal is to find a variable selection strategy that mimics the behavior of the classic branching strategy known as strong branching while running faster than strong branching. They split a single MILP instance into a training and test set. The beginning of the B&B algorithm is the training phase: their algorithm assigns features to each node and observes the variable selected to branch on by strong branching using the product scoring rule (see the definition in Section 2.1.2). Collecting these features and variable observations for a pre-specified number of nodes, they thus amass a training set. Their algorithm then uses this training set together with a classic ranking algorithm from the machine learning literature [Joachims, 2002] to determine a function that, ideally, will imitate strong branching. In a bit more detail, on each node the algorithm encounters as it explores the rest of the tree, the algorithm assigns features to that node, evaluates the function which returns a variable to branch on, and the algorithm branches on that variable. The hope is that matches the variable strong branching would choose to branch on at that node.
Other works have explored the use of machine learning techniques in the context of other aspects of B&B beyond variable selection. For example, He et al. [2014] use machine learning to speed up branch-and-bound, focusing on speeding up the node selection policy. Their work does not provide any learning-theoretic guarantees. Beyond node selection, He et al. [2014] also aim to learn a pruning policy, which determines whether to fathom a given node. This policy may occasionally fathom a node even when the branch contains the optimal solution, but ideally, this will happen infrequently or the resulting solution will be nearly optimal. Their learning algorithm takes as input a set of MIP instances and their optimal solutions. For each MIP in this set, the algorithm constructs a simple oracle which returns, given a set of B&B leaf nodes as input, the leaf whose feasible set contains the optimal solution. The learning algorithm uses the oracle to train the node selection and pruning policies using imitation learning. Ideally, the resulting node selection policy should choose the nodes the oracle selects, and the pruning policy should prune any node that does not contain the optimal solution in its feasible set.
Appendix B Variable selection policies
Appendix C Proofs from Section 3
Notation.
In the proofs in this section, we will use the following notation. Let be a MILP instance. Suppose that we branch on and , setting and . We use the notation to denote the resulting MILP. Similar, if we set and , we denote the resulting MILP as .
See 3.1
Proof.
We populate the support of the distribution by relying on two helpful theorems: Theorem 3.2 and C.4. In Theorem 3.2, we prove that for all , there exists an infinite family of MILP instances such that for any , if , then the scoring rule results in a B&B tree with nodes and if , the scoring rule results a tree with nodes. Conversely, in Theorem C.4, we prove that there exists an infinite family of MILP instances such that for any , if , then the scoring rule results in a B&B tree with nodes and if , the scoring rule results a tree with nodes.
Now, let be an arbitrary instance in and let be an arbitrary instance in . The theorem follows by letting be a distribution such that We know that if , then the expected value of is Meanwhile, if , then with probability 1,
[TABLE]
Throughout the proof of this theorem, we assume the node selection policy is depth-first search. We then prove that for any infeasible MILP, if NSP and NSP’ are two node selection policies and for any , then tree B&B builds using NSP and score equals the tree it builds using NSP’ and score (see Theorem C.9). Thus, the theorem holds for any node selection policy.∎
See 3.2
Proof.
For ease of notation in this proof, we will drop from the input of the functions and since the scoring rules do not depend on , they only depend on the input MILP instance and variable.
For any constant , let and let . Let be the concatenation of and . Next, define the -dimensional vectors and , and let be a matrix whose first row is and second row is . Let be the MILP
[TABLE]
We define
Example C.1**.**
If and , then is
[TABLE]
For every even , both of the constraints and are infeasible for since and are even numbers but 3 and are odd numbers. The key idea of this proof is that if branch-and-bound branches on all variables in first, it will terminate upon making a tree of size at most , since at most three branches are necessary to determine that is infeasible. However, if branch-and-bound branches on all variables in first, it will create a tree with exponential size before it terminates.
Lemma C.1**.**
Suppose . Then for any MILP , branches on all variables in before branching on variables in .
Proof of Lemma C.1.
For ease of notation, for the remainder of this proof, we drop the subscript from and denote this MILP as . We first need to determine the form of , which is the optimal solution to the LP relaxation of . It is easiest to see how the LP relaxation will set the variables , , and . The only constraints on these variables are that and that . Recall that is the vector defining the objective value of . Since , we know that , which means that . Since the goal is to maximize , the LP relaxation will set , , and . The logic for the first variables is similar. In this case, , so the LP relaxation’s solution will put as much weight as possible on the variable , then as much weight as possible on the variable , and so on, putting as little weight as possible on the variable since it has the smallest corresponding objective coefficient . Since the only constraints on these variables are that and , the LP objective value can set of the variables to 1, it can set one variable to , and it has to set the rest of the variables to 0. Letting , this means the LP relaxation will set the first variables to zero, it will set , and it will set to 1. In other words,
[TABLE]
For example, if , then . (See Figure 9(a).) Therefore, the only candidate variables to branch on are and where again, .
To determine when variable B&B will branch on, we need to calculate which is the solution to the LP relaxation of with the additional constraint that , as well as which is the solution to the LP relaxation of with the additional constraint that , and and . First, we will determine the form of the vectors and . Suppose we set . We now need to ensure that and that . Since , the solution to the LP relaxation of will set and . (See Figure 9(b).) Similarly, if we set , we now need to ensure that and that . Therefore, the solution to the LP relaxation of will set and . (See Figure 9(c).) In other words, and .
The argument for and is similar. Recall that in , the solution to the LP relaxation of the original MIP , we have that since it is the median of the variables . For all , we have that and for all , we have that . Suppose we set . As before, the LP relaxation’s solution will put as much weight as possible on the variable , then as much weight as possible on the variable , and so on, putting as little weight as possible on the variable since it has the smallest corresponding objective coefficient . Since it cannot set , it will set the next-best variable to , which is . (See Figure 9(d).) In other words, . If we set , the LP relaxation’s solution will have to take some weight away from the variables since it needs to ensure that . Therefore, it will set to and to 1 for all . (See Figure 9(e).) In other words, .
Therefore,
[TABLE]
This means that , , and . Therefore, and This means that so long as .
The next node branch-and-bound will explore is . The vector has fractional values only in positions and . Branching on , we again have that . Branching on , is infeasible, so equals some large number . Next, so Therefore, and
[TABLE]
where the final inequality holds because . Therefore, will be branched on next.
Since is infeasible, the next node branch-and-bound will explore is . The vector has fractional values only in positions and . Both MILP instances and are infeasible, so whereas , as before. Therefore, branch-and-bound will branch on and fathom both children.
The next node branch-and-bound will explore is . The vector has fractional values only in positions and . Branching on , we again have that . Branching on , so Meanwhile, is infeasible, so . Therefore, and . Therefore, will be branched on next.
The next node branch-and-bound will explore is . The vector has fractional values only in positions and . Both MILP instances and are infeasible, so whereas , as before. Therefore, branch-and-bound will branch on and fathom both children.
At this point, all children have been fathomed, so branch-and-bound will terminate. ∎
Lemma C.2**.**
Suppose . Then for any MILP , branch-and-bound with the scoring rule will create a tree of depth at least .
Proof of Lemma C.2.
To prove this lemma, we use induction to show that on any path from the root of the branch-and-bound tree to a node of depth , if are the set of indices branched on along that path, then . Even after branching on nodes from , the MILP will still be feasible, so the branch will not yet have been fathomed (since the original MILP is infeasible, a node will be fathomed only when it is infeasible). Therefore, branch-and-bound will continue down every branch to depth , thus creating a tree with nodes.
Claim C.3**.**
On any path from the root of the branch-and-bound tree to a node of depth , if are the set of indices branched on along that path, then .
Proof of Claim C.3.
We prove this claim by induction.
Inductive hypothesis. For , let be the set of indices branched on along an arbitrary path of the branch-and-bound tree from the root to a node of depth . Then .
Base case (). As we saw in the proof of Lemma C.1, if , then branch-and-bound will first branch on where .
Inductive step. Let be an arbitrary index such that . Let be the set of indices branched on along an arbitrary path of the branch-and-bound tree from the root to a node of depth . We know from the inductive hypothesis that . Let be the MILP at that node. Since , we know that the LP relaxation of is feasible. Let be the number of variables set to zero in and let be ordered such that for . We know that the solution to the LP relaxation of will have the first variables set to 0, it will set to 1/2, and it will set the remaining variables in to 1. Thus, the fractional variables are and . Note that since , .
Suppose we branch on . If we set , then the LP relaxation of will set to be 1/2 and otherwise the optimal solution will remain unchanged. Thus, . Meanwhile, if we set , then the LP relaxation of will set to be 0 and otherwise the optimal solution will remain unchanged. Thus, . Suppose that . Then
[TABLE]
Meanwhile, suppose that . Then
[TABLE]
Meanwhile, as in the proof of Lemma C.1, so long as . Thus, branch-and-bound will branch next on . ∎
∎
∎
Theorem C.4**.**
Let
[TABLE]
For all even and all , there exists an infinite family of MILP instances such that for any , if , then the scoring rule results in a branch-and-bound tree with nodes and if , the scoring rule results a tree with nodes.
Proof.
For any constant , let be a vector such that
[TABLE]
and let . Let be the concatenation of and multiplied with . For example, if and , then Next, define the -dimensional vectors and , and let be a matrix whose first row is and second row is . Let be the MILP
[TABLE]
We define
For every even , , both of the constraints and are infeasible for since and are even numbers but 3 and are odd numbers. The key idea of this proof is that if branch-and-bound branches on all variables in first, it will terminate upon making a tree of size at most , since at most three branches are necessary to determine that is infeasible. However, if branch-and-bound branches on all variables in first, it will create a tree with exponential size before it terminates.
Lemma C.5**.**
Suppose . Then for any MILP , branches on all variables in before branching on variables in .
Proof of Lemma C.5.
For ease of notation, for the remainder of this proof, we drop the subscript from and denote this MILP as . The optimal solution to the LP relaxation of has the following form:
[TABLE]
For example, if , then . Therefore, the only candidate variables to branch on are and where . Branching on , we have and . Branching on , we have and . Therefore,
[TABLE]
This means that , , and . Therefore, and This means that so long as .
The next node branch-and-bound will explore is . The vector has fractional values only in positions and . Branching on , we again have that and . Branching on , is infeasible, so equals some large number . Next, so Therefore, and
[TABLE]
where the final inequality holds because . Therefore, will be branched on next.
Since is infeasible, the next node branch-and-bound will explore is . The vector has fractional values only in positions and . Since both MILP instances and are infeasible, so whereas . Therefore, branch-and-bound will branch on and fathom both children.
The next node branch-and-bound will explore is . The vector has fractional values only in positions and . Branching on , we again have that and . Branching on , so Meanwhile, is infeasible, so equals some large number . Therefore, and . Therefore, will be branched on next.
The next node branch-and-bound will explore is . The vector has fractional values only in positions and . Since both MILP instances and are infeasible, so whereas , as before. Therefore, branch-and-bound will branch on and fathom both children.
At this point, all children have been fathomed, so branch-and-bound will terminate. ∎
Lemma C.6**.**
Suppose . Then for any MILP , branch-and-bound with the scoring rule will create a tree of depth at least .
Proof.
Let . We first prove two useful claims.
Claim C.7**.**
Let be an even number such that and let . Suppose that B&B has branched on exactly the variables in and suppose that the number of variables set to 1 equals the number of variables set to 0. Then B&B will next branch on the variable . Similarly, suppose . Suppose that B&B has branched on exactly the variables in and suppose that the number of variables set to 1 equals the number of variables set to 0. Then B&B will next branch on the variable .
Proof.
Let be the MILP contained in the node at the end of the path. This proof has two cases.
Case 1: .
In this case, there is a set of variables smaller than that have not yet been branched on and there is a set of variables in that have not yet been branched on. Since the number of variables set to 1 in equals the number of variables set to 0, the LP relaxation will set the variables in to 0, the variables in to 1, and to It will also set , , and . Therefore, the two fractional variables are and . Branching on , we have and . Branching on , we have that and . Therefore,
[TABLE]
This means that , , and . Therefore, and . Since and , we have that
[TABLE]
Therefore, will be branched on next.
Case 2: .
In this case, there is a set of variables smaller than that have not yet been branched on and a set of variables in that have not yet been branched on. Since the number of variables set to 1 in equals the number of variables set to 0, the LP relaxation will set the variables in to 0, the variables in to 1, and to It will also set , , and . Therefore, the two fractional variables are and . Branching on , we have and . Branching on , we have that and . Therefore,
[TABLE]
This means that , , and as in the previous case, so will be branched on next. ∎
Claim C.8**.**
Suppose that is the set of variables branched on along a path of depth where is odd and let . Suppose that . Moreover, suppose that the number of variables set to 1 in equals the number of variables set to 0, plus or minus 1. Then B&B will either branch on or .
Proof.
Let be the MILP contained a the end of the path. There are variables that are smaller than that have not yet been branched on, and variables in that have not yet been branched on. Let be the number of variables in set to 0 and let be the number of variables set to 1. This proof has two cases:
Case 1: .
Since , we know that and . Therefore, the LP relaxation will set the variables in to zero for a total of zeros, it will set the variables in to one for a total of ones, and it will set to . It will also set , , and . Therefore, the two fractional variables are and . Branching on , we have and . Branching on , we have that and . Therefore,
[TABLE]
This means that , , and . Therefore, and . Since and , we have that
[TABLE]
Therefore, will be branched on next.
Case 1: .
Since , we know that and . Therefore, the LP relaxation will set the variables in to zero for a total of zeros, it will set the variables in to one for a total of