Stochastic model-based minimization of weakly convex functions
Damek Davis, Dmitriy Drusvyatskiy

TL;DR
This paper introduces a unified analysis framework for stochastic algorithms minimizing weakly convex functions, establishing convergence rates and complexity guarantees for several classical methods through implicit smoothing techniques.
Contribution
It provides the first complexity guarantees for stochastic proximal point, subgradient, and Gauss-Newton methods on composite functions, using a novel implicit smoothing approach.
Findings
Algorithms achieve an $O(k^{-1/4})$ stationarity measure convergence rate.
First complexity bounds for stochastic proximal point, subgradient, and Gauss-Newton methods.
Convergence rate for stochastic projected gradient without batching on smooth convex sets.
Abstract
We consider a family of algorithms that successively sample and minimize simple stochastic models of the objective function. We show that under reasonable conditions on approximation quality and regularity of the models, any such algorithm drives a natural stationarity measure to zero at the rate . As a consequence, we obtain the first complexity guarantees for the stochastic proximal point, proximal subgradient, and regularized Gauss-Newton methods for minimizing compositions of convex functions with smooth maps. The guiding principle, underlying the complexity guarantees, is that all algorithms under consideration can be interpreted as approximate descent methods on an implicit smoothing of the problem, given by the Moreau envelope. Specializing to classical circumstances, we obtain the long-sought convergence rate of the stochastic projected gradient method, without…
Click any figure to enlarge with its caption.
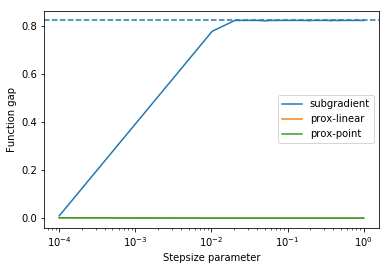 Figure 1
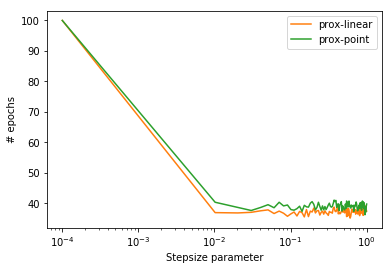 Figure 2
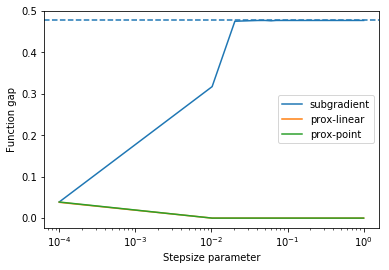 Figure 3
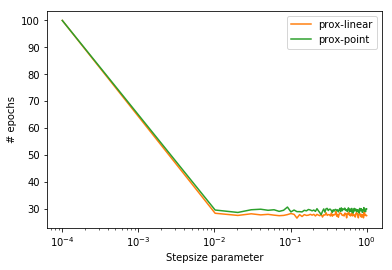 Figure 4
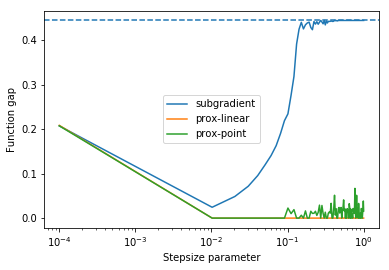 Figure 5
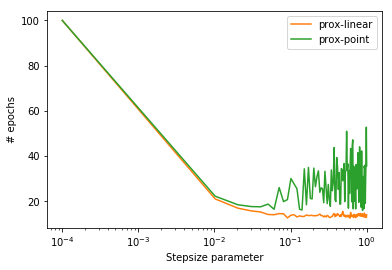 Figure 6
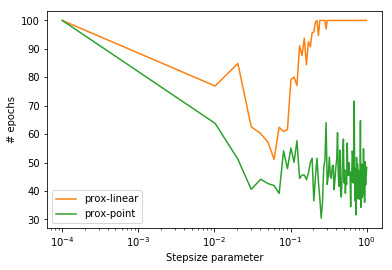 Figure 7
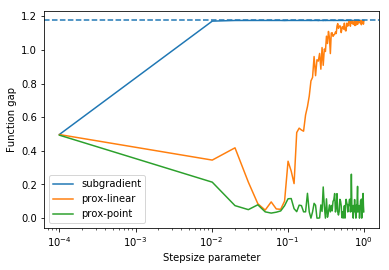 Figure 8
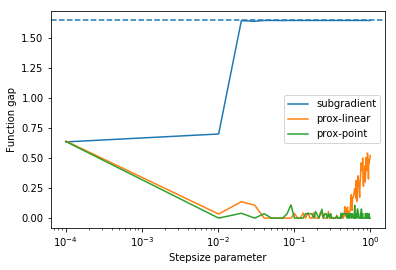 Figure 9
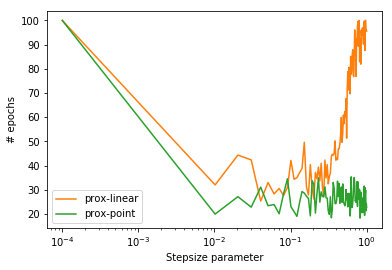 Figure 10
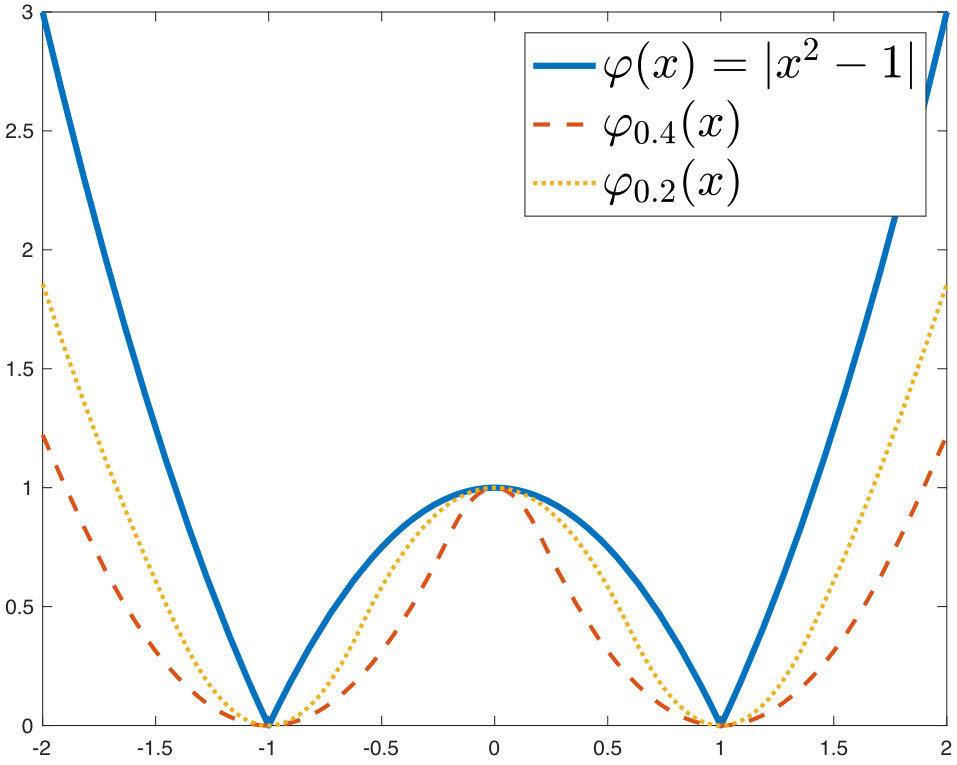 Figure 11
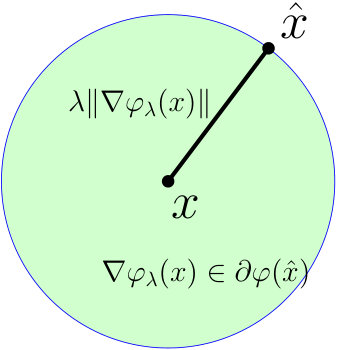 Figure 12
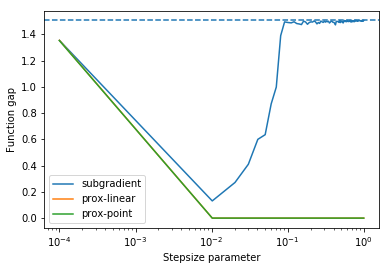 Figure 13
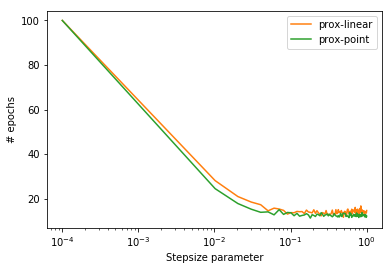 Figure 14
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
\newsiamremark
remarkRemark \newsiamremarkhypothesisHypothesis
\newsiamthmclaimClaim
\headersStochastic model-based minimization of weakly convex functionsDamek Davis and Dmitriy Drusvyatskiy
Stochastic model-based minimization of weakly convex functions††thanks: Submitted to the editors March 29, 2018. The results in this paper are a combination of the two arXiv preprints [22, 21].
\fundingResearch of Drusvyatskiy was supported by the AFOSR YIP award FA9550-15-1-0237 and by the NSF DMS 1651851 and CCF 1740551 awards.
Damek Davis School of Operations Research and Information Engineering, Cornell University, Ithaca, NY 14850, USA (, people.orie.cornell.edu/dsd95). [email protected]
Dmitriy Drusvyatskiy Department of Mathematics, University of Washington, Seattle, WA 98195 (, www.math.washington.edu/d̃drusv). [email protected]
Abstract
We consider a family of algorithms that successively sample and minimize simple stochastic models of the objective function. We show that under reasonable conditions on approximation quality and regularity of the models, any such algorithm drives a natural stationarity measure to zero at the rate . As a consequence, we obtain the first complexity guarantees for the stochastic proximal point, proximal subgradient, and regularized Gauss-Newton methods for minimizing compositions of convex functions with smooth maps. The guiding principle, underlying the complexity guarantees, is that all algorithms under consideration can be interpreted as approximate descent methods on an implicit smoothing of the problem, given by the Moreau envelope. Specializing to classical circumstances, we obtain the long-sought convergence rate of the stochastic projected gradient method, without batching, for minimizing a smooth function on a closed convex set.
keywords:
stochastic, subgradient, proximal, prox-linear, Moreau envelope, weakly convex
{AMS}
65K05, 65K10, 90C15, 90C30
1 Introduction
Stochastic optimization plays a central role in the statistical sciences, underlying all aspects of learning from data. The goal of stochastic optimization in data science is to learn a decision rule from a limited data sample, which generalizes well to the entire population. Learning such a decision rule amounts to minimizing the regularized population risk:
[TABLE]
Here, encodes the population data, which is assumed to follow some fixed but unknown probability distribution . The functions and play qualitatively different roles. Typically, evaluates the loss of the decision rule parametrized by on a data point . In contrast, the function models constraints on the parameters or encourages to have some low dimensional structure, such as sparsity or low rank. Within a Bayesian framework, the regularizer can model prior distributional information on .
Robbins-Monro’s pioneering 1951 work [54] gave the first procedure for solving (SO) in the setting when are smooth and strongly convex and , thereby inspiring decades of further research. Among such algorithms, the proximal stochastic (sub)gradient method is the most successful and widely used in practice. This method constructs a sequence of approximations of the minimizer of (SO) by iterating:
[TABLE]
where is an appropriate control sequence and is the proximal map
[TABLE]
Thus, in each iteration, the method travels from in the direction opposite to a sampled gradient , followed by a proximal operation.
Nonsmooth convex problems may be similarly optimized by replacing sample gradients by sample subgradients , where is the subdifferential in the sense of convex analysis [59]. Even more broadly, when is neither smooth nor convex, the symbol may refer to a generalized subdifferential. The formal definition of the subdifferential appears in Section 2, and is standard in the optimization literature (e.g. [58, Definition 8.3]). The reader should keep in mind that in practice, the functions are often all differentiable along the iterate sequence . Therefore from the viewpoint of implementation, one always computes the true gradients of the sampled functions, using conventional means. On the other hand, the nonsmoothness cannot be ignored in the analysis, since the gradients do not vary continuously and the objective function is can be nonsmooth at every limit point of the process. We will expand on these two observations shortly.
Performance of stochastic optimization methods is best judged by their sample complexity – the number of i.i.d. realizations needed to reach a desired accuracy of the decision rule. Classical results [45] stipulate that for convex problems, it suffices to generate samples to reach functional accuracy in expectation, and this complexity is unimprovable without making stronger assumptions. For smooth problems, the stochastic gradient method has sample complexity of to reach a point with the gradient norm at most in expectation [35, 36, 67].
Despite the ubiquity of the stochastic subgradient method in applications, its sample complexity is not yet known for any reasonably wide class of problems beyond those that are smooth or convex. This is somewhat concerning as the stochastic subgradient method is the simplest and most widely-used optimization algorithm for large-scale problems arising in machine learning and is the core optimization subroutine in industry backed software libraries, such as Google’s TensorFlow [1].
The purpose of this work is to provide the first sample complexity bounds for a number of popular stochastic algorithms on a reasonably broad class of nonsmooth and nonconvex optimization problems. The problem class we consider captures a variety of important computational tasks in data science, as we illustrate below, while the algorithms we analyze include the proximal stochastic subgradient, proximal point, and regularized Gauss-Newton methods. Before stating the complexity guarantees, we must first explain the “stationarity measure” that we will use to judge the quality of the iterates. It is this stationarity measure that tends to zero at a controlled rate.
The search for stationary points
Convex optimization algorithms are judged by the rate at which they decrease the function value along the iterate sequence. Analysis of smooth optimization algorithms focuses instead on the magnitude of the gradients along the iterates. The situation becomes quite different for problems that are neither smooth nor convex.
As in the smooth setting, the primary goal of nonsmooth nonconvex optimization is the search for stationary points. A point is called stationary for the problem (SO) if the inclusion holds. In “primal terms”, these are precisely the points where the directional derivative of is nonnegative in every direction. Indeed, under mild conditions on , equality holds [58, Proposition 8.32]:
[TABLE]
Thus a point , satisfying , approximately satisfies first-order necessary conditions for optimality.
An immediate difficulty in analyzing stochastic methods for nonsmooth and nonconvex problems is that it is not a priori clear how to measure the progress of the algorithm. Neither the functional suboptimality gap, , nor the stationarity measure, , necessarily tend to zero along the iterate sequence. This difficulty persists even in the simplest setting of minimizing a smooth function on a closed convex set by the stochastic projected gradient method. Indeed, what is missing is a continuous measure of stationarity to monitor, instead of the highly discontinuous function .
Weak convexity and the Moreau envelope
In this work, we focus on a class of problems that naturally admit a continuous measure of stationarity. We say that a function is -weakly convex if the assignment is convex. The class of weakly convex functions, first introduced in English in [50], is broad. It includes all convex functions and smooth functions with Lipschitz continuous gradient. More generally, any function of the form
[TABLE]
with convex and Lipschitz and a smooth map with Lipschitz Jacobian, is weakly convex [29, Lemma 4.2]. Notice that such composite functions need not be smooth nor convex; instead, the composite function class nicely interpolates between the smooth and convex settings. Classical literature highlights the importance of weak convexity in optimization [56, 51, 52], while recent advances in statistical learning and signal processing have further reinvigorated the problem class. Nonlinear least squares, phase retrieval [34, 30, 23], minimization of the Conditional Value-at-Risk [7, 8, 60], graph synchronization [6, 63, 2], covariance estimation [17], and robust principal component analysis [11, 14] naturally lead to weakly convex formulations. For a recent discussion on the role of weak convexity in large-scale optimization, see e.g., [26].
It has been known since Nurminskii’s work [49, 50] that when the functions are -weakly convex and , the stochastic subgradient method on (SO) generates an iterate sequence that subsequentially converges to a stationary point of the problem, almost surely. Nonetheless, the sample complexity of the basic method and of its proximal extension, has remained elusive. Our approach to resolving this open question relies on an elementary observation: weakly convex problems naturally admit a continuous measure of stationarity through implicit smoothing. The key construction we use is the Moreau envelope [43]:
[TABLE]
where . Standard results (e.g. [43], [55, Theorem 31.5]) show that as long as is -weakly convex and , the envelope is -smooth with the gradient given by
[TABLE]
See Figure 1(a) for an illustration.
When is -smooth with -Lipschitz gradient and there is no regularizer , the norm is proportional to the magnitude of the true gradient . More generally, when is -smooth and is nonzero, the norm is proportional to the size of the proximal gradient step, commonly used to measure convergence in additive composite minimization [47]. See the end of Section 2.2 for a precise statement. In the broader nonsmooth setting, the norm of the gradient has an intuitive interpretation in terms of near-stationarity for the target problem . Namely, the definition of the Moreau envelope directly implies that for any point , the proximal point satisfies
[TABLE]
Thus a small gradient implies that is near some point that is nearly stationary for ; see Figure 1(b). In the language of numerical analysis, one can interpret algorithms that drive the gradient of the Moreau envelope to zero as being “backward-stable”. For a longer discussion of the near-stationarity concept, we refer to reader to [26] or [29, Section 4.1].
Contributions
In this paper, we show that as long as the functions are -weakly convex and mild Lipschitz conditions hold, the proximal stochastic subgradient method will generate a point satisfying after at most iterations. This is perhaps surprising, since neither the Moreau envelope nor the proximal map of explicitly appear in the definition of the stochastic proximal subgradient method. This work appears to be the first to recognize the Moreau envelope as a useful potential function for analyzing subgradient methods.
Indeed, we will show that the worst-case complexity holds for a much wider family of algorithms than the stochastic subgradient method. Setting the stage, recall that the stochastic subgradient method relies on sampling subgradient estimates of , or equivalently sampling good linear models of the function. More broadly, suppose that is an arbitrary function (not necessarily written as an expectation), and for every point we have available a family of “models” , indexed by a random element . The oracle concept we use assumes that the only access to is by sampling a model centered around any base point . Naturally, to make use of such models we must have some control on their approximation quality. We will call the assignment a stochastic one-sided model if it satisfies
[TABLE]
Thus in each expectation, each model should lower bound up to a quadratic error, while agreeing with at the basepoint . See Figure 2 for an illustration.
The methods we consider then simply iterate the steps:
[TABLE]
We will prove that under mild Lipschitz conditions and provided that each function is -weakly convex, Algorithm 1.2 finds a point with after at most iterations. The main principle underlying the convergence guarantees is interesting in its own right. We will show that Algorithm 1.2 can be interpreted as an approximate descent method on the Moreau envelope:
[TABLE]
where are problem dependent constants.
When the models are true under-estimators of in expectation, meaning that (1.1) holds with , and the functions are convex, one expects guarantees that are analogous to the stochastic subgradient method for convex minimization. Indeed, we will show that under these circumstances, Algorithm (1.2) has complexity in terms of function value. The complexity estimate improves to when the functions are -strongly convex. Though the convexity assumption may appear stringent, it does hold in a number of nonclassical circumstances, such as for minimizing the Condition Value-at Risk (cVaR) of a loss function; see Example 2.6 and Section 4.2 for details.
To crystallize the ideas, consider the setting of stochastic composite optimization, studied recently by Duchi-Ruan [31]:
[TABLE]
where the functions are convex and the maps are smooth. Note that in the simplest setting when is a discrete distribution on , the problem (SO) reduces to minimizing a regularized empirical average of composite functions:
[TABLE]
In this setting, the following three stochastic one-sided models appear naturally:
[TABLE]
where is a subgradient selection. Each iteration of Algorithm 1.2 with the models (1.4) reduces to the stochastic proximal subgradient update, already mentioned previously. When equipped with the models (1.5), the method becomes the stochastic prox-linear algorithm — a close variant of Gauss-Newton. Both of these schemes were recently investigated in [31], where the authors showed that almost surely all limit points are stationary for the problem (SO). Algorithm 1.2 equipped with the models (1.6) is the stochastic proximal-point algorithm. This scheme was recently considered for convex minimization in [61] and extended to monotone inclusions in [9]. Notice that in contrast to the stochastic proximal subgradient method, the stochastic proximal point and prox-linear algorithms require solving an auxiliary subproblem. The advantage of these two schemes is that the models (1.5) and (1.6) provide much finer approximation quality, in that they are two-sided instead of one-sided. Indeed, empirical evidence [31, Section 4] suggests that the latter two algorithms can perform significantly better and are much more robust to the choice of the sequence . We also observe this phenomenon in our experiments in Section 5.
The outline of the paper is as follows. We begin with Section 2, which records some basic notation and results focusing on weak convexity and the Moreau envelope. This section also presents a number of illustrative applications that will be readily amenable to our algorithmic techniques. We then present three distinct convergence arguments: for the stochastic projected subgradient method in Section 3.1, for the stochastic proximal subgradient method in Section 3.2, and for algorithms based on general stochastic one-sided models in Section 4. Each argument has its own virtue. In particular, our guarantees for the stochastic projected subgradient method place no restriction on the parameters to be used, in contrast to our latter results. The argument for the stochastic proximal subgradient method generalizes verbatim to the setting when is -smooth and the stochastic gradient estimator has bounded variance, instead of a bounded second moment that we assume elsewhere. Section 4 applies to the most general classes of algorithms including stochastic proximal subgradient, prox-linear, and proximal point methods.
Context and related literature
The convergence guarantees we develop for the proximal stochastic subgradient method are new even in simplified cases. Two such settings are when are smooth and is the indicator function of a closed convex set, and when is nonsmooth, we have explicit access to the exact subgradients of , and .
Analogous convergence guarantees when is an indicator function of a closed convex set were recently established for a different algorithm in [24]. This scheme proceeds by directly applying the gradient descent method to the Moreau envelope , with each proximal point approximately evaluated by a convex subgradient method. In contrast, we show here that the basic stochastic subgradient method in the fully proximal setting, and without any modification or parameter tuning, already satisfies the desired convergence guarantees.
Our work also improves in two fundamental ways on the results in the seminal papers on the stochastic proximal gradient method for smooth functions [35, 36, 67]: first, we allow to be nonsmooth and second, even when are smooth, we do not require the variance of our stochastic estimator for to decrease as a function of . The second contribution removes the well-known “mini-batching” requirements common to [36, 67], while the first significantly expands the class of functions for which the rate of convergence of the stochastic proximal subgradient method is known. It is worthwhile to mention that our techniques rely on weak convexity of the regularizer , while [67] makes no such assumption.
The results in this paper are orthogonal to the recent line of work on accelerated rates of convergence for smooth nonconvex finite sum minimization problems, e.g., [38, 4, 53, 3]. These works crucially exploit the finite sum structure and/or (higher order) smoothness of the objective functions to push beyond the complexity. We leave it as an intriguing open question whether such improvement is possible for the nonsmooth weakly convex setting we consider here.
The unifying concept of stochastic one-sided models has not been explicitly used before. The complexity guarantees for the proximal stochastic subgradient, prox-linear, and proximal point methods (Theorem 3) for stochastic composite minimization are new and nicely complement the recent paper [31]. There, the authors proved that almost surely all limit points of the first two methods are stationary. For a historical account of the prox-linear method, see e.g., [10, 40, 29] and the references therein. For a systematic study of two-sided models (e.g. (1.5) and (1.6)) in optimization, see [27]. Stochastic compositional problems have also appeared in the parallel line of work [66]. There, the authors require the entire composite function to be either convex or smooth. We make no such assumptions here.
The convergence rate of Algorithm 1.2 in terms of function values in the convex setting is presented in Theorems 4.4, 4.6, and is intriguing. Even specializing to the proximal stochastic subgradient method, Theorems 4.4 and 4.6 appear to be stronger than the state of the art. Namely, in contrast to previous work [32, 19], the norms of the subgradients of do not enter the complexity bounds established in Theorem 4.4, while Theorem 4.6 extends the nonuniform averaging technique of [62] for strongly convex minimization to the fully proximal setting.
The observation that Algorithm 1.2 is an approximate descent method on the Moreau envelope (1.3) is tangentially related to the recent work on “inexact first-order oracles” in convex optimization [48, 25] and its partial extensions to nonconvex settings [33]. Expanding on the precise relationship between the techniques is an intriguing open question.
2 Basic notation and preliminaries
Throughout, we consider a Euclidean space endowed with an inner product and the induced norm . For any function , the domain and epigraph are the sets
[TABLE]
respectively. We say that is closed if the is a closed set.
This work focuses on algorithms for minimizing weakly convex functions.111To the best of our knowledge, the class of weakly convex functions was introduced in [50]. A function is called -weakly convex if the assignment is a convex function. In this section, we summarize some basic properties of this function class. All results we state in this section are either standard, or follow quickly from analogous results for convex functions. For further details and a historical account, we refer the reader to the short note [26].
2.1 Examples of weakly convex functions
Weakly convex functions are widespread in applications and are typically easy to recognize. One common source is the composite function class:
[TABLE]
where is convex and -Lipschitz and is a -smooth map with -Lipschitz continuous Jacobian. An easy argument shows that the composite function is -weakly convex [29, Lemma 4.2]. Below, we list a few examples to illustrate how widespread this problem class is in large-scale data scientific applications. The examples are here only to set the context; the reader can safely skip this discussion during the initial reading.
Example 2.1** (Robust phase retrieval).**
Phase retrieval is a common computational problem, with applications in diverse areas such as imaging, X-ray crystallography, and speech processing. For simplicity, we will consider the version of the problem over the reals. The (real-valued) phase retrieval problem seeks to determine a point satisfying the magnitude conditions,
[TABLE]
where and are given. Whenever gross outliers occur in the measurements , the following robust formulation of the problem is appealing [34, 30, 23]:
[TABLE]
The use of the penalty promotes strong recovery and stability properties even in the noiseless setting [30, 34]. Numerous other nonconvex approaches to phase retrieval exist, which rely on different problem formulations; for example, [12, 15, 64].* *
Example 2.2** (Covariance matrix estimation).**
The problem of covariance estimation from quadratic measurements, introduced in [16], is a higher rank variant of phase retrieval. Let be measurement vectors. The goal is to recover a low rank decomposition of a covariance matrix , with for a given , from quadratic measurements
[TABLE]
Note that we can only recover up to multiplication by an orthogonal matrix. This problem arises in a variety of contexts, such as covariance sketching for data streams and spectrum estimation of stochastic processes. We refer the reader to [16] for details. Supposing that is even, the authors of [16] show that the following potential function has strong recovery guarantees under usual statistical assumptions:
[TABLE]
Example 2.3** (Blind deconvolution and biconvex compressive sensing).**
The problem of blind deconvolution seeks to recover a pair of vectors in two low-dimensional structured spaces from their pairwise convolution. This problem occurs in a number of fields, such as astronomy and computer vision [13, 39]. For simplicity focusing on the real-valued case, one appealing formulation of the problem reads
[TABLE]
where and are known vectors, and are the convolution measurements. More broadly, problems of this form fall within the area of biconvex compressive sensing [41]. Similarly to the previous two examples, the use of the -penalty on the residuals allows for strong recovery and identifiability properties of the problem under statistical assumptions. Details will appear in a forthcoming paper. * *
Example 2.4** (Sparse dictionary learning).**
The problem of sparse dictionary learning seeks to find a sparse representation of the input data as a linear combination of basic atoms, which comprise the “dictionary”. This technique is routinely used in image and video processing. More formally, given a set of vectors , we wish to find a matrix and sparse weights such that the error is small for all . The following is a robust variant of the standard relaxation of the problem:
[TABLE]
More precisely, typical formulations use the squared norm instead of the norm ; see e.g. [65, 42]. When there are outliers in the data (i.e. not all of the data vectors can be sparsely represented), the formulation (2.3) may be more appealing. * *
Example 2.5** (Robust PCA).**
In robust principal component analysis, one seeks to identify sparse corruptions of a low-rank matrix [11, 14]. One typical example is image deconvolution, where the low-rank structure models the background of an image while the sparse corruption models the foreground. Formally, given a matrix , the goal is to find a decomposition , where is low rank and is sparse. A common relaxation of the problem is
[TABLE]
where is the target rank. As is common, the entrywise norm encourages a sparse residual .* *
Example 2.6** (Conditional Value-at-Risk).**
As in the introduction, let be a loss of a decision rule parametrized by on a data point , where the population data follows a probability distribution . Rather than minimizing the expectation , one often wishes to minimize the conditional expectation of the random variable over its -tail, for some fixed . This quantity is called the Conditional Value-at-Risk (cVaR) and it has a distinguished history. In particular, it is well known from the seminal work [60] that minimizing cVaR of the loss function can be formalized as222We refer the reader to [57, pp. 44] and [8] for a historical account of the cVaR minimization formula, and in particular its interpretation as the “optimized certainty equivalent” introduced in [7].
[TABLE]
where we use the notation . If the loss function is -weakly convex for a.e. , then the entire objective function is -weakly convex jointly in . In particular, this is the case when is -smooth with Lipschitz gradient, or when the loss is is convex for a.e. . Notice that the terms inside the expectation are always nonsmooth, even if the loss function is smooth. * *
2.2 Subdifferential and the Moreau envelope
A key property of convex functions is that any subgradient yields a global affine under-estimator of the function. It is this availability of global under-estimators that enables convergence guarantees for nonsmooth convex optimization. An analogous property is true for weakly convex functions, with the caveat that the subdifferential is meant in a broader variational analytic sense and the affine under-estimators are replaced by concave quadratic under-estimators. We now formalize this observation.
Consider a function and a point , with finite. The subdifferential of at , denoted , consists of all vectors satisfying
[TABLE]
We set for all . When is -smooth, the subdifferential consists only of the gradient , while for convex functions it reduces to the subdifferential in the sense of convex analysis. The following characterization of weak convexity is standard; we provide a short proof for completeness.
Lemma 2.1** (Subdifferential characterization).**
The following are equivalent for any lower-semicontinuous function .
The function is -weakly convex. 2. 2.
The approximate secant inequality holds:
[TABLE]
for all and . 3. 3.
The subgradient inequality holds:
[TABLE] 4. 4.
The subdifferential map is hypomontone:
[TABLE]
for all , , and .
If is -smooth, then the four properties above are all equivalent to
[TABLE]
Proof 2.2**.**
*Algebraic manipulation shows that the usual secant inequality on the function is precisely the approximate secant inequality (2.4) on . Therefore we deduce the equivalence . Suppose now 1 holds and define the function . Note the equality ; see e.g. [58, Exercise 8.8]. Since is convex, the inequality, , holds for all and . Algebraic manipulations then immediately imply (2.5), and therefore 3 holds. The implication follows by adding to (2.5) the analogous inequality with and interchanged. Finally suppose that 4 holds. Algebraic manipulations than imply that the subdifferential of is a globally monotone map. Applying [58, Theorem 12.17], we conclude that is convex and therefore 1 holds. Finally the characterization of weak convexity when is -smooth is immediate from the second-order characterization of convexity of the function . *
For any function and , the Moreau envelope and the proximal map are defined by
[TABLE]
respectively. Classically, the Moreau envelope of a convex function is -smooth for any ; see [43]. The same is true for weakly convex functions, provided is sufficiently small.
Lemma 2.3**.**
Consider a -weakly convex function . Then for any , the Moreau envelope is -smooth with gradient given by
[TABLE]
See Figure 1(a) for an illustration.
As mentioned in the introduction, the norm of the gradient has an intuitive interpretation in terms of near-stationarity. Namely, the optimality conditions for the minimization problem in (2.6) directly imply that for any point , the proximal point satisfies
[TABLE]
Thus a small gradient implies that is near some point that is nearly stationary for ; see Figure 1(b). All of the convergence guarantees that we present will be in terms of the quantity .
It is important to keep in mind that in more classical circumstances, the size of the gradient of the Moreau envelope is proportional to more familiar quantities. To illustrate, consider the optimization problem
[TABLE]
where is -smooth with -Lipschitz gradient and is closed and convex. Much of the literature [47, 36] focusing on this problem class highlights the role of the prox-gradient mapping:
[TABLE]
Indeed, complexity estimates are typically stated in terms of the norm of the prox-gradient mapping . On the other hand, one can show that the two stationarity measures, and , are proportional [28, Theorem 4.5]:
[TABLE]
Thus when specializing our results to the setting (2.7), all of the convergence guarantees can be immediately translated in terms of the prox-gradient mapping.
3 Proximal stochastic subgradient method
In this section, we analyze the proximal stochastic subgradient method for weakly convex minimization. Throughout, we consider the optimization problem
[TABLE]
where is a closed convex function and is a -weakly convex function. We assume that the only access to is through a stochastic subgradient oracle.
Assumption A** (Stochastic subgradient oracle).**
Fix a probability space and equip with the Borel -algebra. We make the following three assumptions:
- (A1)
It is possible to generate i.i.d. realizations . 2. (A2)
There is an open set containing and a measurable mapping satisfying for all . 3. (A3)
There is a real such that the inequality, , holds for all .
The three assumption (A1), (A2), (A3) are standard in the literature on stochastic subgradient methods: assumptions (A1) and (A2) are identical to assumptions (A1) and (A2) in [44], while Assumption (A3) is the same as the assumption listed in [44, Equation (2.5)]. We will investigate the efficiency of the proximal stochastic subgradient method, described in Algorithm 1.
Henceforth, the symbol will denote the expectation conditioned on all the realizations .
3.1 Projected stochastic subgradient method
Our analysis of Algorithm 1 is shorter and more transparent when is the indicator function of a closed, convex set . This is not surprising, since projected subgradient methods are typically much easier to analyze than their proximal extensions (e.g. [32, 19]). Note that (3.1) then reduces to the constrained problem
[TABLE]
and the proximal map becomes the nearest point projection . Thus throughout Section 3.1, we suppose that Assumptions (A1), (A2), and (A3) hold and that is the indicator function of a closed convex set . The following is the main result of this section.
Theorem 1** (Stochastic projected subgradient method).**
Let be the point returned by Algorithm 1. Then in terms of any constant , the estimate holds:
[TABLE]
and therefore we have
[TABLE]
In particular, if Algorithm 1 uses the constant parameter , for some real , then the point satisfies:
[TABLE]
Proof 3.1**.**
Let denote the points generates by Algorithm 1. For each index , define and set . We successively deduce
[TABLE]
where (3.6) follows directly from the definition of the proximal map, (3.7) uses that the projection is -Lipschitz, and (3.8) follows from (2.5).
Next, observe that the function is strongly convex with parameter , and therefore
[TABLE]
where the last equality follows from Lemma 2.3. Thus we deduce
[TABLE]
Taking expectations of both sides with respect to , and using the law of total expectation yields the claimed inequality (3.3)
Unfolding the recursion (3.3) yields:
[TABLE]
Lower-bounding the left-hand side by and rearranging, we obtain the bound:
[TABLE]
*Notice that the left-hand-side is precisely the expectation . Thus (3.4) holds, as claimed. Finally, (3.5) follows from (3.4) by setting and for all indices . *
Let us translate the estimate (3.5) into a complexity bound by minimizing out in . Namely, suppose we have available some real satisfying . We deduce from (3.5) the estimate, Minimizing the right-hand side in yields the choice and therefore the guarantee
[TABLE]
In particular, suppose that is -Lipschitz and the diameter of is bounded by some . Then we may set , where the first term follows from the definition of the Moreau envelope and the second follows from Lipschitz continuity. Then the number of subgradient evaluations required to find a point satisfying is at most
[TABLE]
This complexity in matches the guarantees of the stochastic gradient method for finding an -stationary point of a smooth function [35, Corollary 2.2].
Improved complexity under convexity
It is intriguing to ask if the complexity (3.10) can be improved when is a convex function. The answer, unsurprisingly, is yes. Since is convex, here and for the rest of the section, we will let the constant be arbitrary. As a first attempt, one may follow the observation of Nesterov [46] for smooth minimization. The idea is that the right-hand-side of the complexity bound (3.9) depends on the initial gap . We can make this quantity as small as we wish by a separate subgradient method. Namely, we may simply run a subgradient method for iterations to decrease the gap to ; see for example [37, Proposition 5.5] for this basic guarantee. Then we run another round of a subgradient method for iterations using the optimal choice . A quick computation shows that the resulting two-round scheme will find a point satisfying after at most iterations.
By following a completely different technique, introduced by Allen-Zhu [5] for smooth stochastic minimization, this complexity can be even further improved to by running logarithmically many rounds of the subgradient method on quadratically regularized problems. Since this procedure and its analysis is somewhat long and is independent of the rest of the material, we have placed it in an independent arXiv technical report [20].
3.2 Proximal stochastic subgradient method
We next move on to convergence guarantees of Algorithm 1 in full generality. An important consequence we discuss at the end of the section is a convergence guarantee for the stochastic proximal gradient method for minimizing a sum of a smooth function and a convex function, where the gradient oracle has bounded variance (instead of bounded second moment). Those not interested in this guarantee can in principle skip to Section 4, which details our most general convergence result for nonsmooth minimization.
Before we proceed, let us note that for any and , we have . To see this, observe that (A2) and (A3) directly imply that whenever is differentiable at , we have
[TABLE]
Since at any point , the subdifferential is the convex hull of limits of gradients at nearby points [55, Theorem 25.6], the claim follows. We will use this estimate in the proof of Lemma 3.
We break up the analysis of Algorithm 1 into two lemmas. Henceforth, fix a real . Let be the iterates produced by Algorithm 1 and let be the i.i.d. realizations used. For each index , define and set . Observe that by the optimality conditions of the proximal map and the subdifferential sum rule [58, Exercise 10.10], there exists a vector satisfying . The following lemma realizes as a proximal point of .
Lemma 2**.**
For each index , equality holds:
[TABLE]
Proof 3.2**.**
By the definition of , we have
[TABLE]
*where the last equivalence follows from the optimality conditions for the proximal subproblem. This completes the proof. *
The next lemma establishes a crucial descent property for the iterates.
Lemma 3**.**
Suppose and we have for all indices . Then the inequality holds:
[TABLE]
Proof 3.3**.**
Set . We successively deduce
[TABLE]
*where the first equation follows from Lemma 2, (3.11) uses that is -Lipschitz [58, Proposition 12.19], and (3.13) follows from (4). The result now follows from the assumed inequality . *
With Lemma 3 proved, we can now establish convergence guarantees of Algorithm 1 in full generality.
Theorem 4** (Stochastic proximal subgradient method).**
Fix a real and a stepsize sequence . Then the iterates generated by Algorithm 1 satisfy
[TABLE]
and the point returned by Algorithm 1 satisfies:
[TABLE]
In particular, if Algorithm 1 uses the constant parameter , for some real , then the point satisfies:
[TABLE]
Proof 3.4**.**
We successively observe
[TABLE]
where the first inequality follows directly from the definition of the proximal map and the second follows from Lemma 3. Taking expectations with respect to yields the claimed inequality (3.14). The rest of the proof proceeds as in Theorem 1. Namely, unfolding the recursion (3.14) yields:
[TABLE]
Lower-bounding the left-hand side by and rearranging, we obtain the bound:
[TABLE]
*Recognizing the left-hand-side as establishes (3.15). Setting and in (3.15) yields the final guarantee (3.16). *
Proximal stochastic gradient for smooth minimization
Let us now look at the consequences of our results in the setting when is -smooth with -Lipschitz gradient. Note, that then is automatically -weakly convex. In this smooth setting, it is common to replace assumption (A3) with the finite variance condition:
There is a real such that the inequality, , holds for all .
Henceforth, let us therefore assume that is -smooth with -Lipschitz gradient, and Assumptions (A1), (A2), and hold.
All of the results in Section 3.2 can be easily modified to apply to this setting. In particular, Lemma 2 holds verbatim, while Lemma 3 extends as follows.
Lemma 5**.**
Fix a real and a sequence . Then the inequality holds:
[TABLE]
Proof 3.5**.**
By the same argument as in Lemma 3, we arrive at (3.12) with . Set and . Adding and subtracting , we successively deduce
[TABLE]
*where (3.18) follows from assumption (A2), namely , (3.19) follows by expanding the square and using assumption , and (3.20) follows from (4) and Lipschitz continuity of . The assumption guarantees . The result follows. *
We can now state the convergence guarantees of the proximal stochastic gradient method. The proof is completely analogous to that of Theorem 4, with Lemma 5 playing the role of Lemma 3.
Corollary 6** (Stochastic prox-gradient method for smooth minimization).**
Fix a real and a stepsize sequence . Then the iterates generated by Algorithm 1 satisfy
[TABLE]
and the point returned by Algorithm 1 satisfies:
[TABLE]
In particular, if Algorithm 1 uses the constant parameter , for some real , then the point satisfies:
[TABLE]
As mentioned at the end of Section 2.2, it is immediate to translate the complexity estimate in Corollary 6 to an analogous estimate in terms of the size of the prox-gradient mapping (2.8), thereby allowing for a direct comparison with previous results.
4 Stochastic model-based minimization
In the previous section, we established the complexity of for the stochastic proximal subgradient methods. In this section, we show that the complexity persists for a much wider class of algorithms, including the stochastic proximal point and prox-linear algorithms. Henceforth, we consider the optimization problem
[TABLE]
where is a closed function (not necessarily convex) and is locally Lipschitz. We assume that the only access to is through a stochastic one-sided model.
Assumption B** (Stochastic one-sided model).**
Fix a probability space and equip with the Borel -algebra. We assume that there exist real such that the following four properties hold:
- (B1)
(Sampling) It is possible to generate i.i.d. realizations . 2. (B2)
(One-sided accuracy) There is an open convex set containing and a measurable function , defined on , satisfying
[TABLE]
and
[TABLE] 3. (B3)
(Weak-convexity) The function is -weakly convex , a.e. . 4. (B4)
(Lipschitz property) There exists a measurable function satisfying and such that
[TABLE]
for all and a.e. .
It will be useful for the reader to keep in mind the following lemma, which shows that the objective function is itself weakly convex with parameter and that is -Lipschitz continuous on .
Lemma 1**.**
The function is -weakly convex and the inequality holds:
[TABLE]
Proof 4.1**.**
Fix arbitrary points and a real , and set . Define the function . Taking into account the equivalence of weak convexity with the approximate secant inequality (2.4), we successively deduce
[TABLE]
where (4.4) uses (B2), inequality (4.5) uses (B3), and (4.6) uses (B2). Thus is -weakly convex, as claimed.
Next, taking expectations in (B2) and in (4.2) yields the estimates:
[TABLE]
Thus for any point , we deduce
[TABLE]
*In particular, when is differentiable at , setting with , we deduce . Since is locally Lipschitz continuous, its Lipschitz constant on is no greater than .333This follows by combining gradient formula for the Clarke subdifferential [18, Theorem 8.1] with the mean value theorem [18, Theorem 2.4]. We therefore deduce that is -Lipschitz continuous on , as claimed. *
We can now formalize the algorithm we investigate, as Algorithm 2. The reader should note that, in contrast to the previously discussed algorithms, Algorithm 2 employs a nondecreasing stepsize , which is inversely proportional to . This notational choice will simplify the analysis and complexity guarantees that follow.
4.1 Analysis of the algorithm
Henceforth, let be the iterates generated by Algorithm 2 and let be the corresponding samples used. For each index , define the proximal point
[TABLE]
As in Section 3, we will use the symbol to denote the expectation conditioned on all the realizations . The analysis of Algorithm 2 relies on the following lemma, which establishes two descent type properties. Estimate (4.7) is in the same spirit as Lemma 3 in Section 3. The estimate (4.8), in contrast, will be used at the end of the section to obtain the convergence rate of Algorithm 2 in function values under convexity assumptions.
Lemma 2**.**
In general, for every index , we have
[TABLE]
Moreover, for any point , the inequality holds:
[TABLE]
Proof 4.2**.**
Recall that the function is strongly convex with constant