Virtual CNN Branching: Efficient Feature Ensemble for Person Re-Identification
Albert Gong, Qiang Qiu, Guillermo Sapiro

TL;DR
This paper introduces 'virtual branching,' an efficient CNN ensemble method for person re-identification that enhances robustness against pose and view variations with minimal additional computational cost.
Contribution
The paper presents a novel virtual branching technique for CNNs that creates effective ensemble representations without significant extra parameters or computation.
Findings
Achieves competitive results on Market-1501, CUHK03, and DukeMTMC-reID datasets.
Enhances robustness to pose, view, and body misalignment in person re-ID.
Requires nearly no additional parameters or computation.
Abstract
In this paper we introduce an ensemble method for convolutional neural network (CNN), called "virtual branching," which can be implemented with nearly no additional parameters and computation on top of standard CNNs. We propose our method in the context of person re-identification (re-ID). Our CNN model consists of shared bottom layers, followed by "virtual" branches, where neurons from a block of regular convolutional and fully-connected layers are partitioned into multiple sets. Each virtual branch is trained with different data to specialize in different aspects, e.g., a specific body region or pose orientation. In this way, robust ensemble representations are obtained against human body misalignment, deformations, or variations in viewing angles, at nearly no any additional cost. The proposed method achieves competitive performance on multiple person re-ID benchmark datasets,…
Click any figure to enlarge with its caption.
 Figure 1
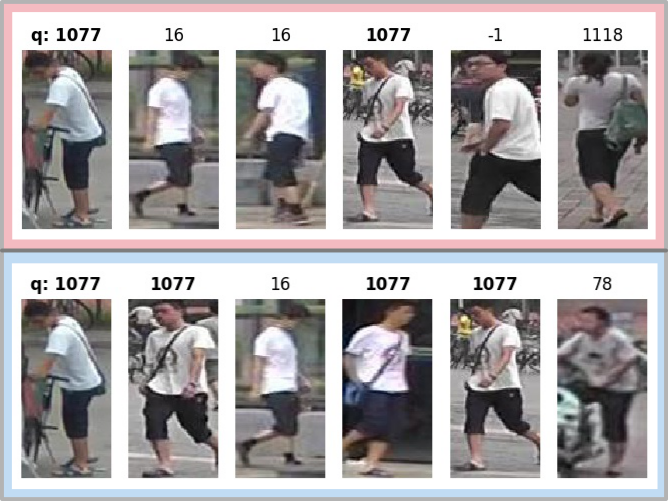 Figure 2
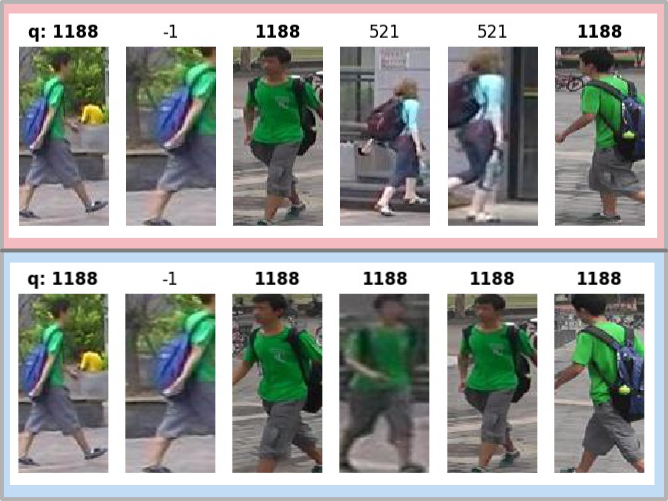 Figure 3
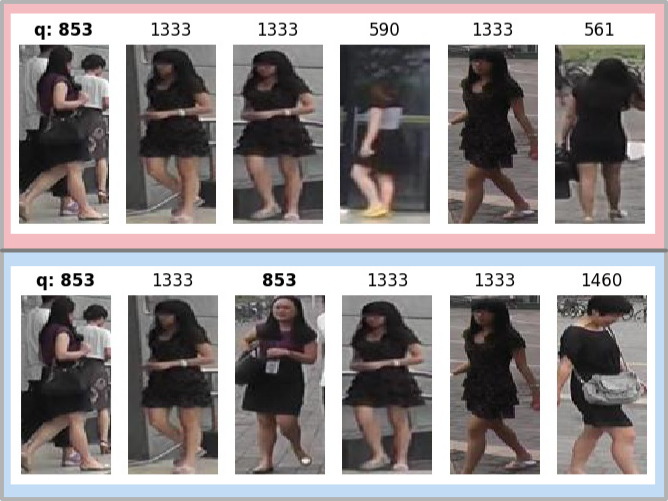 Figure 4
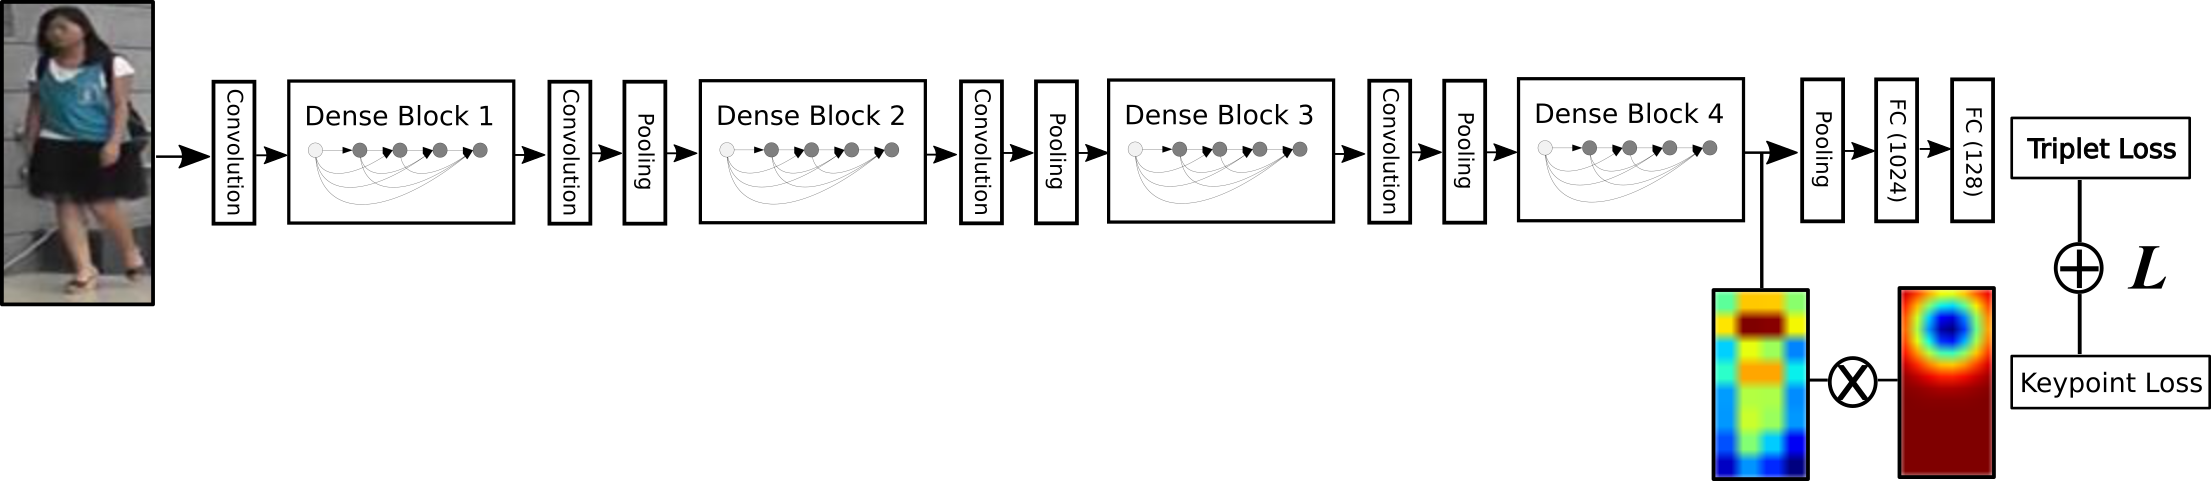 Figure 5
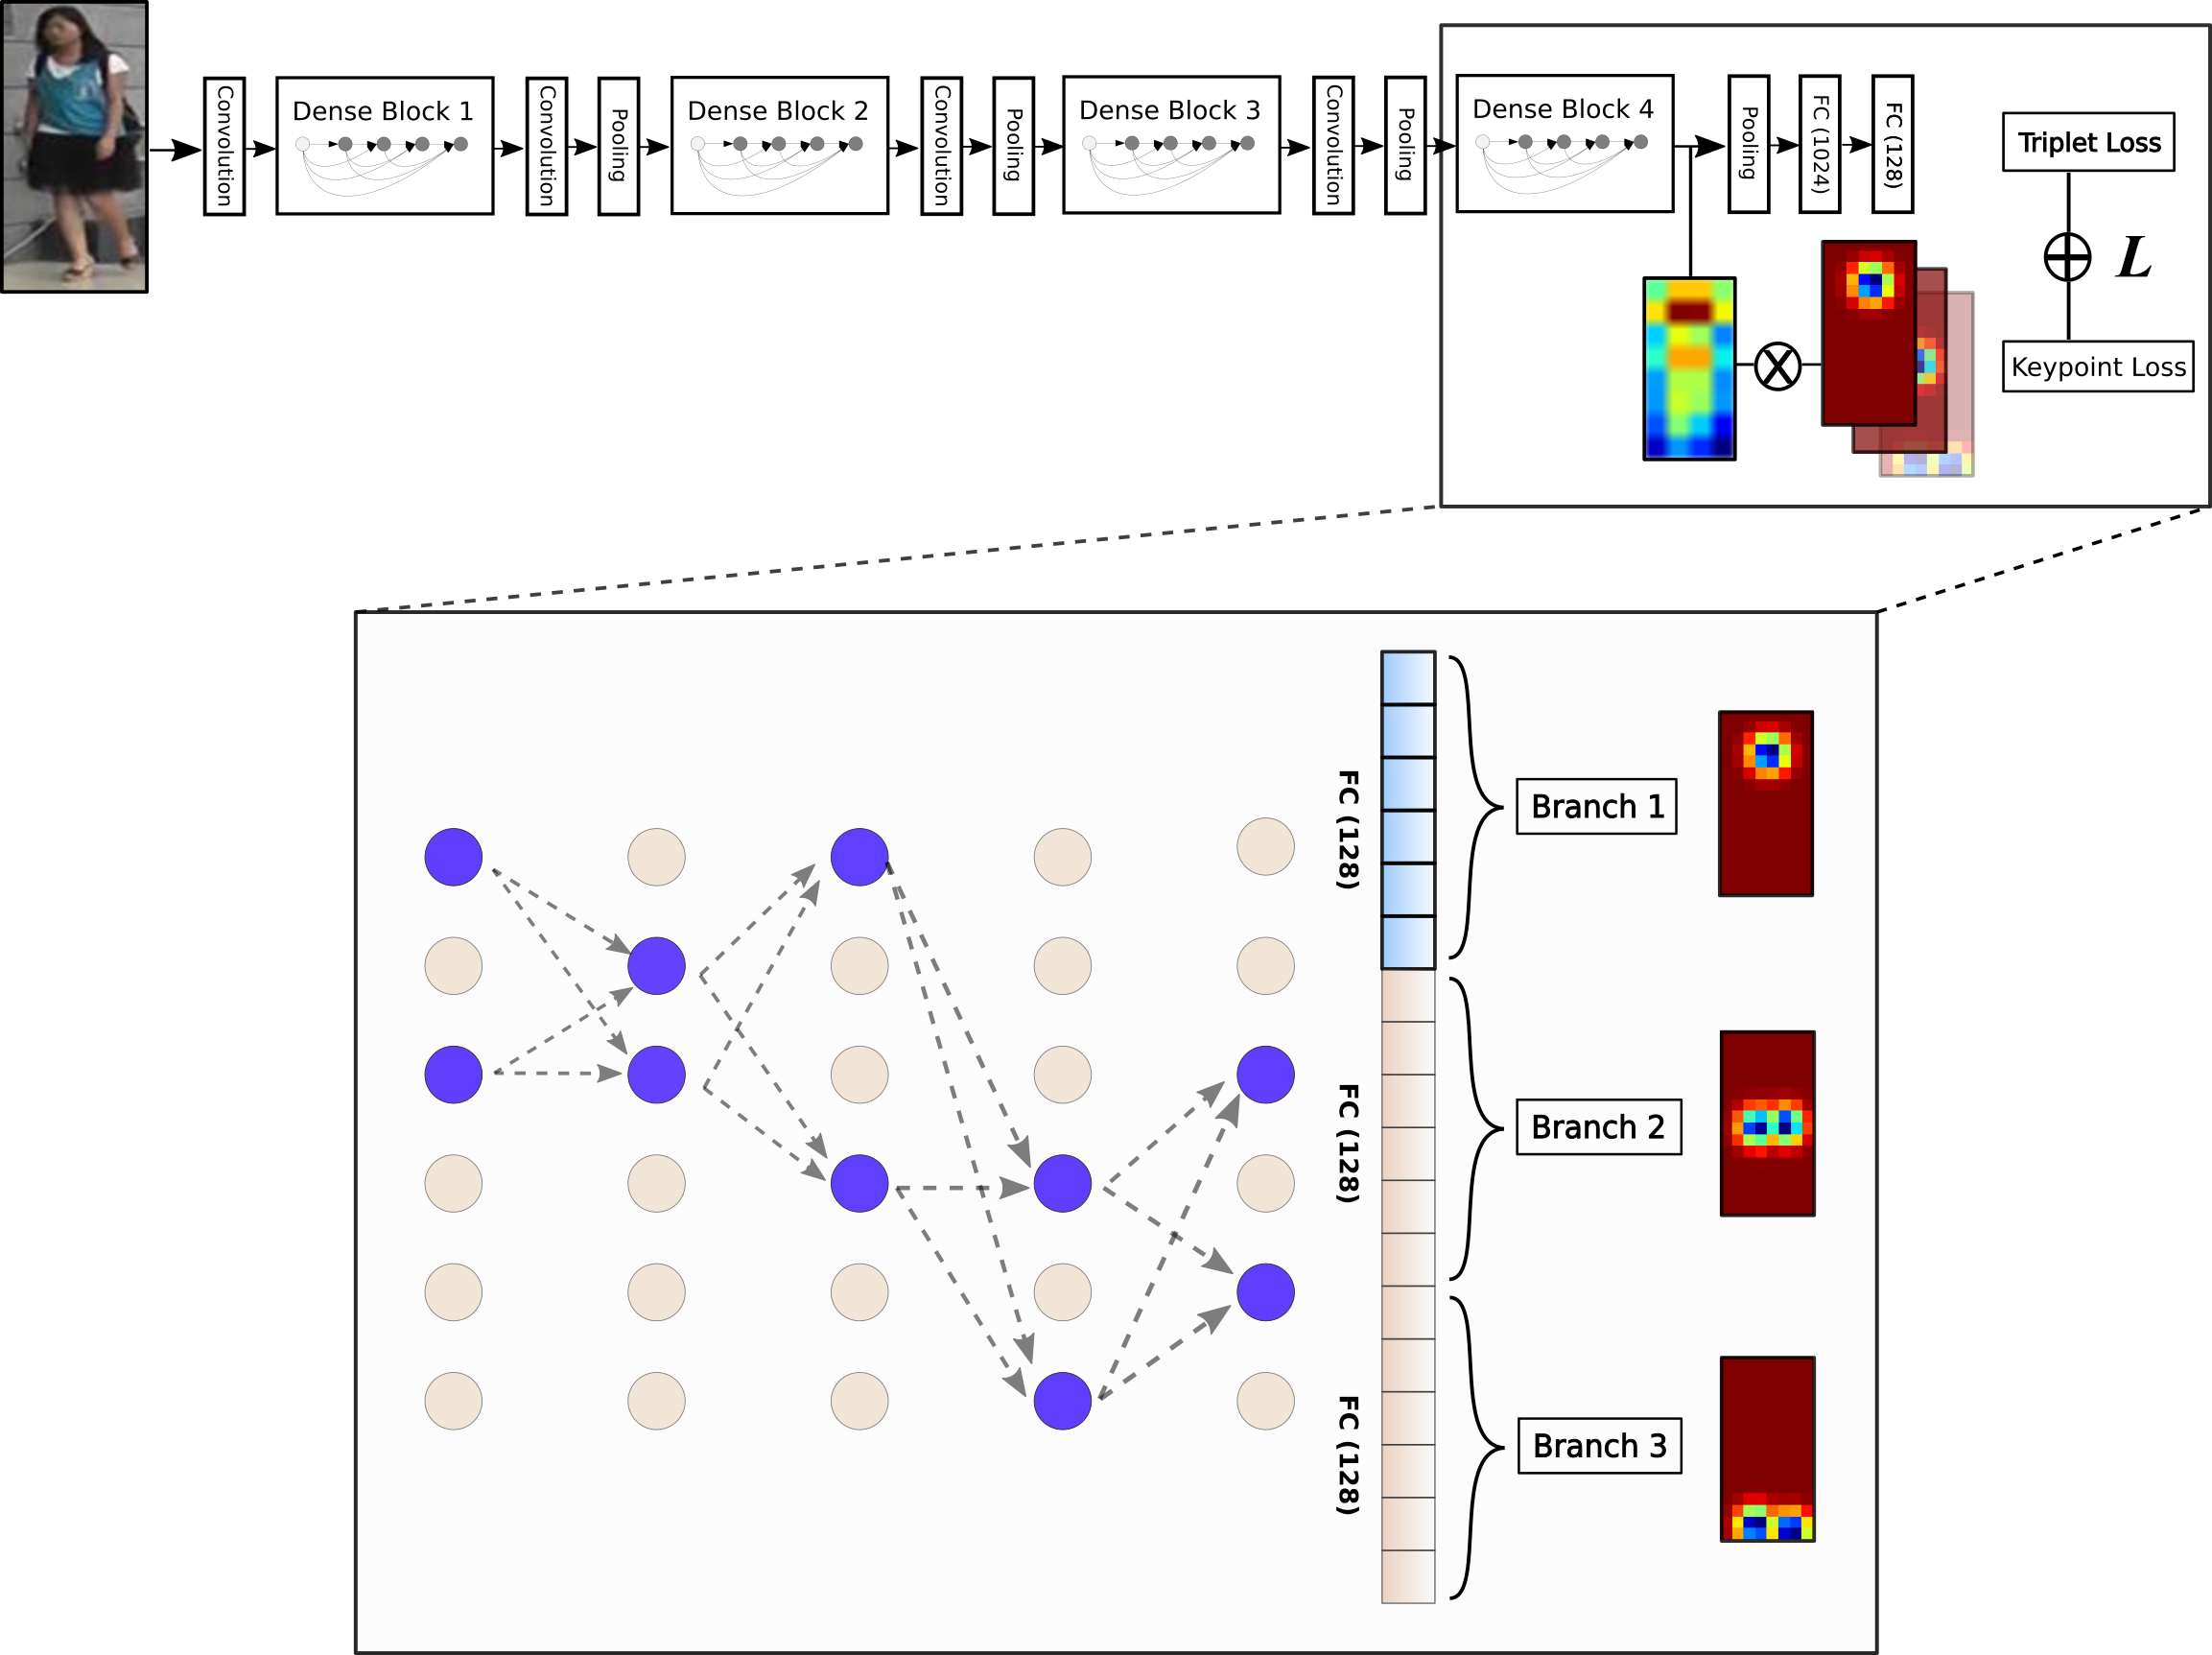 Figure 6
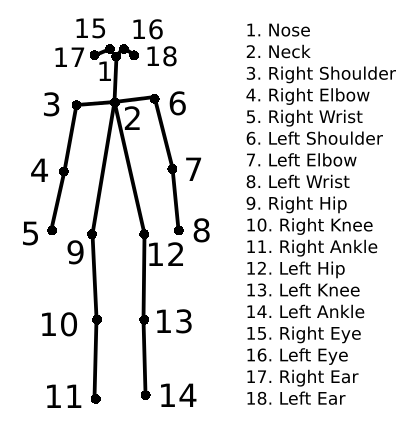 Figure 7
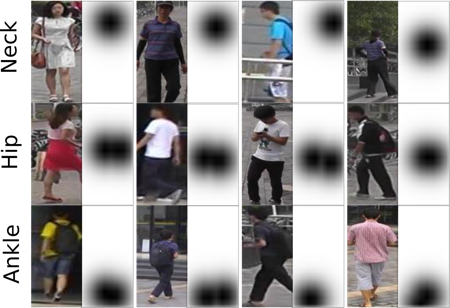 Figure 8
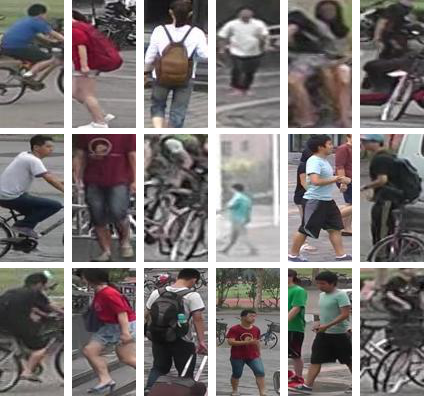 Figure 9
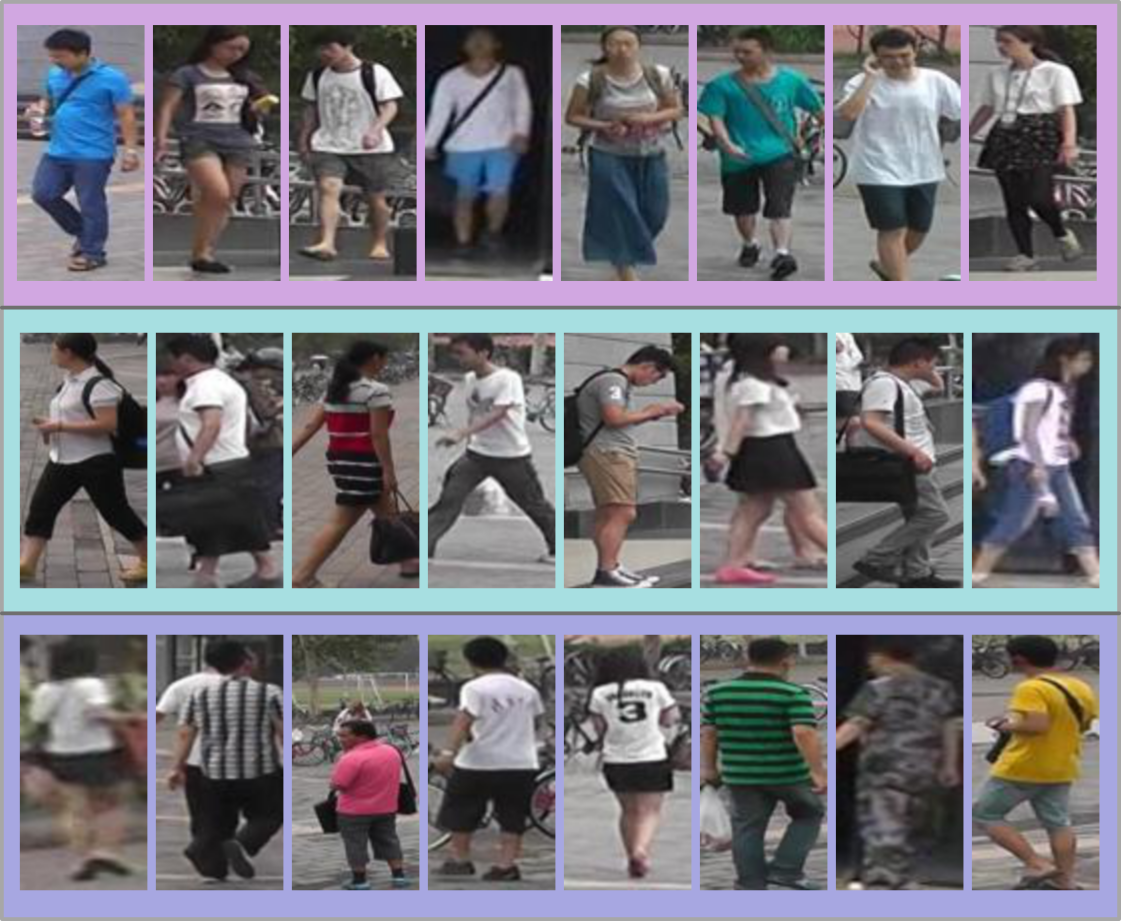 Figure 10
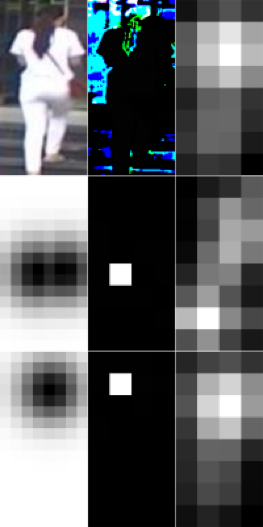 Figure 11
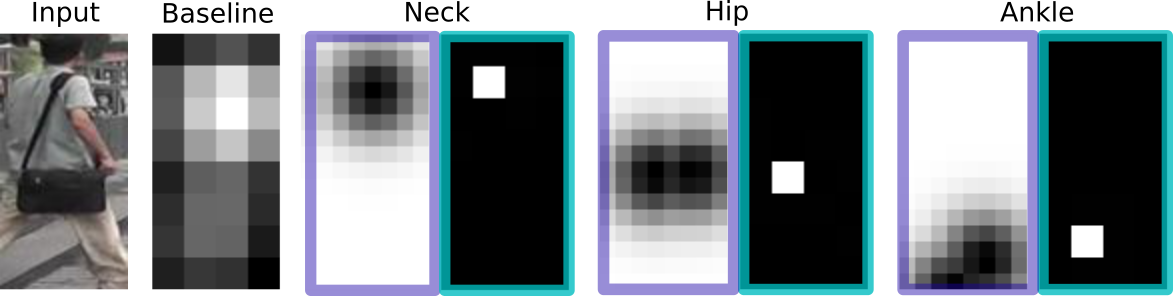 Figure 12
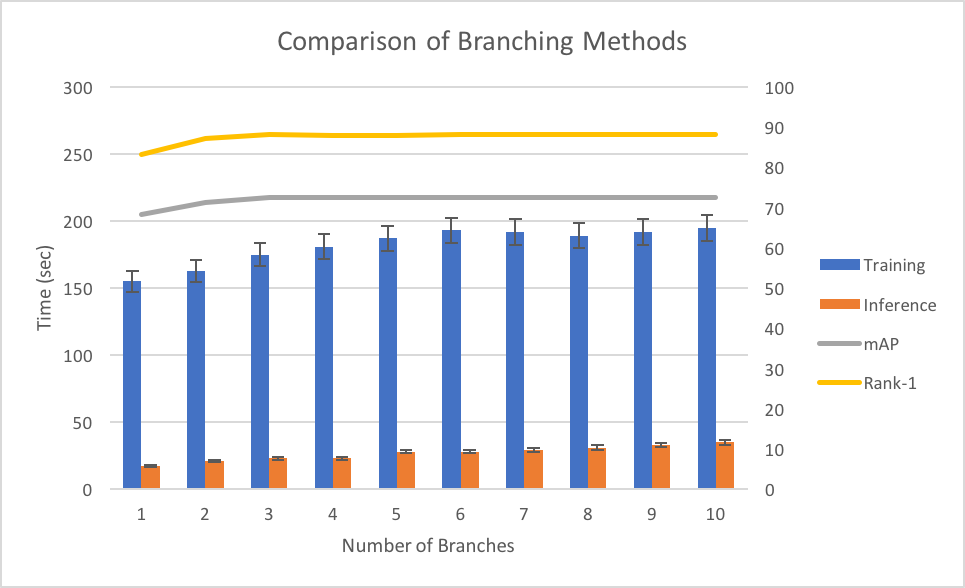 Figure 13
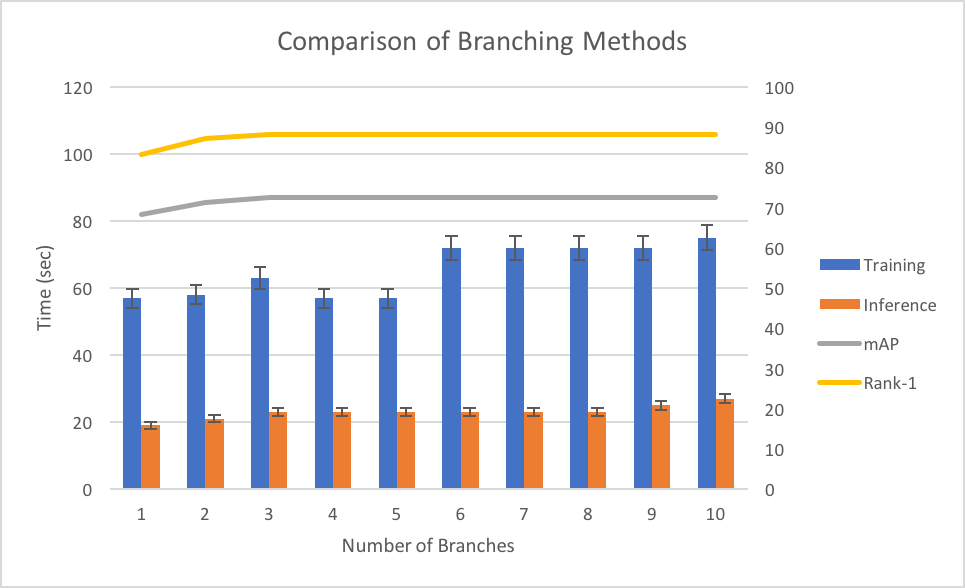 Figure 14
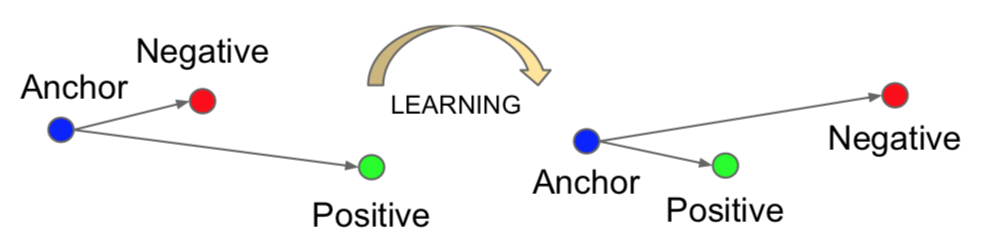 Figure 15
| Single Query | Multi-query | |||||
| Method | mAP | Rank-1 | Rank-5 | mAP | Rank-1 | Rank-5 |
| Gated Siamese CNN [34] | 39.95 | 65.88 | - | 48.45 | 76.04 | - |
| PIE [3] | 53.87 | 78.65 | 90.26 | - | - | - |
| JLML [22] | 65.5 | 85.1 | - | 74.5 | 89.7 | - |
| PAN [3] | 63.35 | 82.81 | - | 71.72 | 88.18 | - |
| Res50 + Attribute [21] | 64.67 | 84.29 | 93.20 | - | - | - |
| GoogLeNet + DTL [20] | 65.5 | 83.7 | - | 73.08 | 89.6 | - |
| PDC [4] | 63.41 | 84.14 | 92.73 | - | - | - |
| SpindleNet [5] | - | 76.9 | 91.5 | - | - | - |
| TriNet [17] | 69.14 | 84.92 | 94.21 | 76.42 | 90.53 | 96.29 |
| MobileNet + DML [35] | 68.86 | 87.73 | - | 77.14 | 91.66 | - |
| Baseline | 68.3 | 83.3 | 93.1 | 75.8 | 90.1 | 95.9 |
| Human Landmark | 70.8 | 87.9 | 96.0 | 79.4 | 93.5 | 98.9 |
| Pose Orientation | 71.1 | 87.7 | 96.5 | 79.3 | 93.3 | 98.5 |
| Labeled | Detected | |||||
| Method | mAP | Rank-1 | Rank-5 | mAP | Rank-1 | Rank-5 |
| Gated Siamese CNN [34] | - | - | - | 51.25 | 61.8 | 80.9 |
| PIE [3] | - | - | - | 67.21 | 61.50 | 89.30 |
| JLML [22] | - | 83.2 | 98.0 | - | 80.6 | 96.9 |
| PAN [3] | 35.03 | 36.86 | 56.86 | 34.00 | 36.29 | 55.50 |
| GoogLeNet + DTL [20] | - | 85.4 | - | - | 84.1 | - |
| PDC [4] | - | 88.70 | - | - | 78.29 | - |
| SpindleNet [5] | - | - | - | - | 88.5 | 97.8 |
| TriNet [17] | - | 89.63 | 99.01 | - | 87.58 | 98.17 |
| Baseline | 93.6 | 88.2 | 99.4 | 92.0 | 86.4 | 98.1 |
| Human Landmark | 95.5 | 91.0 | 99.8 | 94.7 | 88.9 | 99.4 |
| Pose Orientation | 95.8 | 90.9 | 99.6 | 94.5 | 89.3 | 99.4 |
| Method | mAP | Rank-1 | Rank-5 |
| JLML [22] | 56.4 | 73.3 | - |
| PAN [3] | 51.51 | 71.59 | - |
| Res50 + Attribute [21] | 51.88 | 70.69 | - |
| BoW + KissMe [36] | 12.17 | 25.13 | - |
| LOMO + XQDA [37] | 17.04 | 30.75 | - |
| Res50 + LSRO [38] | 47.1 | 67.7 | - |
| SVDNet + Res50 [39] | 56.8 | 76.7 | - |
| Baseline | 55.6 | 74.0 | 83.5 |
| Human Landmark | 58.4 | 76.1 | 85.7 |
| Pose Orientation | 58.2 | 75.7 | 84.3 |
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Code & Models
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
Taxonomy
TopicsVideo Surveillance and Tracking Methods · Human Pose and Action Recognition · Gait Recognition and Analysis
11institutetext: 1North Carolina School of Science and Mathematics,
2Duke University
Virtual CNN Branching: Efficient Feature Ensemble for Person Re-Identification
Albert Gong1
Qiang Qiu2 [email protected]
Guillermo Sapiro2
Abstract
In this paper we introduce an ensemble method for convolutional neural network (CNN), called “virtual branching,” which can be implemented with nearly no additional parameters and computation on top of standard CNNs. We propose our method in the context of person re-identification (re-ID). Our CNN model consists of shared bottom layers, followed by “virtual” branches, where neurons from a block of regular convolutional and fully-connected layers are partitioned into multiple sets. Each virtual branch is trained with different data to specialize in different aspects, e.g., a specific body region or pose orientation. In this way, robust ensemble representations are obtained against human body misalignment, deformations, or variations in viewing angles, at nearly no any additional cost. The proposed method achieves competitive performance on multiple person re-ID benchmark datasets, including Market-1501, CUHK03, and DukeMTMC-reID.
Keywords:
Deep learning, CNN architecture, ensemble learning, person re-identification
1 Introduction
In person re-identification (re-ID), the main goal is to find in a gallery set a matching image with the same identity as a query set. This is a challenging problem due to the potentially large difference between the query and the matching image, such difference resulting from intrinsic changes, e.g., body position, to extrinsic, e.g., viewing angles. Although a complete person re-ID system also involves person detection and person tracking, we use the term person re-ID primarily to refer to the task of person retrieval, which remains an open and heavily studied topic among the computer vision community [1]. In terms of real-world applications, automated person re-ID has great potential, especially within the fields of security, enabling efficient identification of human subjects from images or video data without human intervention. While motivated by this important problem, the overall framework here proposed is expected to have numerous applications, as it will be clear after fully describing it.
We propose a CNN ensemble architecture in Fig. 1 for person re-ID, to improve robustness to human body misalignments, deformations, or orientation variance (Fig. 2). By training several models, each specialized for a different aspect, e.g., a specific body region or pose orientation, we construct a final ensemble whose predictions are more robust against body misalignment, pose deformations or variations in camera angles. Conventional approaches to ensemble deep learning are limited by the computational expense of training multiple deep models and longer inference times during testing. Thus, to make our proposed system usable, an efficient method for implementing ensemble networks is needed that minimizes the number of additional parameters and that can be easily parallelized with limited computational resources, e.g., low GPU memory.
To enable our deep model to exhibit ensemble behavior without adding extra parameters, we introduce the method of “virtual branching.” Since lower-level features are often similar between deep convolutional neural networks, we construct a pseudo-ensemble network by inducing variation only in the top layers of the model, while sharing the low-level features in the bottom layers. Whereas in conventional ensemble learning, each member of the ensemble is often treated as a stand-alone model with information only being shared during the final prediction stage, virtual branching assigns a certain subset of the neurons in the original CNN model to each branch partition. Although no physical connections between neurons are broken, we omit activations of neurons not assigned to the same branch (Fig. 1). Compared to Dropout [2], which is used primarily as a regularization technique, our proposed method fixes the neurons within each branch, and trains each set of neurons using different training data, allowing neurons to develop more specialized features.
We illustrate the capability of the proposed ensemble architecture with two example training schemes, tailored to the person re-ID task. In the first scheme, we extract keypoint locations of select human landmarks, e.g., shoulders, hips, and ankles, to generate heatmaps, which serve as labels to localize each branch to a specific body region, to improve robustness to body misalignments. In the second scheme, we train each branch using subsets of the original dataset comprised of images of people with different pose orientations to improve robustness to different viewing angles. Compared to other person re-ID methods, e.g., [3], [4], and [5], our method does not use a region proposal network and can easily be implemented on existing deep CNN models at little additional computation cost. Our method achieves state-of-the-art performance comparable to current methods on the Market-1501, CUHK03, and Duke-MTMC person re-ID datasets.
The main contributions of this paper can be summarized as follows:
- •
We propose an ensemble deep learning method, called “virtual branching,” that allows a network to exhibit ensemble behavior without additional parameters. Thus, our method does not incur significantly increased computation during both training and testing.
- •
We introduce a localization-inducing loss function component that results in improved alignment of deep features around specific body regions for improved person re-ID performance.
- •
We demonstrate that the proposed method can also produce deep features that are more robust to different pose orientations, i.e., variations in viewing angles.
2 Related Work
2.1 Model Averaging
Conventional ensemble methods, such as bagging [6] and boosting [7], have been shown to improve generalization performance of machine learning methods by combining several diverse models into a single predictor. These early works clearly motivate the design of ensemble CNNs. Recently, Dropout [2] was proposed as a regularization technique to randomly omit neurons in the network, effectively resulting in an exponential number of different neural networks that are averaged into a single deep model. While dropout is one of the responsible techniques for the current success of CNNs, the overall motivation and (semantic) structure is very different than the model here introduced. Opitz et al. [8] proposed a loss function to encourage diversity between individual networks during training for improved ensemble learning. Van der Laan et al. [9] proposed a cross-validation ensemble framework for creating a weighted combination of many candidate learners to build a “super learner,” which Ju et al. [10] demonstrated to outperform many conventional ensemble methods, i.e., unweighted averaging, majority voting. As mentioned before, these methods, which were not developed for re-ID, result in increased cost and lack the semantic tailored architecture here proposed.
2.2 Person Re-Identification
The two main approaches to deeply learned person re-ID algorithms have been (1) to treat person re-ID as a metric learning problem, and (2) to treat person re-ID as a classification problem. Before the release of large-scale person re-ID datasets, e.g., Market-1501 [11], CUHK03 [12], training of deeply learned models was limited to small datasets, e.g., VIPeR [13], i-LIDS [14], each consisting of only a few hundred training images. Thus, instead of a directly-trained identity classifier, a Siamese CNN was adopted to learn the similarity between pairs of images [12], [15]. This approach was expanded to triplets using the triplet loss [5], [16], [17], [18], [19].
Recent research has combined a metric-based identification approach with a classification approach. Geng et al. [20] designed a model consisting of a person re-ID verification subnet that learns a softmax classifier with cross-entropy loss and a pairwise verification subnet that learns whether an input image pair contain the same person. Lin et al. [21] proposed a CNN that learns a re-ID embedding and predicts pedestrian attributes simultaneously using a combined classification loss function.
A common theme among person re-ID research has been to design methods that consider local features, in addition to global features, for improved invariance to confounding variables, such as pose distortion. Li et al. [22] proposed a Joint Learning Multi-Loss CNN model that divides a global feature map into stripes, which are each then convolved further for more localized representations. Zheng et al. [3], [23] applied affine transformations to the input image in order to produce more normalized pedestrian representations. Zhao et al. [5] used a region proposal network as well as tree-structured feature fusion model to incorporate information about the human body. Wang et al. [24] focused on the vehicle re-ID task, and uses output response maps from a region proposal module to produce orientation invariant feature embeddings. As we will show later in this paper, the simple ensemble method here introduced outperforms all these approaches without increasing the cost of existing CNNs.
3 Methodology
In this section, we illustrate in detail the virtual branching architecture, to enable ensemble behavior without adding extra parameters to the baseline CNN model. To demonstrate its capability to allow virtual branches being trained differently, we then present two example training schemes for the person re-ID task. In the first scheme, we use human landmarks to localize each virtual branch to a specific body region, to address challenges such as body misalignments, deformation, and occlusion, etc. In the second scheme, we train each branch using subsets with different pose orientations to improve robustness to different viewing angles.
3.1 Virtual Branching
To construct our model, we assign neurons in the baseline CNN to specific partitions, which we call “branches.” Let be the set of neurons in the -th branch. Each neuron represents a convolutional filter in a convolutional layer, and a fully-connected unit in a fully-connected layer. Further, let be the set of neurons in the -th layer of the model, and be the subset of in . Thus,
[TABLE]
Let be the number of “branches” in the model. Thus, each layer in the network (except the input layer) to which “virtual branching” is applied has outputs. During both testing and training, we multiply the -th output of neuron in the -th layer by the constant, :
[TABLE]
for all . To select the neurons for each branch, we define the hyperparameter,
[TABLE]
to represent the degree of parameter sharing, where is the number of neurons in the -th layer that is common among all branches and is the number of neurons in the -th layer that is unique to each branch. Let be the number of total neurons in the -th layer, i.e., last dimension of the output of the -th layer. Thus,
[TABLE]
[TABLE]
when ; and , , when . In general, we set to include the neurons , where , regardless of pre-initialized weights.
3.1.1 Architecture
We initialize our model using the DenseNet architecture [25] pre-trained on the ImageNet dataset [26]. Since person re-ID datasets are relatively small, only containing several thousands of samples, models trained on larger datasets, such as ImageNet [26], contain knowledge that may be common to more specific domains or tasks. As done by Hermans et al. [17], we discard the final classification layer and add two fully-connected (FC) layers for our task; the first FC layer having 1024 units, followed by a batch normalization layer [27] with ReLU activation [28]; the second FC layer having 128 units and also serving as the final feature embedding.
Specifically for the DenseNet archiecture, we apply a drop mask layer after every convolutional and fully-connected layer in the last block [25]. In image classification, a common challenge is determining the relative weights of predictions from multiple models. By treating person re-ID as a metric learning problem, we simply concatenate the embeddings from each branch after discarding the outputs from masked neurons to form the final embedding.
3.2 Human Landmark Localization
We localize the features of each branch around specific human body regions in order to improve feature robustness to challenges such as body misalignments. deformation, and occlusion. More specifically, we train each branch as a regressor in addition to the baseline identification task. Thus, this implementation essentially serves as a multi-task learning scenario. We generate separate heatmaps for the neck and hip regions and use the heatmaps as labels during training. Without loss of generality, let represent the location of some given keypoint. Thus, we define the corresponding heatmap, as
[TABLE]
where . For the hip and ankle regions, we take the element-wise maximum of the heatmaps for the right and left body parts in order to reduce the number of branches for training.
3.2.1 Localization-inducing Loss Component
In order to localize the feature embeddings of each branch around certain human body regions, we penalize activations produced by the layer just before the final global average pooling layer according to the respective body region heatmaps. Specifically, let be the output of the final layer before the global average pooling operation for an input image, , where is the output height, is the output width, and is the number of output “channels.” In order to calculate the value of the localization-inducing loss component, , we first compute the channel-wise average, :
[TABLE]
We then normalize such that ,
[TABLE]
[TABLE]
Without loss of generality, let (Eq. 4) be the corresponding keypoint heatmap for the input image, , for some body region, , i.e., neck, hips, or ankle. Note that the dimensions of the heatmap, i.e., , are not necessarily equal to the dimensions of the output activation map, , in which case bilinear interpolation is used to scale the activation to the dimensions of the heatmap. However, for the purposes of this paper, we use . Next, we define the localization-inducing loss function component:
[TABLE]
where is some set of model parameters and is the training batch. The final loss function is then a weighted sum of the baseline triplet loss, (Eq. 6), and the localization-inducing loss component:
[TABLE]
where is some hyperparameter constant. For all experiments with the localization-inducing loss function component, we set to have an appropriate balance between training of the baseline identification and body-region localization tasks.
3.3 Pose Orientation
We also train each branch according to specific pose orientations, i.e., viewing angles, whereby each branch is trained on disjoint subsets of the training data, comprised of images of people taken from frontal, side, and back views (Fig. 4). Essentially, we treat the training scenario as a multi-domain learning task, i.e., each pose orientation is a distinct domain. Thus, our model has three inputs, one for each data subset. We then train each branch using the baseline triplet loss (Section 3.4).
To determine the orientation of a person within an image, we extract human keypoint information using a pose estimation algorithm, e.g., OpenPose [29]. Specifically, we select the locations, of the right shoulder (RS), left shoulder (LS), right hip (RH), and left hip (LH): such that represents the top-left corner of an image. We then determine the angle of rotation as: \theta\approx cos^{-1}\Big{(}\frac{\mu D(k_{RS},k_{LS})}{\frac{1}{2}(D(k_{RS},k_{RH})+D(k_{LS},k_{LH}))}\Big{)}, where is the 2D Euclidean distance and , used to distinguish between images of people facing forward and people facing backward. Each image with orientation angle is assigned to its respective training subset ,
[TABLE]
3.4 Baseline Loss
For all of the models, we use a triplet loss baseline, which aims to “pull together” input images from matching identities while “pushing away” input images from different identities. Thus, we learn a mapping , for some set of parameters , such that semantically similar points in the input domain , are metrically close in the embedding vector space , and analogously semantically different points in are metrically distant in .
We employ the batch-hard variant of the triplet loss [17], which results in triplets that are more informative than trivially-chosen triplets. To construct a training batch, we randomly select person identities, then randomly sample images from each identity. We calculate the triplet loss, , by selecting the hardest positives, , and the hardest negatives, , within each batch, X:
[TABLE]
[TABLE]
[TABLE]
where is the anchor point, is the positive point, and is the negative point. We use the norm as the distance measure, , and as the hinge function, for some constant . For all experiments, we use due to its good performance [17].
4 Experiment Setup
4.1 Datasets
To evaluate our proposed method, we select Market-1501 [11], CUHK03 [12], and DukeMTMC-reID [30], three large-scale person re-ID datasets, each comprised of images taken by an array of multiple cameras at university campuses. The large scale and use of automatic detection (for Market-1501 and CUHK03), which introduces increased image misalignment, allow these datasets to be more realistic compared to smaller person re-ID datasets.
4.1.1 Market-1501.
This dataset contains 32,668 images of 1,501 identities. We use the provided training/testing split with 12,936 training images across 750 identities and 19,732 testing images across 751 identities. Following the evaluation protocol specified by Zheng et al. [11], we calculate the cumulative match score (CMC) and mean average precision (mAP) metrics to evaluate the performance of our models.
4.1.2 CUHK03.
This dataset contains 14,097 images of 1,467 identities. For evaluation, the dataset provides 20 test sets, each with 100 identities. For each set, we use the 100 identities for testing and the rest 1,367 identities for training. We report the averaged performance after repeating the experiments for 20 times. We follow standard evaluation protocols to calculate CMC and mAP scores. This evaluation process is repeated for 100 times and the mean value is reported as the final result [12].
4.1.3 DukeMTMC-reID.
This dataset is a subset of Duke-MTMC [30] for image-based re-ID in the format of the Market-1501 dataset and is comprised of 36,411 images across 1,812 different identities from eight camera angles, where 1,404 identities appear in more than two cameras and the other 408 identities are considered distractor IDs. Among the 1,404 identities, 16,522 images of 702 identities are used for training, and the other 702 identities are divided into 2,228 query images and 17,661 gallery images.
4.2 Training Implementation
All of our models are trained using the Keras deep learning library (version 2.0.8) with TensorFlow [31] (version 1.3.0) backend on a single NVIDIA K80 GPU (12 GB). Due to memory constraints, we set and when generating training data batches. Additionally, we use the Adam optimizer [32] with , , , and .
4.2.1 Data Pre-processing.
We find that simply resizing the input images yields best performance. For transfer learning on pre-trained ImageNet models, we noticed that using an input resolution similar to that of the pre-trained model yields the best results, likely because the pre-trained features are optimized for a certain scale. Thus, we set input images to resolution for Market-1501 and DukeMTMC-reID and resolution for CUHK03.
4.2.2 Learning Rate Schedule.
To train our models, we use a decaying learning rate: at epoch . We noticed that using the floor function yields the best performance by stabilizing the training. We train our models for 150 epochs, setting , with 100 steps per epoch.
4.3 Testing Implementation
Following common practice [17, 33], we average the embeddings from horizontal flips of the original input image, yielding noticeable performance gains at the cost of acceptable increases in computation. As a distance measure between embeddings, we employ the Euclidean distance. After initial inference, the computations of the CMC and mAP metrics can easily be parallelized for reduced testing times.
5 Experimental Results
Performance comparisons on person re-ID benchmarks are reported in tables 1, 2, and 3. Our baseline model already outperforms many of the other previously published methods, due in part to the use of the batch-hard variant of the triplet loss [17]. Although our baseline achieves marginally worse performance compared to TriNet [17], which uses the same triplet loss function, our model uses significantly less parameters (8.2M) due to the use of the DenseNet architecture [25], compared to TriNet (25.8M parameters), which uses the ResNet-50 architecture [40].
We immediately compensate for this slight performance drop using our proposed virtual branching method, which incorporates the Human Landmark and the Pose Orientation as introduced before. On average, we report a 3-4% improvement over the baseline model on the Market-1501, CUHK03, and DukeMTMC-reID datasets. Our method exceeds or achieves comparable performance with current state-of-the-art methods on these datasets in terms of mAP and CMC rank-1 and rank-5 score.
We see that training each virtual branch using human landmark information achieves similar performance gains compared to training each virtual branch using pose orientation information. These results support our claim that combining several specialized models results in better overall performance. Furthermore, our proposed method provides an alternative to previous pose alignment methods, e.g., [3, 4, 5], using region proposal networks or input-level transformations.
5.1 Branching
We compare models with varying numbers of branches and degrees of parameter sharing within each layer, defined by the hyperparameter (Eq. 1). Only varying the number of branches, we notice that the performance increases significantly with the addition of several branches, but quickly experiences diminished returns since the number of neurons in each layer for each branch decreases as the number of branches increases (eqs. 2 and 3). However, even with significantly less neurons than in the baseline model for the last few layers (i.e., 20-30%), each branch is still able extract informative deep features. Additionally, the performance tends to increase as the degree of parameter overlap decreases. One possible explanation is that increasing the level of parameter sharing decreases the same level of induced variation that improves ensemble performance.
We analyze the effects of our ensemble method on training and inference times (Fig. 5). Theoretically, we should only see modest increases in computation times; although the use of branching should increase the number of operations per forward pass, branching only occurs in the top few layers and involves relatively few branches.
5.2 Localization
We verify that our proposed method indeed encourages the models to localize around their corresponding human body regions. Recall that the localization-inducing loss function component penalizes against activations that are far away from the central keypoints (Section 3.2); we therefore expect that the activation map to which the localization-inducing loss is applied will have high response around the corresponding body region and low response elsewhere. Looking at the normalized mean output activations (defined in Section 3.2), we see that the activations indeed are more concentrated around the corresponding body regions, Fig. 6.
5.3 Feature Robustness
We also examine the robustness effect of the proposed ensemble features with landmark localized branches. Looking at examples of rankings for image retrieval (Fig. 7), we see that the proposed branching method indeed helps the deep model to become more robust to variability in misalignment, pose deformation, occlusions, and other expected diversity in the re-ID challenges. Overall, these improvements lead to better performance on the entire testing set, in terms of mAP and rank-1 (tables 1, 2, 3).
6 Conclusions
In this paper, we proposed “virtual branching,” an ensemble method for person re-ID. The novel architecture enables the deep model to exhibit ensemble behavior without significantly increased computation during training and testing. Specifically for the task of person re-ID, we train each branch according to different body regions and pose orientations and achieve state-of-the-art performance on several benchmark person re-ID datasets, i.e., Market-1501, CUHK03, and DukeMTMC-reID. The application of the proposed framework to other datasets and tasks is currently under investigation.
Acknowledgments
Work partially supported by NSF, NIH, ONR, NGA, and ARO.
The reference list from the paper itself. Each links out to its DOI / PubMed record.
- 1[1] Zheng, L., Yang, Y., Hauptmann, A.G.: Person re-identification: Past, present and future. ar Xiv:1610.02984 (2016)
- 2[2] Srivastava, N., Hinton, G., Krizhevsky, A., Sutskever, I., Salakhutdinov, R.: Dropout: A Simple Way to Prevent Neural Networks from Overfitting. Journal of Machine Learning Research 15 (2014) 1929–1958
- 3[3] Zheng, L., Huang, Y., Lu, H., Yang, Y.: Pose invariant embedding for deep person re-identification. ar Xiv:1701.07732 (2017)
- 4[4] Su, C., Li, J., Zhang, S., Xing, J., Gao, W., Tian, Q.: Pose-driven Deep Convolutional Model for Person Re-identification. International Conference on Computer Vision (ICCV) (2017)
- 5[5] Zhao, L., Li, X., Zhuang, Y., Wang, J.: Deeply-learned part-aligned representations for person re-identification. International Conference on Computer Vision (ICCV) (2017)
- 6[6] Breiman, L.: Bagging predictors. Mach. Learn. 24 (2) (August 1996) 123–140
- 7[7] Friedman, J.H.: Greedy function approximation: A gradient boosting machine. The Annals of Statistics 29 (5) (2001) 1189–1232
- 8[8] Opitz, M., Possegger, H., Bischof, H.: Efficient Model Averaging for Deep Neural Networks. Asian Conference on Computer Vision (ACCV) (2016)