Gaussian Processes Over Graphs
Arun Venkitaraman, Saikat Chatterjee, Peter H\"andel

TL;DR
This paper introduces Gaussian processes tailored for signals on graphs, leveraging graph Laplacian regularization to improve prediction accuracy, especially with limited or noisy data, by enforcing specific spectral properties.
Contribution
It develops a novel Gaussian process framework over graphs that incorporates spectral regularization, reducing predictive variance compared to traditional GPs.
Findings
GPG has strictly smaller predictive variance than standard GP.
GPG outperforms GP with small training datasets.
GPG demonstrates robustness under noisy training conditions.
Abstract
We propose Gaussian processes for signals over graphs (GPG) using the apriori knowledge that the target vectors lie over a graph. We incorporate this information using a graph- Laplacian based regularization which enforces the target vectors to have a specific profile in terms of graph Fourier transform coeffcients, for example lowpass or bandpass graph signals. We discuss how the regularization affects the mean and the variance in the prediction output. In particular, we prove that the predictive variance of the GPG is strictly smaller than the conventional Gaussian process (GP) for any non-trivial graph. We validate our concepts by application to various real-world graph signals. Our experiments show that the performance of the GPG is superior to GP for small training data sizes and under noisy training.
Click any figure to enlarge with its caption.
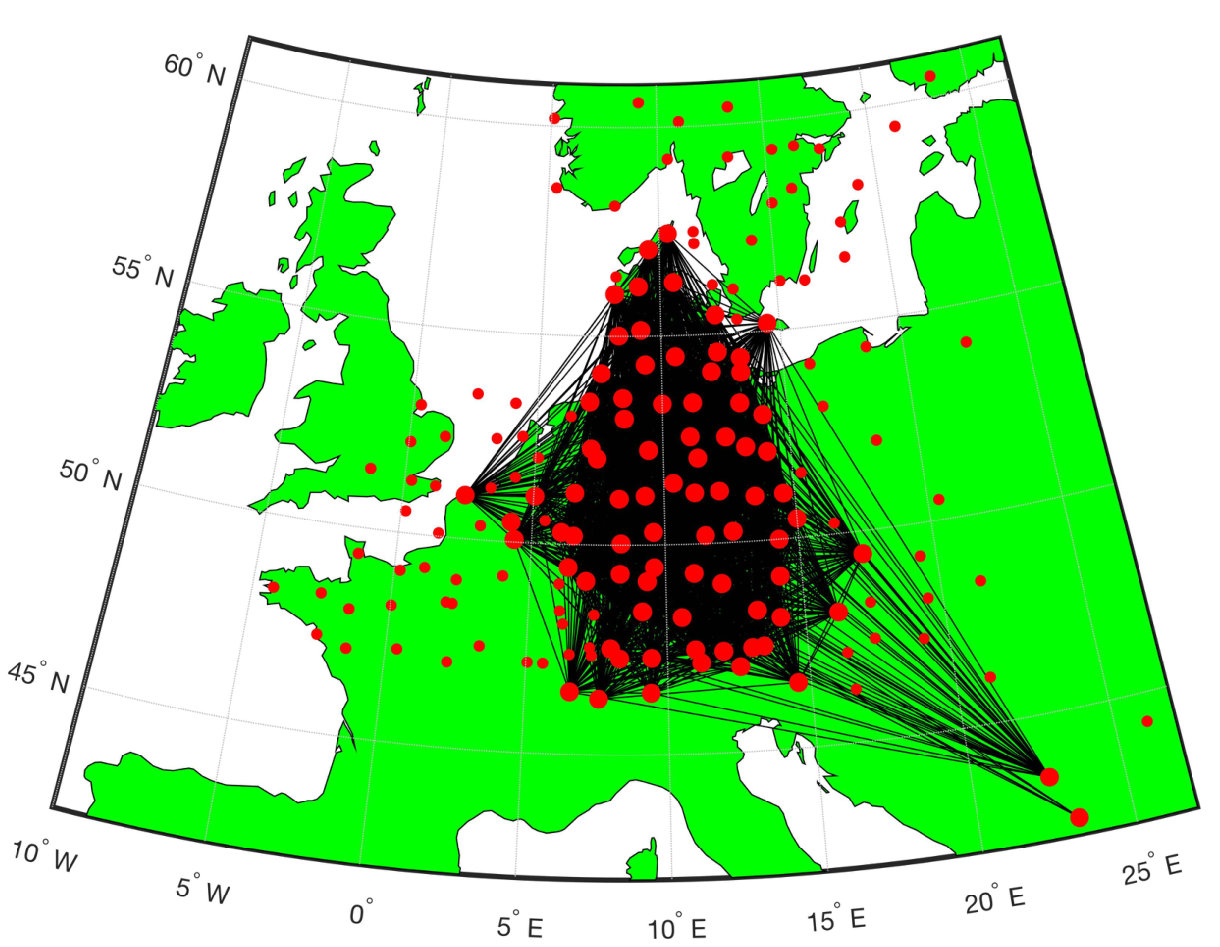 Figure 1
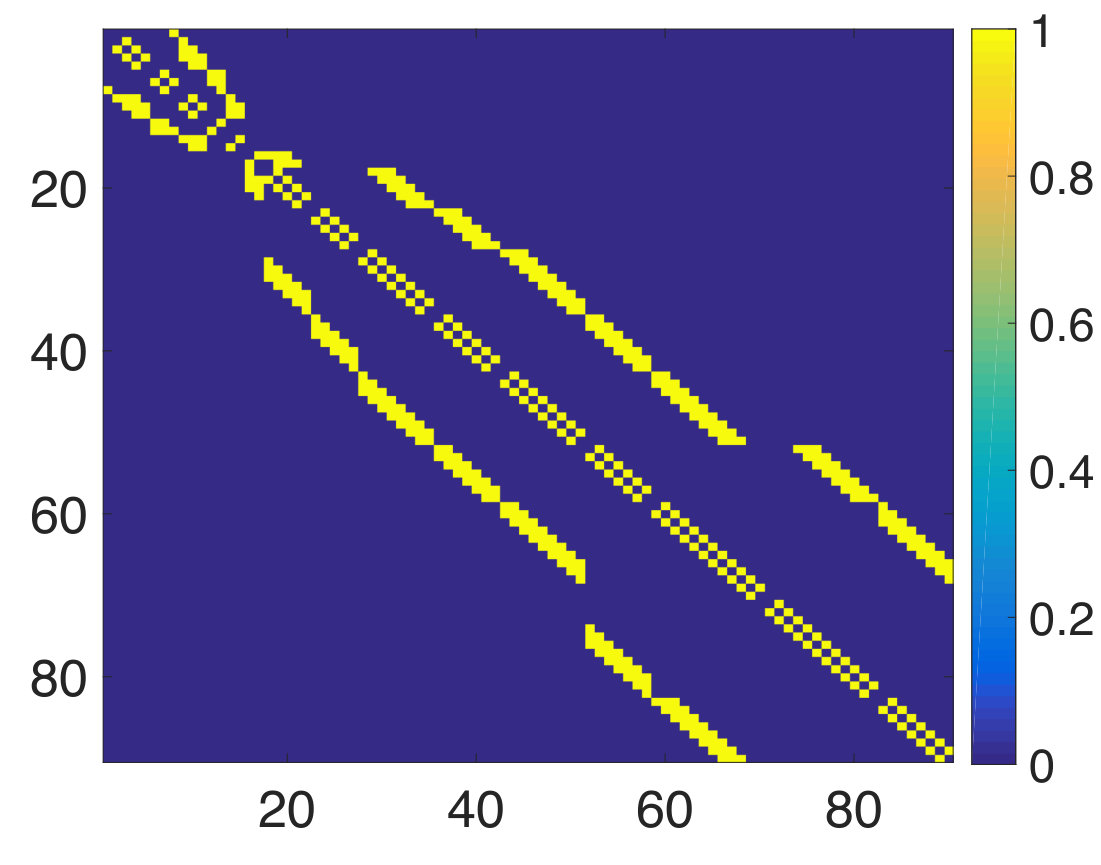 Figure 2
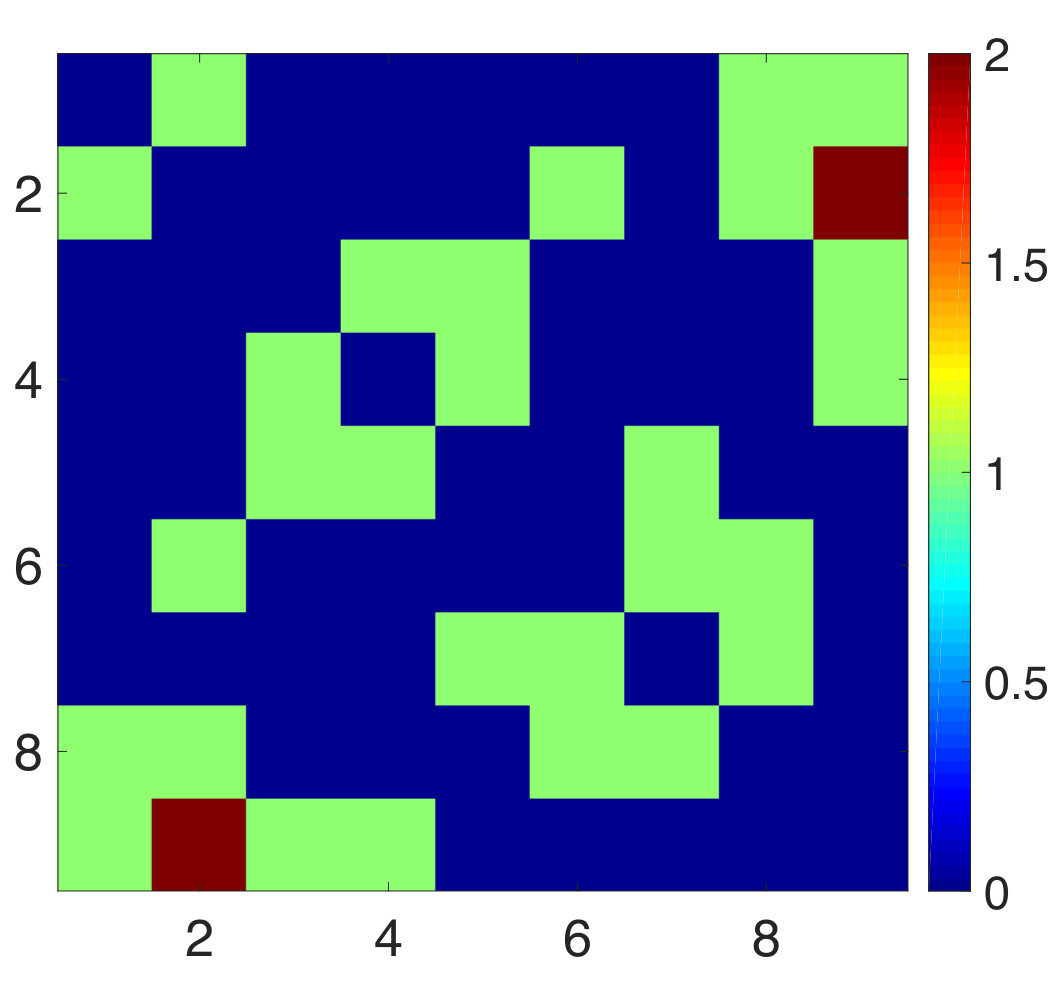 Figure 3
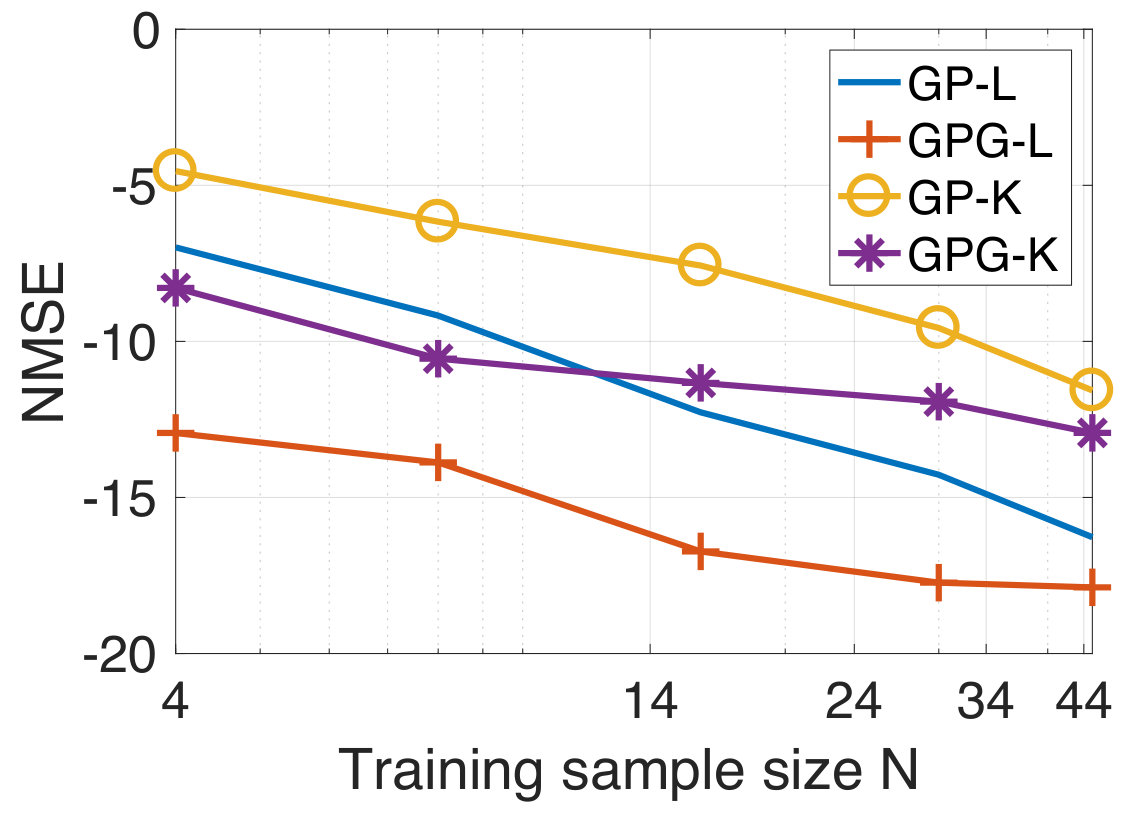 Figure 4
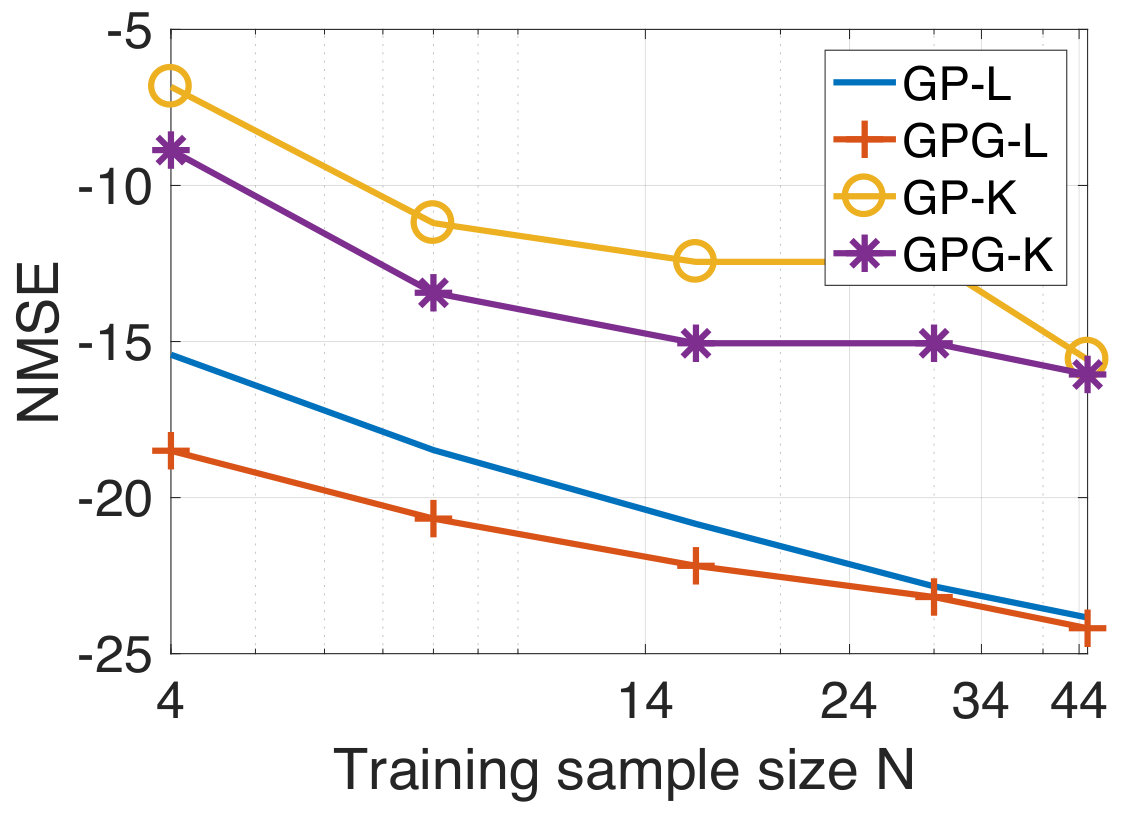 Figure 5
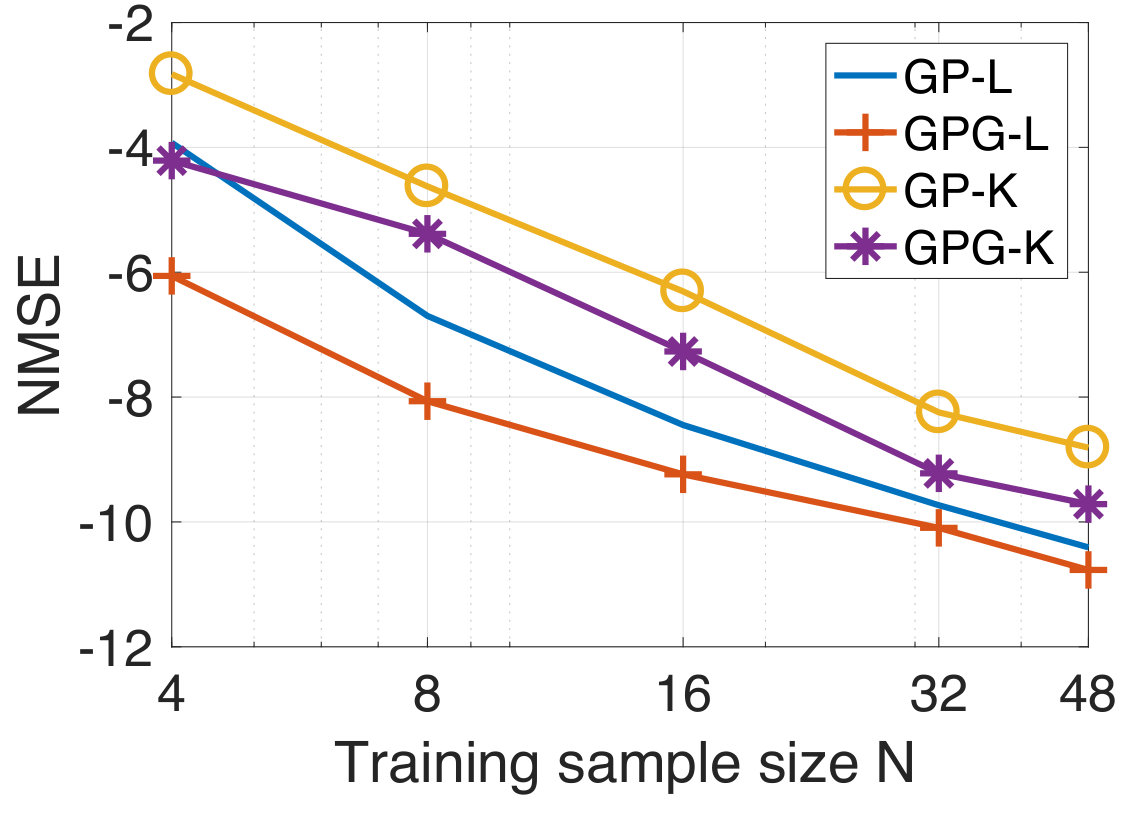 Figure 6
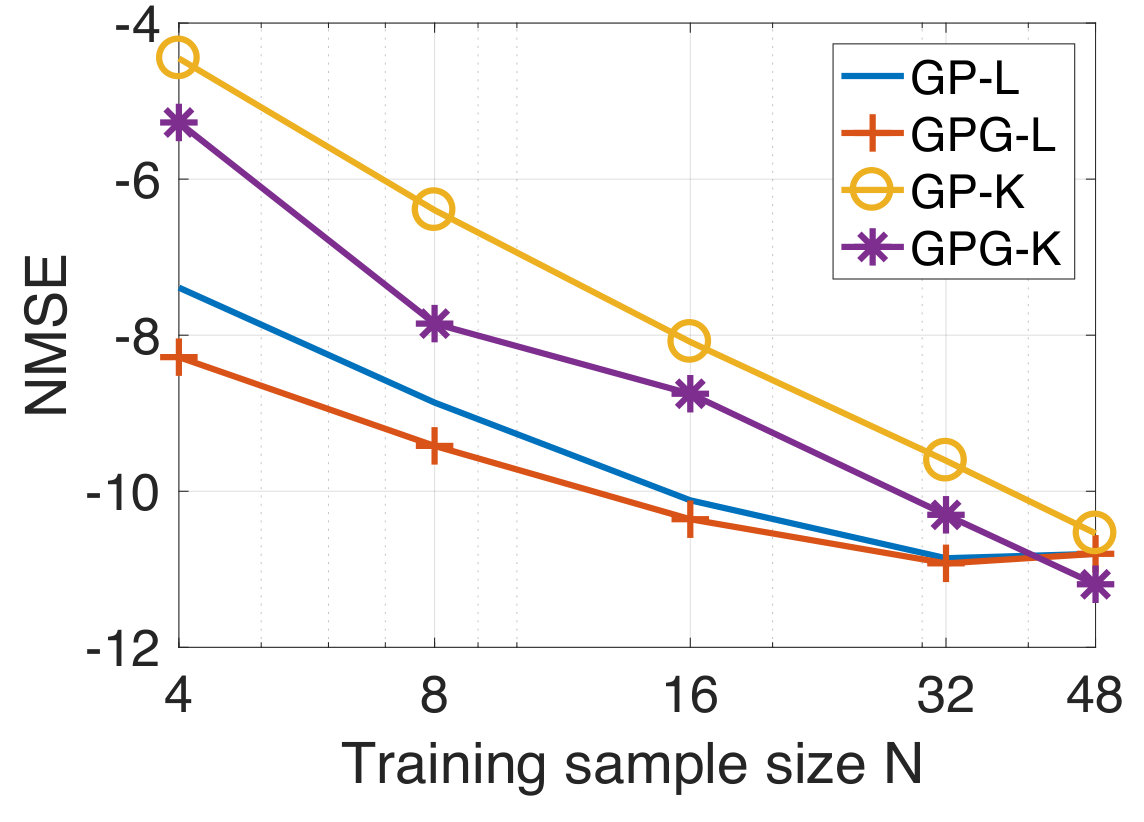 Figure 7
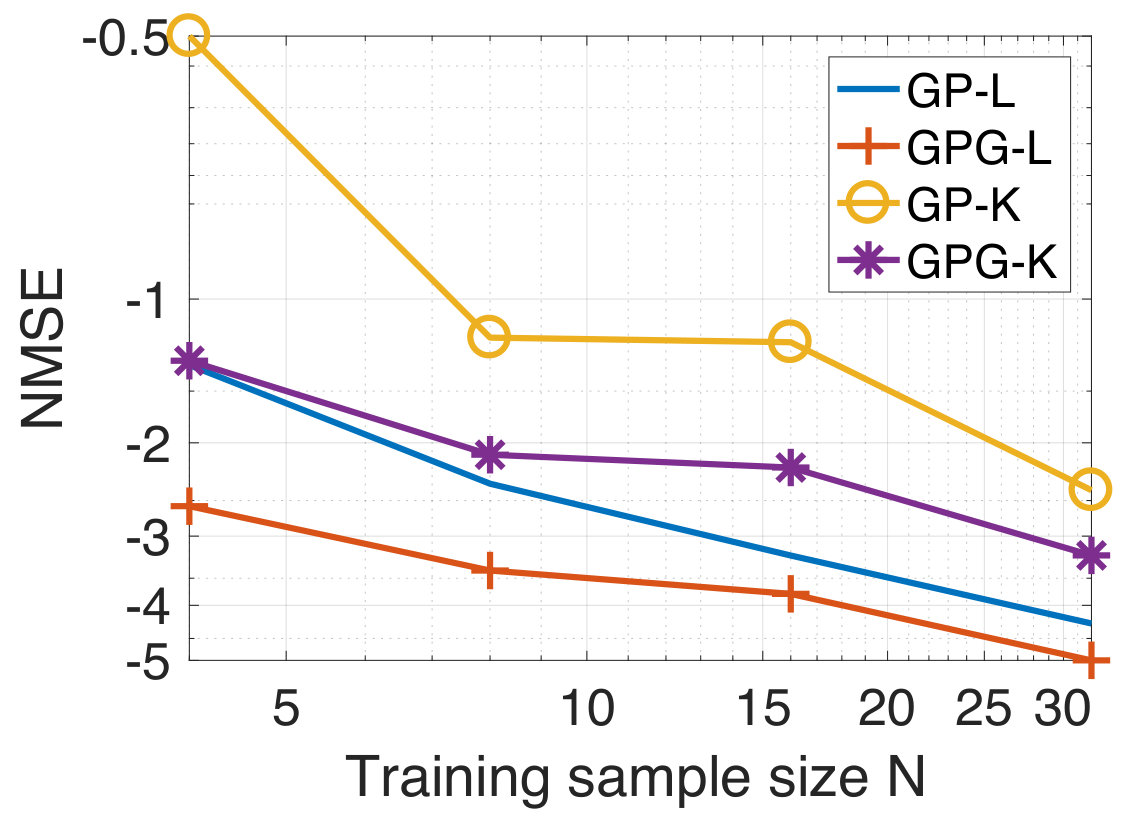 Figure 8
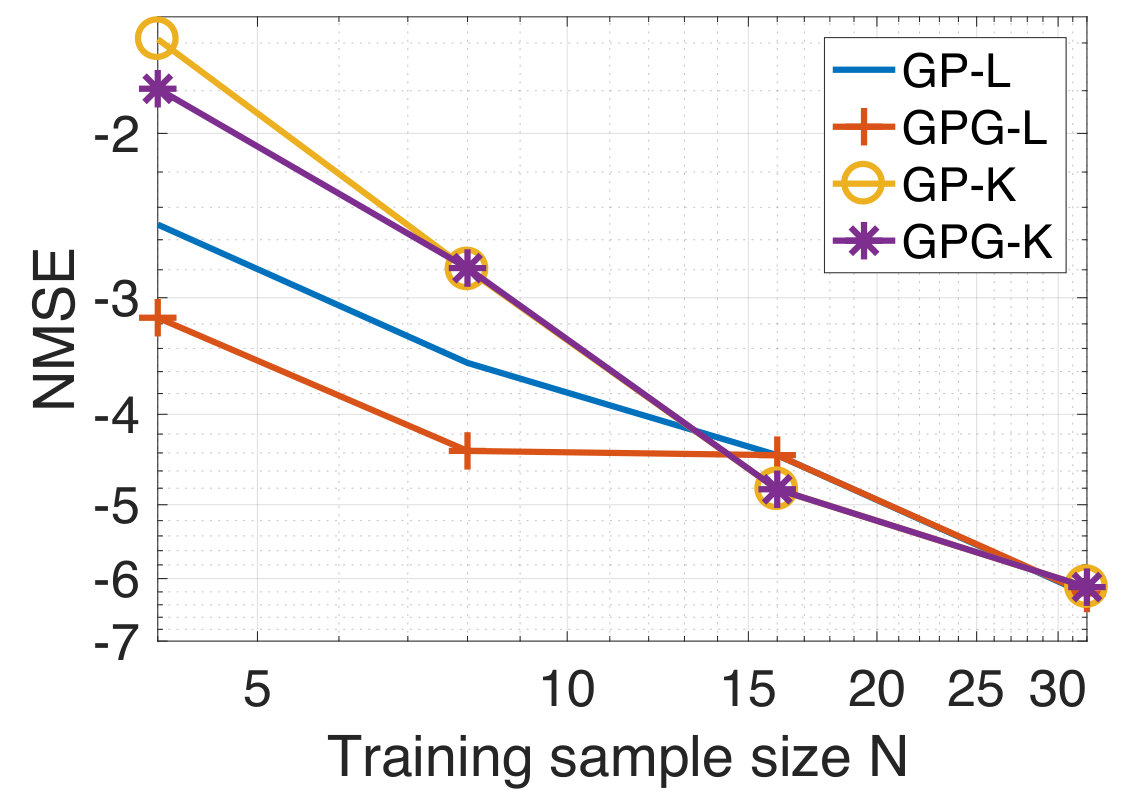 Figure 9
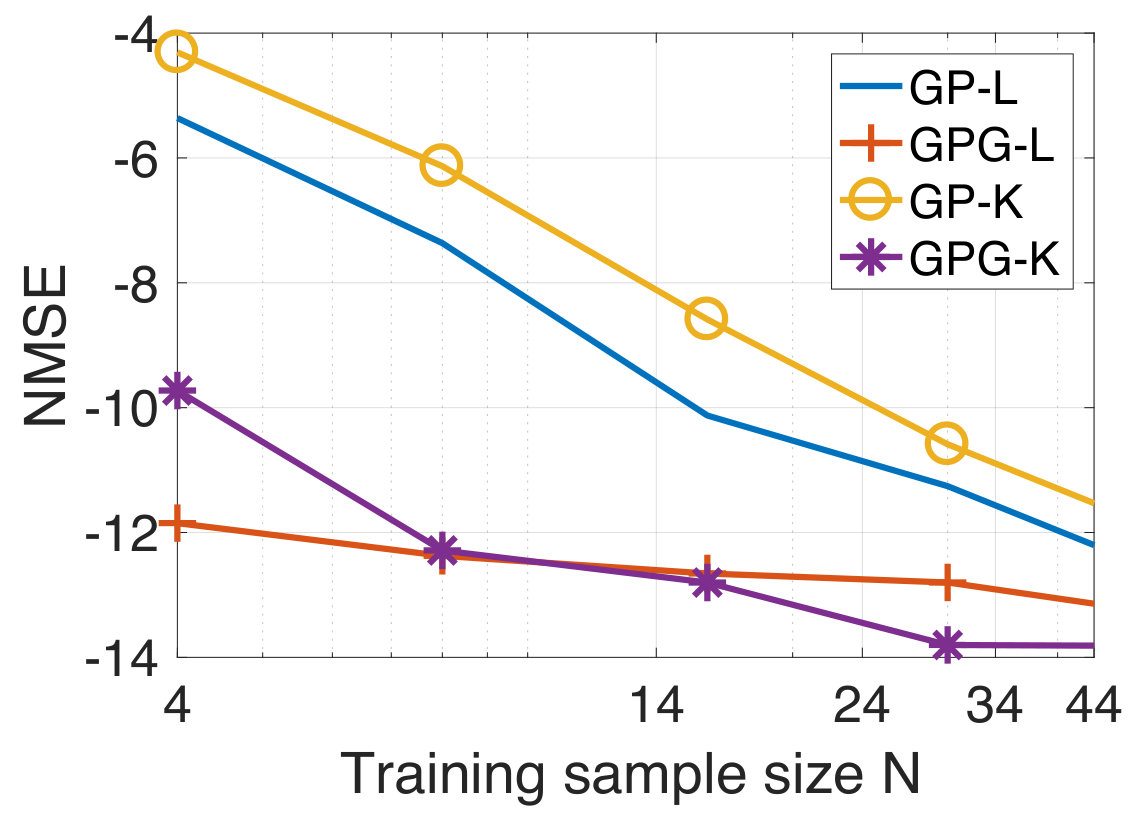 Figure 10
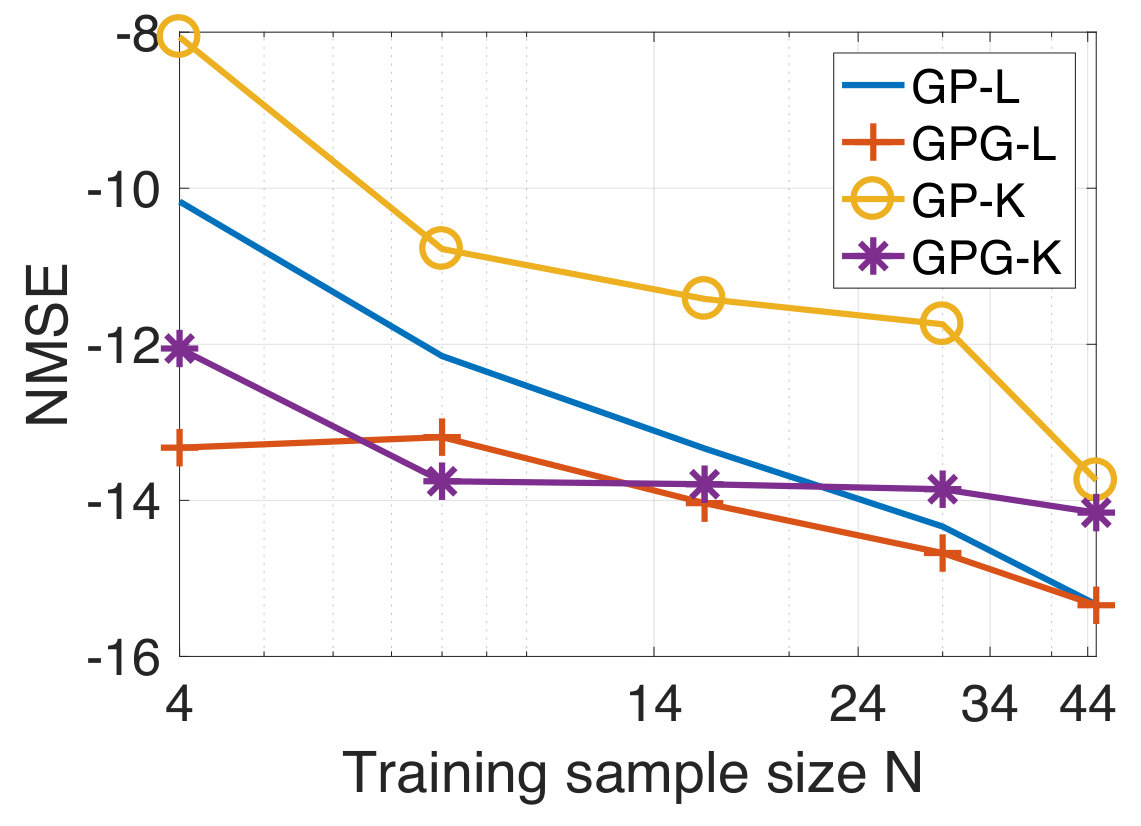 Figure 11
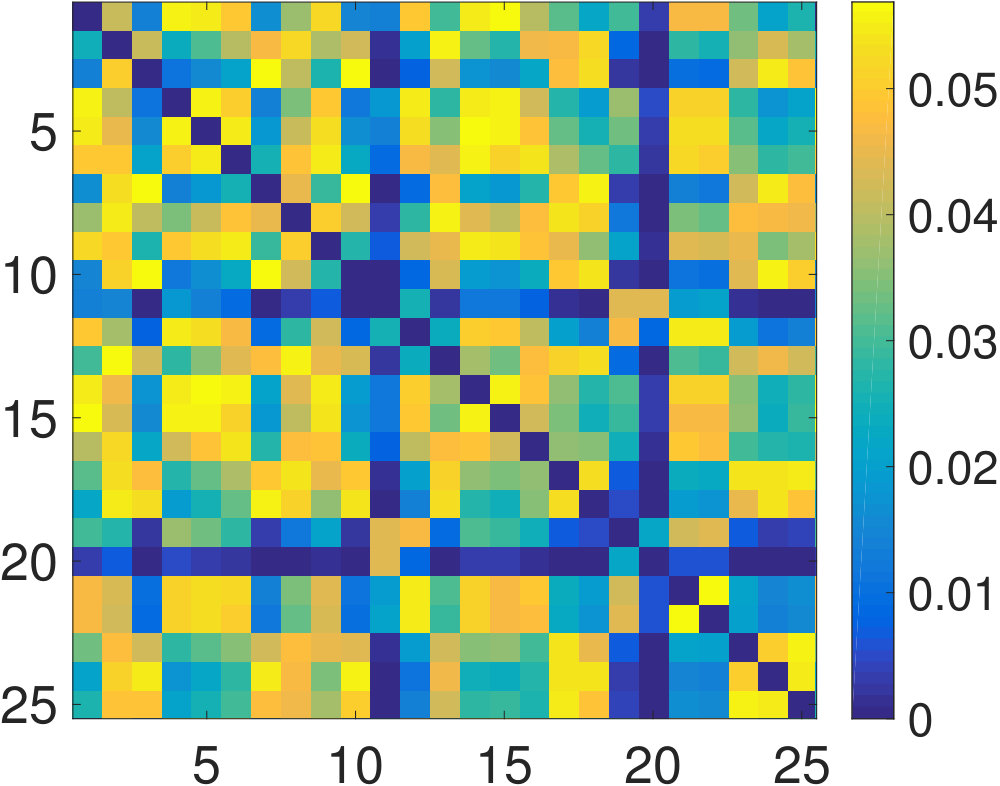 Figure 12
| Number | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Name | praf | pmek | plcg | PIP2 | PIP3 | p44/42 | pjnk | pakts473 | PKA | PKC | P38 |
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
Taxonomy
MethodsGaussian Process
Gaussian Processes Over Graphs
Arun Venkitaraman, Saikat Chatterjee, Peter Händel
Department of Information Science and Engineering
School of Electrical Engineering and Computer Science
KTH Royal Institute of Technology, SE-100 44 Stockholm, Sweden
[email protected], [email protected], [email protected]
Abstract
We propose Gaussian processes for signals over graphs (GPG) using the apriori knowledge that the target vectors lie over a graph. We incorporate this information using a graph-Laplacian based regularization which enforces the target vectors to have a specific profile in terms of graph Fourier transform coeffcients, for example lowpass or bandpass graph signals. We discuss how the regularization affects the mean and the variance in the prediction output. In particular, we prove that the predictive variance of the GPG is strictly smaller than the conventional Gaussian process (GP) for any non-trivial graph. We validate our concepts by application to various real-world graph signals. Our experiments show that the performance of the GPG is superior to GP for small training data sizes and under noisy training.
Index Terms:
Gaussian processes, Bayesian, graph signal processing, Linear model, kernel regression, .
I Introduction
Gaussian processes are a natural extension of the ubiquitous kernel regression to the Bayesian setting where the regression parameters are modelled as random variables with a Gaussian prior distribution [1]. Given the training observations, Gaussian processes generate posterior probabilities of the target or output for new inputs or observations, as a function of the training data and the input kernel function [2]. Gaussian process models and its variants have been applied in a number of diverse fields such as model predictive control and system analysis [3, 4, 5, 6, 7], latent variable models [8, 9, 10, 11], multi-task learning [10, 12, 13], image analysis and synthesis [14, 15, 16, 17], speech processing [18, 19, 20], and magnetic resonance imaging (MRI) [21, 22]. Gaussian processes have also been extended to a non-stationary regression setting [23, 24, 25] and for regression over complex-valued data[26]. Recently, Gaussian processes were shown to be useful in training and analysis of deep neural networks, and that a Gaussian process can be viewed as a neural network with a single infinite-dimensional layer of hidden units [27, 28]. The prediction performance of the Gaussian process depends on the availability of training data, progressively improving as the training data size is increased. In many applications, however, we are required to make predictions using a limited number of observations which may be further corrupted with observation noise. For such cases, providing additional structure helps improve the prediction performance of the GP significantly. In this article, we advocate the use of graph signal processing for improving prediction performance in the lack of sufficient and reliable training data.
We propose Gaussian processes by incorporating the apriori knowledge that the vector-valued target or output vectors lie over an underlying graph. This forms a natural Bayesian extension of the kernel regression for graph signals proposed recently in [29]. In particular, the target vectors are enforced to follow a pre-specified profile in terms of the graph Fourier coefficients, such being lowpass, bandpass, or high-pass. We show that this in turn translates to a specific structure on the prior distribution of the target vectors. We derive the predictive distribution for a general input given the training observations, and prove that graph signal structure leads to decrease in variance of the predictive distribution. Our hypothesis is that incorporating the graph structure would boost the prediction performance. We validate our hypothesis on various real-world datasets such as temperature measurements, flow-cytometry data, functional MRI data, and tracer diffusion experiment for air pollution studies. Though we consider GPG mainly for undirected graphs characterized by the graph-Laplacian in our analysis, we also discuss how our approach may be extended to handle directed graphs using an appropriate regularization.
II Preliminaries on Graph Signal Processing
Graph signal processing or signal processing over graphs deals with extension of several traditional signal processing methods while incorporating the graph structural information [30, 31]. This includes signal analysis concepts such as Fourier transforms[32], filtering [30, 33], wavelets [34, 35], filterbanks [36, 37], multiresolution analysis [38, 39, 40], denoising [41, 42], and dictionary learning [43, 44], and stationary signal analysis [45, 46]. Spectral clustering and principal component analysis approaches based on graph signal filtering have also been proposed recently [47, 48]. Several approaches have been proposed for learning the graph directly from data [49, 50]. Recently, kernel regression based approaches have also been developed for graph signals [29, 51, 52]. We now briefly review the relevant concepts from graph signal processing which will be used in our analysis and development. This review has been included to keep our article self-contained.
II-A Graph Laplacian and graph Fourier spectrum
Consider an undirected graph with nodes and adjacency matrix . The th entry of denotes the strength of the edge between the th and th nodes, denoting absence of edge. Since the graph is undirected, we have symmetric edge-weights or . The graph-Laplacian matrix is defined as , where is the diagonal degree matrix with th diagonal element given by the sum of the elements in the th row of [53]. is symmetric for an undirected graph and by construction has nonnegative eigenvalues with the smallest eigenvalue being equal to zero. A graph signal is an -dimensional vector such that denotes the value of the signal at the th node, where denotes transpose operation. The smoothness of is measured using . The quantity is small when takes the similar value across all connected nodes, in agreement with what one intuitively expects of a smooth signal. Similarly, is a high-frequency or non-smooth signal if it has dissimilar values across connected nodes, or equivalently a large value of .
The eigenvectors of the graph-Laplacian are used to define the notion of frequency of graph signals. Let and denote the eigenvalues and eigenvectors of , respectively. Then, the eigenvalue decomposition of is
[TABLE]
where is the diagonal eigenvalue matrix of , such that
[TABLE]
It is standard practice to order the eigenvectors of the graph-Laplacian according to their smoothness in terms of . The eigenvectors are referred to as the graph Fourier transform (GFT) basis vectors since they generalize the notion of the discrete Fourier transform [31]. Let denote the th eigenvalue of ordered as . Then, we observe that . In other words, the eigenvectors corresponding to smaller vary smoothly over the graph and those with large exhibit more variation across the graph. This in turn gives an intuitive frequency ordering of the GFT basis vectors. The GFT coefficients of a graph signal are defined as the inner product of the signal with the GFT basis vectors , that is, the GFT coefficient vector is defined as:
[TABLE]
The inverse GFT is then given by . A graph signal may then be low-pass or smooth, high-pass, band-pass, or band-stop according to the distribution of its GFT coefficients in .
II-B Generative model for graph signals
We now derive the expressions for the graph signal of a particular GFT profile closest to any given signal, which shall be used in our analysis later. For any signal , a graph signal with a specified graph frequency profile closest to can be obtained by solving the following generative model
[TABLE]
where is the GFT of and is the diagonal matrix whose values penalize or promote specific GFT coefficients. For example, if is to have energy predominantly in GFT vectors with indices , we set the corresponding diagonal entries of to zero and assign large values to the remaining diagonal entries. From the properties of the GFT, we have that
[TABLE]
where . Then, the generative model is equivalently expressible as:
[TABLE]
Since all the eigenvalues of are nonnegative, is positive semidefinite giving the unique closed-form solution for as
[TABLE]
We note that most graph signals encountered in practice are usually smooth over the associated graph. One of the simplest cases of generating a smooth graph signal is to penalize the frequencies linearly by setting . This in turn corresponds to and the smooth graph signal then becomes .
III Gaussian process over graph
We first develop Bayesian linear regression over graph and then proceed to develop a Gaussian process over graph.
III-A Bayesian linear regression over graph
We now propose linear regression over graphs. Let denote the set of input observations, and denote the corresponding vector target values. We model the target as the output of a linear regression such that
[TABLE]
where denotes the additive noise vector following a zero mean isotropic Gaussian distribution, that is,
[TABLE]
Here denotes the identity matrix of dimension and is the precision parameter for the noise. The signal is
[TABLE]
where is a function of , denotes the regression coefficient matrix. We further consider an isotropic Gaussian prior with precision for the entries of . Let us use the notation where denotes the vectorization of obtained by concatenating the columns of into a single vector. Then, we have that
[TABLE]
Our principal assumption is that the predicted target vector or regression output has a graph Fourier spectrum as characterized by the diagonal spectrum matrix . However, is not necessarily satisfy this requirement for an arbitrary choice of , since is also fixed apriori and has not been assumed to be graph-specific. It becomes clear then that the prior on should be chosen in a way that it promotes to have the required graph Fourier spectrum. We next discuss our strategy for formulating such a prior distribution. Given the regression output generated using a fixed drawn from (6), the graph signal closest to is obtained by using the generative model (2) with the following result
[TABLE]
where . Let , then we have that
[TABLE]
Thus, we note that regression of with regression coefficient matrix produces graph signals possessing the desired graph Fourier profile. In the case of , this is the same as regression output being smooth over the graph. On vectorizing both sides of (7) and using properties of the Kronecker product [54], we get that
[TABLE]
where denotes the Kronecker product operation. Note that is symmetric as and hence, is symmetric. Since , we get that is distributed according to
[TABLE]
This in turn implies that choosing a prior for the regression coefficients of the form (8) yields graph signals with specified graph Fourier spectrum over the graph with the Laplacian matrix . We then pose the regression problem (III-A) in the following form
[TABLE]
We assume that follows the same distribution of in (III-A). Then, the conditional distribution of is given by
[TABLE]
We define the matrices , , and as follows:
[TABLE]
On accumulating all the observations we have
[TABLE]
where , and is the noise term. Dropping the dependency of the distribution on for brevity, we have that
[TABLE]
Since , we have that
[TABLE]
The prior distribution of is then a multivariate Gaussian distribution with mean and covariance given by
[TABLE]
We refer to this model as Bayesian linear regression over graph.
III-B Gaussian process over graph
We next develop Gaussian process over graphs (GPG). We first note the existence of in (12) and that the input enters the equation only in the form of inner products of . The inner product is a measure of similarity between the th and th inputs. Keeping this in mind, one may generalize the inner-product to any valid kernel function[2] of the inputs and . The kernel matrix is denoted by , and its th entry is . Following (10), (11), and (III-A) we find that is Gaussian distributed with zero mean and following covariance
[TABLE]
where we use the first subscript to denote the graph, and the second subscript to show explicit dependency on observations. With samples, we have that
[TABLE]
where
- ,
- , and
- .
Then, using properties of conditional probability for jointly Gaussian vectors [2], we have the predictive distribution of GPG as follows
[TABLE]
where
- and .
We note that in the case of completely disconnected graph, which corresponds to the conventional Gaussian process (GP), the graph adjacency matrix is equal to the identity matrix and correspondingly, . Then, the covariance of the joint distribution of is given by
[TABLE]
where the subscript denotes it being the conventional Gaussian process. Correspondingly, the predictive distribution of is given by
[TABLE]
where
- ,
- ,
- ,
- .
We note that since Bayesian linear regression on graphs developed in Section A is a special case of the Gaussian process on graphs with kernels, we shall refer to the former as Gaussian process-Linear (GPG-L) and the latter as Gaussian process-Kernel (GPG-K). Correspondingly, we refer to the conventional versions as GP-L, and GP-K, respectively.
We next show that use of graph information reduces the variance of the predictive distribution. This implies that the GPG models the observed training samples better than conventional GP.
Theorem 1** (Reduction in variance).**
Graph structure reduces the variance of the marginal distribution , that is, GPG results in smaller variance of than GP:
[TABLE]
Proof.
In order to prove the result, we need to show that the trace of is nonnegative. Using the properties of trace operation, we have that
[TABLE]
Since is positive semidefinite by construction as a kernel matrix, we have that if and only if . Let and denote the eigenvalues and eigenvectors of , respectively. Then, the eigenvalue decomposition of and are given by
[TABLE]
where and denote the diagonal eigenvalue matrix of and , respectively, such that
[TABLE]
Since , we have
[TABLE]
Let denote the graph eigenvalue index corresonding to the denote the smallest non-zero diagonal value in , the value given by . Then, we have that . Then, a sufficient condition to ensure is to impose that
[TABLE]
A graph with atleast one connected subgraph has atleast one eigenvalue of strictly greater than 0 [53]. Thus, barring the completely disconnected graph and the pathological case of (or ), any graph with connections across nodes results in or in other words that the variance strictly reduces in comparison with the conventional regression, that is,
[TABLE]
In other words, introducing non-zero connections among the nodes ensures that the marginal variance is strictly lesser than that obtained for the conventional regression case. We also note that in order for the reduction in variance to be significant, must be large, which in turn implies that the connected communities within the graph must have strong algebraic connectivity [53]. In the case of regression output being smooth graph signals in the sense of , we have that and for a graph with -connected components or disjoint subgraphs. This is because the number of zero eigenvalues of is equal to the nunber of connected components in the graph [53, 55]. ∎
An immediate consequence of the Theorem is the following important Corrollary which informs us that the variance of the predicted target reduces when the graph signal structure is employed:
Corollary 1.1** (Reduction in predictive variance).**
GPG-K with a non-trivial graph has strictly smaller predictive variance than GPG-K, that is,
[TABLE]
Proof.
We are required to prove that , or equivalently that is a positive semidefinite matrix. We notice that is given by
[TABLE]
We observe that is then the Schur complement of in . Since the Schur complement of a positive-definite matrix is also positive-definite [56], and we have already proved that is positive-definite from Theorem 1, it follows that
[TABLE]
∎
By the preceding analysis, we also observe that the variance of the joint distribution , and hence, that of is inversely related to the graph regularization parameter . This is because a large implies a small value of for all , and therefore, a small value of .
III-C On the mean vector of predictive distribution
We now show that the mean of predictive distribution is a graph signal with a graph Fourier spectrum which adheres to the condition imposed by . We demonstrate this by computing the graph Fourier spectrum of the predictive mean. Using the eigendecompostions of and , we have that
[TABLE]
where
- ,
- is the th diagonal element of ,
- ,
- denotes the th column vector of , and
- .
Since the is a function of some th eigenvalue of and th eigenvalue of , we shall alternatively use the notation to be more specific in the following analysis. Similarly, expressed as and the eigenvectors . The component of the prediction mean along the graph eigenvector (or the th graph frequency) is then given by
[TABLE]
We observe that a nonzero reduces or shrinks the contribution from the graph-frequencies corresponding to larger , in comparison with the conventional mean obtained by setting . In the case of smooth graph signals, we have implying that the prediction mean has lower contributions from higher graph-frequencies, which in turn shows that GPG performs a noise-smoothening by making use of the graph topology. However, this does not imply that the value of may be set to be arbitrarily large. A large will in turn force the resulting target predictions to lie close to the smoother eigenvectors of , which is not desirable since it reduces the learning ability of the GP. We note that since GPG-L is a special case of the GPG-K, Theorem 1 and the analysis following it apply directly also to GPG-L.
III-D Extension for directed graphs
In our analysis, we have assumed the underlying graph for the target vectors to be undirected and hence, characterized by the symmetric positive semidefinite graph-Laplacian matrix . We now discuss how GPG may be derived for the case of directed graphs, that is, when the adjacency matrix of the graph is assymetric. In the case of directed graphs, the following metric is popular for quantifying the smoothness of the graph signals:
[TABLE]
where and denote the graph signal and adjacency matrix, respectively, the adjacency matrix assumed to be normalized to have maximum eigenvalue modulus equal to unity [30]. A signal is smooth over a directed graph if it has a small value. This is because measures the difference between the signal and its one-step diffused or ’graph-shifted’ version, thereby measuring the difference between the signal value at each node and its neighbours, weighted by the strength of the edge between the nodes. In the case of directed graphs, we may adopt the same approach as that of the undirected graph case with one important distinction: instead of solving (2), we now solve the following problem for each observation:
[TABLE]
Then, we have that
[TABLE]
Using a similar analysis as with the undirected graph case, we arrive at the following Gaussian process model:
[TABLE]
where is distributed according to the prior:
[TABLE]
where . By following similar analysis as with the undirected graphs, it is possible to show that the variance of the predictive distribution reduces using GPG and that the predictive mean is smooth over the graph. In the interest of space and to avoid repetition, we do not include the analysis for directed graphs here.
IV Experiments
We consider application of GPG to various real-world signal examples. For the examples, we consider undirected graphs. Our interest is to compute the predictive distribution (17) given the noisy targets and the corresponding inputs . Our assumption is that a target vector is smooth over an underlying graph. We use the graph-regularization with . To evaluate the prediction performance, we use the normalized-mean-square-error (NMSE) defined as follows:
[TABLE]
where denotes the mean of the predictive distribution and the true value of target matrix, that means does not contain any noise. The noisy target matrix is generated obtained by adding white Gaussian noise with precision parameter to . In the case of real-world examples, we compare the performance of the following cases:
GP with linear regression (GP-L): , where and , 2. 2.
GPG with linear regression (GPG-L): and , where , 3. 3.
GP with kernel regression (GP-K): Using radial basis function (RBF) kernel and , and 4. 4.
GPG with kernel regression over graphs (GPG-K): Using RBF kernel and .
We use five-fold cross-validation to obtain the values of regularization parameters and . We set the kernel parameter . We perform experiments under various signal-to-noise ratio (SNR) levels, and choose the precision parameter accordingly.
IV-A Prediction for fMRI in cerebellum graph
We first consider the functional magnetic resonance imaging (fMRI) data obtained for the cerebellum region of brain [57]111The data is available publicly at https://openfmri.org/dataset/ds000102.. The original graph consists of 4465 nodes corresponding to different voxels of the cerebellum region. The voxels are mapped anatomically following the atlas template [58, 59]. We refer to [57] for details of graph construction and associated signal extraction. We consider a subset of the first 100 vertices in our analysis. Our goal is to use the first ten vertices as input to make predictions for remaining 90 vertices, which forms the output . Thus, the target signals lie over a graph of dimension . The corresponding adjacency matrix is shown in Figure 1(a). We have a total of 295 graph signals corresponding to different measurements from a single subject. We use a portion of the signals for training and the remaining for testing. We construct noisy training targets by adding white Gaussian noise at SNR-levels of 10 dB and 0 dB. The NMSE of the prediction mean for testing data, averaged over 100 different random choices of training and testing sets is shown in 1(b) and (c); this is Monte Carlo simulation to check robustness. We observe that for both linear and kernel regression cases, GPG outperforms GP by a significant margin, particularly at small training data sizes as expected. The trend is also similar when larger subsets of nodes from the full set are considered. The results are not reported here for brevity and to avoid repetition.
IV-B Prediction for temperature data
We next apply GPG on temperature measurements from the 45 most populated cities in Sweden for a period of three months from October to December 2017. The data is available publicly from the Swedish Meteorological and Hydrological Institute [60]. Our goal is to perform one-day temperature prediction: given the temperature data for a particular day , we predict the temperature for the next day . We have 90 input-target data pairs in total, of which one half is used for training and the rest for testing. We consider the geodesic graph in our analysis with the th entry of the graph adjacency matrix is given by
[TABLE]
where denotes the geodesic distance between the th and th cities. In order to remove self loops, the diagonal of is set to zero. We generate noisy training data by adding zero-mean white Gaussian noise at SNR of dB and [math] dB to the true temperature measurements. In Figure 2, we show the NMSE obtained for testing data by averaging over 100 different random partitioning of the total dataset into training and testing datasets. We observe that GPG outperforms GP for both linear and kernel regression cases.
IV-C Prediction for flow-cytometry data
We now consider the application of GPG to flow-cytometry data considered by Sachs et al. [61] which consists of response or signalling level of 11 proteins in different experiment cells. Since the protein signal values have a large dynamic range and are all positive values, we perform experiments on signals obtained by taking a logarithm with the base of 10 for reducing the dynamic range. We use the first 1000 measurements in our analysis. We use the symmetricized version of the directed unweighted acyclic graph proposed by Sachs et al. [61]. Among the 11 proteins, we choose proteins 10 and 11 arbitrarily as input to make predictions for the remaining 9 proteins which forms the target vector lying on a graph of nodes. We perform the experiment 100 times in Monte Carlo simulation, where we random divide the total dataset into training and testing datasets. The average NMSE for testing datasets is shown in Figure 3 at SNR levels of dB and [math] dB. We once again observe the same trend that GPG outperforms GP for both linear and kernel cases at low sample sizes corrupted with noise.
IV-D Prediction for atmospheric tracer diffusion data
Our next experiment is on the atmospheric tracer diffusion measurements obtained from the European Tracer Experiment (ETEX) which tracked the concentration of perfluorocarbon tracers released into the atmosphere starting from a fixed location (Rennes, France)[62]. The observations were collected from two experiments over a span of 72 hours at 168 ground stations over Europe, giving two sets of 30 measurements, in total 60 measurements. Our goal is to predict the tracer concentrations on one half (84) of the total ground stations, using the concentrations at the remaining locations. The target signal is then a graph signal over a graph of nodes where denotes the measurement index. The corresponding input vector is also of length 84. We illustrate the ground station locations in a schematic in Figure 4 (a). The output nodes which correspond to the the target are shown in red markers with corresponding edges, whereas the rest of the markers denote the input. We simulate noisy training by adding white Gaussian noise at different SNR levels to the training data. We consider a geodesic distance based graph. The graph is constructed in the same manner like the graph used in the temperature data experiment previously. We randomly divide the total dataset of 60 samples equally into training and test datasets. We compute the NMSE for the different approaches by averaging over 100 different randomly drawn training subsets of size from the full training set of size . We plot the NMSE as a function of in Figures 4(b)-(c) at SNR levels of dB and [math]dB. We observe that graph structure enhances the prediction performance signficantly under noisy and low sample size conditions.
V Reproducible research
In the spirit of reproducible research, all the codes relevant to the experiments in this article are made available at https://www.researchgate.net/profile/Arun_Venkitaraman and https://www.kth.se/ise/research/reproducibleresearch-1.433797.
VI Conclusions
We developed Gaussian processes for signals over graphs by employing a graph-Laplacian based regularization. The Gaussian process over graphs was shown to be a consistent generalization of the conventional Gaussian process, and that it provably results in a reduction of uncertainty in the output prediction. This in turn implies that the Gaussian process over graph is a better model for target vectors lying over a graph in comparison to the conventional Gaussian process. This observation is important in cases when the available training data is limited in both quantity and quality. Our expectation and motivation was that incorporating the graph structural information would help the Gaussian process make better predictions, particularly in absence sufficient and reliable training data. The experimental results with the real-world graph signals illustrated that this is indeed the case.
The reference list from the paper itself. Each links out to its DOI / PubMed record.
- 1[1] C. E. Rasmussen and C. K. I. Williams, Gaussian Processes for Machine Learning (Adaptive Computation and Machine Learning) . The MIT Press, 2005.
- 2[2] C. M. Bishop, Pattern Recognition and Machine Learning (Information Science and Statistics) . Secaucus, NJ, USA: Springer-Verlag New York, Inc., 2006.
- 3[3] G. Cao, E. M. K. Lai, and F. Alam, “Gaussian process model predictive control of unknown non-linear systems,” IET Control Theory Appl. , vol. 11, no. 5, pp. 703–713, 2017.
- 4[4] G. Chowdhary, H. A. Kingravi, J. P. How, and P. A. Vela, “Bayesian nonparametric adaptive control using Gaussian processes,” IEEE Transactions on Neural Networks and Learning Systems , vol. 26, no. 3, pp. 537–550, March 2015.
- 5[5] M. Stepančič and J. Kocijan, “On-line identification with regularised evolving Gaussian process,” IEEE Evolving and Adaptive Intelligent Systems (EAIS) , pp. 1–7, May 2017.
- 6[6] H. Soh and Y. Demiris, “Spatio-temporal learning with the online finite and infinite echo-state Gaussian processes,” IEEE Trans. Neural Netw. Learn. Syst. , vol. 26, no. 3, pp. 522–536, March 2015.
- 7[7] G. Chowdhary, H. A. Kingravi, J. P. How, and P. A. Vela, “Bayesian nonparametric adaptive control using Gaussian processes,” IEEE Trans. Neural Netw. Learn. Syst. , vol. 26, no. 3, pp. 537–550, March 2015.
- 8[8] G. Song, S. Wang, Q. Huang, and Q. Tian, “Multimodal similarity Gaussian process latent variable model,” IEEE Trans. Image Process. , vol. 26, no. 9, pp. 4168–4181, Sept 2017.