Time-Staging Enhancement of Hybrid System Falsification
Gidon Ernst, Ichiro Hasuo, Zhenya Zhang, Sean Sedwards

TL;DR
This paper introduces time staging, a method that improves the efficiency of optimization-based falsification of hybrid systems by exploiting the time-causal structure of signals, demonstrated through experiments and theoretical analysis.
Contribution
The paper proposes a novel time staging approach that enhances hybrid system falsification by incrementally constructing input signals, with supporting theoretical insights.
Findings
Time staging significantly improves falsification performance in certain cases.
Experimental results confirm the effectiveness of the proposed method.
Theoretical analysis identifies conditions where time staging is most beneficial.
Abstract
Optimization-based falsification employs stochastic optimization algorithms to search for error input of hybrid systems. In this paper we introduce a simple idea to enhance falsification, namely time staging, that allows the time-causal structure of time-dependent signals to be exploited by the optimizers. Time staging consists of running a falsification solver multiple times, from one interval to another, incrementally constructing an input signal candidate. Our experiments show that time staging can dramatically increase performance in some realistic examples. We also present theoretical results that suggest the kinds of models and specifications for which time staging is likely to be effective.
Click any figure to enlarge with its caption.
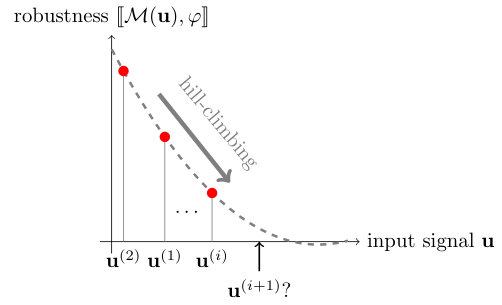 Figure 1
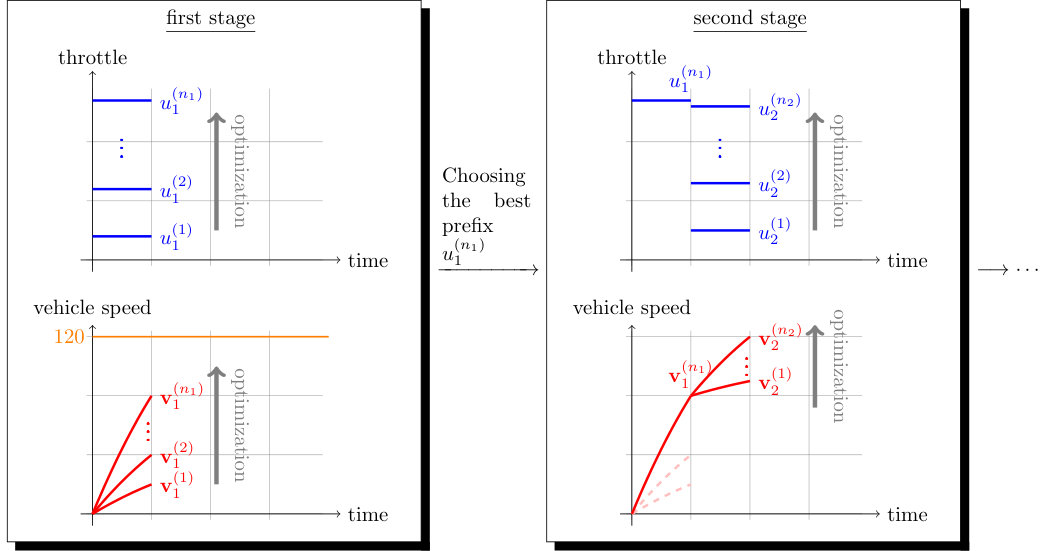 Figure 2
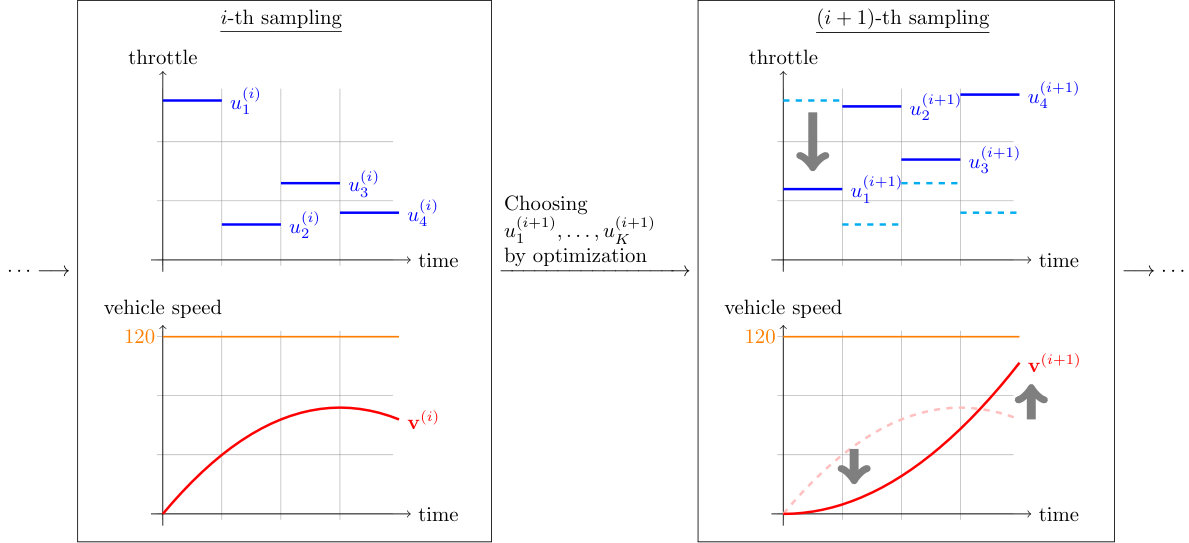 Figure 3
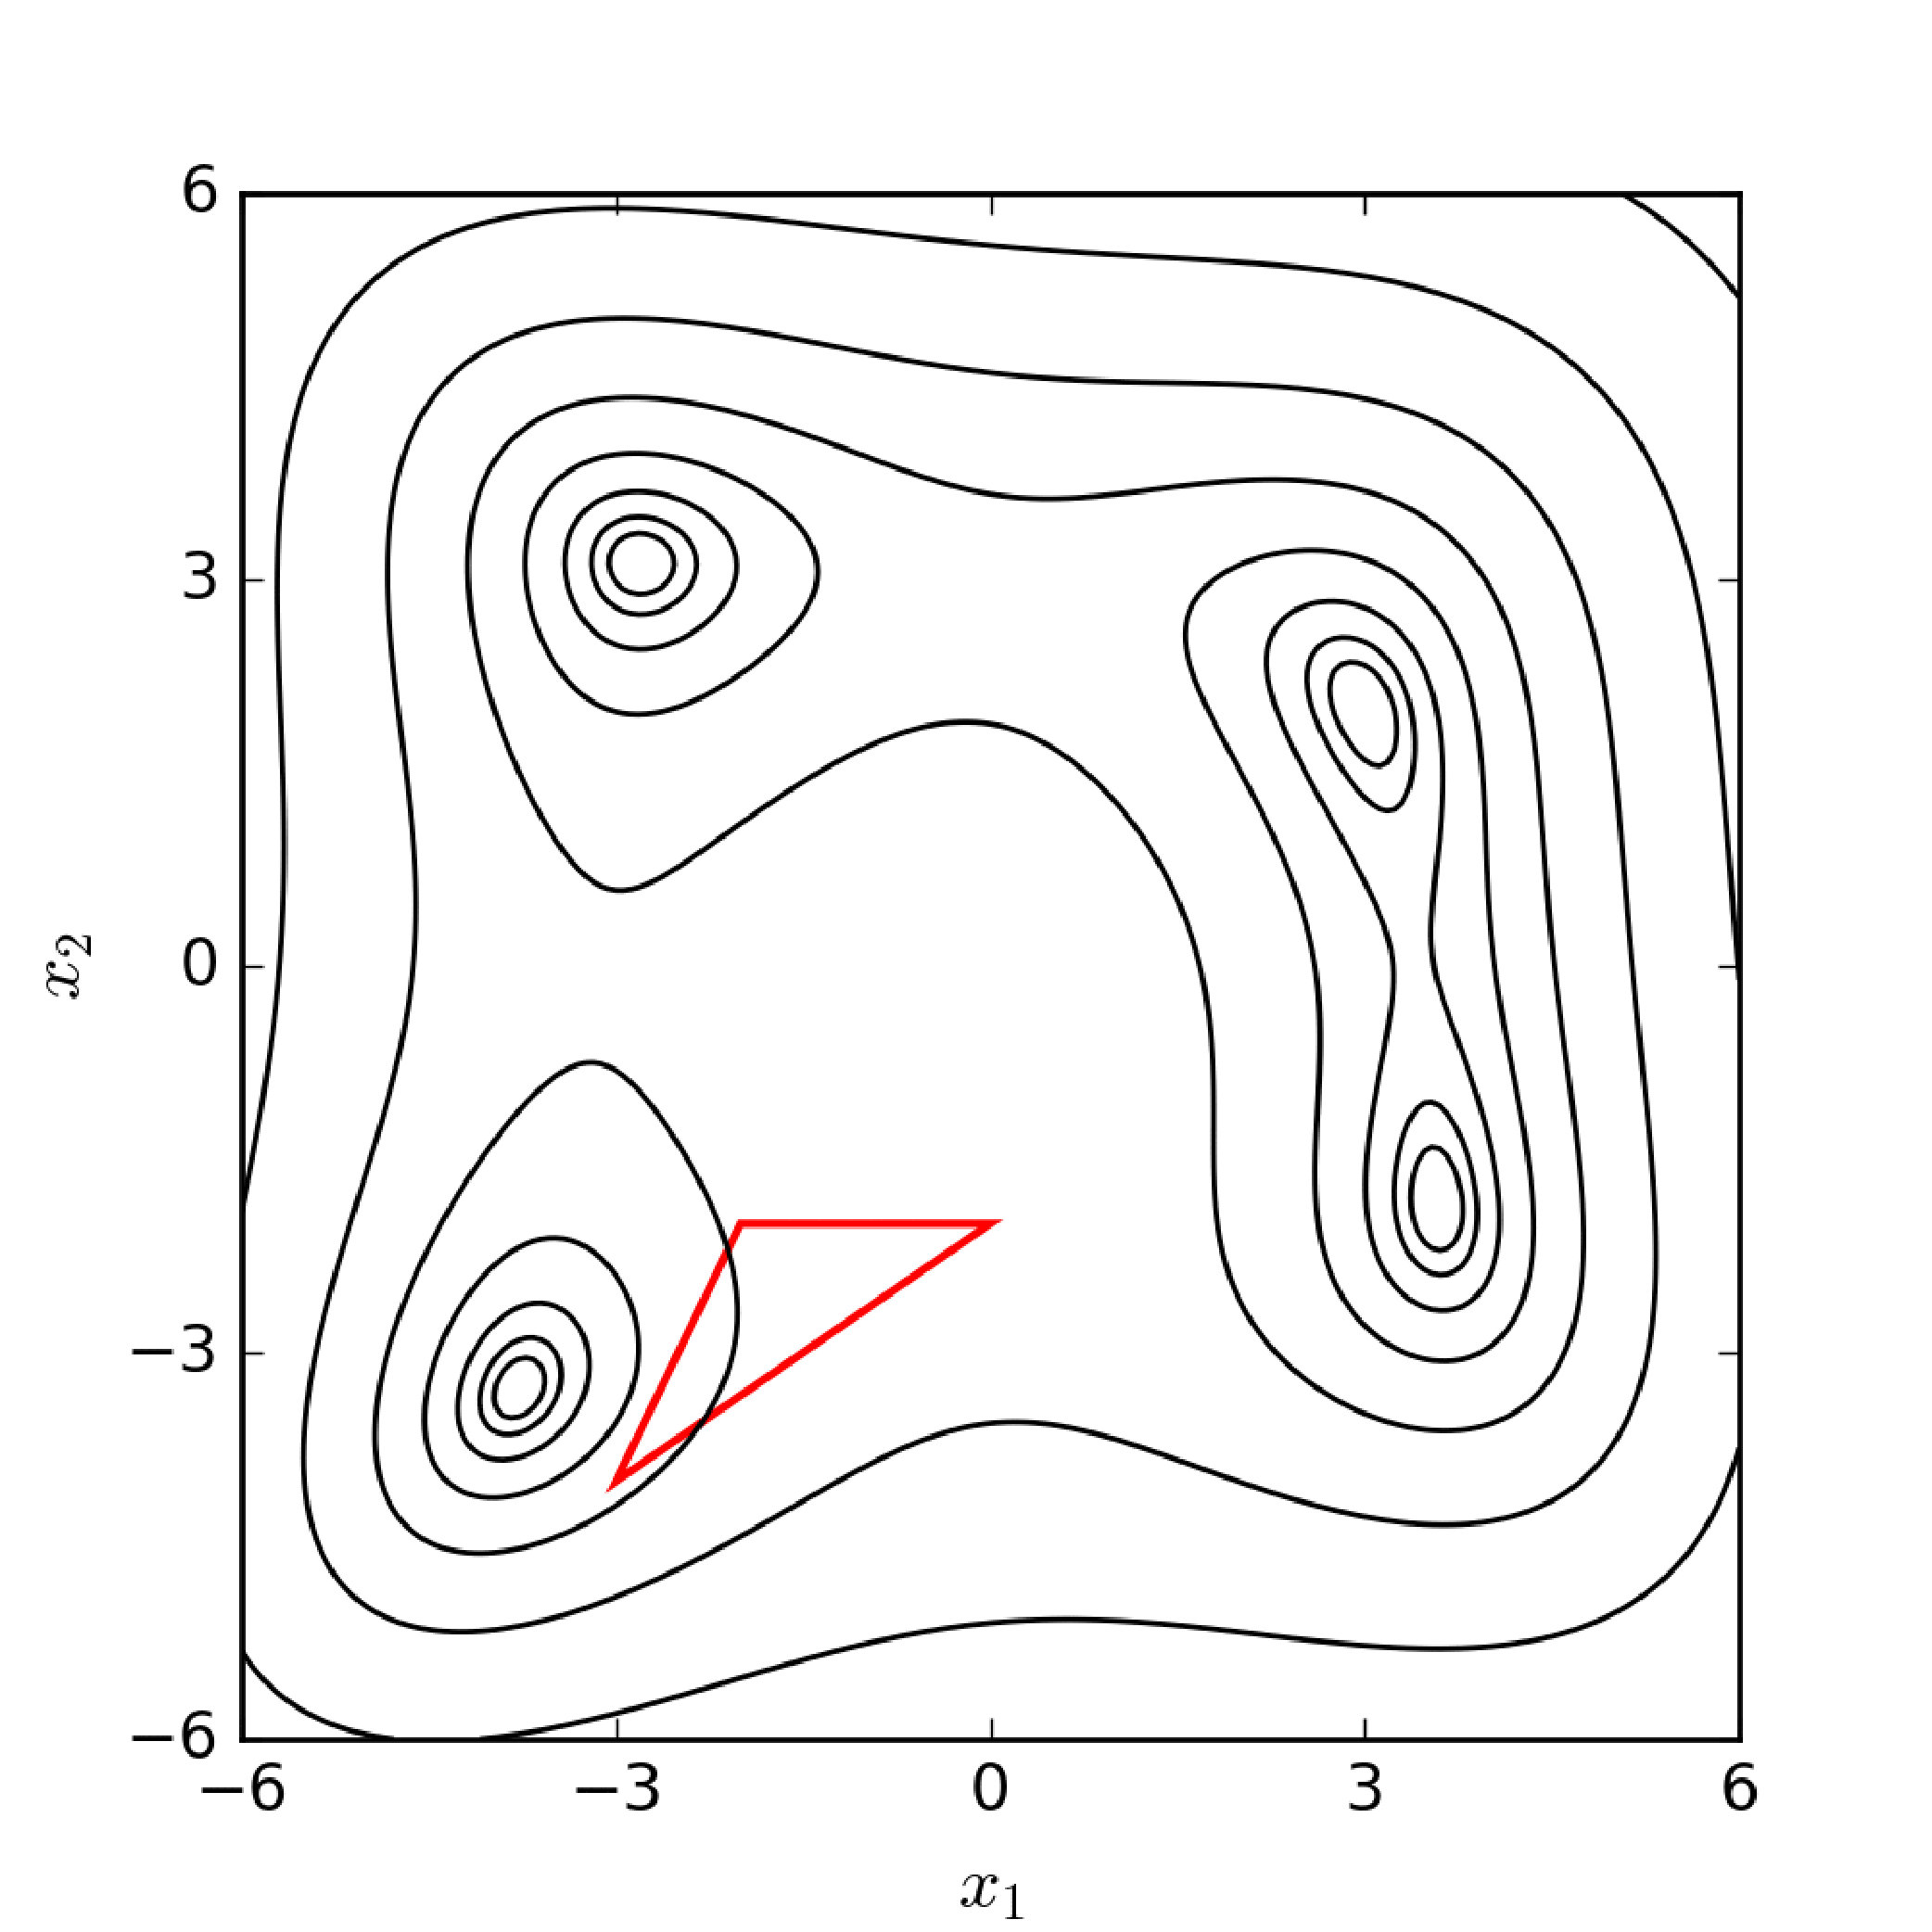 Figure 4
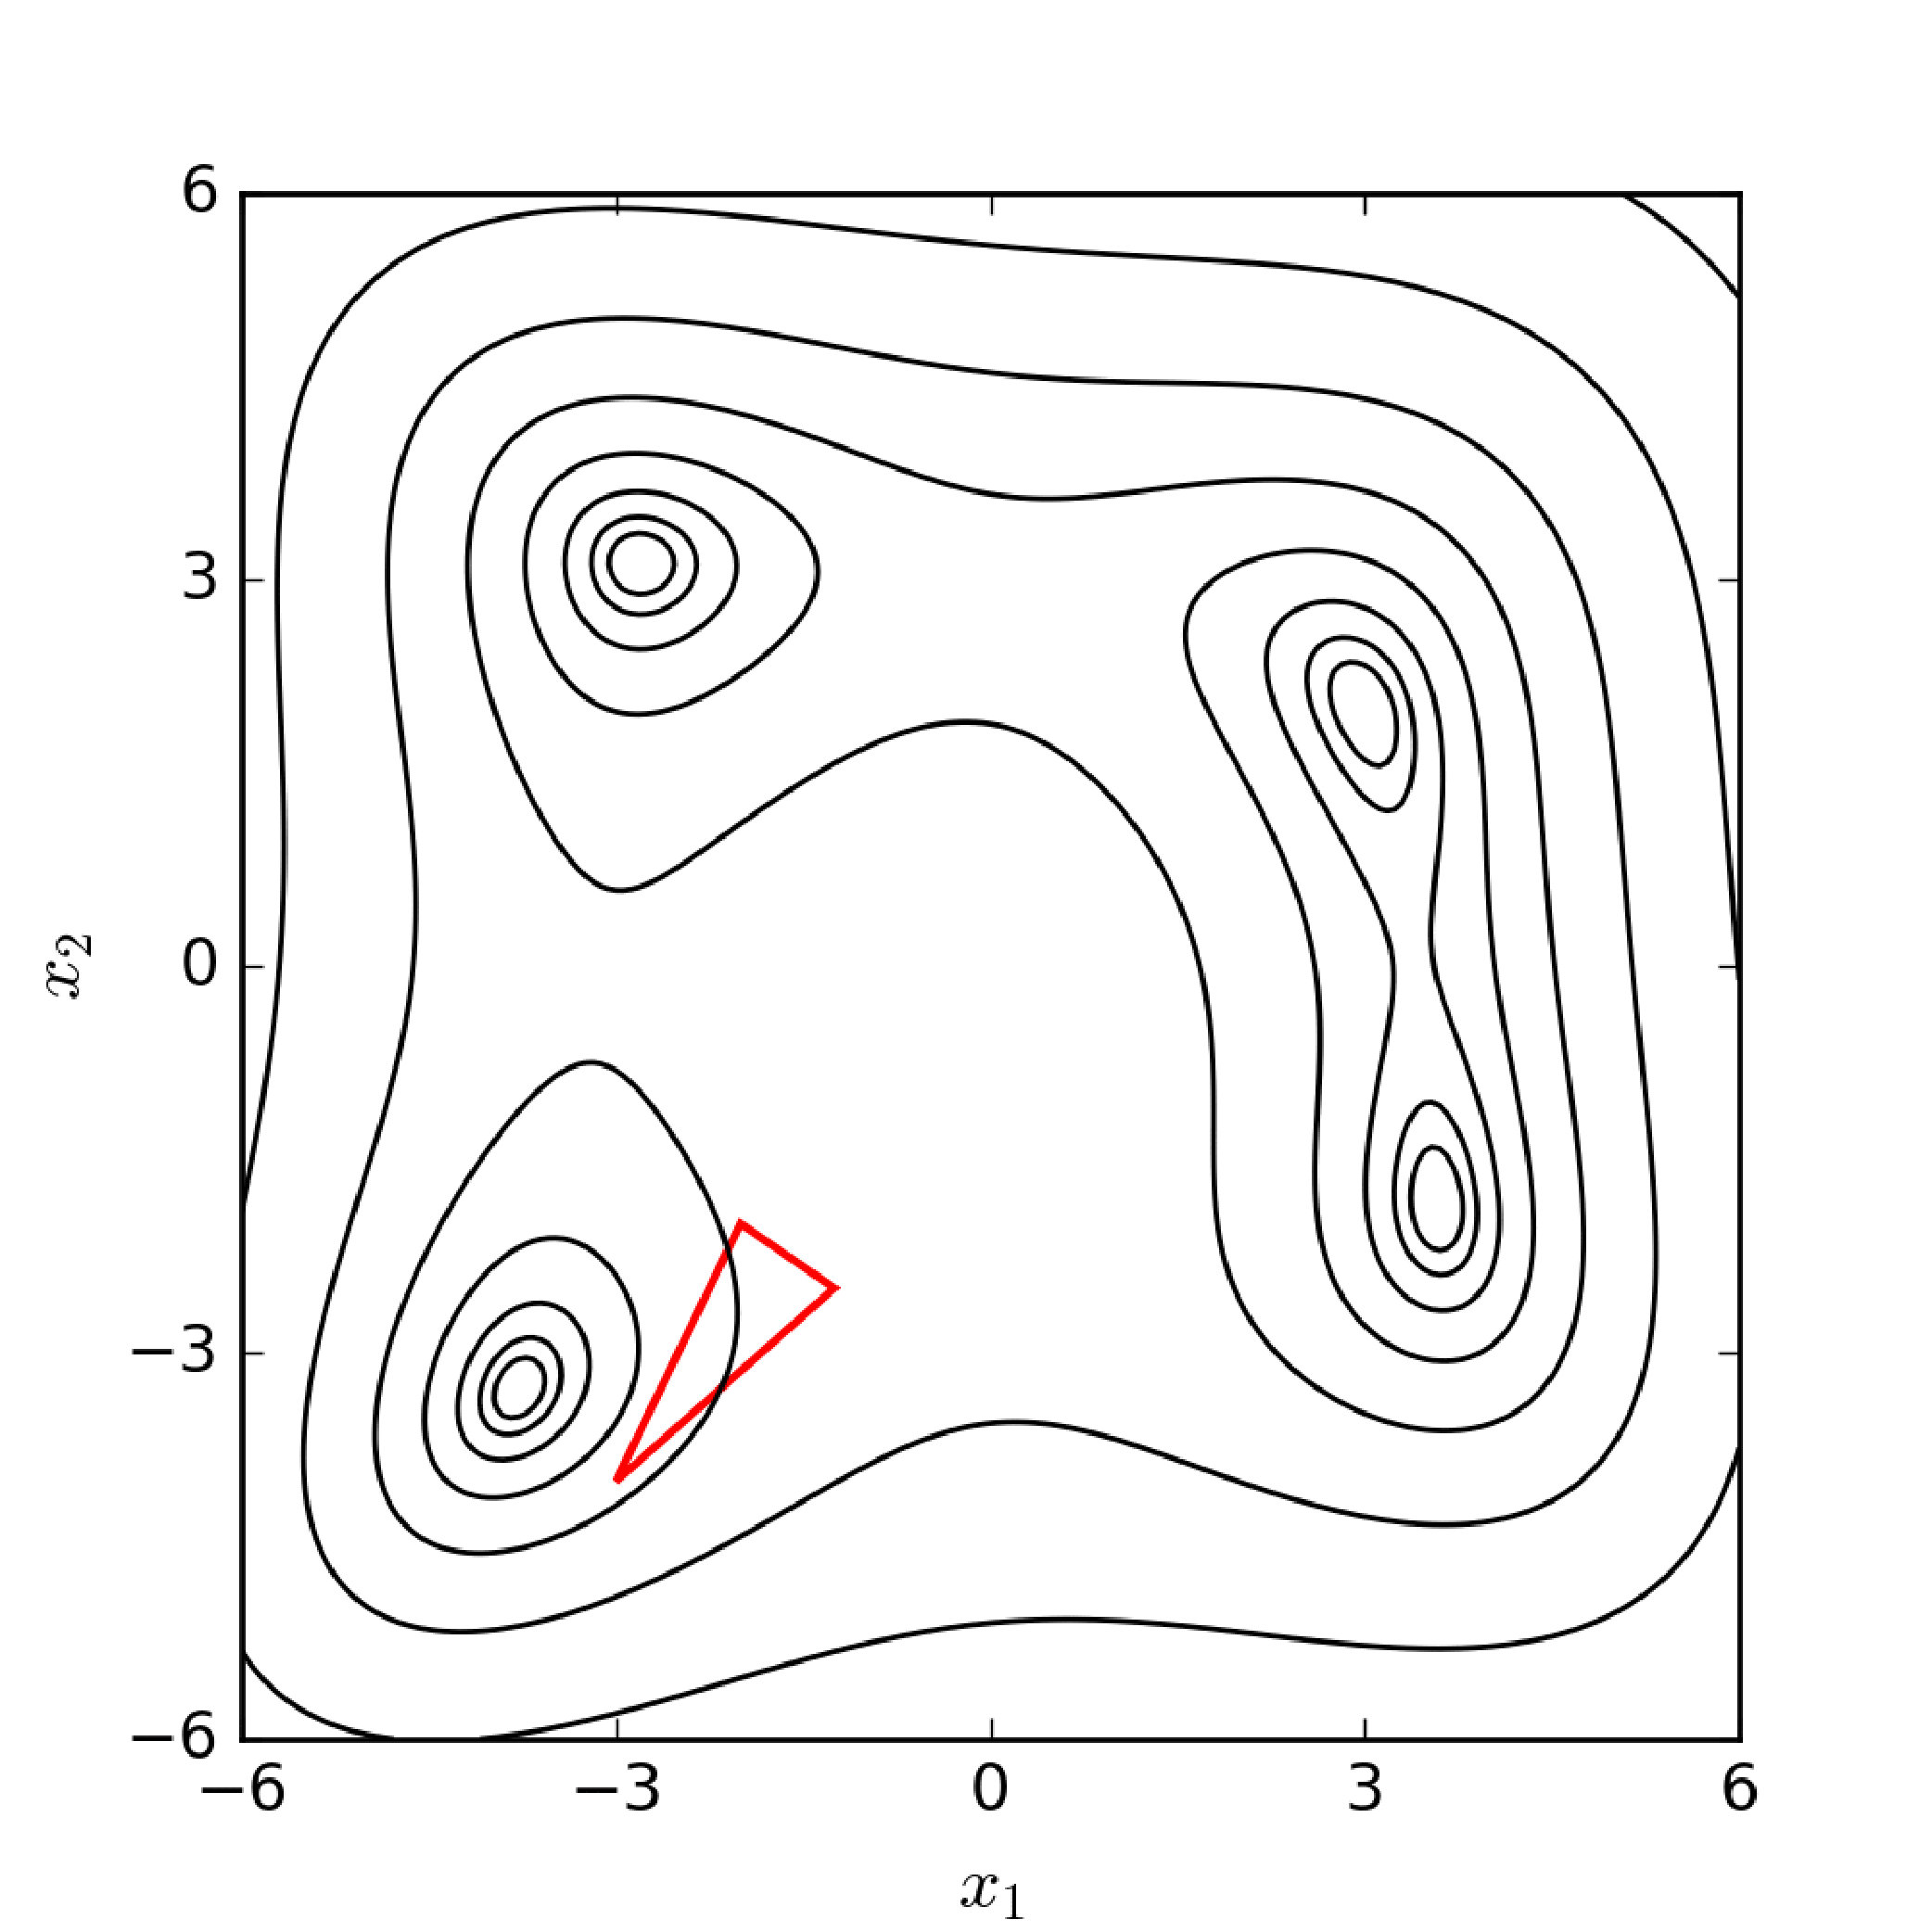 Figure 5
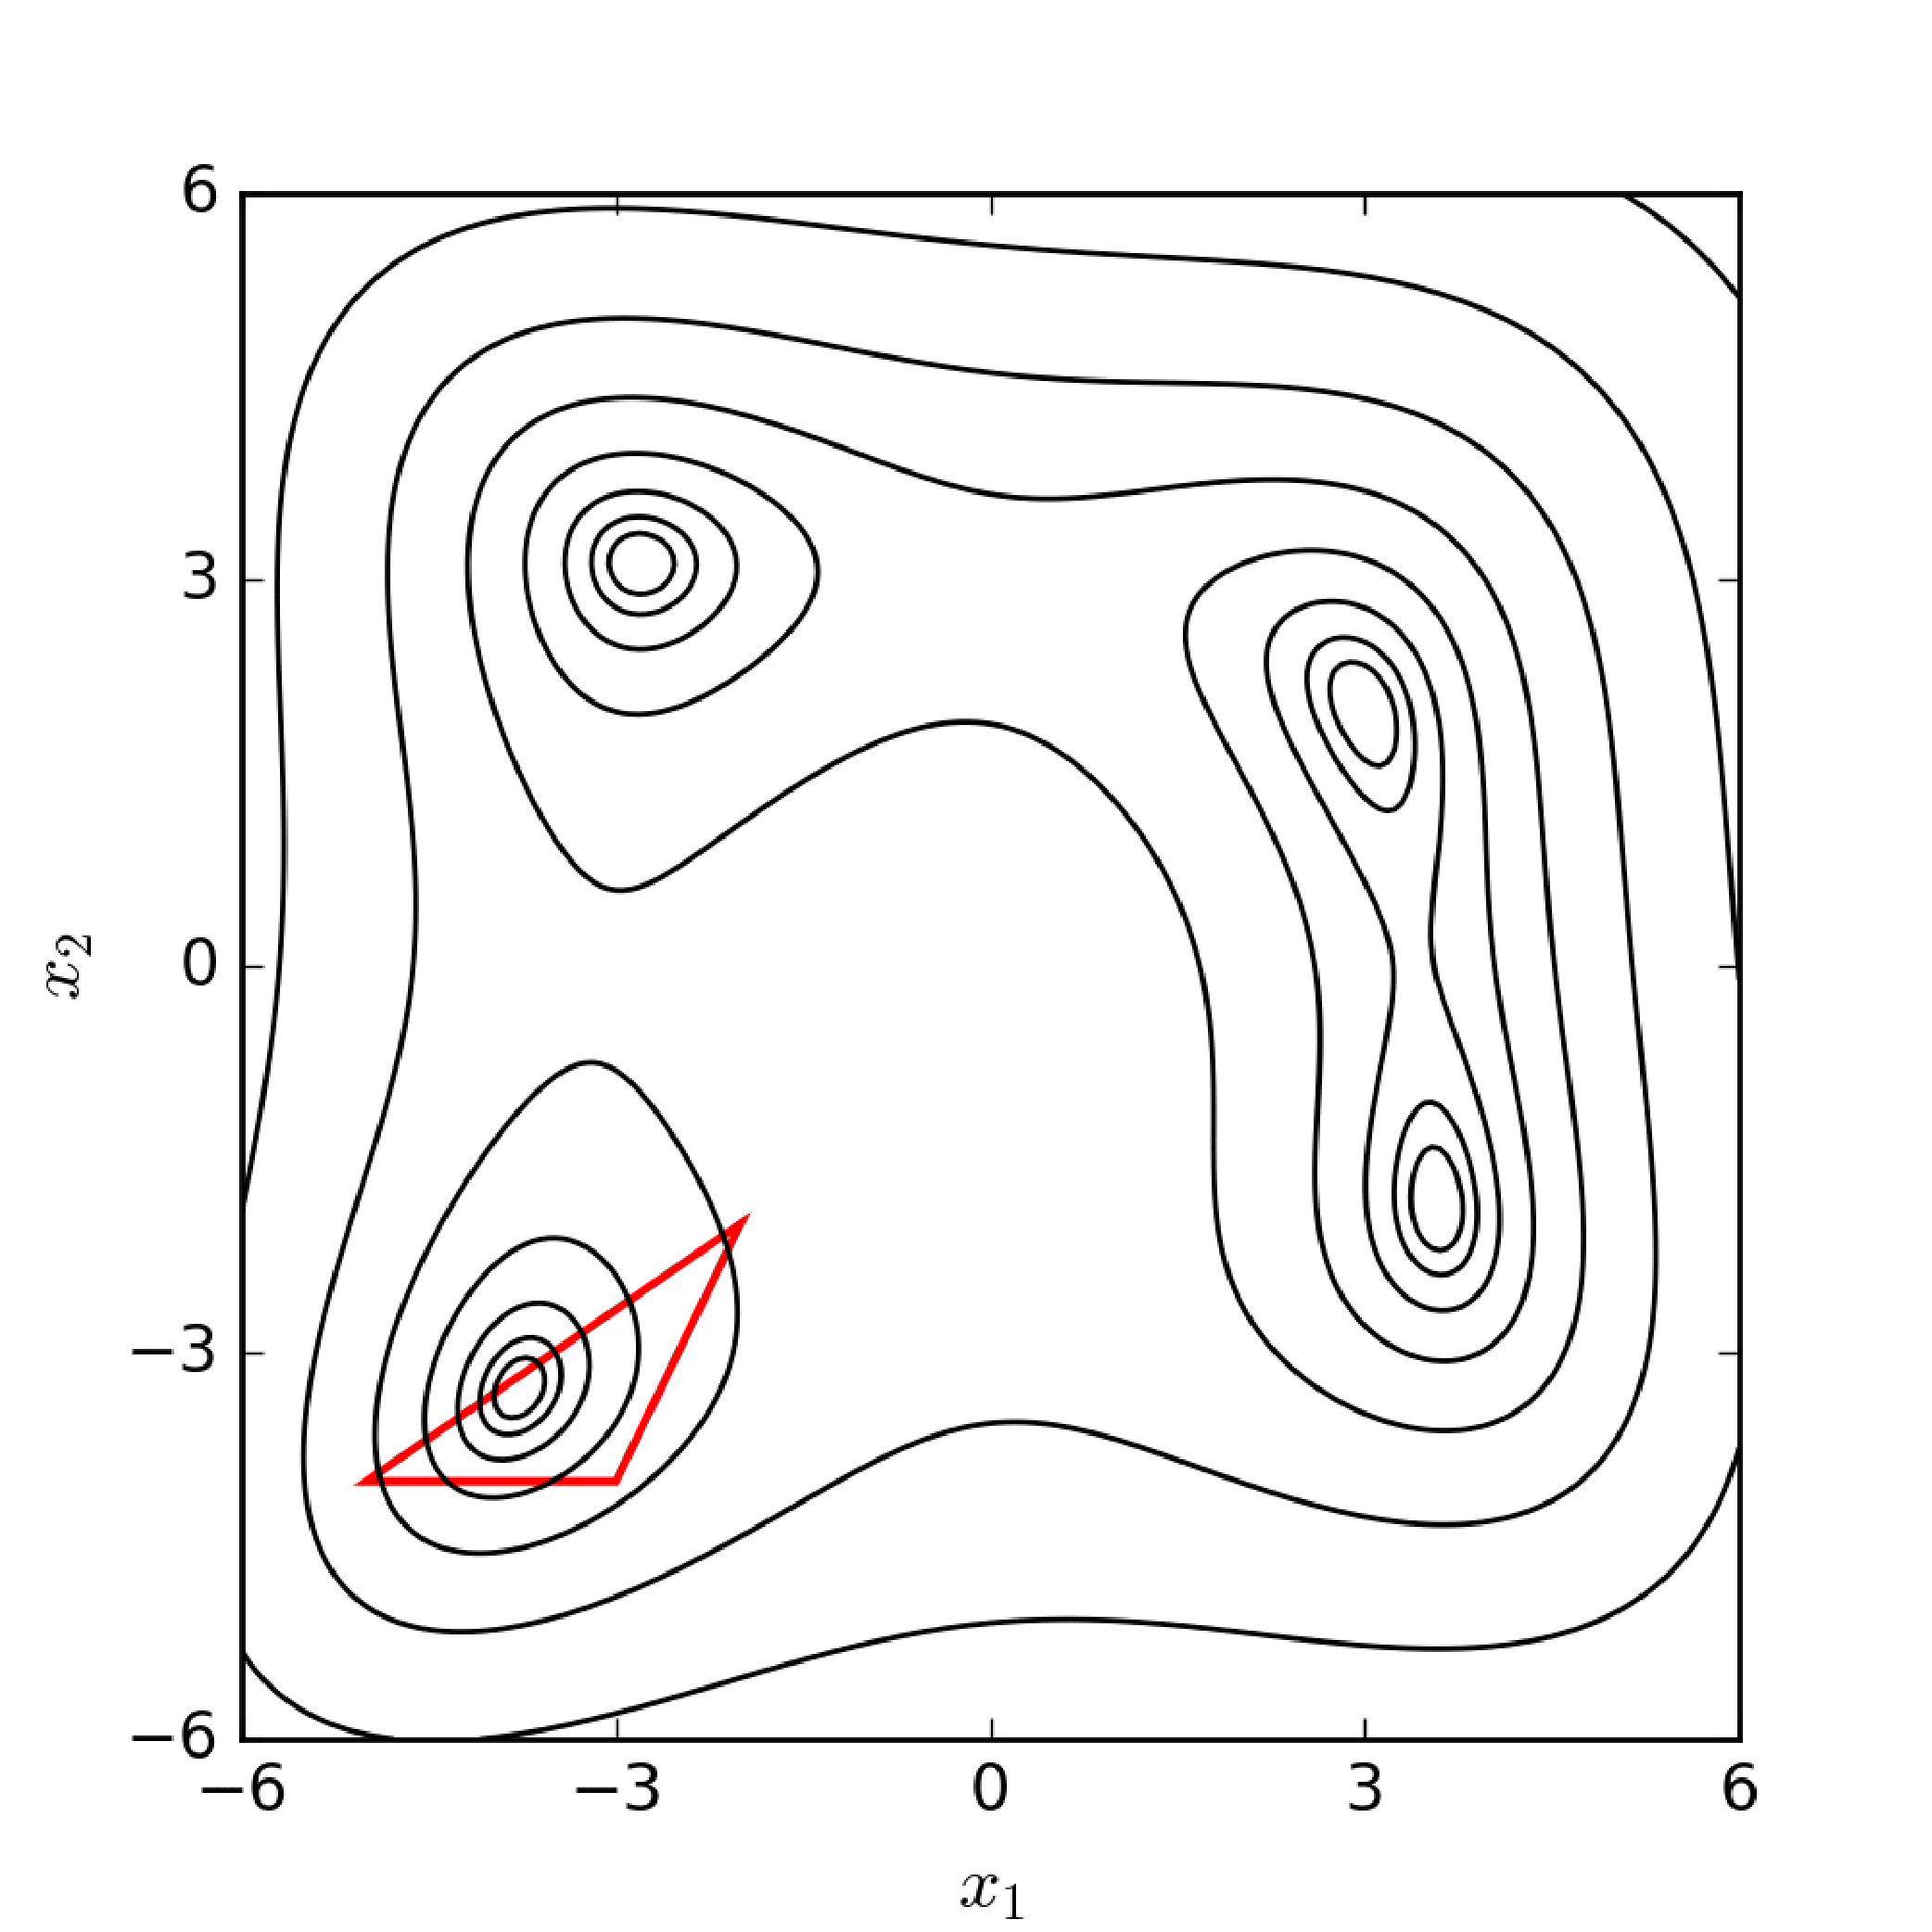 Figure 6
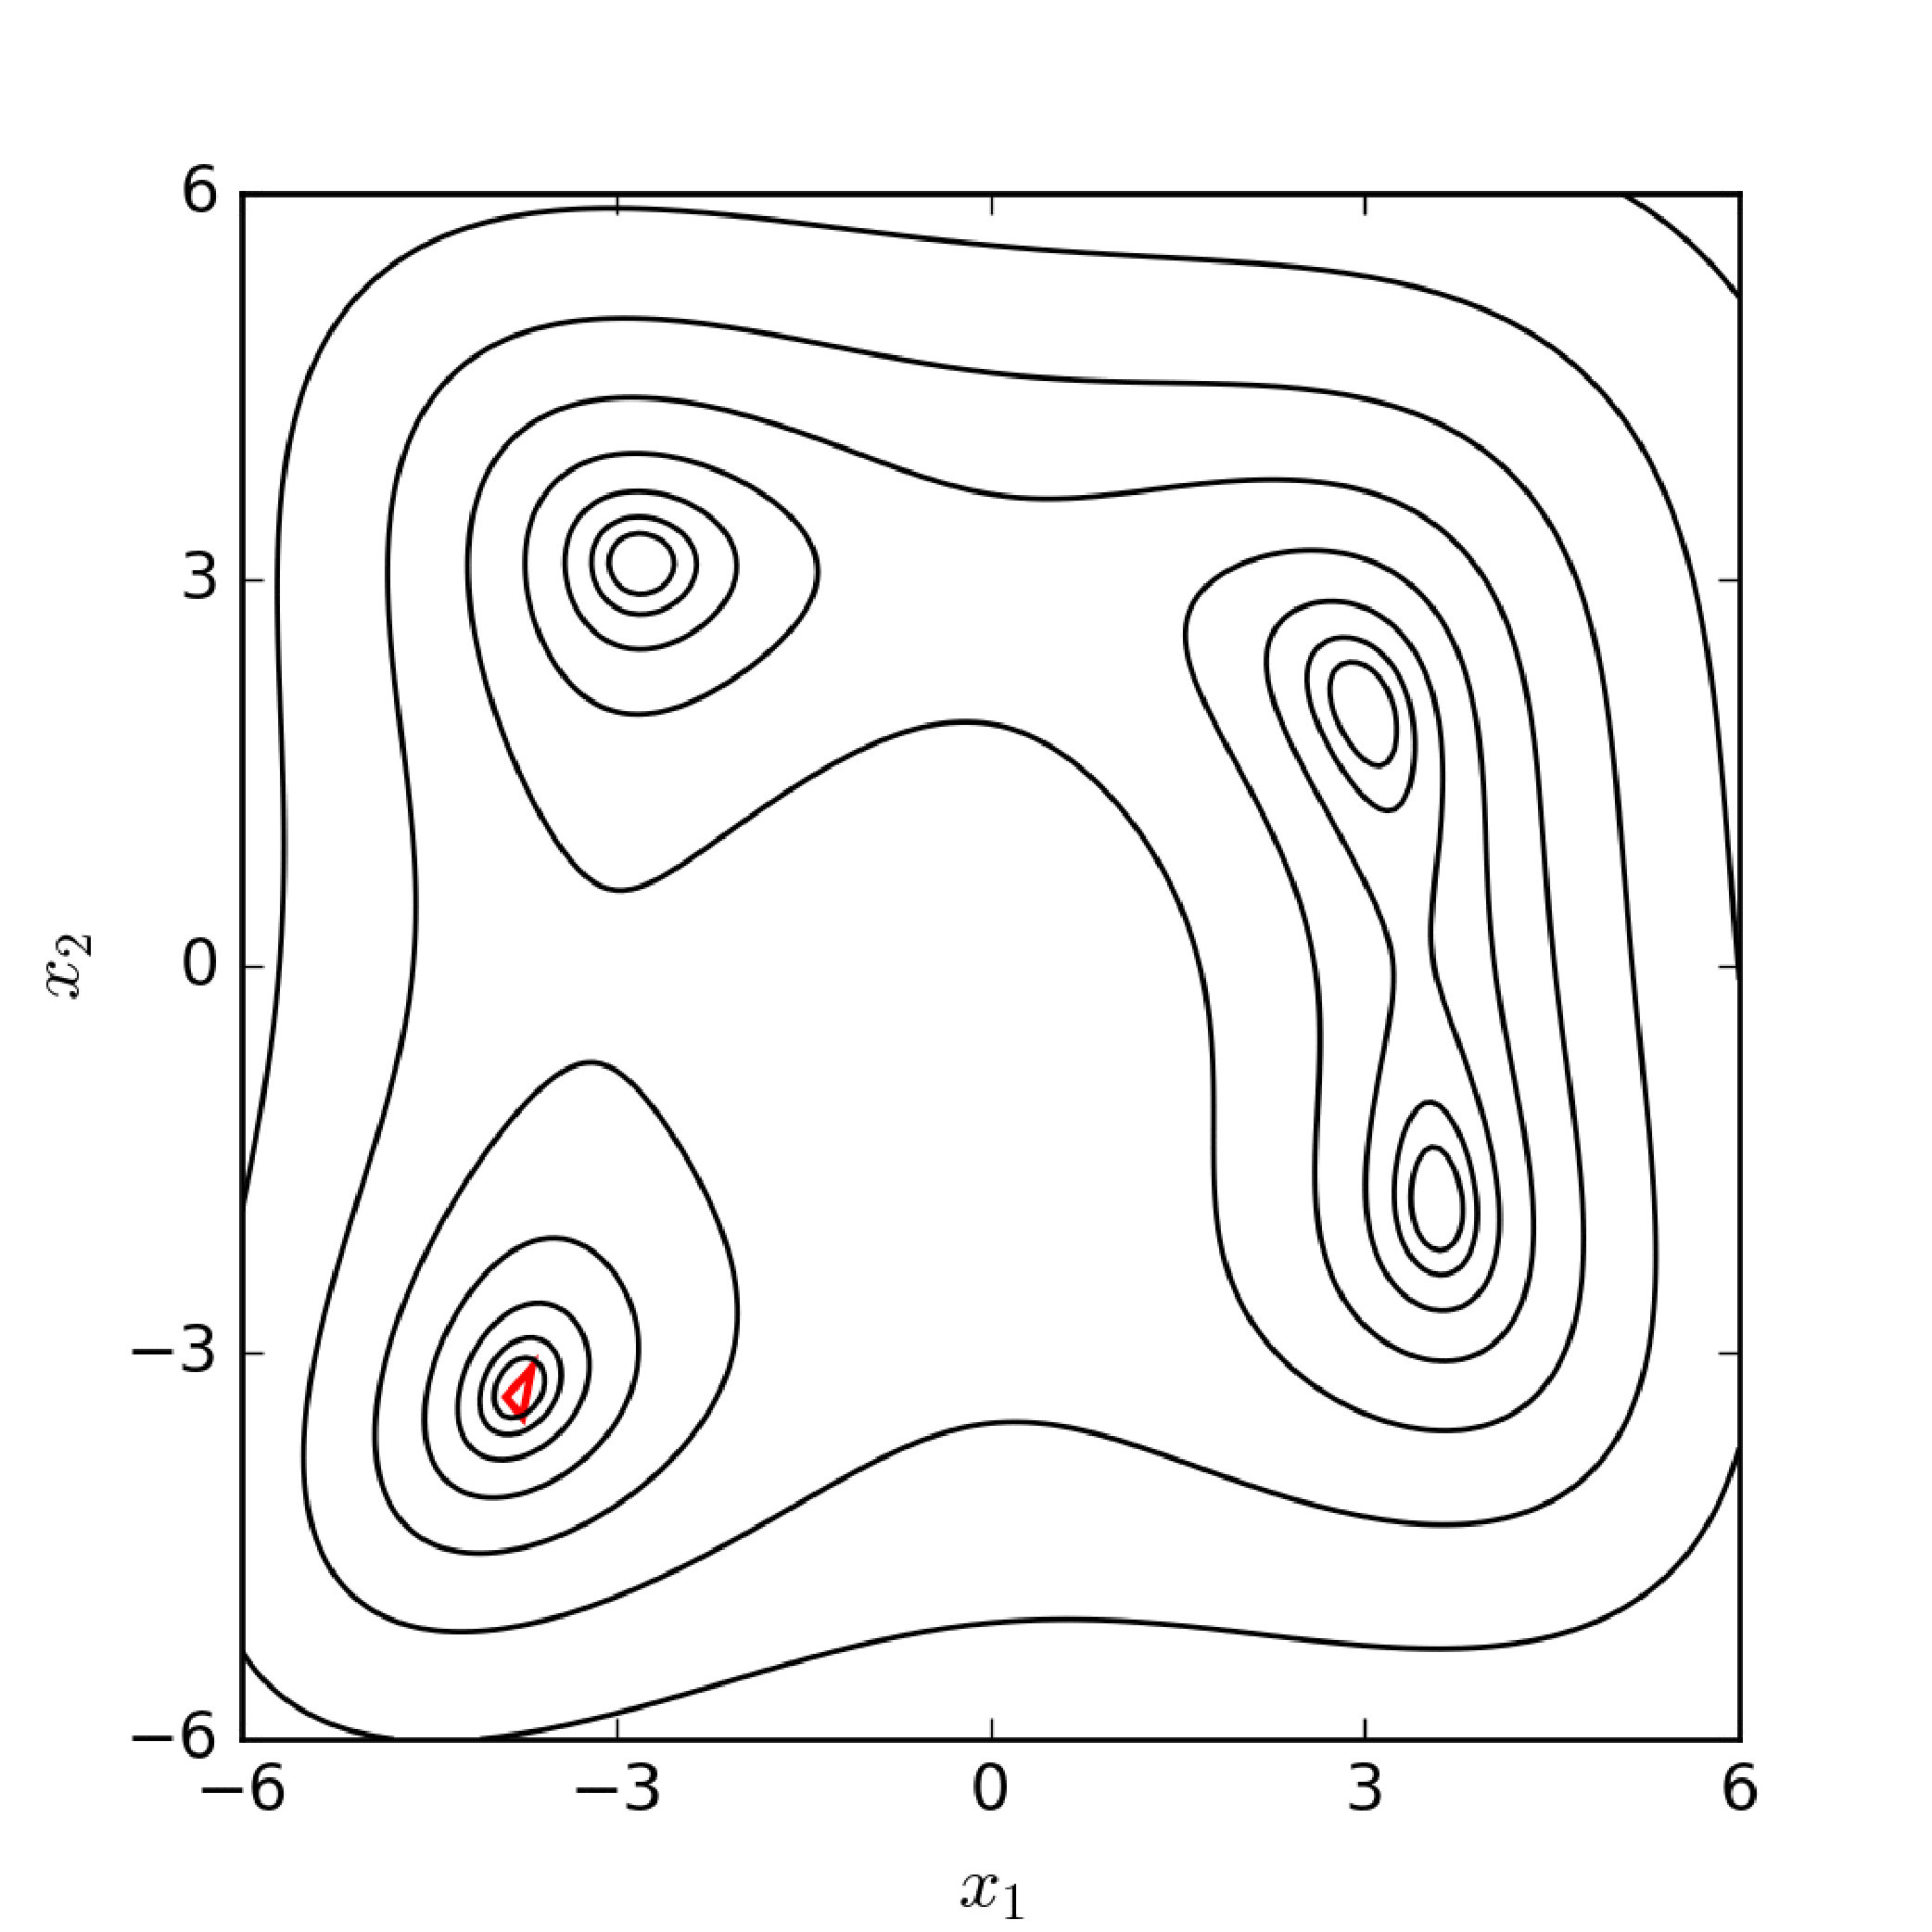 Figure 7
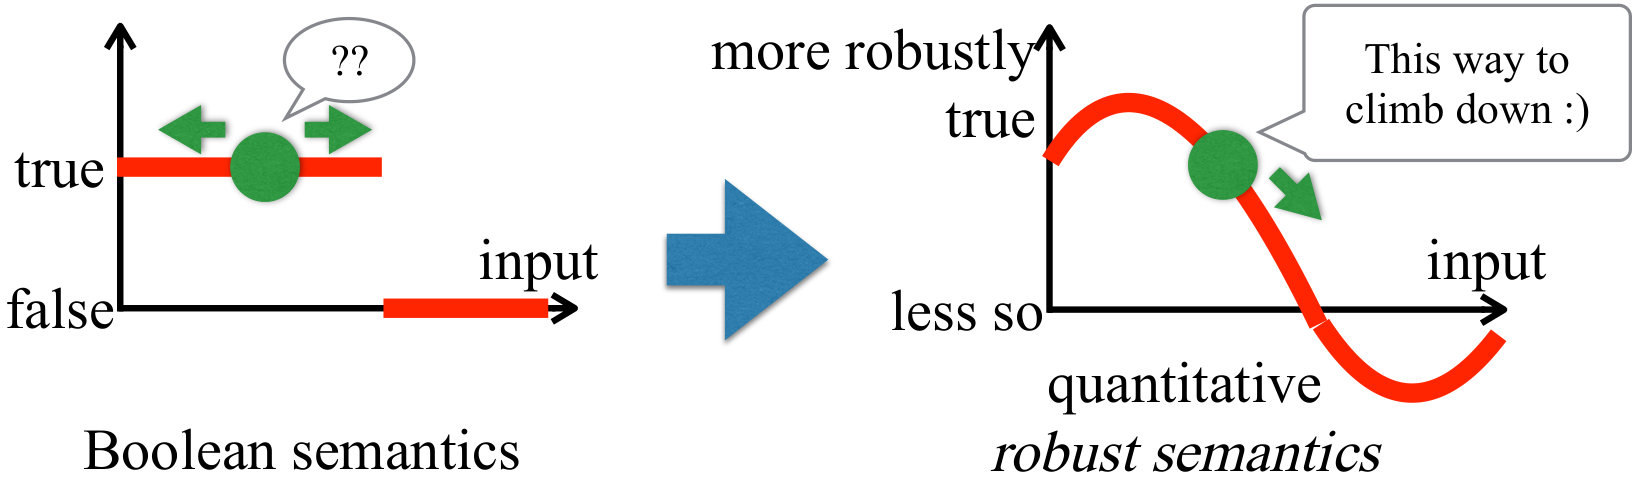 Figure 8
| model | Automatic Transmission | Abst. Fuel Ctrl. | ||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| spec. | S1 | S2 | S3 easy | S3 hard | S4 easy | S4 mid | S4 hard | S init | S stable | |||||||||
| algorithm | time | #/20 | time | #/20 | time | #/20 | time | #/20 | time | #/20 | time | #/20 | time | #/20 | time | #/20 | time | #/20 |
| CMA-ES | 27s | 20 | 5s | 20 | 39s | 14 | 57s | 0 | 32s | 16 | 37s | 9 | 59s | 0 | 49s | 0 | 82s | 1 |
| +TS | 52s | 15 | 15s | 16 | 9s | 19 | 23s | 11 | 15s | 14 | 14s | 14 | 24s | 3 | 30s | 0 | 42s | 1 |
| +A-TS | 41s | 18 | 15s | 17 | 9s | 16 | 21s | 10 | 26s | 14 | 22s | 14 | 20s | 5 | 26s | 0 | 41s | 0 |
| SA | 50s | 5 | 43s | 7 | 37s | 9 | 55s | 0 | 35s | 6 | 36s | 9 | 47s | 5 | 51s | 0 | 76s | 2 |
| +TS | 37s | 20 | 33s | 16 | 11s | 19 | 33s | 8 | 21s | 14 | 25s | 13 | 51s | 0 | 47s | 1 | 54s | 7 |
| +A-TS | 34s | 20 | 18s | 17 | 9s | 18 | 26s | 4 | 16s | 18 | 21s | 11 | 30s | 2 | 34s | 0 | 42s | 5 |
| GNM | 6s | 20* | 61s | 0* | 56s | 0* | 55s | 0* | 43s | 0* | 46s | 0* | 53s | 0* | 50s | 0* | 86s | 0* |
| +TS | 42s | 20* | 15s | 20* | 13s | 20* | 25s | 20* | 11s | 20* | 45s | 0* | 52s | 0* | 30s | 20* | 20s | 20* |
| +A-TS | 20s | 20* | 16s | 20* | 10s | 20* | 26s | 20* | 13s | 20* | 45s | 0* | 43s | 0* | 37s | 0* | 19s | 20* |
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
\setlistdepth
20
Time-Staging Enhancement of
Hybrid System Falsification ††thanks: Presented at SNR’2018. G. Ernst and Z. Zhang were then at the National Institute of Informatics.
Gidon Ernst LMU Munich, Germany [email protected] National Institute of Informatics, Tokyo, JapanKyushu University, JapanUniversity of Waterloo, Waterloo, Canada
Ichiro Hasuo National Institute of Informatics, Tokyo, Japan [email protected] Kyushu University, JapanUniversity of Waterloo, Waterloo, Canada
Zhenya Zhang Kyushu University, Japan [email protected] University of Waterloo, Waterloo, Canada
Sean Sedwards University of Waterloo, Waterloo, Canada [email protected]
Abstract
Optimization-based falsification employs stochastic optimization algorithms to search for error input of hybrid systems. In this paper we introduce a simple idea to enhance falsification, namely time staging, that allows the time-causal structure of time-dependent signals to be exploited by the optimizers. Time staging consists of running a falsification solver multiple times, from one interval to another, incrementally constructing an input signal candidate. Our experiments show that time staging can dramatically increase performance in some realistic examples. We also present theoretical results that suggest the kinds of models and specifications for which time staging is likely to be effective.
1 Introduction
Hybrid Systems
Quality assurance of cyber-physical systems (CPS) has been recognized as an important challenge, where many CPS are hybrid systems that combine the discrete dynamics of computers and the continuous dynamics of physical components. Unfortunately, analysis of hybrid systems poses unique challenges, such as the limited applicability of formal verification. In formal verification one aims to give a mathematical proof for a system’s correctness. This is much harder for hybrid systems than for computer software/hardware, where the presence of continuous dynamics makes many problems more complex or even undecidable (e.g. reachability in hybrid automata).
Optimization-Based Falsification
Because of these difficulties, an increasing number of researchers are turning to optimization-based falsification as a quality assurance measure. It is a testing method rather than that of formal verification; the problem is formalized as follows.
- •
Given: a model (that takes an input signal and yields an output signal ), and a specification (a temporal formula)
- •
Answer: error input, that is, an input signal such that the corresponding output violates
\textstyle{\mathbf{u}}$$\textstyle{\mathcal{M}}$$\textstyle{\mathcal{M}(\mathbf{u})}$$\textstyle{\not\models\varphi\;?}
In the optimization-based falsification approach, the above falsification problem is turned into an optimization problem. This is possible thanks to robust semantics of temporal formulas [15]. Instead of the Boolean satisfaction relation , robust semantics assigns a quantity that tells us, not only whether is true or not (by the sign), but also how robustly the formula is true or false. This allows one to employ hill-climbing optimization (see Fig. 1): we iteratively generate input signals, in the direction of decreasing robustness, hoping that eventually we hit negative robustness.
Optimization-based falsification is a subclass of search-based testing: it adaptively chooses test cases (input signals ) based on previous observations. One can use stochastic algorithms for optimization (such as simulated annealing), which turn out to be much more scalable than many model checking algorithms that rely on exhaustive search. Note also that the system model can be black box: it is enough to know the correspondence between input and output . An error input is concrete evidence for the system’s need for improvement, and thus has great appeal to practitioners.
The approach of optimization-based falsification was initiated in [15] and has been actively pursued ever since [6, 4, 8, 21, 9, 11, 12]. There are now mature tools, such as Breach [9] and S-Taliro [6], which work with industry-standard Simulink models.
Contribution
We introduce a simple idea of time staging for enhancement of optimization-based falsification. Time staging consists of running a falsification solver repeatedly, from one input segment to another, incrementally constructing an input signal.
In general, in solving a concrete problem by a metaheuristic (such as stochastic optimization, evolutionary computation, etc.), a key to success is to communicate as much information as possible in the translation from to —that is, to let exploit structures unique to . Our idea of time staging follows this philosophy. More specifically, via time staging we communicate the time-causal structure of time-dependent signals—a structure that is present in some instances of the falsification problem but not in optimization problems in general—to stochastic optimization solvers.
Our implementation of time-staged falsification is based on Breach [9]. We show that this simple idea can dramatically enhance its performance in some examples. We also present some theoretical considerations on the kinds of problem instances where time staging is likely to work, and some results that aid implementation of time staging.
Structure of the Paper
In §2 we informally outline optimization-based falsification and illustrate the idea of time staging. We then turn to formal developments: in §3 we review existing falsification works and in §4 we present our algorithm, augmented by some theoretical results that aid its implementation. §5 is devoted to the theoretical consideration of two specific settings in which time staging is guaranteed to work well. These settings will serve as useful “rules of thumb” for practical applications. In §6 we discuss our implementation and experimental results. We conclude in §8.
2 Schematic Overview: Falsification and Time Staging
We illustrate falsification and time staging, informally with an example.
Example Setting
We take as a system model a simple automotive powertrain whose input signal is -dimensional (the throttle ) and whose output signal is the vehicle speed . We assume that exhibits the following natural behavior: the larger is, the quicker grows. Let our specification be \varphi\equiv\bigl{(}\Box(v\leq 120)\bigr{)}, where denotes the syntactic equality. To falsify the vehicle speed must exceed . From the assumption about ’s behavior, we expect to be large in a falsifying input signal. Note that this is a simplified version of one of our experiments in §6.
Optimization-Based Falsification
Fig. 5 illustrates how a conventional optimization-based falsification procedure works. In the -th sampling one tries an input signal . Following the falsification literature we focus on piecewise constant signals. Thus a signal is represented by a sequence of real numbers. See the top left of Fig. 5. The corresponding output signal is shown below it.
Since does not reach the threshold , we move on to the -th sampling and try a new input signal . The choice of is made by an optimization algorithm. Specifically, the optimization algorithm observes the results of the previously sampled input signals —especially the robustness value that each input achieves. In the current setting where \varphi\equiv\bigl{(}\Box(v\leq 120)\bigr{)}, the robustness value is simply the difference between and the peak vehicle speed. The optimization algorithm tries to derive some general tendency, which it then uses to increase the probability that the next input signal will make the robustness smaller (i.e. the peak vehicle speed higher).
Hill climbing is a prototype of such optimization algorithms. Its use in falsification is illustrated in Fig. 5, where is depicted as one-dimensional for clarity. The actual curve for the robustness value (gray and dashed) is unknown. Still the previous observations under input suggest that to the right is the climbing down direction. The next candidate is picked accordingly, towards negative robustness. Another well-known optimization algorithm is the Nelder-Mead algorithm. See Fig. 5, where the input space is two-dimensional and the (unknown) robustness function is depicted by contour lines.
We see in the right of Fig. 5 that the new input signal leads to a corresponding output signal that reduces the robustness value by achieving a higher peak speed. We continue this way, , hoping to eventually reach a falsifying input signal.
Absence of the Time-Causal Information
A closer look at Fig. 5 reveals room for improvement. In Fig. 5, the new input signal indeed achieves a smaller overall robustness than . However, its initial segment is smaller than ; consequently the vehicle speed is smaller than in the first few seconds. Keeping the initial segment would have achieved an even greater peak speed.
The problem here is that the time-causal structure inherent in the problem is not explicitly communicated to the optimization algorithm. The relevant structure is more specifically time monotonicity: an input prefix that achieves smaller robustness (i.e. a greater peak speed) is more likely to extend to a full falsifying input signal. Although it is possible that a stochastic optimization algorithm somehow “learns” time monotonicity, it is not guaranteed, because the structure of input spaces (the horizontal axis in Fig. 5 and the squares in Fig. 5) does not explicitly reflect time-causal structures.
While the time monotonicity is not shared by all instances of the falsification problems, we find many realistic instances that approximately satisfy the property. We discuss time monotonicity in §5, as well as in the context of our experiments in §6.
Falsification with Time Staging
Our proposal of time staging consists of incrementally synthesizing a candidate input signal. We illustrate this in Fig. 5. In the first stage (left), we run a falsification algorithm and try to find an initial input segment that achieves low robustness (i.e. high peak speed). This first stage comprises running samplings, as illustrated in Fig. 5. This process will gradually improve candidates for the initial input segment, in the way the arrows on the left in Fig. 5 designate. Let us assume that the last candidate is the (tentative) best, achieving the smallest robustness.
In the second stage (on the right in Fig. 5) we continue and synthesize the second input segment. This is again by running a falsification algorithm, as depicted. Note that, in each stage (a box in Fig. 5), the whole iterated process in Fig. 5 is conducted. In this way we continue to the -th stage, always starting with the input segment that performed the best in the previous stage, thus exploiting the time-causal structure.
While time staging is not difficult to implement, there is a challenge in using it effectively. An immediate question is whether choosing the single best input segment in each stage is the optimal approach. Our current strategy favors exploitation over exploration: it might miss a falsifying signal whose robustness must decrease slowly in the earlier segments and only quickly in the latter segments. Indeed we are working on an evolutionary variant of the above time-staged algorithm, where multiple segments are passed over from one stage to another, in order to maintain diversity and conduct exploration. That said, even under the current simple strategy of picking the best one, we observe significant performance enhancement in some falsification problems. See §6.
We can summarize this trade-off in terms of the size of search spaces. Let be the set of candidates for input segments, and be the number of stages. Then the size of the set of whole input signals is , choosing one input segment for each stage. In our staged algorithm, in contrast, the search space for each stage is and overall our search space is . This reduction comes with the risk of missing some falsifying input signals. The experimental results in §6 suggest this risk is worth taking. Moreover, in §5 we present some theoretical conditions for the absence of such risk. They help users decide in practical applications when time staging will be effective.
3 Optimization-Based Falsification
From this section on we turn to the formal description and analysis of our algorithm. This section presents a review of existing works on optimization-based falsification.
System Models
Let us formalize our system models.
Definition 3.1** (time-bounded signal).**
Let be a positive real. A (time-bounded) -dimensional signal with a time horizon is a function .
Let and be (time-bounded) signals. Their concatenation is defined by if , and if .
Let such that . The restriction of to the interval is defined by .
Definition 3.2** (system model ).**
A system model, with -dimensional input, is a function that takes an input signal and returns . Here the common time horizon is arbitrary.
Furthermore, we impose the following causality condition on . For any time-bounded signals and , we require that \mathcal{M}(\mathbf{u}\cdot\mathbf{u}^{\prime})\big{|}_{[0,T]}=\mathcal{M}(\mathbf{u}).
Note that does not hold in general: feeding can change the internal state of . This motivates the following definition.
Definition 3.3** (continuation ).**
Let be a system model and be a signal. The continuation of after , denoted by , is defined as follows. For an input signal : .
Signal Temporal Logic and Robust Semantics
We review signal temporal logic (STL) [22] and its robust semantics [15, 11]. is the set of variables, and let . Variables stand for physical quantities, control modes, etc. denotes syntactic equality.
Definition 3.4** (syntax).**
In STL, atomic propositions and formulas are defined as follows, respectively: , and . Here is an -ary function , , and is a closed non-singular interval in , i.e. or where and .
We omit subscripts for temporal operators if . Other common connectives like , (always) and (eventually), are introduced as abbreviations: and . Atomic formulas like , where is a constant, are also accommodated by using negation and the function .
Definition 3.5** (robust semantics [11, 10]).**
For an unbounded -dimensional signal and , denotes the -shift of , that is, .
Let be a signal (recall ), and be an STL formula. We define the robustness as follows, by induction. Here and denote infimums and supremums of real numbers, respectively.
[TABLE]
Here are some intuitions and consequences. The robustness stands for the vertical margin for the signal at time [math]. A negative robustness value indicates how far the formula is from being true. The robustness for the eventually modality is computed by .
The original semantics of STL is Boolean, given by a binary relation between signals and formulas. The robust semantics refines the Boolean one, in the sense that: implies , and implies . Optimization-based falsification via robust semantics [15] hinges on this refinement. See [11].
Although the definitions so far are for unbounded signals only, we note that the robust semantics , as well as the Boolean satisfaction , allows straightforward adaptation to time-bounded signals (Def. 3.1). See Appendix A.
Falsification Solvers
In the next definition, a prototype of a score function is given by the robustness of a given STL specification . The generality of allowing other is needed later in §4.
[TABLE]
Definition 3.6** (falsification solver).**
A falsification solver is a stochastic algorithm that takes, as input:
- a system model (Def. 3.2) with -dimensional input;
- a score function that takes an output signal of and returns a score ; and
a time horizon . The algorithm returns an -dimensional signal .
Each invocation of the solver is called a falsification trial. It is successful if the returned signal satisfies . Note that the returned signal can differ in every trial, since is a stochastic algorithm.
We further assume the internal structure of the solver follows the scheme in Algorithm 1. It consists of two phases. The first initial sampling phase collects some candidates for regardless of the system model or the score function . In the second optimization sampling phase, a stochastic optimization algorithm is employed to sample a candidate that is likely to make the score small.
Implementation of Falsification Solvers
Both Breach [9] and S-Taliro [6] take industry-standard Simulink models as system models. For input signal candidates the tools focus on piecewise constant signals; they are represented by sequences of real numbers, much like in §2. Here is the number of control points; in our staged algorithm we use the same for the number of stages.
The tools offer multiple stochastic optimization algorithms for the optimization sampling phase, including CMA-ES [7], global Nelder-Mead and simulated annealing. The initial sampling phase is mostly by random sampling. Additionally, in Breach with global Nelder-Mead, so-called corner samples are added to the list . The number of corner samples grows exponentially as grows, i.e. as we have more control points.
4 Time Staging in Optimization-Based Falsification
Definition 4.1** (time-staged deployment of falsification solver).**
Let be a system model, be an STL formula, and be a time horizon. Let be a parameter; it is the number of time stages. The time-staged deployment of a falsification solver is the procedure in Algorithm 2. On the line 4, the model is the continuation of after (Def. 3.3); the score function is defined by
[TABLE]
The whole procedure is stochastic (since is); an invocation is called a time-staged falsification trial. It is successful if the returned signal satisfies .
A falsification trial (i.e. an invocation of Algorithm 1) is an iterative process: the more we sample, the more likely we obtain a falsifying input signal. Since we run multiple falsification trials in Algorithm 2 (one trial for each of the stages), an important question is how we distribute available time to different stages.
A simple strategy is to fix the number of samples in each phase of Algorithm 1. Then the predicates and are given by and , where are constants.
An adaptive strategy, that we also implemented for the optimization sampling phase, is to continue sampling until we stop seeing progress. Here we fix a parameter , and we stop after consecutive samplings without reducing robustness. A similar strategy of adaptively choosing the number of samples can be introduced for random sampling in the initial sampling phase (the lines 3–5 of Algorithm 1).
4.1 Towards Efficient Implementation
A key to speedup of Algorithm 2 is in the line 4; more specifically, how we handle the previous input prefix . Here we discuss two directions, one on the model and the other on the score function . (We note that the suggested enhancements are not currently used in our implementation, because of performance reasons. See below.)
Continuation of Models
Optimization-based falsification has a very wide application domain. Since it only requires a black-box model , the concrete form of can vary from a program to a Simulink model and even a system with hardware components (HILS). These models can be very big, and usually the bottleneck in falsification lies in simulation, that is, to compute given an input signal .
In the line 4 of Algorithm 2, therefore, using the definition in Def. 3.3 is in principle not a good strategy: it requires simulation of for the whole prefix , which can be avoided if we can directly simulate the continuation . In Simulink this is possible by saving the snapshot of the model after a simulation, via the SaveFinalState model configuration parameter. In our implementation we do not do so, though, because the overhead of saving and loading snapshots is currently greater than the cost of simulating. This balance can become different, if we figure out a less expensive way to use snapshots, or if we study more complex models.
Derivative of Formulas
The situation is similar with the score function in the line 4 of Algorithm 2. Using the presentation in (2) requires scanning the same prefix repeatedly. Desired here is a syntactic presentation of , that will be given as an STL formula such that . This would allow one to utilize available algorithms for computing robustness values .
Definition 4.2** (derivative of flat STL formulas).**
Let , and be a signal. Given an STL formula that is flat in the sense that it does not have nested temporal operators, the derivative by is defined inductively as follows.
[TABLE]
Here the interval is obtained by shifting endpoints, such as . For each , the notation abbreviates the atomic formula , where is thought of as a constant function. We use the fact that .
Until formulas are split into the evaluation on the signal prefix (first disjunct), and a continuation (second disjunct). The constant injects the robustness of seen so far into the residual formula (recall that both of and take the infimum). It follows that \partial_{\mathbf{v}}\bigl{(}\Box_{I}~{}\varphi\bigr{)}\equiv\mathsf{c}_{\llbracket\mathbf{v},\Box\varphi\rrbracket}\land\Box_{I-T}~{}\varphi and \partial_{\mathbf{v}}\bigl{(}\Diamond~{}\varphi\bigr{)}\equiv\mathsf{c}_{\llbracket\mathbf{v},\Diamond\varphi\rrbracket}\lor\Diamond_{I-T}~{}\varphi.
Proposition 4.3**.**
Let , be a signal, and be a flat STL formula. We have, for any , .
A proof is in Appendix B. Use of derivatives for timed specifications is also found e.g. in [23]. The settings are different, though: Boolean semantics in [23] while our semantics is quantitative. Our restriction to flat formulas comes mainly from this difference, and lifting the flatness restriction seems hard.
5 Sufficient Conditions for Time Staging
We present some theoretical analyses of the performance of time staging that indicate to which class of systems the time-staged approach can apply. We give some sufficient conditions under which the approach is guaranteed to work. However, it should be noted that it is not necessary that a concrete system satisfies these conditions strictly as these are rather restrictive. Nevertheless, we believe that users with expert domain knowledge can judge whether their models satisfy these conditions approximately. This way our results provide those users with “rules of thumb.”
As we discussed in the last paragraph of §2, the potential performance advantage by time staging comes from the reduction of search spaces from to . Here is the set of potential input segments for each stage, and is the number of stages. This advantage comes at the risk of missing out some error input signals. The following basic condition (3), that we call incremental falsification, ensures that there is no such risk. More precisely, we can decompose the “best” input signal into a first stage and its remainder such that the entire falsification problem (left hand side) is solved by greedy optimization of the initial segment (inner ), and subsequent optimization of the continuation (outer ). For all choices of with ranges and :
[TABLE]
Algorithm 2 repeatedly unfolds (3) by picking constant where is the time horizon and is the number of stages. The rest of this section is devoted to the search for concrete sufficient conditions for (3).
Monotone Systems and Ceiling Specifications
We formalize the time monotonicity property in §2. That it implies incremental falsification (3) can be easily proved.
Definition 5.1** (time-monotone falsification problem).**
A system model and an STL formula are said to constitute a time-monotone falsification problem if, for any input signals and , implies .
We investigate yet more concrete conditions that ensures time monotonicity. The following condition on system models is assumed in the example of §2.
Definition 5.2** (monotone system, ceiling specification).**
Let be a variable (for output). A system model is said to be monotone in if, for each and , implies .
An STL formula of the form , where is a variable and is a constant, is called a ceiling formula.
One can speculate that a monotone system and a ceiling specification , like those in §2, constitute a time-monotone falsification problem. The speculation is not true, unfortunately; a counterexample is easily constructed using a model whose output signal is not increasing. We can instead show the following weaker property.
Definition 5.3** (truncated time monotonicity).**
A system model and an STL formula constitute a truncated time-monotone falsification problem if, for any input and , implies existence of such that
Proposition 5.4**.**
Let be a model monotone in , and \varphi\equiv\bigl{(}\Box(x<c)\bigr{)}. Then and constitute a truncated time-monotone falsification problem.
The proof, in Appendix C.1, constructs a concrete choice of in Def. 5.3. Specifically it is the instant in which the robustness is minimum. In the scenario of §2 this is the instant that the vehicle speed is in its peak. Note that truncated time monotonicity does not guarantee incremental falsification as per (3), but it implies that the current rigid time staging at is not optimal. These theoretical considerations suggest potential improvement of the staged procedure in Def. 4.1 with adaptive choice of stages, which is left for future work.
Stateless Systems and Reachability Specifications
Here is another sufficient condition.
Definition 5.5** (stateless system, reachability formula).**
A system model is said to be stateless if, for any input signals and , we have .
An STL formula , where is modality-free, is called a reachability formula.
Note that being stateless is a sufficient but not necessary condition for . Statelessness requires insensitivity to previous input prefixes, but a stateless system can still be sensitive to time.
Proposition 5.6**.**
Let be a stateless system and be a reachability specification . Then and satisfy the incremental falsification property (3).
A proof is easy. A typical situation in which we would appeal to Prop. 5.6 is when: the specification is (which can be hard to falsify if are close); and the system is already in its stable state (so that its behavior does not depend much on what happened during the transient phase). Our experiments in §6 demonstrate that time staging can drastically improve performance in such settings.
Corner Samples for Global Nelder-Mead
The reduction of search spaces from to has its analogue in the number of corner samples in Breach with global Nelder-Mead (lines 3–5 of Algorithm 1, see the last paragraph of §3). Originally the number of corner samples is , where is the number of control points and is the number of input values. By introducing time stages, the total number of corner samples is reduced to .
6 Experiments
We compare the success rate and time consumption of the proposed method. The benchmarks here use automotive Simulink models that are commonly used in the falsification literature. Specifications are chosen taking the deliberations of §5 into account, namely with ceiling specifications (Def. 5.2, including the example of §2), a reachability specification (Def. 5.5) and a combination thereof.
The base line is Algorithm 1 implemented by Breach [9]. The methods proposed in §4 are implemented on top of Breach: the time-staged Algorithm 2 (TS), and the adaptive strategy (A-TS, the one described after Def. 4.1). All three algorithms (plain, TS, A-TS) are combined with different optimization solvers: CMA-ES, simulated annealing (SA), global Nelder-Mead (GNM), obtaining a total of nine configurations.
The results in Table 1 indicate that both success rate and runtime performance are significantly improved by time staging, often finding counterexamples when non-staged Breach fails (e.g. columns S3 hard and S init). Furthermore, we see that while the adaptive algorithm (A-TS) does not necessarily lead to a higher success rate in comparison to the time-staged one (TS), it gives yet another runtime performance improvement. However, as discussed in detail in §6, there is no overall best algorithm, and time staging affects the optimization algorithms differently depending on the problem.
Benchmarks
Automatic Transmission is a Simulink model that was proposed as a benchmark for falsification in [16]. It has input values and , and outputs the car’s speed , the engine rotation , and the selected gear .
With this model we consider five specifications S1–5. The first two are ceiling ones. Specification S1 (cf. the example in §2) states the speed be always below a threshold. This property is easily falsified with . Specification S2 states that it is not possible to drive slowly in a high gear. A falsifying trajectory first has to speed up to reach this gear and subsequently roll out until speed falls below the threshold. This latter part of the trajectory can again be seen as a ceiling specification. Note that this property is interesting because the robustnes does not provide any guidance unless gear 3 has been entered by the system.
Specification S3 is a reachability problem, , that encodes the search for a trajectory that keeps the speed between a lower and upper bound. The falsification problem consists of two sub-challenges: 1) hitting this speed interval precisely after an initial acceleration up to 10s simulated time; and 2) maintaining a correct speed till the time horizon. This suggests that a natural decomposition of the problem can indeed be achieved by separating these two aspects in time.
Specification S4 expresses that speed can only be reached with an engine rotation exceeding a threshold . This specification is mentioned in [16] and evaluated in e.g., [5, 4], too. To falsify, a trajectory must be found that reaches speed early with an engine rotation lower than . The difficulty increases with higher and lower , respectively. The formula represents the mixture of ceiling and reachability specifications.
The second system model is Abstract Fuel Control from [18]. It takes two input values, pedal angle (from ) and engine speed (from ); it outputs air-fuel ratio , which influences fuel efficiency and performance of the car. The value of is expected to be close to a reference value . According to [18], this setting corresponds to the so-called normal mode, where is constant.
We used the specification : the air-fuel ratio does not deviate from an acceptable range for more than seconds. We evaluated this specification with two parameter sets: the initial period with a larger error margin, and the stable period with a smaller margin. See Table 1 for parameter values.
Experimental Setup and Results
For the experiments with the Automatic Transmission model, the input signals were piecewise constant with 5 control points. The time horizon was . The parameters outlined in §4 were as follows: the maximum number of samplings for each plain (non-staged) falsification trial was (initial and optimization samplings combined). In the time-staged (TS) trials, we make the number of stages coincide with that of control points. Analogously, the sampling budget per stage was set to for stages, resulting in overall 150 samplings. The adaptive algorithm (A-TS) ran with the threshold per each of five stages. The experiments with the Abstract Fuel Control model were run up to the time horizon where and are as in Table 1. We used three and five stages, respectively, for the initial and stable specifications. These again coincide with the number of control points. The TS algorithms conducted 30 samplings in each stage.
The experiments ran Breach version 1.2.9 and MATLAB R2017b on an Amazon EC2 c4.8xlarge instance with a 36 core Intel(R) Xeon(R) CPU (2.90GHz) and 58G of main memory. However, we did not use the opportunity to parallelize, and the time reported is in the same order of magnitude as that of a modern desktop workstation.
The results are shown in Table 1. They are grouped by the underlying stochastic optimization algorithm: CMA-ES, simulated annealing (SA) and global Nelder-Mead (GNM). In each group, we compare plain (unstaged) Breach to the time-staged (TS) and the adaptive time-staged (A-TS) ones. We compare average runtimes (lower is better) and the success rate (higher is better), aggregated over 20 falsification trials for each configuration. Those good results which deserve attention are highlighted in bold. Note that the implementation of the global Nelder-Mead algorithm in Breach uses a deterministic source of quasi-randomness (Halton sequences), which implies that whether GNM finds a counterexample is consistent across all trials (marked with an asterisk ).
Discussion
Focusing on the Automatic Transmission model first, we see that CMA-ES works well for S1, although GNM performs even better (6s, supposedly because it uses corner samples, see §3). Time staging introduces overhead to CMA-ES and GNM, because each stage is optimized individually. In contrast, simulated annealing (SA) benefits from time staging for the two ceiling specifications S1–2. We presume that since SA emphasizes exploration, it benefits from exploitation added by time staging (cf. §2).
The second specification S2 is slightly more complex: before gear 3 is reached, there is no guidance from the robustness semantics, because masks any quantitative information on . Hence, falsifying this property needs some luck during the collection of initial samples in Algorithm 1. CMA-ES apparently exploits this, see top of column S2 of Table 1. Considering the other algorithms, SA and GNM, both benefit from time staging: exploitation of time causality prevents these good trajectory prefixes from being discarded accidentally once the required gear is reached (cf. Fig 5).
The results for S3 are evaluated with two different choices of parameters. The harder instance was falsified by the time-staged algorithms only, which can likely be attributed to the flattening of the search space from size to (§5). S4 is evidently harder than the previous ones. Time staging improves performance in a general tendency but not in all cases (SA for S4 hard).
The results for the Abstract Fuel Control model (the last two columns in Table 1) show that the time-staged algorithms boost the ability to falsify some rare events. The specification for the initial stage where is still unstable (S init) can be considered a rare event since all the three non-staged algorithms failed to falsify it. Time-staged SA and time-staged GNM managed to find error inputs. In the last column (stable period) is remarkable, too, where success rate and run time of SA and GNM significantly improved.
Overall, while the performance of the non-staged algorithms suffers from tightening the bounds, the time-staged versions are able to find falsifying trajectories with good success rates while at the same time exhibiting significantly shorter runtimes.
7 Related Work
Falsification is a special case of search-based testing, so considerable research efforts have been made towards coverage [4, 8, 21]. The benefits of coverage in falsification guarantees are twofold. Firstly, they indicate confidence for correctness in case no counterexamples are found. Paired with sound robustness estimates for simulations, one can cover a an infinite parameter space with finitely many simulations. C2CE [14] is a recent tool that computes approximations of reachable states using such an approach. Secondly, coverage can be utilized for a better balance between exploration and exploitation: stochastic optimization algorithms can be called in an interleaved manner, in which coverage guides further exploration. The approach based on Rapidly-Exploring Random Trees [12] puts an emphasis on exploration by achieving high coverage of the state space. In their algorithm, robustness-guided hill-climbing optimization plays a supplementary role. Compared to these works, our current results go in an orthogonal direction, by utilizing time causality to enhance exploitation. The so-called multiple-shooting approach to falsification [25] can be seen of a generalization of RRTs. It consists of: an upper layer that searches for an abstract error trace given by a succession of cells; and a lower layer where an abstract error trace is concretized to an actual error trace by picking points from cells. The approach can discover falsifying traces by backwards search from a goal region, but needs to concatenate partial traces with potential gaps, which can fail. Furthermore it is unclear how to extend it to general STL specifications. A survey of simulation based approaches has been done by Kapinski et al. [19].
Monotonicity has been exploited in different ways for falsification. Robust Neighborhood Descent [2, 3] (RED) searches for trajectories incrementally, restarting the search from points of low robustness. Descent computation of RED assumes explicit derivatives of the dynamics to guarantee convergence to (local) minima. It is the same principle underlying Prop. 5.4) and our experiments indicate that this principle is useful for black-box optimization, too. In [3], RED is paired with simulated annealing to combine local and global search and to account for more exploration. Doing so for our present work remains to be done in the future. In [17], Hoxha et al. mine parameters under which specifications are satisfied or falsified by the system. They show that the robust semantics of formulas is monotone in and use that fact to tighten such parameters. This is orthogonal to this work as it does not use monotonicity of the system itself. Kim et al. [20] use an idea similar to [17] to partition specifications into upper bounds and lower ceilings. However, instead of robustness-guided optimization they use exhaustive exploration of the input space in a way that in turn requires that the system dynamics is monotone in the choice of each input at each time point. This is different from our Def 5.1 of time-monotonicity that aims at incrementally composing good partial choices.
The recent work [13] introduces a compositional falsification framework, focusing on those systems which include machine-learning (ML) components that perform tasks such as image recognition. While the current work aims at the orthogonal direction of finding rare counterexamples, we are interested in its combination with the results in [13], given the increasingly important roles of ML algorithms in CPS.
8 Conclusions and Future Work
We have introduced and evaluated the idea of time staging to enhance falsification for hybrid systems. The proposed method emphasizes exploitation over exploration as part of stochastic optimization. As there is no single algorithm that fits every problem (as a consequence of having no free lunch [24]), having a variety of methods at disposal permits the user of a system to choose the one suitable for the problem at hand. We have shown that the proposed approach is a good fit for problems that suitable exhibit time-causal structures, where it significantly outperforms non-staged algorithms.
Two obvious directions for future work have been pointed out already. Instead of just picking the best trajectory for each stage, it might be beneficial to retain a few, potentially diverse ones in the spirit of evolutionary algorithms (§2). For example, it would be interesting to explore the space between this work on one hand and coverage-driven rapidly-exploring random trees.
Another idea is to discover time stages adaptively (§5, the discussion after Prop. 5.4). For the experiments presented here, we chose to set uniformly fixed stages, which runs the risk of either being too coarse grained (missing some falsifying input), or being too fine grained (wasting analysis time).
Finally, another future direction is to explore variations of robust semantics to mitigate discrete propositions like (§6), for example using averaging modalities [5]. Other t-norms than min/max for the semantics of conjunction/disjunction could preserve more information from different subformulas.
Acknowledgement.
This work is supported by ERATO HASUO Metamathematics for Systems Design Project (No. JPMJER1603), Japan Science and Technology Agency.
Appendix A STL Semantics for Time-Bounded Signals
Definition A.1** (robust semantics for time-bounded signals).**
Let , be a time-bounded signal, and be an STL formula. We define the robustness of with respect to as follows, by induction. Here the superscript is an annotation that designates the time horizon.
[TABLE]
The Boolean semantics , found e.g. in [11], allows a similar adaptation to time-bounded signals, too.
Appendix B Brzozowski Derivative of Flat STL Formulas
In the time-staged falsification procedure we often encounter the following situation: an STL formula and a signal are fixed; and we have to compute robustness for a number of different signals . To aid such computation, a natural idea is to use a syntactic construct of (Brzozowski) derivative. It should be compatible with robust semantics in the sense that , reducing the computation of the LHS to that of the RHS.
Similar use of derivatives is found e.g. in [23]. The settings are different, though: Boolean semantics is used in [23] while we use quantitative robust semantics. In fact, the definition of derivatives in this section focuses on flat formulas (i.e. free from nested modalities). This restriction is mandated by the quantitative semantics, as our proof later suggests. Anyway, the definitions and results in this section are new to the best of our knowledge.
We need the following extension of STL syntax.
Definition B.1** (extended STL).**
We extend the syntax of STL (Def. 3.4) by atomic propositions for each . The robust semantics in Def. 3.5 (and that in Def. A.1 in Appendix A) is extended accordingly: .
Intuitively is an atomic proposition that constantly returns the robustness value .
Definition B.2** (derivative).**
Let , and be a time-bounded signal. For each extended STL formula , we define its derivative by by the following induction.
[TABLE]
Here the interval is obtained from by shifting both of its endpoints earlier by , such as .
Definition B.3** (flat STL formula).**
An STL formula is flat if it does not have nested temporal modal operators. This means: if is a subformula of , then neither nor contains .
Proposition B.4**.**
Let , be a signal, and be a flat STL formula. We have, for each and , .
Proof.
By induction on the construction of . Most equalities below follow from the definition of and that of .
[TABLE]
Here is a nontrivial case.
[TABLE]
In we used the following facts. Firstly, for a formula without temporal operators, we have . Secondly, if ’s domain is and , then .
∎
Note that the flatness assumption on is crucially used in the proof step. Modifying Def. 4.2 in order to accommodate nested modalities seems hard, after analyzing the proof step .
Appendix C Omitted Proofs
C.1 Proof of Prop. 5.4
Proof.
By the definitions we have, for each input signal ,
[TABLE]
Therefore the assumption expands to
[TABLE]
The first infimum in the above is taken over a compact domain ; therefore there exists that achieves the infimum. Let be such a real number. The following is obvious.
[TABLE]
Another immediate consequence, derived using the causality of (Def. 3.2), is
[TABLE]
Our goal is to show .
[TABLE]
In the above we heavily used the causality of (Def. 3.2). For example, in the step above, causality is used in deriving . In the step we applied the monotonicity of to the signals , and . Note that (6) allows to do so.
∎
The reference list from the paper itself. Each links out to its DOI / PubMed record.
- 1[1]
- 2[2] Houssam Abbas, Andrew K. Winn, Georgios E. Fainekos & A. Agung Julius (2014): Functional gradient descent method for Metric Temporal Logic specifications . In: American Control Conference, ACC 2014, Portland, OR, USA, June 4-6, 2014 , IEEE, pp. 2312–2317, 10.1109/ACC.2014.6859453 . · doi ↗
- 3[3] Houssam Y Abbas (2015): Test-based falsification and conformance testing for cyber-physical systems . Ph.D. thesis, Arizona State University.
- 4[4] Arvind S. Adimoolam, Thao Dang, Alexandre Donzé, James Kapinski & Xiaoqing Jin (2017): Classification and Coverage-Based Falsification for Embedded Control Systems . In Rupak Majumdar & Viktor Kuncak, editors: Computer Aided Verification - 29th Int. Conf., CAV 2017 , LNCS 10426, Springer, pp. 483–503, 10.1007/978-3-319-63387-9_24 . · doi ↗
- 5[5] Takumi Akazaki & Ichiro Hasuo (2015): Time Robustness in MTL and Expressivity in Hybrid System Falsification . In Daniel Kroening & Corina S. Pasareanu, editors: Computer Aided Verification - 27th Int. Conf., CAV 2015 , LNCS 9207, Springer, pp. 356–374, 10.1007/978-3-319-21668-3_21 . · doi ↗
- 6[6] Yashwanth Annpureddy, Che Liu, Georgios E. Fainekos & Sriram Sankaranarayanan (2011): S-Ta Li Ro: A Tool for Temporal Logic Falsification for Hybrid Systems . In Parosh Aziz Abdulla & K. Rustan M. Leino, editors: Tools and Algorithms for the Construction and Analysis of Systems - 17th Int. Conf., TACAS 2011 , LNCS 6605, Springer, pp. 254–257, 10.1007/978-3-642-19835-9_21 . · doi ↗
- 7[7] Anne Auger & Nikolaus Hansen (2005): A restart CMA evolution strategy with increasing population size . In: Proceedings of the IEEE Congress on Evolutionary Computation, CEC 2005 , IEEE, pp. 1769–1776, 10.1109/CEC.2005.1554902 . · doi ↗
- 8[8] Jyotirmoy V. Deshmukh, Xiaoqing Jin, James Kapinski & Oded Maler (2015): Stochastic Local Search for Falsification of Hybrid Systems . In Bernd Finkbeiner, Geguang Pu & Lijun Zhang, editors: Automated Technology for Verification and Analysis - 13th Int. Symp., ATVA 2015 , LNCS 9364, Springer, pp. 500–517, 10.1007/978-3-319-24953-7_35 . · doi ↗