TL;DR
This paper evaluates how different community detection algorithms overfit or underfit on diverse real-world networks, revealing significant variability and proposing a new diagnostic for assessment.
Contribution
It provides a comprehensive comparison of 16 algorithms on 406 networks, introduces a diagnostic for over/underfitting, and identifies Bayesian methods as generally effective.
Findings
Algorithms vary widely in community count and composition.
Distinct groups of algorithms exhibit similar output patterns.
Bayesian methods generally outperform others in accuracy.
Abstract
A common data mining task on networks is community detection, which seeks an unsupervised decomposition of a network into structural groups based on statistical regularities in the network's connectivity. Although many methods exist, the No Free Lunch theorem for community detection implies that each makes some kind of tradeoff, and no algorithm can be optimal on all inputs. Thus, different algorithms will over or underfit on different inputs, finding more, fewer, or just different communities than is optimal, and evaluation methods that use a metadata partition as a ground truth will produce misleading conclusions about general accuracy. Here, we present a broad evaluation of over and underfitting in community detection, comparing the behavior of 16 state-of-the-art community detection algorithms on a novel and structurally diverse corpus of 406 real-world networks. We find that (i)…
Click any figure to enlarge with its caption.
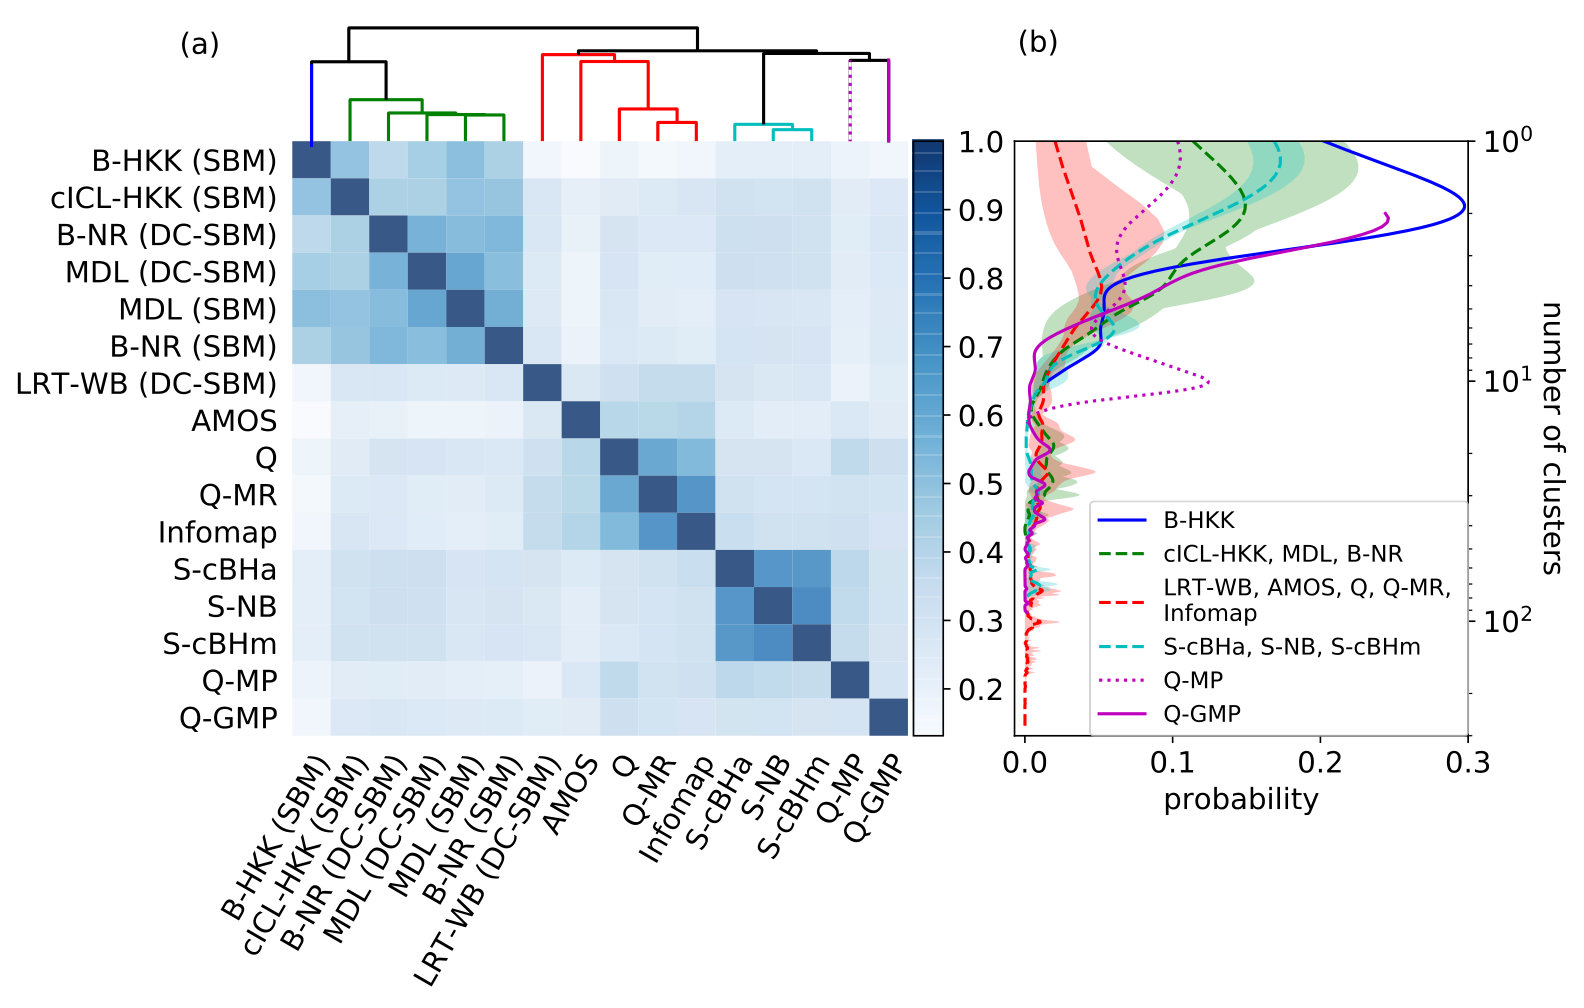 Figure 1
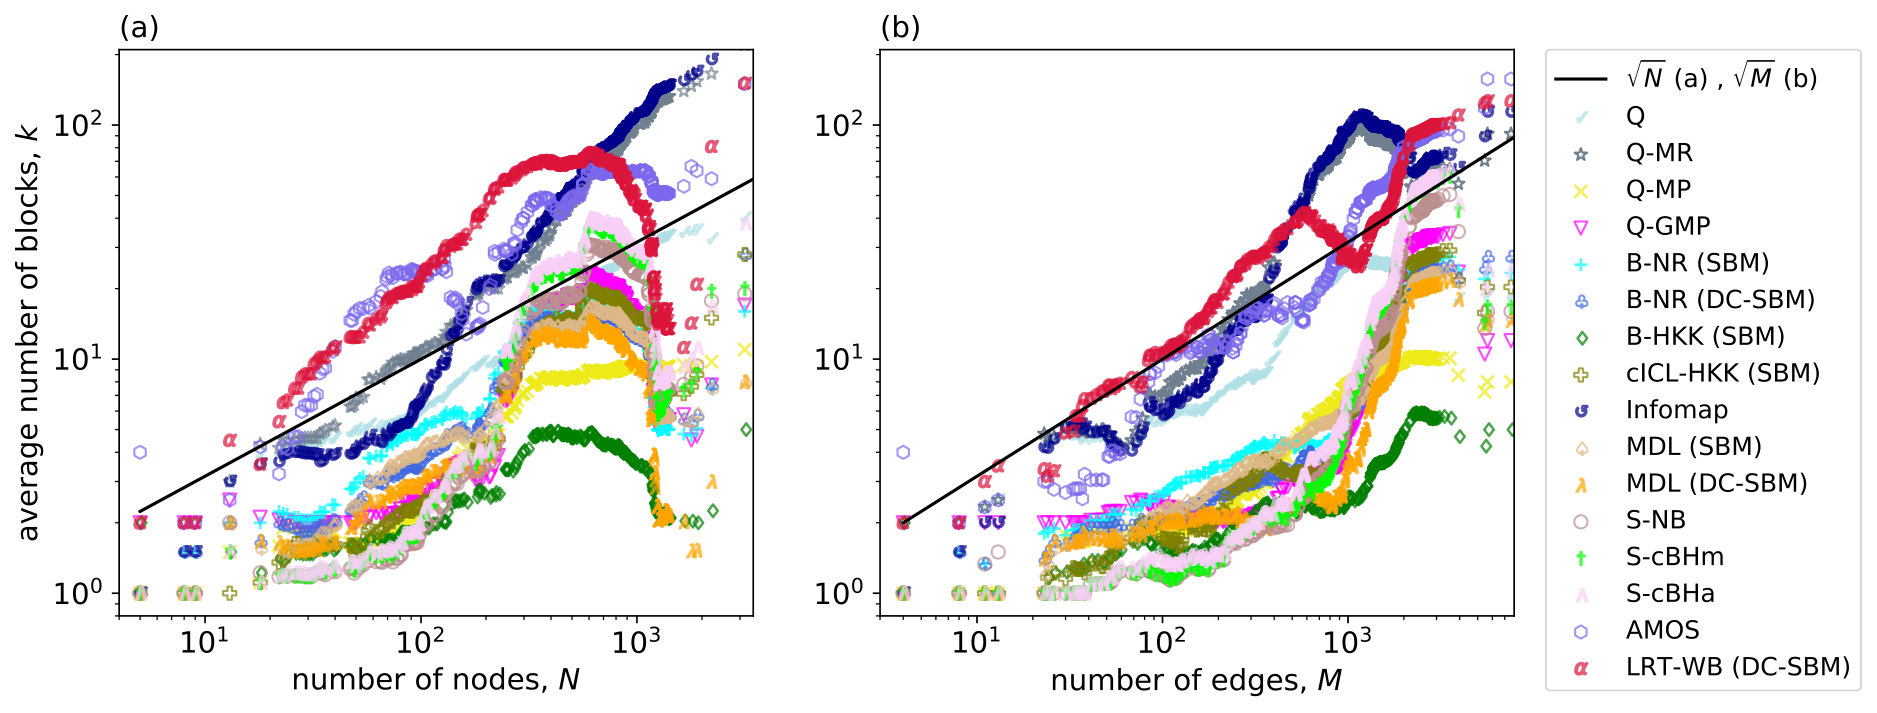 Figure 2
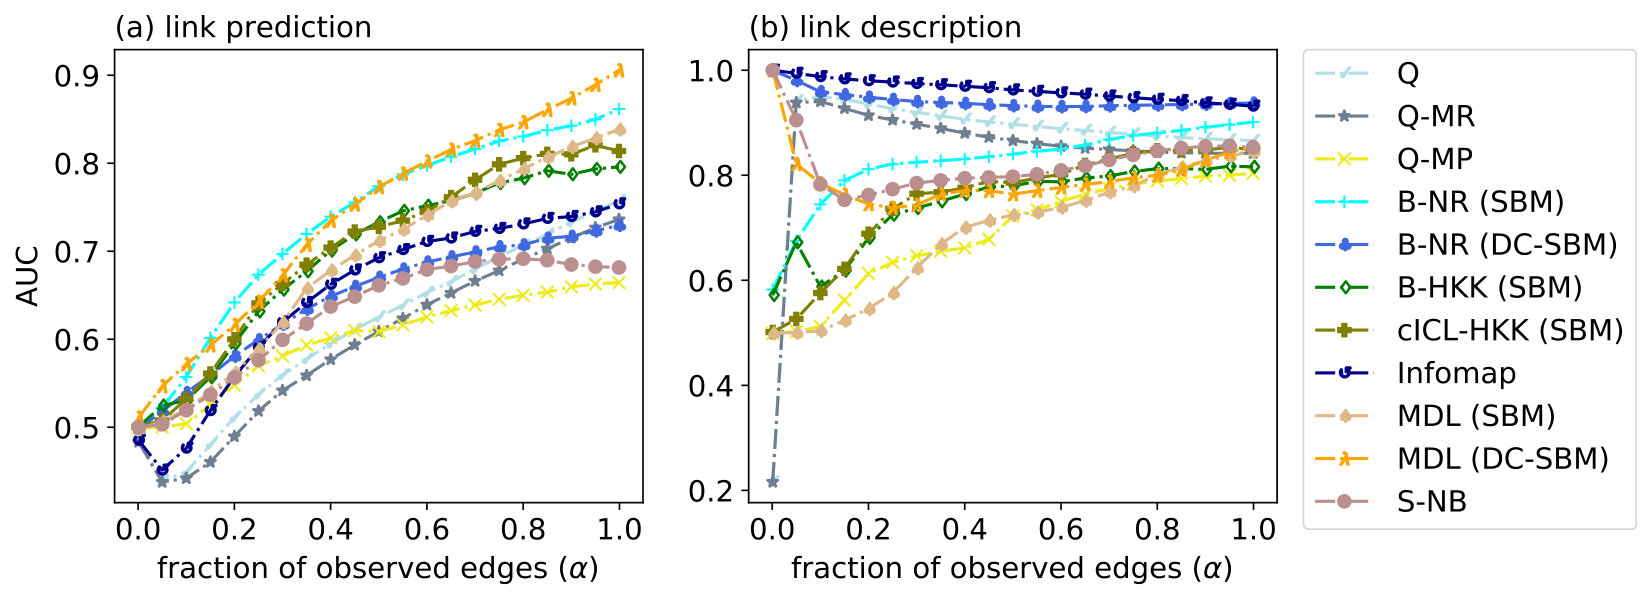 Figure 3
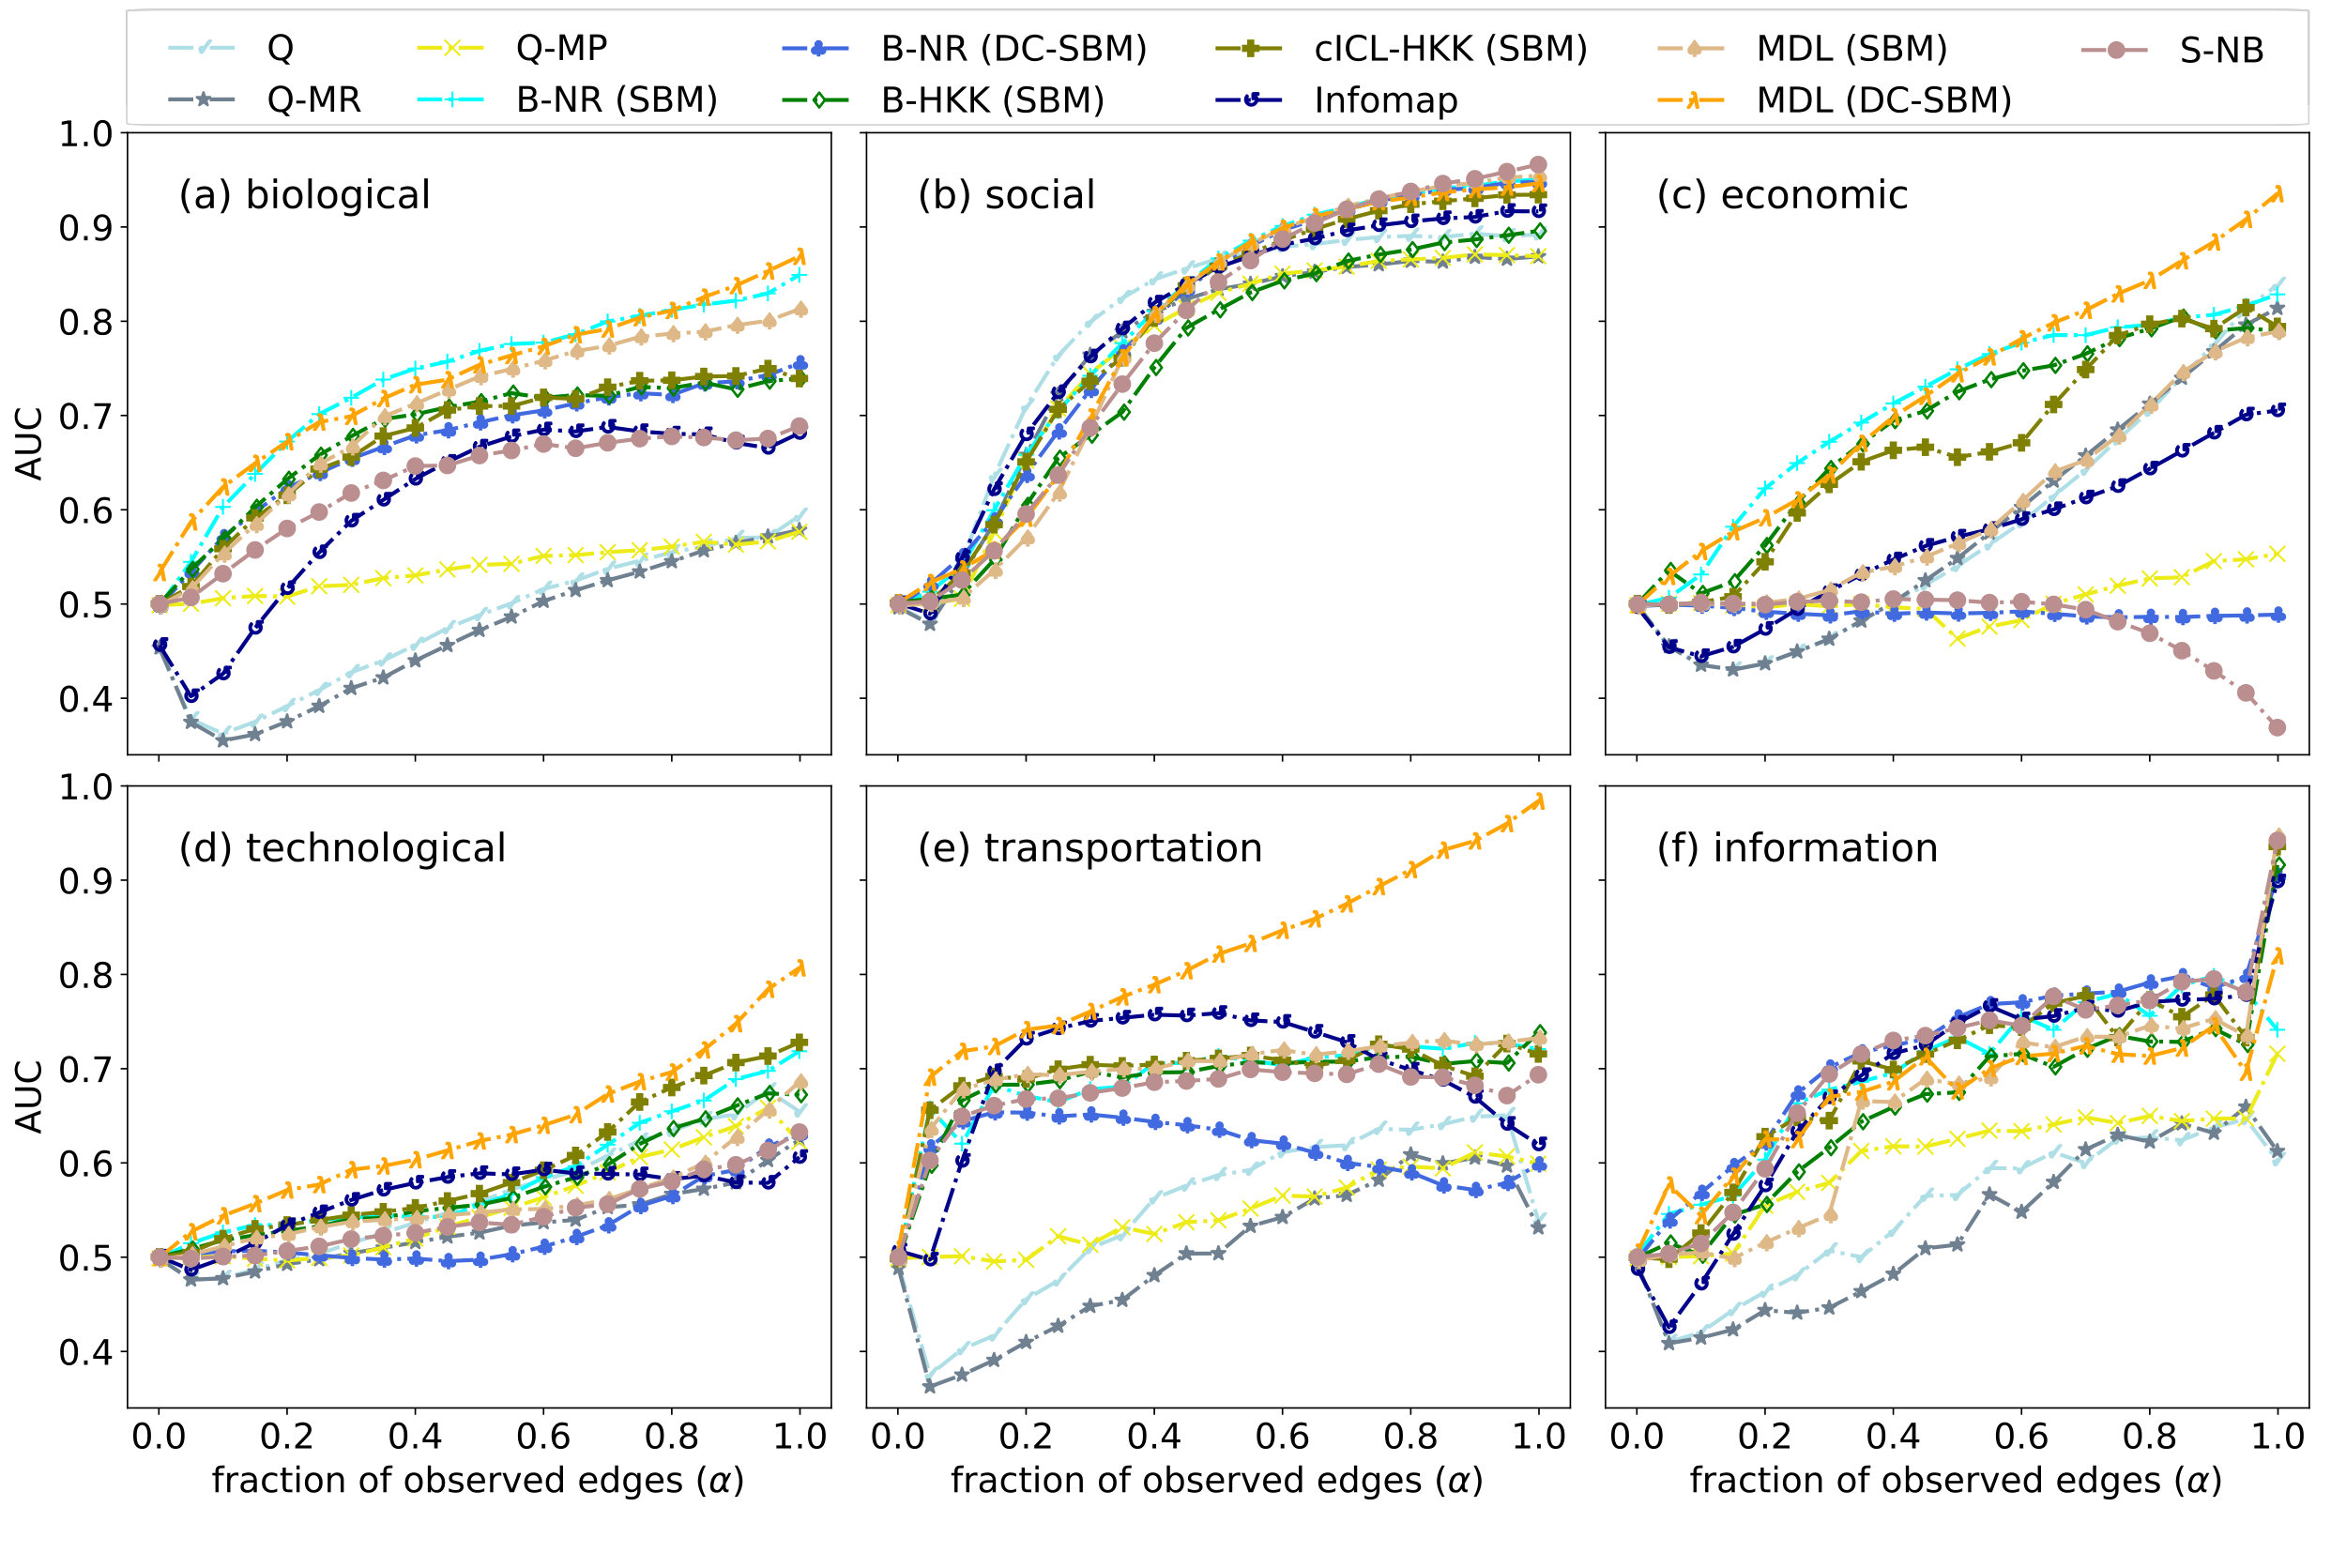 Figure 4
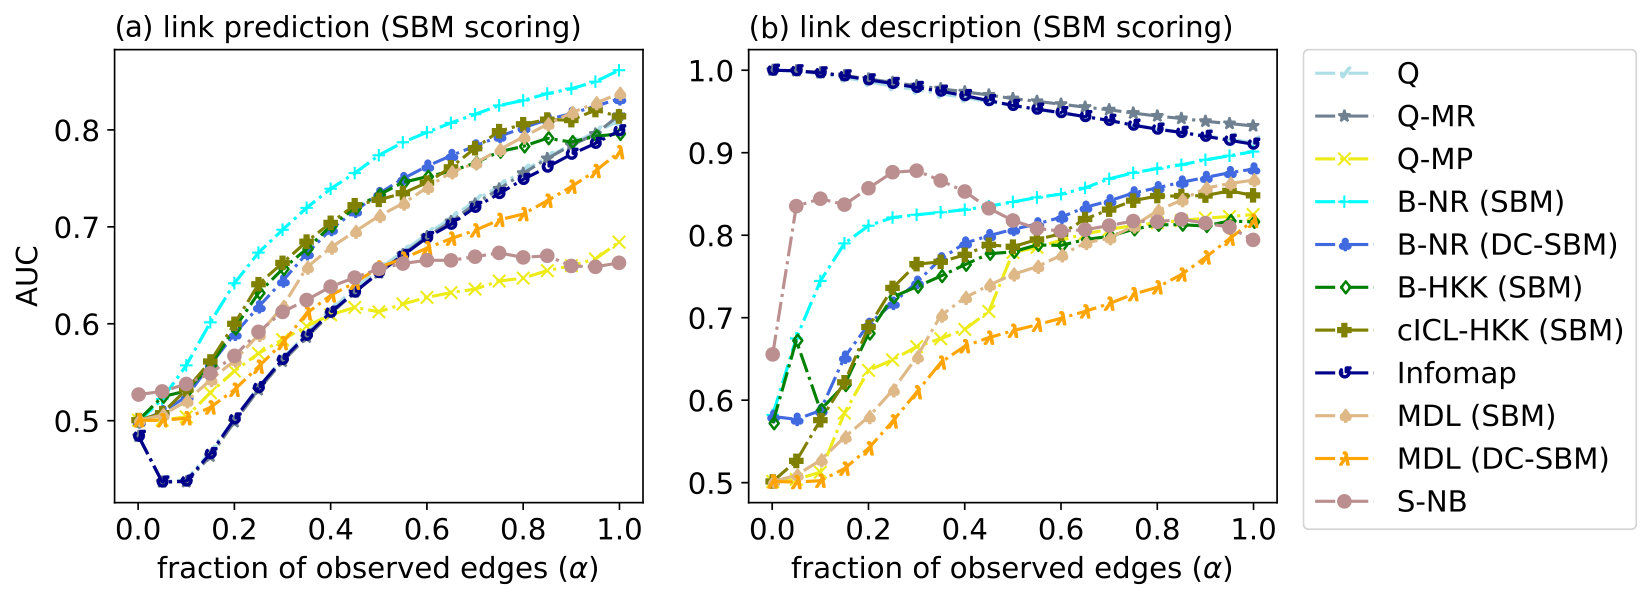 Figure 5
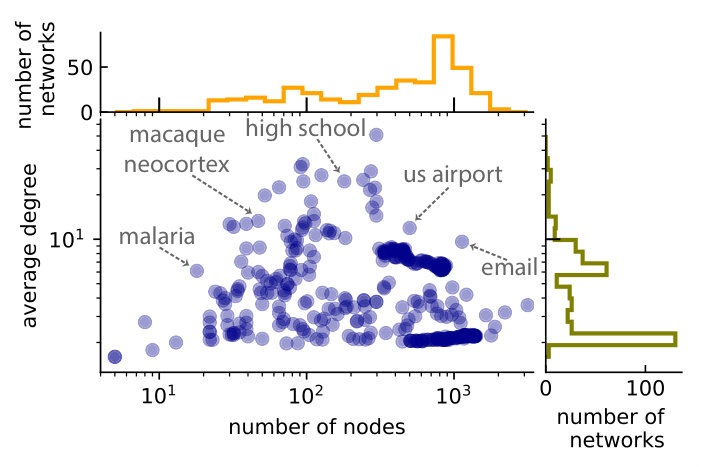 Figure 6
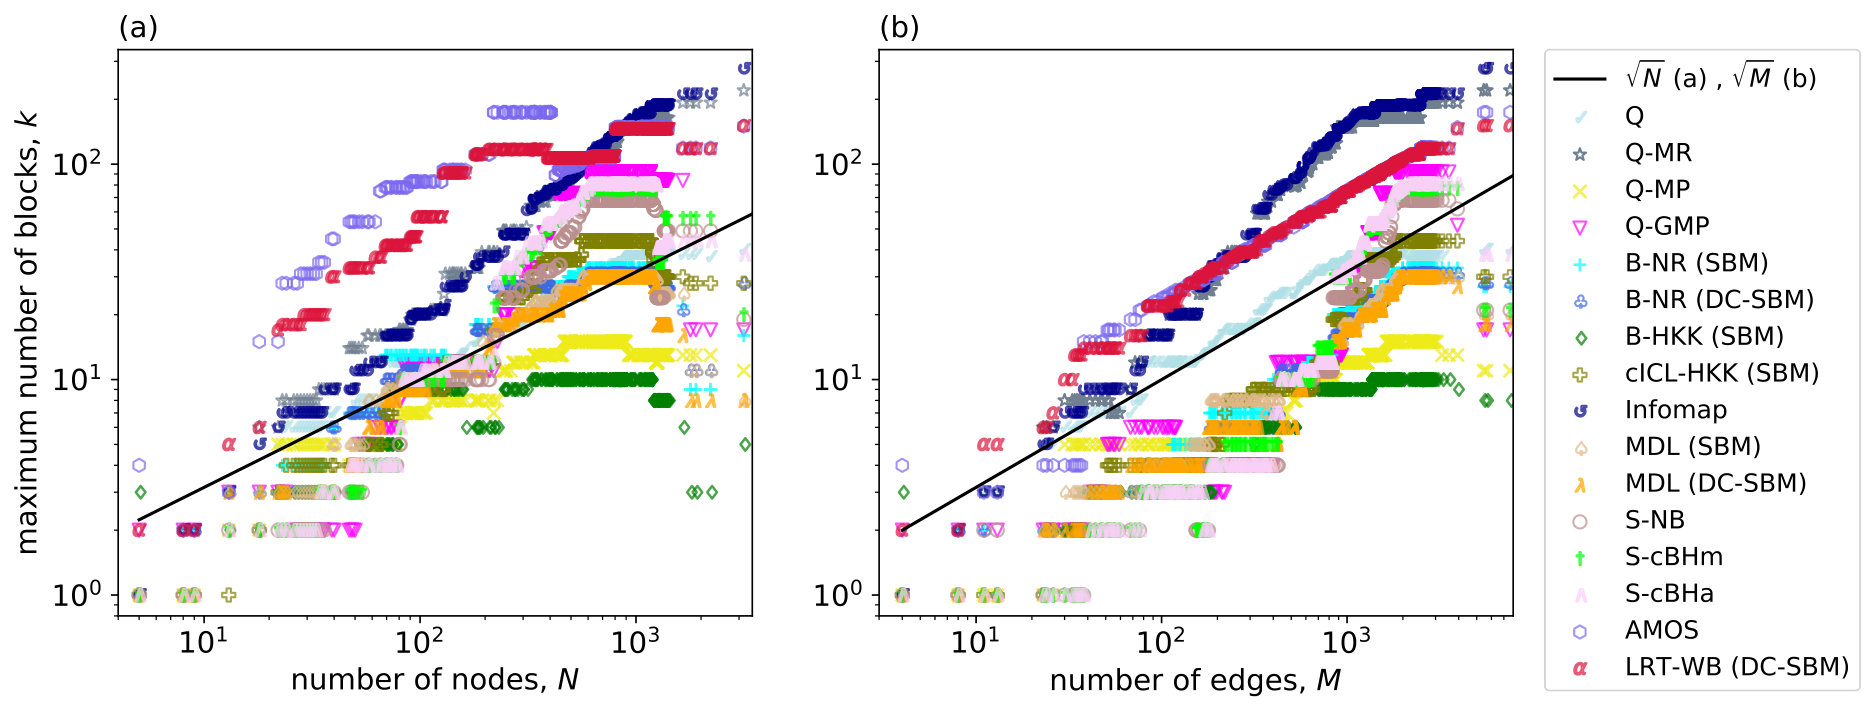 Figure 7
 Figure 8
| Abbreviation | Ref. | Description |
|---|---|---|
| Q | [5] | Modularity, Newman-Girvan |
| Q-MR | [30] | Modularity, Newman’s multiresolution |
| Q-MP | [24] | Modularity, message passing |
| Q-GMP | [17] | Modularity, generalized message passing with CV-LOO as model selection |
| B-NR (SBM) | [29] | Bayesian, Newman and Reinert |
| B-NR (DC-SBM) | [29] | Bayesian, Newman and Reinert |
| B-HKK (SBM) | [31] | Bayesian, Hayashi, Konishi and Kawamoto |
| cICL-HKK (SBM) | [31] | Corrected integrated classification likelihood |
| Infomap | [12] | Map equation |
| MDL (SBM) | [20] | Minimum description length |
| MDL (DC-SBM) | [20] | Minimum description length |
| S-NB | [9] | Spectral with non-backtracking matrix |
| S-cBHm | [11] | Spectral with Bethe Hessian, version m |
| S-cBHa | [11] | Spectral with Bethe Hessian, version a |
| AMOS | [32] | Statistical test using spectral clustering |
| LRT-WB (DC-SBM) | [13] | Likelihood ratio test |
| Number of | Partition | Link Prediction | Link Description | ||
| Algorithm | Communities, | Type | Benchmark | Benchmark | Overall Fit |
| Q | larger | non-probabilistic | poor | good | over fits |
| Q-MR | larger | non-probabilistic | poor | good | over fits |
| Q-MP | smaller | \pbox2.5cmspectral/ | |||
| non-probabilistic | poor | poor | under fits | ||
| Q-GMP | smaller | \pbox2.5cmspectral/ | |||
| non-probabilistic | —– | —– | inconclusive | ||
| B-NR (SBM) | smaller | probabilistic | very good | moderate | well-fitted |
| B-NR (DC-SBM) | smaller | probabilistic | moderate | very good | over fits, modestly |
| B-HKK (SBM) | smaller | probabilistic | good | moderate | under fits, modestly |
| cICL-HKK (SBM) | smaller | probabilistic | good | moderate | under fits, modestly |
| Infomap | larger | non-probabilistic | moderate | moderate | over fits |
| MDL (SBM) | smaller | probabilistic | good | poor | under fits |
| MDL (DC-SBM) | smaller | probabilistic | very good | moderate | well-fitted |
| S-NB | smaller | spectral | moderate | moderate | uneven fits |
| S-cBHm | smaller | spectral | —– | —– | inconclusive |
| S-cBHa | smaller | spectral | —– | —– | inconclusive |
| AMOS | larger | non-probabilistic | —– | —– | inconclusive |
| LRT-WB (DC-SBM) | larger | non-probabilistic | —– | —– | inconclusive |
| Social | Economic | Biological | Technological | Information | Transportation | Total |
|---|---|---|---|---|---|---|
| 123/1 | 11/111 | 147/45 | 71/0 | 22/0 | 41/0 | 415/157 |
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Code & Models
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
\pdfcolInitStack
tcb@breakable
Evaluating Overfit and Underfit in Models of Network Community Structure
Amir Ghasemian, Homa Hosseinmardi and Aaron Clauset A. Ghasemian is with the Department of Statistics, Harvard University, Cambridge, MA, 02138.
E-mail: [email protected]H. Hosseinmardi is with the Information Sciences Institute, University of Southern California, Marina del Rey, CA, 90292.
Email: [email protected]A. Clauset is an Associate Professor of Computer Science, University of Colorado, Boulder, CO, 80309, and in the BioFrontiers Institute, University of Colorado, Boulder, CO, 80305. Also he is an external Faculty at the Santa Fe Institute, 1399 Hyde Park Road, Santa Fe, NM, 87501.
Email: [email protected]
Abstract
A common graph mining task is community detection, which seeks an unsupervised decomposition of a network into groups based on statistical regularities in network connectivity. Although many such algorithms exist, community detection’s No Free Lunch theorem implies that no algorithm can be optimal across all inputs. However, little is known in practice about how different algorithms over or underfit to real networks, or how to reliably assess such behavior across algorithms. Here, we present a broad investigation of over and underfitting across 16 state-of-the-art community detection algorithms applied to a novel benchmark corpus of 572 structurally diverse real-world networks. We find that (i) algorithms vary widely in the number and composition of communities they find, given the same input; (ii) algorithms can be clustered into distinct high-level groups based on similarities of their outputs on real-world networks; (iii) algorithmic differences induce wide variation in accuracy on link-based learning tasks; and, (iv) no algorithm is always the best at such tasks across all inputs. Finally, we quantify each algorithm’s overall tendency to over or underfit to network data using a theoretically principled diagnostic, and discuss the implications for future advances in community detection.
Index Terms:
Community Detection, Model Selection, Overfitting, Underfitting, Link Prediction, Link Description.
1 Introduction
Networks are an increasingly important and common kind of data, arising in social, technological, communication, and biological settings. One of the most common data mining tasks in network analysis and modeling is to coarse-grain the network, which is typically called community detection. This task is similar to clustering, in that we seek a lower-dimensional description of a network by identifying statistical regularities or patterns in connections among groups of nodes. Fundamentally, community detection searches for a partition of the nodes that optimizes an objective function of the induced clustering of the network.
Due to broad interest across disciplines in clustering networks, many approaches for community detection now exist [1, 2, 3], and these can be broadly categorized into either probabilistic methods or non-probabilistic methods. Graphical models, like the popular stochastic block model (SBM) [4], typically fall in the former category, while popular methods like modularity maximization [5] fall in the latter. Across these general categories, methods can also be divided into roughly six groups: Bayesian and regularized likelihood approaches [6, 7, 8], spectral and embedding techniques [9, 10, 11], modularity methods [5], information theoretic approaches such as Infomap [12], statistical hypothesis tests [13], and cross-validation methods [14, 15].
Despite great interest, however, there have been relatively few broad comparative studies or systematic evaluations of different methods in practical settings [16, 11, 17] and little is known about the degree to which different methods perform well on different classes of networks in practice. As a result, it is unclear which community detection algorithm should be applied to which kind of data or for which kind of downstream task, or how to decide which results are more or less useful when different algorithms produce different results on the same input [18].
This situation is worsened by two recently proved theorems for community detection [19]. The No Free Lunch (NFL) theorem for community detection implies that no method can be optimal on all inputs, and hence every method must make a tradeoff between better performance on some kinds of inputs for worse performance on others. For example, an algorithm must choose a number of communities to describe a given network, and the way it makes this decision embodies an implicit tradeoff that could lead to overfitting (finding too many clusters) on some networks and underfitting (finding too few or the wrong clusters) on others.
The “no ground truth” theorem states that there is no bijection between network structure and “ground truth” communities, which implies that no algorithm can always recover the correct ground truth on every network [19], even probabilistically. Together, these theorems have broad implications for measuring the efficacy of community detection algorithms. In the most popular evaluation scheme, a partition defined by node metadata or node labels is treated as if it were “ground truth”, e.g., ethnicity in a high-school social network or cellular function in a protein interaction network, and accuracy on its recovery is compared across algorithms. However, the NFL and “no ground truth” theorems imply that such comparisons are misleading at best, as performance differences are confounded by implicit algorithmic tradeoffs across inputs [19]. Hence, relatively little is known about how over- and under-fitting behavior varies by algorithm and input, past evaluations offer little general guidance, and a new approach to evaluating and comparing community detection algorithms is needed.
Here, we present a broad and comprehensive comparison of the performance of 16 state-of-the-art community detection methods and we evaluate the degree to and circumstances under which they under- or over-fit to network data. We evaluate these methods using a novel corpus of 572 real-world networks from many scientific domains, which constitutes a realistic and structurally diverse benchmark for evaluating and comparing the practical performance of algorithms. We characterize each algorithm’s performance (i) relative to general theoretical constraints, (ii) on the practical task of link prediction (a kind of cross-validation for network data), and (iii) on a new task we call link description. The tradeoff between these two tasks is analogous to the classic bias-variance tradeoff in statistics and machine learning, adapted to a network setting in which pairwise interactions violate independence assumptions.
In both link description and link prediction, some fraction of a network’s observed edges are removed before communities are detected, much like dividing a data set into training and test sets for cross validation. We then score how well the identified communities (and any corresponding model parameters the method returns) predict the existence of either the remaining observed edges (link description) or the removed edges (link prediction). By design, no algorithm can be perfectly accurate at both tasks, and the relative performance becomes diagnostic of a method’s tendency to overfit or underfit to data. Hence, as in a non-relational learning setting, a method can be said to overfit to the data if its accuracy is high on the training data but low for the test data, and it can be said to underfit if its accuracy is low on both training and test data.
Our results show that (i) algorithms vary widely both in the number of communities they find and in their corresponding composition, given the same input, (ii) algorithms can be clustered into distinct high-level groups based on similarities of their outputs on real-world networks, (iii) algorithmic differences induce wide variation in accuracy on link-based learning tasks, and (iv) no algorithm is always the best at such tasks across all inputs. Finally, we introduce and apply a diagnostic that uses the performance on link prediction and link description to evaluate a method’s general tendency to under- or over-fitting in practice.
Our results demonstrate that many methods make uncontrolled tradeoffs that lead to overfitting on real data. Across methods, Bayesian and regularized likelihood methods based on SBM tend to perform best, and a minimum description length (MDL) approach to regularization [20] provides the best general learning algorithm. On some real-world networks and in specific settings, other approaches perform better, which illustrates the NFL’s relevance for community detection in practice. That is, although the SBM with MDL regularization may be a good general algorithm for community detection, specialized algorithms can perform better when applied to their preferred inputs.
2 Methods and Materials
Despite well-regarded survey articles [1, 2, 3] there are relatively few comparative studies for model selection techniques in community detection [21, 22, 16, 11, 17, 23] and most of these consider only a small number of methods using synthetic data (also called “planted partitions”) or select only a small number of real-world networks, e.g., the Zachary karate club network, a network of political blogs, a dolphin social network, or the NCAA 2000 schedule network. The narrow scope of such comparative studies has been due in part to the non-trivial nature both of implementing or obtaining working code for competing methods, and of applying them to a large and representative sample of real-world network data sets.
For example, Ref. [11] compared several spectral approaches using planted partition networks and five small well-studied real-world networks. In contrast, Ref. [17] carried out a broader comparative analysis of the number of clusters found by six different algorithms. The authors also introduce a generalized message passing approach for modularity maximization [24] in which they either use modularity values directly or use leave-one-out cross-validation [15] to infer the number of clusters. These methods were only evaluated on planted partition models and a small number of real-world networks. Ref. [23] proposed a multi-fold cross-validation technique similar to Refs. [14, 22] and compared results with other cross-validation techniques using synthetic data. Recently, Ref. [25] showed that model selection techniques based on cross-validation are not always consistent with the most parsimonious model and in some cases can lead to overfitting. None of these studies compares methods on a realistically diverse set of networks, or provides general guidance on evaluating over- and under-fitting outcomes in community detection.
In general, community detection algorithms can be categorized into two general settings. The first group encompasses probabilistic models, which use the principled method of statistical inference to find communities. Many of these are variants on the popular stochastic block model (SBM). Under this probabilistic generative model for a graph with the size , a latent variable denoting the node’s community label , with prior distribution (), is assigned to each node . Each pair of nodes is connected independently with probability . In the sparse case, where , the resulting network is locally tree-like and the number of edges between groups is Poisson distributed. However, a Poisson degree distribution does not match the heavy-tailed pattern observed in most real-world networks, and hence the standard SBM tends to find partitions that correlate with node degrees. The degree-corrected stochastic block model (DC-SBM) [26] corrects this behavior by introducing a parameter for each node and an identifiability constraint on . In this model, each edge exists independently with probability . The aforementioned planted partition model for synthetic networks can simply be a special case of the SBM with communities, when if and if [27].
This first group of methods includes a variety of regularization approaches for choosing the number of communities, e.g., those based on penalized likelihood scores [8, 28], various Bayesian techniques including marginalization [29, 7], cross-validation methods with probabilistic models [15, 17], compression approaches like MDL [20], and explicit model comparison such as likelihood ratio tests (LRT) [13].
The second group of algorithms encompasses non-probabilistic score functions. This group is more varied, and contains methods such as modularity maximization and its variants [5, 24], which maximizes the difference between the observed number of edges within groups and the number expected under a random graph with the same degree sequence; the map equation (Infomap) [12], which uses a two-level compression of the trajectories of random walkers to identify groups; and, various spectral techniques [9, 11], which seek a low-rank approximation of a noisy but roughly block-structured adjacency matrix, among others.
Methods in both groups can differ by whether the number of communities is chosen explicitly, as a parameter, or implicitly, either by an assumption embedded within the algorithm or by a method of model complexity control. In fact, the distinction between explicit and implicit choices can be subtle as evidenced by a recently discovered equivalence between one form of modularity maximization (traditionally viewed as choosing implicitly) and one type of SBM (which typically makes an explicit choice) [30]. For the interested reader, a brief survey of model selection techniques for community detection is presented in Appendix E.
In this study, a central aim is to develop and apply a principled statistical method to evaluate and compare the degree to which different community detection algorithms under- or over-fit to data. Toward this end, we compare the results of a large number of algorithms in order to illustrate the different kinds of behaviors that emerge, and to ensure that our results have good generality. For this evaluation, we selected a set of 16 representative and state-of-the-art approaches that spans both general groups of algorithms (see Table LABEL:table:abbr). This set of algorithms is substantially larger and more methodologically diverse than any previous comparative study of community detection methods and covers a broad variety of approaches. To be included, an algorithm must have had reasonably good computational complexity, generally good performance, and an available software implementation. Because no complete list of community detection algorithms and available implementations exists, candidate algorithms were identified manually from the literature, with an emphasis on methodological diversity in addition to the above criteria.
From information theoretic approaches we selected MDL [20] and Infomap [12]. From the regularized likelihood approaches, we selected the corrected integrated classification likelihood (cICL-HKK) [31]. From among the Bayesian methods Newman and Reinert’s Bayesian (B-NR) [29] and Hayashi, Konishi and Kawamoto’s Bayesian (B-HKK) [31] are selected. From among the modularity based approaches, we selected Newman’s multiresolution modularity (Q-MR) [30], the classic Newman-Girvan modularity (Q) [5] (both fitted using the Louvain method [33]), the Zhang-Moore message passing modularity (Q-MP) [24], and the Kawamoto-Kabashima generalized message passing modularity algorithm (Q-GMP) [17]. (We consider a cross-validation technique called leave-one-out (CV-LOO) [15] to be the model selection criterion of Q-GMP.) From the spectral methods, we selected the non-backtracking (S-NB) [9] and Bethe Hessian [10, 11] approaches. For the latter method, we include two versions, S-cBHa and S-cBHm [11], which are corrected versions of the method proposed in Ref. [10]. From among the more traditional statistical methods, we selected AMOS [32] and a likelihood ratio test (LRT-WB) [13].
Examples of algorithms that were not selected under the criteria listed above include the infinite relational model (IRM) [34], a nonparametric Bayesian extension of SBM, along with a variant designed to specifically detect assortative communities [35], the order statistics local optimization method (OSLOM) [36], which finds clusters via a local optimization of a significance score, and a method based on semidefinite programming [37]. Two related classes of algorithms that we do not consider are those that return either hierarchical [38, 39, 40, 41] or mixed-membership communities [42]. Instead, we focus on traditional community detection algorithms, which take a simple graph as input and return a “hard” partitioning of the vertices. As a result, hierarchical decompositions or mixed membership outputs are not directly comparable, without additional assumptions.
As a technical comment, we note that the particular outputs of some algorithms depend on the choice of a prior distribution, as in the Bayesian approaches, or on some details of the implementation. For example, the MDL and Bayesian integrated likelihood methods are mathematically equivalent for the same prior [3], but can produce different outputs with different priors and implementations (see below). However, the qualitative results of our evaluations are not affected by these differences. Finally, we note that the link prediction task is carried out using the learned models themselves, rather than using sampling methods, which improves comparability despite such differences.
To evaluate and compare the behavior of these community detection algorithms in a practical setting, we introduce and exploit the “CommunityFitNet corpus,” a novel data set111Available at https://github.com/AGhasemian/CommunityFitNet containing 572 real-world networks drawn from the Index of Complex Networks (ICON) [43]. The CommunityFitNet corpus spans a variety of network sizes and structures, with 22% social, 21% economic, 34% biological, 12% technological, 4% information, and 7% transportation graphs (Fig. 1). Within it, the mean degree of a network is roughly independent of network size, making this a corpus of sparse graphs. In our analysis, we treat each graph as being simple, meaning we ignore the edge weights and directions. If a graph is not connected, we consider only its largest component.
3 Number of Communities in Theory and Practice
3.1 In Theory
A key factor in whether some community detection method is over- or under-fitting to a network is its selection of the number of clusters or communities for the network. In the community detection literature, most of the consistency theorems, which provide guarantees on the fraction of mislabeled nodes, apply to dense networks only. For example, Ref. [44], proposes that the fraction of misclassified nodes converges in probability to zero under maximum likelihood fitting, when the number of clusters grows no faster than and when the average degree grows at least poly-logarithmically in .
However, most real-world networks are sparse [45, 46], including all networks in the CommunityFitNet corpus (Fig. 1), meaning results for dense networks are inapplicable. For sparse networks, several lines of mathematical study argue that the maximum number of detectable clusters is , explicitly [20, 47, 48] or implicitly as an assumption in a consistency theorem [49, 50, 51].
For example, in the planted -partition, the expected number of recoverable clusters grows like [49, 50]. (For convex optimization on the planted -partition model, a tighter bound on the number of clusters has also been claimed [52], although this result is not rigorous.) This theoretical limit is remarkably similar to the well-known resolution limit in modularity [53], which shows that modularity maximization will fail to find communities with sizes smaller than . Hence, the expected number of modularity communities in a sparse graph is also . An argument from compression leads to a similar bound on [20, 47]. Specifically, the model complexity of a stochastic block model is , which under a minimum description length analysis predicts that . This statement can also be generalized to regularized likelihood and Bayesian methods. Although none of these analyses is fully rigorous, they do point to a similar theoretical prediction: the number of recoverable communities in a real sparse network should grow like . Different algorithms, of course, may have different constants of proportionality or different sub-asymptotic behaviors. In our evaluations, we use a constant of 1 as a common reference point.
As a technical comment, we note that the maximum number of clusters found is not the same as the number of identifiable clusters under the information-theoretic limit to detectability [54]. For example, as a result of a resolution limit, an algorithm might merge two clusters, but still infer the remaining clusters correctly. In other words, the network’s communities exist in the detectable regime but the output has lost some resolution.
3.2 In Practice
We applied our set of 16 community detection methods to the 572 real-world networks in the CommunityFitNet corpus. For methods with free parameters, values were set as suggested in their source papers. We then binned networks by their size or and for each method plotted the average (Fig. 2) and maximum number (Fig. 7; see Appendix) of inferred communities as a function of the number of nodes and edges .
In both figures, solid lines show the theoretically predicted trends of and . Two immediate conclusions are that (i) the actual behavior of different algorithms on the same input is highly variable, often growing non-monotonically with network size and with some methods finding 10 times as many communities as others, but (ii) overall, the number of communities found does seem to grow with the number of edges, and perhaps even roughly like the pattern predicted by different theoretical analyses (Section 3.1). Furthermore, the empirical trends are somewhat more clean when we consider the number of communities versus the number of edges (Fig. 2b and Fig. 7b; see Appendix), suggesting that the mean degree of a network impacts the behavior of most algorithms.
From this perspective, algorithms visually cluster into two groups, one of which finds roughly 2-3 times as many communities as the other. The former group contains the methods of Q, Q-MR, Infomap, LRT-WB and AMOS, all of which find substantially more clusters than methods in the latter group, which includes B-NR, B-HKK, cICL-HKK, MDL, spectral methods, Q-MP and Q-GMP. In fact, first group of methods often return many more clusters than we would expect theoretically, which suggests the possibility of consistent overfitting. As a small aside, we note that the expected number of communities found by Q-MR and Q are different, because they are known to have different resolution limits [55]. More generally, the aforementioned groups, and their tendency to find greater or fewer communities aligns with our dichotomy of non-probabilistic (more communities) versus probabilistic (fewer communities) approaches. Additionally, we note that the AMOS method failed to converge on just over half of the networks in the CommunityFitNet corpus, returning an arbitrary maximum value instead of . Because of this behavior, we excluded AMOS from all subsequent analysis.
In Ref. [17], the authors show empirically that Infomap and the Louvain method for modularity maximization tends to overfit the number of clusters planted in synthetic networks with weak community structure. The results shown here on our large corpus of real-world networks are consistent with these previous results, indicating that both modularity and Infomap tend to find substantially more communities compared to other methods. Figure 7 (see Appendix), shows more clearly that the maximum number of clusters detected by Q-MR and Infomap are nearly identical. Furthermore, these methods find the same average number of clusters over 572 networks (Fig. 2). This behavior has not previously been noted, and suggests that Q-MR and Infomap may have the same or very similar resolution limits.
In general, algorithms with similar formulations or that are based on similar approaches show similar behavior in how varies with . For instance, beyond Q-MR and Infomap’s similarity, we also find that MDL, various regularized likelihood methods, and the Bayesian approaches find similar numbers of communities. Spectral methods appear to behave similarly, on average (Fig. 2), to the Bayesian approaches. However, spectral approaches do seem to overfit for large network sizes, by finding a maximum number of communities that exceeds theoretical predictions, in contrast to the Bayesian approaches.
Looking more closely at similar methods, we observe small differences in the number of clusters they return as a function of network size , which must be related to differences in their implicit assumptions. For example B-HKK, B-NR and cICL-HKK often agree on the number of communities for networks with a smaller number of edges, but they disagree for networks with a larger number of edges (Fig. 2). Due to a more exact Laplace approximation with higher order terms, B-HKK penalizes the number of clusters more than B-NR and cICL-HKK, which limits the model space of B-HKK to smaller models that correspond to fewer communities. This tradeoff is a natural one, as approaches that penalize a model for greater complexity, like in B-HKK, are intended to reduce the likelihood of overfitting, which can in turn increase the likelihood of underfitting.
Returning to the Q-MR method, we inspect its results more carefully to gain some insight into whether it is overfitting or not. Ref. [30] proves that Q-MR is mathematically equivalent to a DC-SBM method on a -planted partition space of models. The Q-MR algorithm works implicitly like a likelihood-maximization algorithm, except that it chooses its resolution parameter, which sets , by iterating between the Q and DC-SBM formulations of the model. Evidently, this approach does not limit model complexity as much as a regularized likelihood and tends to settle on a resolution parameter that produces a very large number of communities. This behavior highlights the difficulty of characterizing the underlying tradeoffs that drive over- or under-fitting in non-probabilistic methods. We leave a thorough exploration of such questions for future work.
The variation across these 16 methods of the average and maximum number of communities found, provides suggestive evidence that some methods are more prone to over- or under-fitting than others, in practice. The broad variability of detected communities by different methods applied to the same input is troubling, as there is no accepted procedure for deciding which output is more or less useful.
4 Quantifying algorithm similarity
Although algorithms can be divided into groups based on their general approach, e.g., probabilistic and non-probabilistic methods (see Section 1), such conceptual divisions may not reflect practical differences when applied to real data. Instead, a data-driven clustering of algorithms can be obtained by comparing the inferred labels of different methods applied to a large and consistent set of real-world networks. That is, we can use our structurally diverse corpus to empirically identify groups of algorithms that produce similar kinds of community structure across different data sets. (We note that this kind of comparative analysis has previously been employed to better characterize the behavior of different time series methods [56].) We quantify algorithm similarity by computing the mean adjusted mutual information (AMI) [57] between each pair of methods for the communities they recover on each network in the CommunityFitNet corpus. We then apply a standard hierarchical clustering algorithm to the resulting matrix of pairwise similarities in algorithm output (Fig. 3a). Using the unadjusted or normalized mutual information (NMI) yields precisely the same clustering results, indicating that these results are not driven by differences in the sizes of the inferred communities, which are broadly distributed (Fig. 3b).
The derived clustering of algorithms shows that there is, indeed, a major practical difference in the composition of communities found by probabilistic versus non-probabilistic methods. In fact, methods based on probabilistic models typically find communities that are more similar to those produced by other probabilistic methods, than to those of any non-probabilistic method, and vice versa. This high-level dichotomy indicates a fairly strong division in the underlying assumptions of these two classes of algorithms.
The non-probabilistic methods group further subdivides into subgroups of spectral algorithms (S-cBHa, S-NB, and S-cBHm), consensus-based modularity algorithms (Q-MP and Q-GMP), traditional statistical methods (AMOS and LRT-WB), and finally other non-probabilistic methods (including Infomap, Q, and Q-MR). The fact that algorithms themselves cluster together in the kind of outputs they produce has substantial practical implications for any application that depends on the particular composition of a network clustering. It also highlights the subtle impact that different classes of underlying assumptions can ultimately have on the behavior of these algorithms when applied to real-world data.
5 Evaluating Community Structure Quality
To evaluate and compare the quality of the inferred clusters for a particular network, we need a task that depends only on a network’s connectivity and that can reveal when a method is over- or under-fitting these data. (Recall that the NFL and “no ground truth” theorems of Ref. [19] imply that a comparison based on node metadata cannot be reliable.) For relational data, a common approach uses a kind of network cross-validation technique, called link prediction [58], in which some fraction of the observed edges in a network are “held out” during the model-fitting stage, and their likelihood estimated under the fitted model.
We note, however, that there is as yet neither a consensus about how to design such a task optimally nor a theoretical understanding of its relationship to model fit. For example, it was recently shown that selecting the most parsimonious probabilistic model in community detection, by maximizing model posterior probability, can correlate with selecting the model with highest link prediction accuracy [25]. However, these same results show that it is possible to construct networks, i.e., adversarially, in which the most plausible model (in the sense of posterior probability) is not the most predictive one, and hence improving predictive performance can also lead to overfitting. Furthermore, the theoretical implications are unknown for distinct approaches to construct a held-out data set from a single network, for example, holding out a uniformly random subset of edges or all edges attached to a uniformly random subset of nodes. Although there are strong theoretical results for cross-validation and model selection for non-relational data, whether these results extend to networks is unclear as relational data may violate standard independence assumptions. Theoretical progress on this subject would be a valuable direction of future research.
Here, we introduce an evaluation scheme based on a pairing of two complementary network learning tasks: a link prediction task, described above and in Box 1, and a new task we call link description, described below and in Box 2. The goal of these tasks is to characterize the behavior of methods in general, i.e., a method’s general tendency to over- or under-fit across many real networks, rather than to evaluate the quality of a fit to any particular network. A key feature of this scheme is that a method cannot be perfect at both tasks, and each method’s tradeoff in performance across them creates a diagnostic to evaluate the method’s tendency to over- or under-fit real data.
In our evaluation, each method uses a score function to estimate the likelihood that a particular pair of nodes should be connected. Most algorithms optimize some underlying objective function in order to sort among different community partitions. In our main evaluation, we use model-specific score functions, which are based on the method’s own objective function. This choice ensures that each method makes estimates that are aligned with its underlying assumptions about what makes good communities. We also compare these model-specific results with those derived from a SBM-based scoring function in Appendix B. This comparison to a fixed reference point allows us to better distinguish between poor generalizability being caused by a low-quality score function and the selection of a low-quality partition or set of communities.
5.1 Model-specific Link Prediction and Description
Link prediction
When a graph has been sampled to produce some , where , the goal of link prediction is to accurately distinguish missing links (true positives) from non-edges (true negatives) within the set of unobserved connections . Link prediction is thus a binary classification task and its general accuracy can be quantified by the area under the ROC curve (AUC).
For our evaluation, we parameterize this classification accuracy by , which determines the fraction of edges “observed” (equivalently, the density of sampled edges) in , where is a uniformly random subset of edges in the original graph . For a given method , its AUC as a function of , which we call an “accuracy curve,” shows how performs across a wide variety of such sampled graphs, ranging from when very few edges are observed () to when only a few edges are missing ().
Each network in our corpus produces one such accuracy curve, and we obtain a single “benchmark performance curve” for each method by computing the mean AUC at each value of , across curves produced by the networks in the CommunityFitNet corpus. When computing the AUC, we break ties in the scoring function uniformly at random. Box 1 describes the link prediction task in detail.
In this setting, the AUC is preferred over precision-recall because we are interested in the general performance of these classifiers, rather than their performance under any specific prediction setting. Evaluating other measures of accuracy is beyond the scope of this study. Comparing benchmark performance curves across community detection methods quantifies their relative generalizability and predictiveness, and allows us to assess the quality of choice each method makes for the number of clusters it found in Section 3.2.
In our link prediction and link description evaluations, we exclude S-cBHa and S-cBHm because they produce very similar results to the S-NB method, LRT-WB because of its high computational complexity, and AMOS and Q-GMP because of convergence issues. All other methods are included.
We now define a model-specific score function for each method (see Appendix for more details). Each score function uses the corresponding method to define a model-specific function that estimates the likelihood that a pair of nodes should be connected. For probabilistic methods, the natural choice of score function is simply the posterior probability the model assigns to a pair . For non-probabilistic methods, we constructed score functions that reflected the underlying assumptions of the corresponding method, without introducing many additional or uncontrolled assumptions.
For regularized likelihood/Bayesian approaches of the SBM (cICL-HKK, B-NR and B-HKK), we follow the same scoring rule as in Ref. [59]. Specifically, the score assigned to an unobserved edge between nodes and , for with community assignments of and , respectively, is given by , where is the number of edges in the observed network between the groups and and is the maximum possible number of links between the groups and . For DC-SBM we define , where is the normalized degree of node with respect to total degree of its type as the maximum likelihood estimation of this parameter. For all the Q methods, Infomap, and MDL we define the scores as the contribution that the added unobserved edge would make to their corresponding partition score functions. For the Q methods, we compute the increase in the modularity score due to the added unobserved edge, while for Infomap and MDL we compute the decrease of their objective functions. For each of these methods, the contribution of each pair of nodes is computed under the partition obtained prior to adding the candidate pair as an edge.
There is no commonly accepted link prediction approach for spectral clustering algorithms that is independent of metadata. Although there are some non-linear embedding methods for link prediction like node2vec [60], here we focus on linear decomposition techniques. For spectral clustering, we introduce and use a new link prediction technique based on eigenvalue decomposition. Let the adjacency matrix of the observed graph be denoted by . This matrix can be decomposed as , where with as th eigenvector of matrix and matrix is the diagonal matrix of eigenvalues of , where .
To define a new scoring function, we use a low-rank matrix approximation of using the largest eigenvalues and their corresponding eigenvectors, i.e., we let , where can be inferred using a model selection spectral algorithm. The spectral method scoring rule assigned to an unobserved edge between nodes and , for , is the corresponding entry value in low-rank approximation. We note that alternative constructions exist for a spectral scoring function that meets the aforementioned criteria. For instance, one could use the low-rank approximation via the non-backtracking matrix itself, but such a function would be quite non-trivial. On the other hand, the SBM-based and model-specific performance comparison given in Appendix B indicates that the score function we use for this algorithm (S-NB) performs well and it is not itself the cause of this algorithm’s observed poor performance. Exploring the broader space of scoring functions for spectral or other methods remains an interesting direction for future work.
The performance of each method is assessed by numerically computing its benchmark performance curve, using the 572 real-world networks in the CommunityFitNet corpus. Exactly calculating a single accuracy curve for a sparse graph takes time, which is prohibitive for large networks. However, each AUC in a curve may be accurately estimated using Monte Carlo, because the AUC is mathematically equivalent to the probability that a uniformly random true positive is assigned a higher score than a uniformly random true negative. In all of our experiments, an accuracy of is sufficient to distinguish performance curves, requiring 10,000 Monte Carlo samples.
Community detection methods that are prone to overfitting (underfitting) will tend to find more (fewer) communities in a network than is optimal. Hence, the induced partition of the adjacency matrix into within- and between-group blocks will over- (under-) or under- (under-) estimate the optimal block densities. This behavior will tend to produce lower AUC scores for the prediction of uniformly held-out pairs in the corresponding evaluation set. That is, a lower benchmark performance curve indicates a greater general tendency to over- or under-fit on real-world networks.
Link description
The goal of link description is to accurately distinguish observed edges (true positives) and observed non-edges (true negatives) within the set of all pairs . That is, link description asks how well a method learns an observed network, and it is also a binary classification task.
As in link prediction, we parameterize the sampled graph by the fraction of observed edges from the original graph . And, we use the same scoring functions to evaluate an algorithm’s accuracy at learning to distinguish edges from non-edges. Then, using the networks in the CommunityFitNet corpus, we obtain a benchmark performance curve for each method. Box 2 describes the link description task in detail.
Crucially, an algorithm cannot perform perfectly at both the link prediction and the link description tasks. If an algorithm finds a very good partition for distinguishing between observed edges and observed non-edges (link description), this partition must assign low scores to all of the observed non-edges. This fact implies that the same partition cannot also be very good for distinguishing between non-edges and missing edges (link prediction), as it must assign low scores to both. The link prediction and description tasks thus force an algorithmic tradeoff, similar to a bias-variance tradeoff, and the joint behavior of a method across the two tasks provides a means to evaluate a tendency to over- or under-fit to real data.
Results
The benchmark performance curves generally exhibit reasonable behavior: across the CommunityFitNet corpus networks, methods generally tend to improve their performance on both link prediction and link description tasks as the fraction of sampled edges varies from very low to very high (Fig. 4), with some exceptions. For our purposes, we are specifically interested in the relative differences between the curves, which sheds new light on the degree to which methods tend to over- or under-fit on network data.
In link prediction (Fig. 4a), the low curves for Q methods reinforce our previous suggestion that these algorithms exhibit poor generalizability. Their performance is particularly poor when the edge density in the observed network is very low, e.g., when more than two-thirds of the edges are missing () for Q-MR and Q. This behavior aligns well with the evidence in Section 3.2 that these methods tend to over-partition the network, finding many more communities than is optimal.
We also find that Q and Q-MR exhibit nearly identical benchmark performance curves for link prediction. Although Q has a larger resolution limit, which leads to fewer inferred clusters, our results suggest that Q still finds more communities than is optimal, especially compared to other methods. Evidently, these two methods tend to misinterpret noisy connectivity within communities as indicating the presence of substructure deserving of additional fitting, and they do this in a similar way, leading to similar numbers of communities and very similar link prediction curves. This behavior may reflect the common assumptions of these methods that communities are assortative (edges mainly within groups) and that the between-group edge densities are uniform. If this assumption is not reflected in the input network’s actual large-scale structure, these methods can overfit the number of communities (Fig. 2 and Fig. 7; see Appendix), subdividing larger groups to find a partition with the preferred structure.
The best benchmark performance curves for link prediction are produced by Bayesian methods (B-NR (SBM), B-HKK, and cICL-HKK) and MDL methods (both DC-SBM and SBM). And the SBM methods generally outperform the DC-SBM methods, except for the DC-SBM with MDL regularization, which yields the best overall benchmark curve for nearly every value of .
Such a difference is surprising since the number of inferred clusters for both Bayesian and regularized-likelihood methods is nearly identical (Fig. 2a,b), and the precise composition of the clusters is very similar (Fig. 3). However, these methods use different score functions to estimate the likelihood of a missing edge, and evidently, those based on more general rules perform better at link prediction. For instance, B-NR (SBM) assigns the same scores to the links inside each cluster, whereas B-NR (DC-SBM) assigns higher scores to the links connected to high degree nodes. In B-NR, the emphasis on modeling node degrees by the DC-SBM score function leads to worse performance. In contrast, the MDL technique, while based on the same underlying probabilistic network model, assigns higher scores to edges that produce a better compression of the input data (shorter description length). Hence, the MDL score function prefers adjacencies that decrease the model entropy without increasing model complexity, meaning that it predicts missing links in places with better community structure. The MDL approach to controlling model complexity, particularly in the DC-SBM score function, is more restrictive than most Bayesian approaches, but it evidently leads to more accurate link prediction (Fig. 4a).
The benchmark performance curves for Infomap, spectral clustering (S-NB), and B-NR (DC-SBM) are similar, especially for modest or larger values of , and are close to the middle of the range across algorithms. Furthermore, we find that the curves of B-HKK (SBM) and cICL-HKK (SBM) are similar to, but lower than B-NR (SBM). There are two possibilities for this behavior: (i) the number of inferred clusters is inaccurate, or (ii) these methods perform poorly at link prediction. Because the score functions of B-HKK (SBM), cICL-HKK (SBM), and B-NR (SBM) are similar, the lower link prediction benchmark performance is more likely caused by a low-quality set of inferred clusters, due to over- or under-fitting.
The benchmark results for link description (Fig. 4b) show that B-HKK (SBM) and cICL-HKK (SBM) perform relatively poorly compared to most other methods, which suggests that they must tend to under-fit on networks. This behavior is likely driven by their larger penalty terms, e.g., compared to methods like B-NR (SBM), which will favor finding a smaller number of clusters in practice (Fig. 2). This behavior will tend to aid in link prediction at the expense of link description. We note that Ref. [31] introduced a better approximation for B-HKK (SBM)’s penalty terms, which might suggest that the method would find more optimal partitions in theory. However, our results show that this is not the case in practice, and instead this method illustrates a tradeoff in which a greater penalty for model complexity, by over-shrinking or over-smoothing the model space, can lead to poor performance in practical settings.
The best benchmark performance for link description is given by Infomap first, followed by the Bayesian technique B-NR (DC-SBM), and by modularity Q and Q-MR, all of which exhibit only middling performance curves for link prediction. This behavior suggests that all of these methods tend to overfit on networks. Others are better at link prediction compared to their relative performance at link description (MDL (DC-SBM), B-NR (SBM), cICL-HKK, and B-HKK), suggesting that these methods tend to well-fit on networks. And, some methods perform poorly on both tasks, such as Q-MP. These comparisons illustrate the intended tradeoff in our diagnostic between the link prediction and link description tasks, and provide a useful contrast for evaluating the practical implications of different kinds of underlying algorithmic assumptions.
The relative performance of Q, Q-MR, and Infomap versus other methods on these tasks provides an opportunity to understand how an algorithm’s assumptions can drive over- and under-fitting in practice. By definition, the partitions found by Infomap and modularity-based methods like Q and Q-MR will tend to have highly assortative communities and a uniformly low density of edges between communities. Such a partition must perform poorly at modeling the few edges between these clusters; hence, as the density of these edges increases with , these methods’ link description performance must tend to decrease. In contrast, nearly all other methods generally perform better at link description as more edges are sampled, except for B-NR (DC-SBM), whose performance is relatively independent of . As a group, the probabilistic methods have the flexibility to model different rates of between-group connectivity, but this behavior requires sufficient observed connectivity in order to estimate the corresponding densities. As a result, these models are less data efficient than are modularity and spectral methods at describing the observed structure, especially in the sparsely-sampled regime (low ).
The exception to this interpretation is Q-MP, which exhibits a poor performance on both tasks (Fig. 4a,b). These tendencies can be understood in light of the relatively small number of communities Q-MP tends to find (Fig. 2 and Fig. 7; see Appendix), which suggests that it tends to substantially under-fit to the data. In fact, Q-MP uses a consensus of many high-modularity partitions in order to explicitly avoid overfitting to spurious communities. Evidently, this strategy tends to find far fewer communities than is optimal for either link description or link prediction. The Q-GMP method may perform better, as it controls the bias-variance tradeoff through a learning phase on its parameters. Due to poor convergence behavior with this method, however, we leave this line of investigation for future work.
The reference list from the paper itself. Each links out to its DOI / PubMed record.
- 1[1] M. A. Porter, J.-P. Onnela, and P. J. Mucha, “Communities in networks,” Notices of the American Mathematical Society , vol. 56, no. 9, pp. 1082–1097, 1164–1166, 2009.
- 2[2] S. Fortunato, “Community detection in graphs,” Physics Reports , vol. 486, pp. 75–174, 2010.
- 3[3] T. P. Peixoto, “Bayesian stochastic blockmodeling,” ar Xiv:1705.10225 , 2017.
- 4[4] P. W. Holland, K. B. Laskey, and S. Leinhardt, “Stochastic blockmodels: First steps,” Soc. Netw. , vol. 5, no. 2, pp. 109–137, 1983.
- 5[5] M. E. J. Newman and M. Girvan, “Finding and evaluating community structure in networks,” Phys. Rev. E , vol. 69, no. 2, p. 026113, 2004.
- 6[6] J. M. Hofman and C. H. Wiggins, “Bayesian approach to network modularity,” Phys. Rev. Lett. , vol. 100, no. 25, p. 258701, 2008.
- 7[7] X. Yan, “Bayesian model selection of stochastic block models,” in IEEE/ACM International Conference on Advances in Social Networks Analysis and Mining (ASONAM) . IEEE, 2016, pp. 323–328.
- 8[8] J.-J. Daudin, F. Picard, and S. Robin, “A mixture model for random graphs,” Stat. Comput. , vol. 18, no. 2, pp. 173–183, 2008.
