Breaking the $1/\sqrt{n}$ Barrier: Faster Rates for Permutation-based Models in Polynomial Time
Cheng Mao, Ashwin Pananjady, Martin J. Wainwright

TL;DR
This paper introduces a polynomial-time algorithm for estimating permutation-based isotonic matrices that achieves faster convergence rates, narrowing the gap between statistical and computational efficiency in matrix estimation.
Contribution
The authors develop a new algorithm that improves the estimation rate for permutation-based models, achieving a rate of O(n^{-3/4}) in polynomial time, surpassing previous methods.
Findings
Achieves O(n^{-3/4}) rate in Frobenius norm
Efficient polynomial-time algorithm for permutation-based matrix estimation
Narrowing the gap between statistical and computational rates
Abstract
Many applications, including rank aggregation and crowd-labeling, can be modeled in terms of a bivariate isotonic matrix with unknown permutations acting on its rows and columns. We consider the problem of estimating such a matrix based on noisy observations of a subset of its entries, and design and analyze a polynomial-time algorithm that improves upon the state of the art. In particular, our results imply that any such matrix can be estimated efficiently in the normalized Frobenius norm at rate , thus narrowing the gap between and , which were hitherto the rates of the most statistically and computationally efficient methods, respectively.
Click any figure to enlarge with its caption.
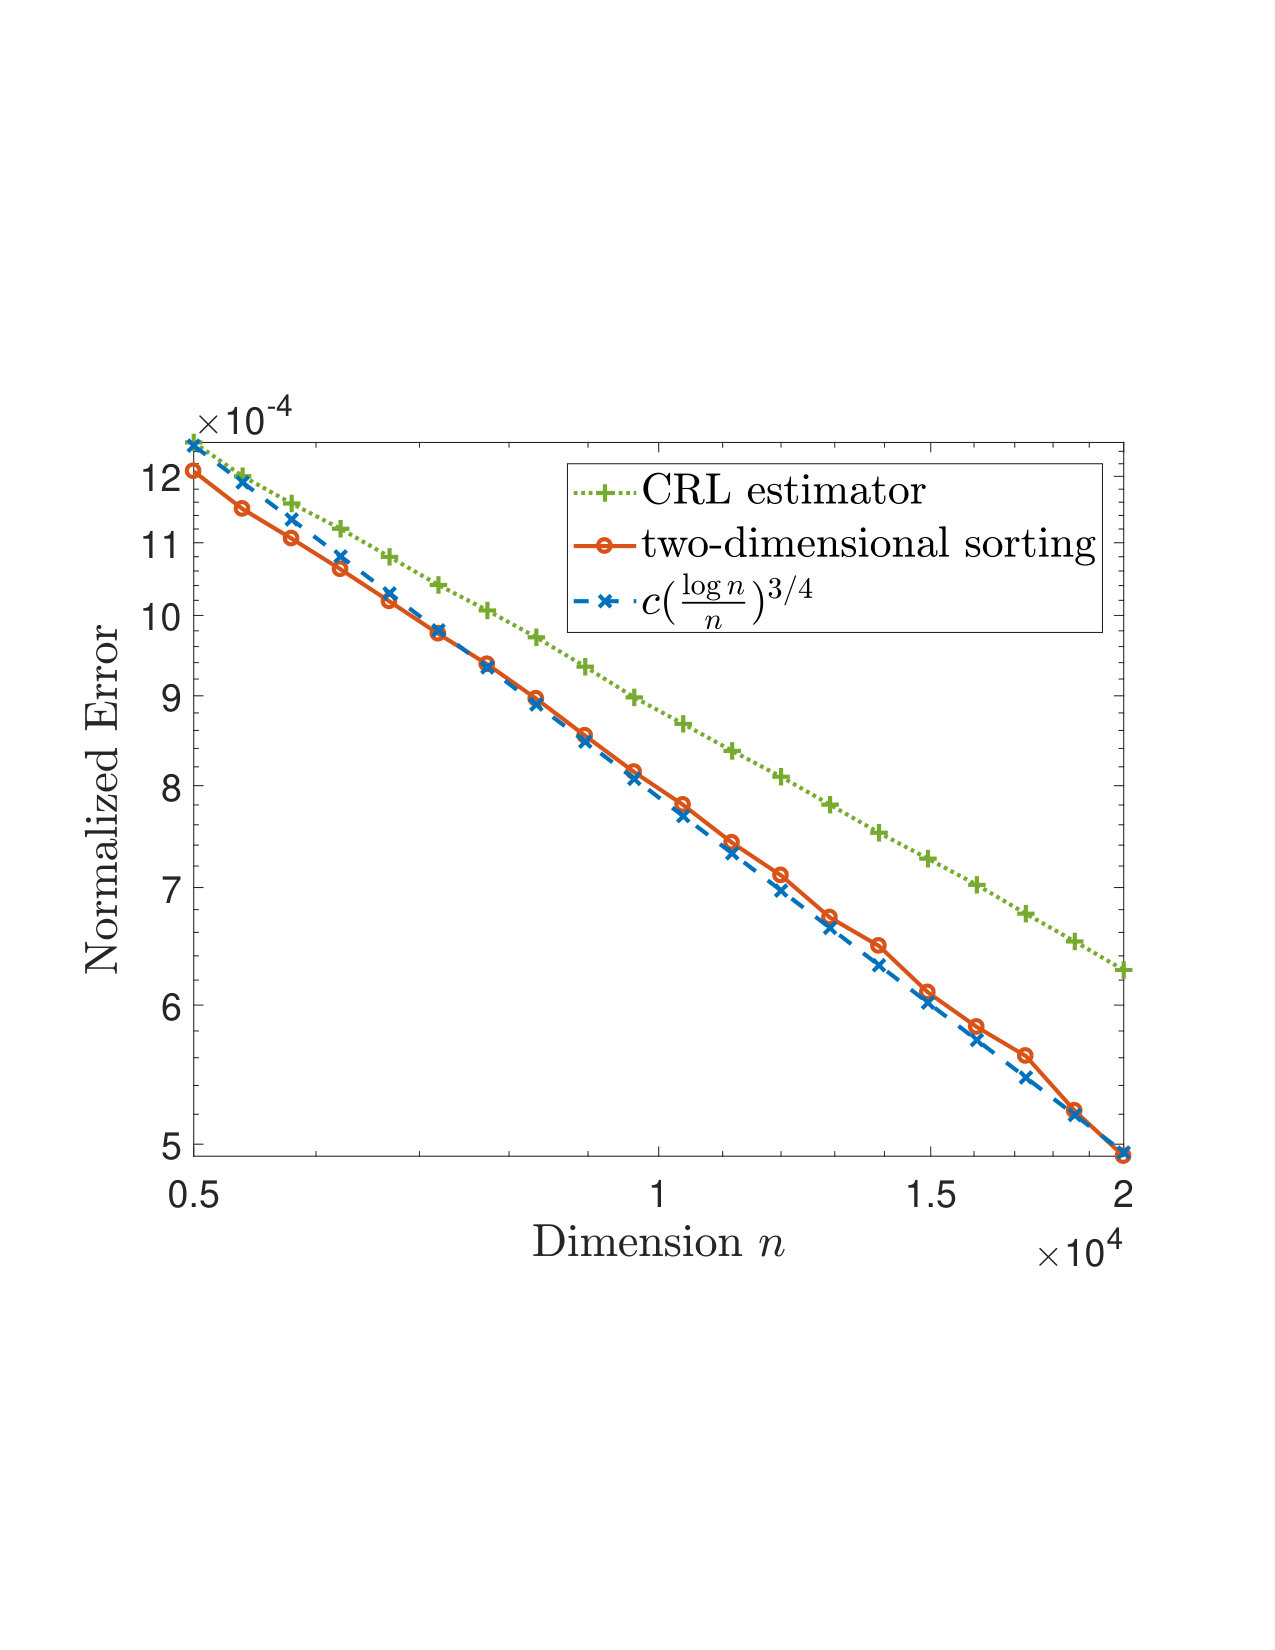 Figure 2
 Figure 2
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
Taxonomy
TopicsImbalanced Data Classification Techniques · Sparse and Compressive Sensing Techniques · Machine Learning and Algorithms
**Breaking the Barrier: Faster Rates for
Permutation-based Models in Polynomial Time**
[TABLE]
[TABLE]
Abstract
Many applications, including rank aggregation and crowd-labeling, can be modeled in terms of a bivariate isotonic matrix with unknown permutations acting on its rows and columns. We consider the problem of estimating such a matrix based on noisy observations of a subset of its entries, and design and analyze a polynomial-time algorithm that improves upon the state of the art. In particular, our results imply that any such matrix can be estimated efficiently in the normalized Frobenius norm at rate , thus narrowing the gap between and , which were hitherto the rates of the most statistically and computationally efficient methods, respectively.
1 Introduction
Structured††Accepted for presentation at Conference on Learning Theory (COLT) 2018 matrices with entries in the range and unknown permutations acting on their rows and columns arise in multiple applications, including estimation from pairwise comparisons [BT52, SBGW17] and crowd-labeling [DS79, SBW16b]. Traditional parametric models [BT52, Luc59, Thu27, DS79] assume that these matrices are obtained from rank-one matrices via a known link function. Aided by tools such as maximum likelihood estimation and spectral methods, researchers have made significant progress in studying both statistical and computational aspects of these parametric models [HOX14, RA14, SBB*+*16, NOS16, ZCZJ16, GZ13, GLZ16, KOS11b, LPI12, DDKR13, GKM11] and their low-rank generalizations [RA16, NOTX17, KOS11a].
There has been evidence from empirical studies (e.g., [ML65, BW97]) that real-world data is not always well-captured by such parametric models. With the goal of increasing model flexibility, a recent line of work has studied the class of permutation-based models [Cha15, SBGW17, SBW16b]. Rather than imposing parametric conditions on the matrix entries, these models impose only shape constraints on the matrix, such as monotonicity, before unknown permutations act on the its rows and columns. This more flexible class reduces modeling bias compared to its parametric counterparts while, perhaps surprisingly, producing models that can be estimated at rates that differ only by logarithmic factors from parametric models. On the negative side, these advantages of permutation-based models are accompanied by significant computational challenges. The unknown permutations make the parameter space highly non-convex, so that efficient maximum likelihood estimation is unlikely. Moreover, spectral methods are often suboptimal in approximating shape-constrained sets of matrices [Cha15, SBGW17]. Consequently, results from many recent papers show a non-trivial statistical-computational gap in estimation rates for models with latent permutations [SBGW17, CM16, SBW16b, FMR16, PWC17].
Related work.
While the main motivation of our work comes from nonparametric methods for aggregating pairwise comparisons, we begin by discussing a few other lines of related work. The current paper lies at the intersection of shape-constrained estimation and latent permutation learning. Shape-constrained estimation has long been a major topic in nonparametric statistics, and of particular relevance to our work is the estimation of a bivariate isotonic matrix without latent permutations [CGS18]. There, it was shown that the minimax rate of estimating an matrix from noisy observations of all its entries is . The upper bound is achieved by the least squares estimator, which is efficiently computable due to the convexity of the parameter space.
Shape-constrained matrices with permuted rows or columns also arise in applications such as seriation [FJBd13, FMR16] and feature matching [CD16]. In particular, the monotone subclass of the statistical seriation model [FMR16] contains matrices that have increasing columns, and an unknown row permutation. The authors established the minimax rate for estimating matrices in this class and proposed a computationally efficient algorithm with rate . For the subclass of such matrices where in addition, the rows are also monotone, the results of the current paper improve the two rates to and respectively.
Another related model is that of noisy sorting [BM08], which involves a latent permutation but no shape-constraint. In this prototype of a permutation-based ranking model, we have an unknown, matrix with constant upper and lower triangular portions whose rows and columns are acted upon by an unknown permutation. The hardness of recovering any such matrix in noise lies in estimating the unknown permutation. As it turns out, this class of matrices can be estimated efficiently at minimax optimal rate by multiple procedures: the original work by Braverman and Mossel [BM08] proposed an algorithm with time complexity for some unknown and large constant , and recently, an -time algorithm was proposed by Mao et al. [MWR17]. These algorithms, however, do not generalize beyond the noisy sorting class, which constitutes a small subclass of an interesting class of matrices that we describe next.
The most relevant body of work to the current paper is that on estimating matrices satisfying the strong stochastic transitivity condition, or SST for short. This class of matrices contains all bivariate isotonic matrices with unknown permutations acting on their rows and columns, with an additional skew-symmetry constraint. The first theoretical study of these matrices was carried out by Chatterjee [Cha15], who showed that a spectral algorithm achieved the rate in the normalized Frobenius norm. Shah et al. [SBGW17] then showed that the minimax rate of estimation is given by , and also improved the analysis of the spectral estimator of Chatterjee [Cha15] to obtain the computationally efficient rate . In follow-up work [SBW16a], they also showed a second estimator based on the Borda count that achieved the same rate, but in near-linear time. In related work, Chatterjee and Mukherjee [CM16] analyzed a variant of the estimator, showing that for subclasses of SST matrices, it achieved rates that were faster than . In a complementary direction, a superset of the current authors [PMM*+*17] analyzed the estimation problem under an observation model with structured missing data, and showed that for many observation patterns, a variant of the estimator was minimax optimal.
Shah et al. [SBW16a] also showed that conditioned on the planted clique conjecture, it is impossible to improve upon a certain notion of adaptivity of the estimator in polynomial time. Such results have prompted various authors [FMR16, SBW16a] to conjecture that a similar statistical-computational gap also exists when estimating SST matrices in the Frobenius norm.
Our contributions.
Our main contribution in the current work is to tighten the aforementioned statistical-computational gap. More precisely, we study the problem of estimating a bivariate isotonic matrix with unknown permutations acting on its rows and columns, given noisy, partial observations of its entries; this matrix class strictly contains the SST model [Cha15, SBGW17] for ranking from pairwise comparisons. As a corollary of our results, we show that when the underlying matrix has dimension and noisy entries are observed, our polynomial-time, two-dimensional sorting algorithm provably achieves the rate of estimation in the normalized Frobenius norm; thus, this result breaks the previously mentioned barrier [SBGW17, CM16]. Although the rate still differs from the minimax optimal rate , our algorithm is, to the best of our knowledge, the first efficient procedure to obtain a rate faster than uniformly over the SST class. This guarantee, which is stated in slightly more technical terms below, can be significant in practice (see Figure 1).
Main theorem (informal)
There is an estimator computable in time such that for any SST matrix , given Bernoulli observations of its entries, we have
[TABLE]
Our algorithm is novel in the sense that it is neither spectral in nature, nor simple variations of the Borda count estimator that was previously employed. Our algorithm takes advantage of the fine monotonicity structure of the underlying matrix along both dimensions, and this allows us to prove tighter bounds than before. In addition to making algorithmic contributions, we also briefly revisit the minimax rates of estimation.
Organization.
In Section 2, we formally introduce our estimation problem. Section 3 contains statements and discussions of our main results, and in Section 4, we describe in detail how the estimation problem that we study is connected to applications in crowd-labeling and ranking from pairwise comparisons. We provide the proofs of our main results in Section 5.
Notation.
For a positive integer , let . For a finite set , we use to denote its cardinality. For two sequences and , we write if there is a universal constant such that for all . The relation is defined analogously. We use to denote universal constants that may change from line to line. We use to denote the Bernoulli distribution with success probability , the notation to denote the binomial distribution with trials and success probability , and the notation to denote the Poisson distribution with parameter . Given a matrix , its -th row is denoted by . For a vector , define its variation as . Let denote the set of all permutations . Let denote the identity permutation, where the dimension can be inferred from context.
2 Background and problem setup
In this section, we present the relevant technical background and notation on permutation-based models, and introduce the observation model of interest.
2.1 Matrix models
Our main focus is on designing efficient algorithms for estimating a bivariate isotonic matrix with unknown permutations acting on its rows and columns. Formally, we define to be the class of matrices in with nondecreasing rows and nondecreasing columns. For readability, we assume throughout that unless otherwise stated; our results can be straightforwardly extended to the other case. Given a matrix and permutations and , we define the matrix by specifying its entries as
[TABLE]
Also define the class as the set of matrices that are bivariate isotonic when viewed along the row permutation and column permutation , respectively.
The class of matrices that we are interested in estimating contains bivariate isotonic matrices whose rows and columns are both acted upon by unknown permutations:
[TABLE]
2.2 Observation model
In order to study estimation from noisy observations of a matrix in the class , we suppose that noisy entries are sampled independently and uniformly with replacement from all entries of . This sampling model is popular in the matrix completion literature, and is a special case of the trace regression model [NW12, KLT11]. It has also been used in the context of permutation models by Mao et al. [MWR17] to study the noisy sorting class.
More precisely, let denote the matrix with in the -th entry and [math] elsewhere, and suppose that is a random matrix sampled independently and uniformly from the set . We observe independent pairs from the model
[TABLE]
where the observations are contaminated by independent, centered, sub-Gaussian noise with variance parameter . Of particular interest is the noise model considered in applications such as crowd-labeling and ranking from pairwise comparisons. Here our samples take the form
[TABLE]
and consequently, the sub-Gaussian parameter is bounded; for a discussion of other regimes of noise in a related matrix model, see Gao [Gao17].
For analytical convenience, we employ the standard trick of Poissonization, whereby we assume throughout the paper that random samples are drawn according to the trace regression model (1). Upper and lower bounds derived under this model carry over with loss of constant factors to the model with exactly samples; for a detailed discussion, see Appendix B.
For notational convenience, denote the probability that an entry of the matrix is observed under Poissonized sampling by . Since we assume throughout that , it can be verified that .
Now given observations , let us define the matrix of observations , with entry given by
[TABLE]
In words, the rescaled entry is the average of all the noisy realizations of that we have observed, or zero if the entry goes unobserved. Note that so that . Moreover, we may write the model in the linearized form , where is a matrix of additive noise having independent, zero-mean, sub-Gaussian entries.
3 Main results
In this section, we present our main results—we begin by briefly revisiting the fundamental limits of estimation, and then introduce our algorithms in Section 3.2. We assume throughout this section that as per the setup, we have and .
3.1 Statistical limits of estimation
We begin by characterizing the fundamental limits of estimation under the trace regression observation model (1) with observations. We define the least squares estimator over the class of matrices as the projection
[TABLE]
The projection is a non-convex problem, and is unlikely to be computable exactly in polynomial time. However, studying this estimator allows us to establish a baseline that characterizes the best achievable statistical rate. The following theorem characterizes its risk up to a logarithmic factor in the dimension; recall the shorthand .
Theorem 1**.**
For any matrix , we have
[TABLE]
*Additionally, under the Bernoulli observation model (2), any estimator satisfies *
[TABLE]
The factor appears in the upper bound instead of the noise variance because even if the noise is zero, there are missing entries. The theorem characterizes the minimax rate of estimation for the class up to a logarithmic factor.
3.2 Efficient algorithms
Next, we propose polynomial-time algorithms for estimating the permutations and the matrix . Our main algorithm relies on two distinct steps: first, we estimate the unknown permutations, and then project onto the class of matrices that are bivariate isotonic when viewed along the estimated permutations. The formal meta-algorithm is described below.
Algorithm 1 (meta-algorithm)
- •
Step 0: Split the observations into two disjoint parts, each containing observations, and construct the matrices and .
- •
Step 1: Use to obtain the permutation estimates .
- •
Step 2: Return the matrix estimate
Owing to the convexity of the set , the projection operation in Step 2 of the algorithm can be computed in near linear time [BDPR84, KRS15]. The following result, a slight variant of Proposition 4.2 of Chatterjee and Mukherjee [CM16], allows us to characterize the error rate of any such meta-algorithm as a function of the permutation estimates .
Proposition 1**.**
Suppose that where and are unknown permutations in and respectively. Then with probability at least , we have
[TABLE]
The first term on the right hand side of the bound (5) corresponds to an estimation error, if the true permutations and were known a priori, and the latter two terms correspond to an approximation error that we incur as a result of having to estimate these permutations from data. Comparing the bound (5) to the minimax lower bound (4b), we see that up to a logarithmic factor, the first term of the bound (5) is unavoidable, and so we can restrict our attention to obtaining good permutation estimates . We now present our main permutation estimation procedure that can be plugged into Step 1 of this meta-algorithm.
3.2.1 Two-dimensional sorting
Since the underlying matrix of interest is individually monotonic along each dimension, the row and column sums provide noisy information about the respective unknown permutations. Consequently, variants of such procedures are popular in the literature [CM16, FMR16]. However, such a procedure does not take simultaneous advantage of the fact that the underlying matrix is monotonic in both dimensions. To improve upon simply sorting row (resp. column) sums, we propose an algorithm that first sorts the columns (resp. rows) of the matrix approximately, and then exploits this approximate ordering to sort the rows (resp. columns) of the matrix.
We need more notation to facilitate the description of the algorithm. For a partition
of the set 111 is a partition of if and for , we group the columns of a matrix into blocks according to their indices in , and refer to as a partition or blocking of the columns of .
Given a data matrix , the following blocking subroutine returns a column partition . In the main algorithm, partial row sums are computed on indices contained in each block.
Subroutine 1 (blocking)
- •
Step 1: Compute the column sums of the matrix as
[TABLE]
Let be the permutation along which the sequence is nondecreasing.
- •
Step 2: Set \tau=16(\zeta+1)\Big{(}\sqrt{\frac{n_{1}^{2}n_{2}}{N}\log(n_{1}n_{2})}+\frac{n_{1}n_{2}}{N}\log(n_{1}n_{2})\Big{)} and . Partition the columns of into blocks by defining
[TABLE]
Note that each block is contiguous when the columns are permuted by .
- •
Step 3 (aggregation): Set . Call a block “large” if and “small” otherwise. Aggregate small blocks in while leaving the large blocks as they are, to obtain the final partition .
More precisely, consider the matrix having nondecreasing column sums and contiguous blocks. Call two small blocks “adjacent” if there is no other small block between them. Take unions of adjacent small blocks to ensure that the size of each resulting block is in the range . If the union of all small blocks is smaller than , aggregate them all.
Return the resulting partition .
The threshold is a chosen to be a high probability bound on the perturbation of any column sum. In particular, this ensures that we obtain blocks containing columns that are close when the matrix is ordered according to the correct permutation. Computing partial row sums within each block then provides more refined information about the underlying row permutation than simply computing full row sums, and this intuition underlies the two-dimensional sorting algorithm to follow. As a technical detail, it is important to note that Step 3 aggregates small blocks into large enough ones to reduce noise in these partial row sums. We are now in a position to describe the two-dimensional sorting algorithm.
Algorithm 2 (two-dimensional sorting)
- •
Step 0: Split the observations into two independent subsamples of equal size, and form the corresponding matrices and according to equation (3).
- •
Step 1: Apply Subroutine 1 to the matrix to obtain a partition of the columns. Let be the number of blocks in .
- •
Step 2: Using the second sample , compute the row sums
[TABLE]
and the partial row sums within each block
[TABLE]
Create a directed graph with vertex set , where an edge is present if either
[TABLE]
- •
Step 3: Compute a topological sort of the graph ; if none exists, set .
- •
Step 4: Repeat Steps 1–3 with replacing for , the roles of and switched, and the roles of and switched, to compute the permutation estimate .
- •
Step 5: Return the permutation estimates .
Recall that a permutation is called a topological sort of if for every directed edge . The construction of the graph in Step 2 dominates the computational complexity, and takes time . We have the following guarantee for the two-dimensional sorting algorithm.
Theorem 2**.**
For any matrix , we have
[TABLE]
with probability at least .
In particular, setting , we have proved that our efficient estimator enjoys the rate
[TABLE]
which is the main theoretical guarantee established in this paper for permutation-based models.
4 Applications
We now discuss in detail how the matrix models studied in this paper arise in practice. The class was studied as a permutation-based model for crowd-labeling [SBW16b] in the case of binary questions, and was proposed as a strict generalization of the classical Dawid-Skene model [DS79, KOS11b, LPI12, DDKR13, GKM11]. Here there is a set of questions of a binary nature; the true answer to these questions can be represented by a vector , and our goal is to estimate this vector by asking these questions to workers on a crowdsourcing platform. A key to this problem is being able to model the probabilities with which workers answer questions correctly, and we do so by collecting these probabilities within a matrix . Assuming that workers have a strict ordering of their abilities, and that questions have a strict ordering of their difficulties, the matrix is bivariate isotonic when the rows are ordered in increasing order of worker ability, and columns are ordered in decreasing order of question difficulty. However, since worker abilities and question difficulties are unknown a priori, the matrix of probabilities obeys the inclusion .
In the calibration problem, we would like to ask questions whose answers we know a priori, so that we can estimate worker abilities and question difficulties, or more generally, the entries of the matrix . This corresponds to estimating matrices in the class from noisy observations of their entries, whose rate of estimation is our main result.
A subclass of specializes to the case , and also imposes an additional skew symmetry constraint. More precisely, define analogously to the class , except with matrices having columns that are nonincreasing instead of nondecreasing. Also define the class , and the strong stochastic transitivity class
[TABLE]
The class is useful as a model for estimation from pairwise comparisons [Cha15, SBGW17], and was proposed as a strict generalization of parametric models for this problem [BT52, NOS16, RA14]. In particular, given items obeying some unknown underlying ranking , entry of a matrix represents the probability with which item beats item in a pairwise comparison between them. The shape constraint encodes the transitivity condition that for all triples obeying , we must have
[TABLE]
For a more classical introduction to these models, see the papers [Fis73, ML65, BW97] and the references therein. Our task is to estimate the underlying ranking from results of passively chosen pairwise comparisons222Such a passive, simultaneous setting should be contrasted with the active case (e.g., [HSRW16, FOPS17, AAAK17]), where we may sequentially choose pairs of items to compare depending on the results of previous comparisons. between the items, or more generally, to estimate the underlying probabilities that govern these comparisons333Accurate, proper estimates of translate to accurate estimates of the ranking (see Shah et al. [SBGW17]).. All the results we obtain in this work clearly extend to the class with minimal modifications; for example, either of the two estimates or may be returned as an estimate of the permutation . Consequently, the informal theorem stated in the introduction is an immediate corollary of Theorem 2 once these modifications are made to the algorithm.
5 Proofs
Throughout the proofs, we assume without loss of generality that . Because we are interested in rates of estimation up to universal constants, we assume that each independent subsample contains observations (instead of or ). We use the shorthand , throughout.
5.1 Some preliminary lemmas
Before turning to the proof of Theorems 1 and 2, we provide three lemmas that underlie many of our arguments. The first lemma can be readily distilled from the proof of Theorem 5 of Shah et al. [SBGW17] with slight modifications. It is worth mentioning that similar lemmas characterizing the estimation error of a bivariate isotonic matrix were also proved by [CGS18, CM16].
Lemma 1** ([SBGW17]).**
Let , and let . Assume that our observation model takes the form , where the noise matrix satisfies the properties
- (a)
the entries are independent, centered, -sub-Gaussian random variables; 2. (b)
the second moments are bounded as for all .
Then the least squares estimator satisfies
[TABLE]
Moreover, the same result holds if the class is replaced by the class .
The proof closely follows that of Shah et al. [SBGW17, Theorem 5]; consequently, we postpone it to Appendix A. The next lemma establishes concentration of sums of our observations around their means.
Lemma 2**.**
For any nonempty subset , it holds that
[TABLE]
Proof.
According to definitions (1) and (3), we have
[TABLE]
where is a -sub-Gaussian noise matrix with independent entries. Consequently, we can express the noise on each entry as where are independent, zero-mean random variables given by
[TABLE]
and are independent, zero-mean random variables such that
[TABLE]
We control the two separately. First, we have and the variance of each is bounded by . Hence Bernstein’s inequality for bounded noise yields
[TABLE]
Taking and recalling that , we obtain
[TABLE]
In order to control the deviation of the sum of , we note that the -th moment of is bounded by Then another version of Bernstein’s inequality [BLM13] yields
[TABLE]
and setting gives
[TABLE]
Combining the above two deviation bounds completes the proof. ∎
The last lemma is a deterministic result.
Lemma 3**.**
Let be a nondecreasing sequence of real numbers. If is a permutation in such that whenever where , then for all .
Proof.
Suppose that for some index . Since is a bijection, there must exist an index such that . However, we then have , which contradicts the assumption. A similar argument shows that also leads to a contradiction. Therefore, we obtain that for every . ∎
With these lemmas in hand, we are now ready to prove our main theorems.
5.2 Proof of Theorem 1
We split the proof into two parts by proving the upper and lower bounds separately.
5.2.1 Proof of upper bound
The upper bound follows from Lemma 1 once we check the conditions on the noise for our model. We have seen in the proof of Lemma 2 that the noise on each entry can be written as . Again, and are -sub-Gaussian and -sub-Gaussian respectively, and have variances bounded by and respectively. Hence the conditions on in Lemma 1 are satisfied. Then we can apply the lemma, recall the relation and normalize the bound by to complete the proof.
5.2.2 Proof of lower bound
The lower bound follows from an application of Fano’s lemma. The technique is standard, and we briefly review it here. Suppose we wish to estimate a parameter over an indexed class of distributions in the square of a (pseudo-)metric . We refer to a subset of parameters as a local -packing set if
[TABLE]
Note that this set is a -packing in the metric with the average KL-divergence bounded by . The following result is a straightforward consequence of Fano’s inequality:
Lemma 4** (Local packing Fano lower bound).**
For any -packing set of cardinality , we have
[TABLE]
In addition, the Gilbert-Varshamov bound [Gil52, Var57] guarantees the existence of binary vectors such that
[TABLE]
for some fixed tuple of constants . We use this guarantee to design a packing of matrices in the class . For each , fix some to be precisely set later, and define the matrix having identical columns, with entries given by
[TABLE]
Clearly, each of these matrices is a member of the class , and each distinct pair of matrices satisfies the inequality .
Let denote the probability distribution of the observations in the model (2) with underlying matrix . Our observations are independent across entries of the matrix, and so the KL divergence tensorizes to yield
[TABLE]
Let us now examine one term of this sum. We observe samples of entry ; conditioned on the event , we have the distributions
[TABLE]
Consequently, the KL divergence conditioned on is given by
[TABLE]
where we have used to denote the KL divergence between the Bernoulli random variables and .
Note that for , we have
[TABLE]
Here, step follows from the inequality , and step from the assumption . Taking the expectation with respect to , we have
[TABLE]
Summing over yields
Substituting into the Fano’s inequality (7), we have
[TABLE]
Finally, choosing and normalizing by yields the claim.
5.3 Proof of Proposition 1
Recall the definition of in the meta-algorithm, and additionally, define the projection of any matrix , as
[TABLE]
and letting , we have
[TABLE]
where step follows from the non-expansiveness of a projection onto a convex set, and steps and from the triangle inequality.
The first term in (10) is the estimation error of a bivariate isotonic matrix with known permutations. Since the sample used to obtain is independent from the sample used in the projection step, it is equivalent to control the error . As before, the noise matrix satisfies the conditions of Lemma 1. Therefore, applying Lemma 1 in the case with yields the desired bound of order .
It remains to bound the second term of (10), the approximation error of the permutation estimates. Note that the approximation error can be split into two components: one along the rows of the matrix, and the other along the columns. More explicitly, we have
[TABLE]
Recall that we assumed without loss of generality that the true permutations are identity permutations, so this completes the proof of Proposition 1. The proof readily extends to the general case by precomposing and with and respectively.
5.4 Proof of Theorem 2
Recall that according to Proposition 1, it suffices to bound the approximation error of our permutation estimate . To ease the notation, we use the shorthand
[TABLE]
and for each block in Algorithm 2 where , we use the shorthand
[TABLE]
throughout the proof. Applying Lemma 2 with and then with for each , we obtain that
[TABLE]
Note that , so a union bound over all events in inequalities (11a) and (11b) yields that , where we define the event
[TABLE]
We now condition on event . Applying the triangle inequality yields that if
[TABLE]
then we have
[TABLE]
It follows that since has nondecreasing columns. Thus, by the choice of thresholds and in inequalities (6a) and (6b), we have guaranteed that every edge in the graph is consistent with the underlying permutation , so a topological sort exists on event .
Conversely, if we have
[TABLE]
then the triangle inequality implies that
[TABLE]
Hence the edge is present in the graph , so the topological sort satisfies the relation . Claim that this allows us to obtain the following bounds on event :
[TABLE]
We now prove inequality (12b). The proof of inequality (12a) follows in the same fashion. We split the proof into two cases.
Case 1.
First, suppose that . Applying Lemma 3 with , and , we see that for all ,
[TABLE]
Case 2.
Otherwise, we have . It then follows that
[TABLE]
where we have used the fact that .
Next, we consider concentration of the column sums of . Applying Lemma 2 again with , we obtain that
[TABLE]
for all with probability at least . We carry out the remainder of the proof conditioned on the event of probability at least that inequalities (12a), (12b) and (13) hold.
Having stated the necessary bounds, we now split the remainder of the proof into two parts for convenience. In order to do so, we first split the set into two disjoint sets of blocks, depending on whether a block comes from an originally large block (of size larger than as in Step 3 of Subroutine 1) or from an aggregation of small blocks. More formally, define the sets
[TABLE]
For a set of blocks , define the shorthand for convenience. We begin by focusing on the blocks .
5.4.1 Error on columns indexed by
Recall that when the columns of the matrix are ordered according to , the blocks in are contiguous and thus have an intrinsic ordering. We index the blocks according to this ordering as where . Now define the disjoint sets
[TABLE]
Let for each .
Recall that each block in remains unchanged after aggregation, and that the threshold we used to block the columns is \tau=16(\zeta+1)\big{(}\sqrt{\frac{n_{1}^{2}n_{2}}{N}\log(n_{1}n_{2})}+2\frac{n_{1}n_{2}}{N}\log(n_{1}n_{2})\big{)}. Hence, applying the concentration bound (13) together with the definition of blocks in Step 2 of Subroutine 1 yields
[TABLE]
where we again used the argument leading to claim (12b) to combine the two terms. Moreover, since the threshold is twice the concentration bound, it holds that under the true ordering , every index in precedes every index in for any . By definition, we have thus ensured that the blocks in do not “mix” with each other.
The rest of the argument hinges on the following lemma, which is proved in Section 5.4.3.
Lemma 5**.**
For , let be a partition of such that each is contiguous and precedes . Let , and . Let be a matrix in with nondecreasing rows and nondecreasing columns. Suppose that
[TABLE]
Additionally, suppose that there are positive reals , and a permutation such that for any , we have , and for each . Then it holds that
[TABLE]
We apply the lemma as follows. For , let the matrix be the submatrix of restricted to the columns indexed by the indices in . The matrix has nondecreasing rows and columns by assumption. We have shown that the blocks in do not mix with each other, so they are contiguous and correctly ordered in . Moreover, the inequality assumptions of the lemma correspond to (15), (12a) and (12b) respectively, with the substitutions
[TABLE]
and setting to be the blocks in . Therefore, applying Lemma 5 yields
[TABLE]
where step follows from the Cauchy-Schwarz inequality, and step follows from the fact that so that . Substituting for and normalizing by yields
[TABLE]
This proves the required result for the set of blocks . Summing over then yields a bound of twice the size for columns of the matrix indexed by .
5.4.2 Error on columns indexed by
Next we bound the approximation error of each row of the matrix with column indices restricted to the union of all small blocks. In the easy case where contains a single block of size less than , we have
[TABLE]
where step follows from the Hölder’s inequality and the fact that , step from the monotonicity of the columns of , and step from equation (12a).
Now we aim to prove a bound of the same order for the general case. Critical to our analysis is the following lemma:
Lemma 6**.**
For a vector , define its variation as . Then we have
[TABLE]
See Section 5.4.4 for the proof of this claim.
For each , define to be the restriction of the -th row difference to the union of blocks . For each block , denote the restriction of to by . Lemma 6 applied with yields
[TABLE]
We now analyze the quantities in inequality (17). By the aggregation step of Subroutine 1, we have , where . Additionally, the bounds (12a) and (12b) imply that
[TABLE]
Moreover, to bound the quantity , we proceed as in the proof for the large blocks in . Recall that if we permute the columns by according to the column sums, then the blocks in have an intrinsic ordering, even after adjacent small blocks are aggregated. Let us index the blocks in by according to this ordering, where . As before, the odd-indexed (or even-indexed) blocks do not mix with each other under the true ordering , because the threshold used to define the blocks is larger than twice the column sum perturbation. We thus have
[TABLE]
where inequality holds because the odd (or even) blocks do not mix, and inequality holds because has monotone rows in .
Finally, putting together all the pieces, we can substitute for , sum over the indices , and normalize by to obtain
[TABLE]
and so the error on columns indexed by the set is bounded as desired.
Combining the bounds (16) and (18), we conclude that
[TABLE]
with probability at least . The same proof works with the roles of and switched and all the matrices transposed, so it holds with the same probability that
[TABLE]
Consequently,
[TABLE]
with probability at least , where we have used the relation . Applying Proposition 1 completes the proof.
5.4.3 Proof of Lemma 5
Since has increasing rows, for any with and any , we have
[TABLE]
Choosing , we obtain
[TABLE]
Together with the assumption on , this implies that
[TABLE]
Hence it follows that
[TABLE]
According to the assumptions, we have
and for any ; 2. 2.
and for any ; 3. 3.
and for any .
Consequently, the following bounds hold:
; 2. 2.
; 3. 3.
.
Combining these inequalities yields the claim.
5.4.4 Proof of Lemma 6
Let and . Since the quantities in the inequality remain the same if we replace by , we assume without loss of generality that . If , then . If , then and . Hence in any case we have .
6 Discussion
While the current paper narrows the statistical-computational gap for estimation in permutation-based models with monotonicity constraints, several intriguing questions remain:
- •
Can Algorithm 2 be recursed so as to improve the rate of estimation, until we eventually achieve the statistically optimal rate (up to lower-order terms) in polynomial time?
- •
If not, does there exist a statistical-computational gap in this problem, and if so, what is the fastest rate achievable by computationally efficient estimators?
- •
Can the techniques from here be used to narrow statistical-computational gaps in other permutation-based models [SBW16b, FMR16, PWC17]?
As a partial answer to the first question, it can be shown that when our two-dimensional sorting algorithm is recursed in the natural way and applied to the noisy sorting subclass of the SST model, it yields another minimax optimal estimator for noisy sorting, similar to the multistage algorithm of Mao et al. [MWR17]. However, showing that this same guarantee is preserved for the larger class of SST matrices seems out of the reach of techniques introduced in this paper. In fact, we conjecture that any algorithm that only exploits partial row and column sums cannot achieve a rate faster than for the SST class.
It is also worth noting that the model (1) allowed us to perform multiple sample-splitting steps while preserving the independence across observations. While our proofs also hold for the observation model where we have exactly independent samples per entry of the matrix, handling the weak dependence of the sampling model with one observation per entry is an interesting technical challenge that may also involve its own statistical-computational tradeoffs [Mon15].
Acknowledgments
CM thanks Philippe Rigollet for helpful discussions. The work of CM was supported in part by grants NSF CAREER DMS-1541099, NSF DMS-1541100 and ONR N00014-16-S-BA10, and the work of AP and MJW was supported in part by grants NSF-DMS-1612948 and DOD ONR-N00014. We thank Jingyan Wang for pointing out an error in an earlier version of the paper.
Appendix A Proof of Lemma 1
The proof parallels that of Shah et al. [SBGW17, Theorem 5(a)], so we only emphasize the differences and sketch the remaining argument. We may assume that , since otherwise the bound is trivial.
We first employ a truncation argument. Consider the event
[TABLE]
If the universal constant is chosen to be sufficiently large, then it follows from the sub-Gaussianity of and a union bound over all index pairs that . Now define the truncation operator
[TABLE]
With the choice , define the random variables for each pair of indices . Consider the model where we observe instead of . Then the new model and the original one are coupled so that they coincide on the event . Therefore, it suffices to prove a high probability bound assuming that the noise is given by .
Let us define and . We claim that for any , the following relations hold:
; 2. 2.
are independent, centered and -sub-Gaussian; 3. 3.
; 4. 4.
.
Taking these claims as given for the moment, we turn to the main argument assuming that our observations take the form .
For any permutations , let . We claim that for any fixed pair such that , we have
[TABLE]
Treating claim (20) as true for the moment, we see that since the least squares estimator is equal to for some pair , a union bound over yields
[TABLE]
which completes the proof. Thus, to prove our result, it suffices to prove claim (20).
Let . The condition yields the basic inequality
[TABLE]
Since , we have by claim 1. If it holds that , then the proof is immediate. Thus, we may assume the opposite, from which it follows that
[TABLE]
Consider the set of matrices
[TABLE]
Additionally, for every , define the random variable
[TABLE]
For every , define the event
[TABLE]
For , either we already have , or we have . In the latter case, on the complement of , we must have . Combining this with inequality (21) then yields . It thus remains to bound the probability .
Using the star-shaped nature of the set , a rescaling argument yields
[TABLE]
The following lemma bounds the tail behavior of the random variable , and its proof is postponed to Section A.2.
Lemma 7**.**
For any and , we have
[TABLE]
Taking the lemma as given and setting and , we see that for any , we have
[TABLE]
In particular, for , on the complement of , we have
[TABLE]
which completes the proof. Note that the original proof sacrificed a logarithmic factor in proving the equivalent of equation (22), and this is why we recover the same logarithmic factors as in the bounded case in spite of the sub-Gaussian truncation argument.
In the setting where we know that , the same proof clearly works, except that we do not even need to take a union bound over as the columns and rows are ordered.
A.1 Proof of claims 1–4
We assume throughout that the constant is chosen to be sufficiently large. Claim 1 follows as a result of the following argument; we have
[TABLE]
By definition, the random variables are independent and zero-mean, and applying Lemma 8 (see Appendix C) yields that they are also sub-Gaussian with the claimed variance parameter, thus yielding claim 2. The triangle inequality together with the definition of then yields claim 3.
Finally, since , we have
[TABLE]
yielding claim 4.
A.2 Proof of Lemma 7
The chaining argument from the proof of Shah et al. [SBGW17, Lemma 10] can applied to show that
[TABLE]
as is -sub-Gaussian by claim 2. Note that although we are considering a set of rectangular matrices instead of square matrices as in [SBGW17], we can augment each matrix by zeros to obtain an matrix, and so can be viewed as a subset of its counterpart consisting of matrices. Hence the entropy bound depending on can be employed so that the chaining argument indeed goes through.
In order to obtain the deviation bound, we apply Lemma 11 of Shah et al. [SBGW17] (i.e., Theorem 1.1(c) of Klein and Rio [KR05]) with , , and . Claim 3 guarantees that is uniformly bounded by . We also have by claim 4 for . Therefore, we conclude that
[TABLE]
Combining the expectation and the deviation bounds completes the proof.
Appendix B Poissonization reduction
In this section, we show that Poissonization only affects the rates of estimation up to a constant factor. Note that we may assume that , since otherwise, all the bounds in the theorems hold trivially.
Let us first show that an estimator designed for a Poisson number of samples may be employed for estimation with a fixed number of samples. Assume that is fixed, and we have an estimator , which is designed under observations . Now, given exactly observations from the model (1), choose an integer , and output the estimator
[TABLE]
Recalling the assumption , we have
[TABLE]
Thus, the error of the estimator , which always uses at most samples, is bounded by with probability greater than , and moreover, we have
[TABLE]
We now show the reverse, that an estimator designed using exactly samples may be used to estimate under a Poissonized observation model. Given samples, define the estimator
[TABLE]
where in the former case, is computed by discarding samples at random.
Again, using the fact that yields
[TABLE]
and so once again, the error of the estimator is bounded by with probability greater than . A similar guarantee also holds in expectation.
Appendix C Truncation preserves sub-Gaussianity
In this appendix, we show that truncating a sub-Gaussian random variable preserves its sub-Gaussianity to within a constant factor.
Lemma 8**.**
Let be a (not necessarily centered) -sub-Gaussian random variable, and for some choice , let denote its truncation according to equation (19). Then is -sub-Gaussian.
Proof.
The proof follows a symmetrization argument. Let denote an i.i.d. copy of , and use the shorthand and . Let denote a Rademacher random variable that is independent of everything else. Then and are i.i.d., and . Hence we have
[TABLE]
Using the Taylor expansion of , we have
[TABLE]
since only the even moments remain. Finally, since the map is -Lipschitz, we have , and combining this with the fact that has odd moments equal to zero yields
[TABLE]
where the last step follows since the random variable is zero-mean and -sub-Gaussian. ∎
The reference list from the paper itself. Each links out to its DOI / PubMed record.
- 1[AAAK 17] Arpit Agarwal, Shivani Agarwal, Sepehr Assadi, and Sanjeev Khanna. Learning with limited rounds of adaptivity: Coin tossing, multi-armed bandits, and ranking from pairwise comparisons. In Conference on Learning Theory , pages 39–75, 2017.
- 2[BDPR 84] Gordon Bril, Richard Dykstra, Carolyn Pillers, and Tim Robertson. Algorithm AS 206: isotonic regression in two independent variables. Journal of the Royal Statistical Society. Series C (Applied Statistics) , 33(3):352–357, 1984.
- 3[BLM 13] Stéphane Boucheron, Gábor Lugosi, and Pascal Massart. Concentration inequalities: A nonasymptotic theory of independence . Oxford university press, 2013.
- 4[BM 08] Mark Braverman and Elchanan Mossel. Noisy sorting without resampling. In Proceedings of the Nineteenth Annual ACM-SIAM Symposium on Discrete Algorithms , pages 268–276. ACM, New York, 2008.
- 5[BT 52] Ralph A. Bradley and Milton E. Terry. Rank analysis of incomplete block designs. I. The method of paired comparisons. Biometrika , 39:324–345, 1952.
- 6[BW 97] T. Parker Ballinger and Nathaniel T. Wilcox. Decisions, error and heterogeneity. The Economic Journal , 107(443):1090–1105, 1997.
- 7[CD 16] Olivier Collier and Arnak S. Dalalyan. Minimax rates in permutation estimation for feature matching. Journal of Machine Learning Research , 17(6):1–31, 2016.
- 8[CGS 18] Sabyasachi Chatterjee, Adityanand Guntuboyina, and Bodhisattva Sen. On matrix estimation under monotonicity constraints. Bernoulli , (2):1072–1100, 05 2018.