ADMM for Multiaffine Constrained Optimization
Wenbo Gao, Donald Goldfarb, and Frank E. Curtis

TL;DR
This paper extends ADMM to solve multiaffine constrained problems with convergence guarantees under weak assumptions, applicable to nonconvex, nonsmooth, and multi-block scenarios, with practical examples.
Contribution
It provides the first convergence analysis of ADMM for multiaffine constraints with weak assumptions, including nonconvex and nonsmooth problems, and demonstrates broad applicability.
Findings
ADMM converges to stationary points under certain conditions.
Applicable to nonconvex, nonsmooth, multi-block problems.
Subproblems have closed-form solutions in examples.
Abstract
We expand the scope of the alternating direction method of multipliers (ADMM). Specifically, we show that ADMM, when employed to solve problems with multiaffine constraints that satisfy certain verifiable assumptions, converges to the set of constrained stationary points if the penalty parameter in the augmented Lagrangian is sufficiently large. When the Kurdyka-\L{}ojasiewicz (K-\L{}) property holds, this is strengthened to convergence to a single constrained stationary point. Our analysis applies under assumptions that we have endeavored to make as weak as possible. It applies to problems that involve nonconvex and/or nonsmooth objective terms, in addition to the multiaffine constraints that can involve multiple (three or more) blocks of variables. To illustrate the applicability of our results, we describe examples including nonnegative matrix factorization, sparse learning, risk…
Click any figure to enlarge with its caption.
 Figure 1
 Figure 2
 Figure 3
 Figure 4
 Figure 5
 Figure 6
 Figure 7
 Figure 8
 Figure 9
 Figure 10
 Figure 11
 Figure 12
 Figure 13
 Figure 14
 Figure 15
 Figure 16
 Figure 17
 Figure 18
 Figure 19
 Figure 20
 Figure 21
 Figure 22
 Figure 23
 Figure 24
 Figure 25
 Figure 26
 Figure 27
 Figure 28
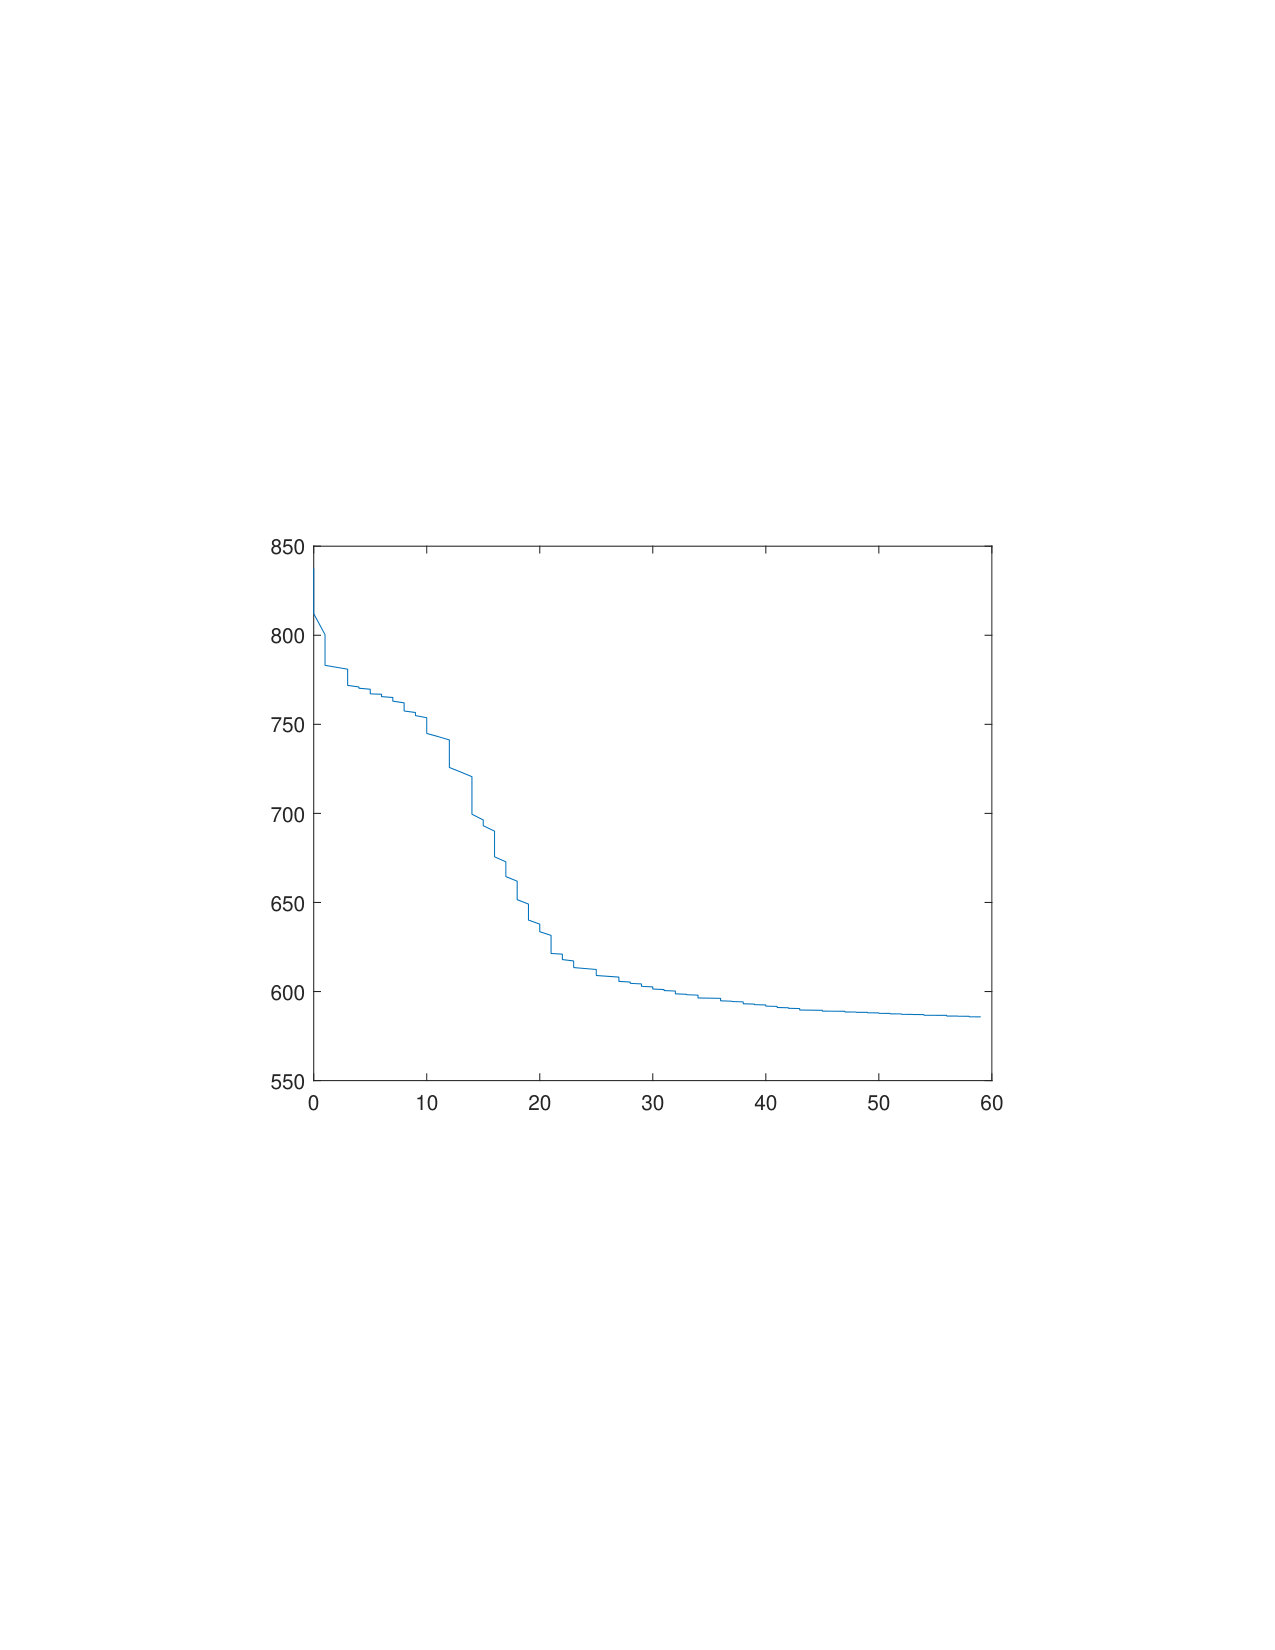 Figure 29
 Figure 30
 Figure 31
 Figure 32
 Figure 33
 Figure 34
 Figure 35
 Figure 36
 Figure 37
 Figure 38
 Figure 39
 Figure 40
| Assumption 1 | |
|---|---|
| -block operator | |
| Total objective function | coercive on feasible region |
| splits as | |
| -block objective function | splits as |
| is proper, convex, and lower semicontinuous | |
| is strongly convex, and either • , or • | |
| is Lipschitz differentiable | |
| -operator | is injective |
| Assumption 2 | |
|---|---|
| -block function | splits into |
| is Lipschitz differentiable | |
| is proper and lower semicontinuous, and continuous on | |
| , for | One of the following cases holds: Case 1: is independent of , and satisfies a strengthened convexity condition (see 5.13). Case 2: is either convex or Lipschitz differentiable. Viewing as a system of constraints, there exists an constraint in the system, with index , such that in the -th constraint, we have for an injective linear map and a multiaffine map . |
| One of the following cases holds: Case 1: satisfies a strengthened convexity condition (5.13). Case 2: , so is a strongly convex function of and . Case 3: Viewing as a system of constraints, there exists an index such that for an injective linear map and multiaffine map . |
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
Taxonomy
TopicsSparse and Compressive Sensing Techniques · Blind Source Separation Techniques · Structural Health Monitoring Techniques
ADMM for Multiaffine Constrained Optimization
Wenbo Gao*†, Donald Goldfarb†, and Frank E. Curtis‡*
[email protected], [email protected], [email protected]
(Date: Oct 04, 2019.)
Abstract.
We expand the scope of the alternating direction method of multipliers (ADMM). Specifically, we show that ADMM, when employed to solve problems with multiaffine constraints that satisfy certain verifiable assumptions, converges to the set of constrained stationary points if the penalty parameter in the augmented Lagrangian is sufficiently large. When the Kurdyka-Łojasiewicz (K-Ł) property holds, this is strengthened to convergence to a single constrained stationary point. Our analysis applies under assumptions that we have endeavored to make as weak as possible. It applies to problems that involve nonconvex and/or nonsmooth objective terms, in addition to the multiaffine constraints that can involve multiple (three or more) blocks of variables. To illustrate the applicability of our results, we describe examples including nonnegative matrix factorization, sparse learning, risk parity portfolio selection, nonconvex formulations of convex problems, and neural network training. In each case, our ADMM approach encounters only subproblems that have closed-form solutions.
2010 Mathematics Subject Classification:
90C26, 90C30
† Department of Industrial Engineering and Operations Research, Columbia University. Research of this author was supported in part by NSF Grant CCF-1527809.
‡ Department of Industrial and Systems Engineering, Lehigh University. Research of this author was supported in part by DOE Grant DE-SC0010615 and NSF Grant CCF-1618717.
1. Introduction
The alternating direction method of multipliers (ADMM) is an iterative method which, in its original form, solves linearly-constrained separable optimization problems with the following structure:
[TABLE]
The augmented Lagrangian of the problem , for some penalty parameter , is defined to be
[TABLE]
In iteration , with the iterate , ADMM takes the following steps:
- (1)
Minimize with respect to to obtain . 2. (2)
Minimize with respect to to obtain . 3. (3)
Set .
ADMM was first proposed [20, 21] for solving variational problems, and was subsequently applied to convex optimization problems with two blocks as in . Several techniques can be used to analyze this case, including an operator-splitting approach [16, 41]. The survey articles [17, 6] provide convergence proofs from several viewpoints, and discuss numerous applications of ADMM. More recently, there has been considerable interest in extending ADMM convergence guarantees when solving problems with multiple blocks and nonconvex objective functions. ADMM directly extends to the problem
[TABLE]
by minimizing with respect to successively. The multiblock problem turns out to be significantly different from the classical 2-block problem, even when the objective function is convex; for example, [9] exhibits an example with blocks and for which ADMM diverges for any value of . Under certain conditions, the unmodified 3-block ADMM does converge. In [39], it is shown that if is strongly convex with condition number (among other assumptions), then 3-block ADMM is globally convergent. If are all strongly convex, and is sufficiently small, then [24] shows that multiblock ADMM is convergent. Other works along these lines include [37, 38, 34].
In the absence of strong convexity, modified versions of ADMM have been proposed that can accommodate multiple blocks. In [13] a new type of 3-operator splitting is introduced that yields a convergent 3-block ADMM (see also [46] for a proof that a ‘lifting-free’ 3-operator extension of Douglas-Rachford splitting does not exist). Convergence guarantees for multiblock ADMM can also be achieved through variants such as proximal ADMM, majorized ADMM, linearized ADMM [49, 36, 14, 10, 40, 5], and proximal Jacobi ADMM [14, 55, 52].
ADMM has also been extended to problems with nonconvex objective functions. In [25], it is proved that ADMM converges when the problem is either a nonconvex consensus or sharing problem, and [57] proves convergence under more general conditions on and . Proximal ADMM schemes for nonconvex, nonsmooth problems are considered in [33, 60, 28, 5]. More references on nonconvex ADMM, and comparisons of the assumptions used, can be found in [57].
In all of the work mentioned above, the system of constraints is assumed to be linear. Consequently, when all variables other than have fixed values, becomes an affine function of . However, this holds for more general constraints in the much larger class of multiaffine maps (see Section 2). Thus, it seems reasonable to expect that ADMM would behave similarly when the constraints are permitted to be multiaffine. To be precise, consider a more general problem than of the form
[TABLE]
The augmented Lagrangian for is
[TABLE]
and ADMM for solving this problem is specified in Algorithm 1.
While many problems can be modeled with multiaffine constraints, existing work on ADMM for solving multiaffine constrained problems appears to be limited. Boyd et al. [6] propose solving the nonnegative matrix factorization problem formulated as a problem with biaffine constraints, i.e.,
[TABLE]
by applying ADMM with alternating minimization on the blocks and . The convergence of ADMM employed to solve the (NMF1) problem appears to have been an open question until a proof was given in [23]111[23] shows that every limit point of ADMM for the problem (NMF) is a constrained stationary point, but does not show that such limit points necessarily exist.. A method derived from ADMM has also been proposed for optimizing a biaffine model for training deep neural networks [53]. For general nonlinear constraints, a framework for “monitored” Lagrangian-based multiplier methods was studied in [4].
In this paper, we establish the convergence of ADMM for a broad class of problems with multiaffine constraints. Our assumptions are similar to those used in [57] for nonconvex ADMM; in particular, we do not make any assumption about the iterates generated by the algorithm. Hence, these results extend the applicability of ADMM to a larger class of problems which naturally have multiaffine constraints. Moreover, we prove several results about ADMM in Section 6 that hold in even more generality, and thus may be useful for analyzing ADMM beyond the setting considered here.
1.1. Organization of this paper
In Section 2, we define multilinear and multiaffine maps, and specify the precise structure of the problems that we consider. In Section 3, we provide several examples of problems that can be formulated with multiaffine constraints. In Section 4, we state our assumptions and main results (i.e., Theorems 4.1, 4.3 and 4.5). In Section 5, we present a collection of necessary technical material. In Section 6, we prove several results about ADMM that hold under weak conditions on the objective function and constraints. Finally, in Section 7, we complete the proof of our main convergence theorems (Theorems 4.1, 4.3 and 4.5), by applying the general techniques developed in Section 6. Appendix A contains proofs of technical lemmas. Appendix B presents an alternative biaffine formulation for deep neural network training. Appendix C organizes the major assumptions in tabular form. Appendix D presents additional formulations of problems where all ADMM subproblems have closed-form solutions. Appendix E presents several numerical experiments.
1.2. Notation and Definitions
We consider only finite-dimensional real vector spaces. The symbols denote finite-dimensional Hilbert spaces, equipped with inner products . By default, we use the standard inner product on and the trace inner product on the matrix space. Unless otherwise specified, the norm is always the induced norm of the inner product. When is a matrix or linear map, denotes the operator norm, and denotes the nuclear norm (the sum of the singular values of ). Fixed bases are assumed, so we freely use various properties of a linear map that depend on its representation (such as ), and view as a matrix as required.
For , the effective domain is the set . The image of a function is denoted by . Similarly, when is a linear map represented by a matrix, is the column space of . We use to denote the null space of . The orthogonal complement of a linear subspace is denoted .
To distinguish the derivatives of smooth (i.e., continuously differentiable) functions from subgradients, we use the notation for partial differentiation with respect to , and reserve the symbol for the set of general subgradients (Section 5.1); hence, the use of serves as a reminder that is assumed to be smooth. A function is Lipschitz differentiable if it is differentiable and its gradient is Lipschitz continuous.
When is a tuple of variables , we write for . Similarly, and represent and respectively.
We use the term constrained stationary point for a point satisfying necessary first-order optimality conditions; this is a generalization of the Karush-Kuhn-Tucker (KKT) necessary conditions to nonsmooth problems. For the problem , where is smooth and possesses general subgradients, is a constrained stationary point if and there exists with .
2. Multiaffine Constrained Problems
The central objects of this paper are multilinear and multiaffine maps, which generalize linear and affine maps.
Definition 2.1**.**
A map is multilinear if, for all and all points , the map given by
[TABLE]
is linear. Similarly, is multiaffine if the map is affine for all and all points of . In particular, when , we say that is bilinear/biaffine.
We consider the convergence of ADMM for problems of the form:
[TABLE]
where , , ,
[TABLE]
with and being multiaffine maps and and being linear maps. The augmented Lagrangian , with penalty parameter , is given by
[TABLE]
where are Lagrange multipliers.
We prove that Algorithm 1 converges to a constrained stationary point under certain assumptions on , and , which are described in Section 4. Moreover, since the constraints are nonlinear, there is a question of constraint qualifications, which we address in Lemma 5.4.
We adopt the following notation in the context of ADMM. The variables in the -th iteration are denoted (with for the -th variable in each component). When analyzing a single iteration, the index is omitted, and we write and . Similarly, we write and will refer to and for values within a single iteration.
3. Examples of Applications
In this section, we describe several problems with multiaffine constraints, and show how they can be formulated and solved by ADMM. Many important applications of ADMM involve introducing auxiliary variables so that all subproblems have closed-form solutions; we describe several such reformulations in appendix D that have this property.
3.1. Representation Learning
Given a matrix of data, it is often desirable to represent in the form , where is a bilinear map and the matrices have some desirable properties. Two important applications follow:
- (1)
Nonnegative matrix factorization (NMF) [31, 32] expresses as a product of nonnegative matrices . 2. (2)
Inexact dictionary learning (DL) [43] expresses every element of as a sparse combination of atoms from a dictionary . It is typically formulated as
[TABLE]
where is the indicator function for the set of matrices whose columns have unit norm, and here is the entrywise 1-norm . The parameter is an input that sets the balance between trying to recover with high fidelity versus finding with high sparsity.
Problems of this type can be modeled with bilinear constraints. As already mentioned in Section 1, [6, 23] propose the bilinear formulation (NMF1) for nonnegative matrix factorization. The inexact dictionary learning problem can similarly be formulated as:
[TABLE]
Other variants of dictionary learning such as convolutional dictionary learning (CDL), that cannot readily be handled by the method in [43], have a biaffine formulation which is nearly identical to (DL1), and can be solved using ADMM. For more information on dictionary learning, see [18, 50, 51, 43, 56].
3.2. Non-Convex Reformulations of Convex Problems
Recently, various low-rank matrix and tensor recovery problems have been shown to be efficiently solvable by applying first-order methods to nonconvex reformulations of them. For example, the convex Robust Principal Component Analysis (RPCA) [26, 8] problem
[TABLE]
can be reformulated as the biaffine problem
[TABLE]
as long as , where is an optimal solution of (RPCA1). See [15] for a proof of this, and applications of the factorization to other problems. This is also related to the Burer-Monteiro approach [7] for semidefinite programming. We remark that (RPCA2) does not satisfy all the assumptions needed for the convergence of ADMM (see 1.3 and Section 4.2), so slack variables must be added.
3.3. Max-Cut
Given a graph and edge weights , the (weighted) maximum cut problem is to find a subset so that is maximized. This problem is well-known to be NP-hard [30]. An approximation algorithm using semidefinite programming can be shown to achieve an approximation ratio of roughly [22]. Applying the Burer-Monteiro approach [7] to the max-cut semidefinite program [22] with a rank-one constraint, and introducing a slack variable (see 1.2), we obtain the problem
[TABLE]
It is easy to verify that all subproblems have very simple closed-form solutions.
3.4. Risk Parity Portfolio Selection
Given assets indexed by , the goal of risk parity portfolio selection is to construct a portfolio weighting in which every asset contributes an equal amount of risk. This can be formulated with quadratic constraints; see [3] for details. The feasibility problem in [3] is
[TABLE]
where is the (positive semidefinite) covariance matrix of the asset returns, and and contain lower and upper bounds on the weights, respectively. The authors in [3] introduce a variable and solve (RP) using ADMM by replacing the quadratic risk-parity constraint by a fourth-order penalty function . To rewrite this problem with a bilinear constraint, let denote the Hadamard product and let be the matrix , where is the all-ones vector of length . Let be the set of permissible portfolio weights , and let be its indicator function. Then we obtain the problem
[TABLE]
where we have introduced a slack variable (see 1.2).
3.5. Training Neural Networks
An alternating minimization approach is proposed in [53] for training deep neural networks. By decoupling the linear and nonlinear elements of the network, the backpropagation required to compute the gradient of the network is replaced by a series of subproblems which are easy to solve and readily parallelized. For a network with layers, let be the matrix of edge weights for , and let be the output of the -th layer for . Deep neural networks are defined by the structure , where is an activation function, which is often taken to be the rectified linear unit (ReLU) . The splitting used in [53] introduces new variables for so that the network layers are no longer directly connected, but are instead coupled through the relations and .
Let be an error function, and a regularization function on the weights. Given a matrix of labeled training data , the learning problem is
[TABLE]
The algorithm proposed in [53] does not include any regularization , and replaces both sets of constraints by quadratic penalty terms in the objective, while maintaining Lagrange multipliers only for the final constraint . However, since all of the equations are biaffine, we can include them in a biaffine formulation of the problem:
[TABLE]
To adhere to our convergence theory, it would be necessary to apply smoothing (such as Nesterov’s technique [44]) when is nonsmooth, as is the ReLU. Alternatively, the ReLU can be replaced by an approximation using nonnegativity constraints (see Appendix B). In practice [53, §7], using the ReLU directly yields simple closed-form solutions, and appears to perform well experimentally. However, no proof of the convergence of the algorithm in [53] is provided.
4. Main Results
In this section, we state our assumptions and main results. We will show that ADMM (Algorithm 2) applied to solve a multiaffine constrained problem of the form (refer to page 2) produces a bounded sequence , and that every limit point is a constrained stationary point. While there are fairly general conditions under which satisfies first-order optimality conditions (see Assumption 1 and the corresponding discussion in Section 4.2 of tightness), the situation with is more complicated because of the many possible structures of multiaffine maps. Accordingly, we divide the convergence proof into two results. Under one broad set of assumptions, we prove that limit points exist, are feasible, and that is a blockwise constrained stationary point for the problem with fixed at (Theorem 4.1). Then, we present a set of easily-verifiable conditions under which is also a constrained stationary point (Theorem 4.3). If the augmented Lagrangian has additional geometric properties (namely, the Kurdyka-Łojasiewicz property (Section 5.5)), then converges to a single limit point (Theorem 4.5).
4.1. Assumptions and Main Results
We consider two sets of assumption for our analysis. We provide intuition and further discussion of them in Section 4.2. (See Section 5 for definitions related to convexity and differentiability.)
Assumption 1**.**
Solving problem (refer to page 2), the following hold.
A 1.1**.**
For sufficiently large , every ADMM subproblem attains its optimal value.
A 1.2**.**
.
A 1.3**.**
The following statements regarding the objective function and hold:
- (1)
* is coercive on the feasible region .* 2. (2)
* can be written in the form*
[TABLE]
where
- (a)
* is proper, convex, and lower semicontinuous.* 2. (b)
* represents either or and is -strongly convex. That is, either is a strongly convex function of or is a strongly convex function of .* 3. (c)
* is -Lipschitz differentiable.* 3. (3)
* is injective.*
While Assumption 1 may appear to be complicated, it is no stronger than the conditions used in analyzing nonconvex, linearly-constrained ADMM. A detailed comparison is given in Section 4.2.
Under Assumption 1, Algorithm 2 produces a sequence which has limit points, and every limit point is feasible with a constrained stationary point for problem with fixed to .
Theorem 4.1**.**
Suppose that Assumption 1 holds. For sufficiently large , the sequence produced by ADMM is bounded, and therefore has limit points. Every limit point satisfies . There exists a sequence such that , and thus
[TABLE]
where is the linear map and is its adjoint. That is, is a constrained stationary point for the problem
[TABLE]
Remark 4.2**.**
Let 222See Section 5.4 for the definition of and . and . One can check that it suffices to choose so that
[TABLE]
Note that Assumption 1 makes very few assumptions about and the map as a function of , other than that is multiaffine. In Section 6, we develop general techniques for proving that is a constrained stationary point. We now present an easily checkable set of conditions, that ensure that the requirements for those techniques are satisfied.
Assumption 2**.**
Solving problem , Assumption 1 and the following hold.
A 2.1**.**
The function splits into
[TABLE]
where is -Lipschitz differentiable, the functions , , , and are proper and lower semicontinuous, and each is continuous on .
A 2.2**.**
For each ,333Note that we have deliberately excluded . 2.2 is not required to hold for . at least one of the following two conditions444That is, either (1a) and (1b) hold, or (2a) and (2b) hold. holds:
-
(1)
-
(a)
* is independent of .* 2. (b)
* satisfies a strengthened convexity condition (5.13).* 2. (2)
- (a)
*Viewing as a system of constraints 555As an illustrative example, a problem may be formulated with constraints , where are injective linear maps. The notation denotes the concatenation of these equations, which can also be seen naturally as a system of four constraints. In this case, the indices , and 2.2(2a) is satisfied by the second constraint for the variables (i.e. and ), and by the fourth constraint for . * , there exists an index such that in the -th constraint,
[TABLE]
for an injective linear map and a multiaffine map . In other words, the only term in that involves is an injective linear map . 2. (b)
* is either convex or -Lipschitz differentiable.*
A 2.3**.**
At least one of the following holds for :
- (1)
* satisfies a strengthened convexity condition (5.13).* 2. (2)
, so is a strongly convex function of and . 3. (3)
Viewing as a system of constraints, there exists an index such that for an injective linear map and multiaffine map .
With these additional assumptions on and , we have that every limit point is a constrained stationary point of problem .
Theorem 4.3**.**
Suppose that Assumption 2 holds (and hence, Assumption 1 and Theorem 4.1). Then for sufficiently large , there exists a sequence with , and thus every limit point is a constrained stationary point of problem . Thus, in addition to (4.1), satisfies, for each ,
[TABLE]
where is the -linear term of evaluated at (see 5.6) and is its adjoint. That is, for each , is a constrained stationary point for the problem
[TABLE]
Remark 4.4**.**
One can check that it suffices to choose so that, in addition to (4.2), we have , where the maximum is taken over all for which 2.2(2) holds, and
[TABLE]
It is well-known that when the augmented Lagrangian has a geometric property known as the Kurdyka-Łojasiewicz (K-Ł) property (see Section 5.5), which is the case for many optimization problems that occur in practice, then results such as Theorem 4.3 can typically be strengthened because the limit point is unique.
Theorem 4.5**.**
Suppose that is a K-Ł function. Suppose that Assumption 2 holds, and furthermore, that 2.2(2) holds for all 666Note that is included here, unlike in Assumption 2., and 2.3(2) holds. Then for sufficiently large , the sequence produced by ADMM converges to a unique constrained stationary point .
In Section 6, we develop general properties of ADMM that hold without relying on Assumption 1 or Assumption 2. In Section 7, the general results are combined with Assumption 1 and then with Assumption 2 to prove Theorem 4.1 and Theorem 4.3, respectively. Finally, we prove Theorem 4.5 assuming that the augmented Lagrangian is a K-Ł function. The results of Section 6 may also be useful for analyzing ADMM, since the assumptions required are weak.
4.2. Discussion of Assumptions
Assumptions 1 and 2 are admittedly long and somewhat involved. In this section, we will discuss them in detail and explore the extent to which they are tight. Again, we wish to emphasize that despite the additional complexity of multiaffine constraints, the basic content of these assumptions is fundamentally the same as in the linear case. There is also a relation between Assumption 2 and proximal ADMM, by which 2.2(2) can be viewed as introducing a proximal term. This is described in Section 4.2.6.
4.2.1. Assumption 1.1
This assumption is necessary for ADMM (Algorithm 2) to be well-defined. We note that this can fail in surprising ways; for instance, the conditions used in [6] are insufficient to guarantee that the ADMM subproblems have solutions. In [11], an example is constructed which satisfies the conditions in [6], and yet the ADMM subproblem fails to attain its (finite) optimal value.
4.2.2. Assumption 1.2
The condition that plays a crucial role at multiple points in our analysis because , a subset of the final block of variables, has a close relation to the dual variables . It would greatly broaden the scope of ADMM, and simplify modeling, if this condition could be relaxed, but unfortunately this condition is tight for general problems. The following example demonstrates that ADMM is not globally convergent when 1.2 does not hold, even if the objective function is strongly convex.
Theorem 4.6**.**
Consider the problem
[TABLE]
If the initial point is , or if for some , then the ADMM sequence satisfies and .
Even for linearly-constrained, convex, multiblock problems, this condition777For linear constraints , the equivalent statement is that . is close to indispensable. When all the other assumptions except 1.2 are satisfied, ADMM can still diverge if . In fact, [9, Thm 3.1] exhibits a simple 3-block convex problem with objective function on which ADMM diverges for any . This condition is used explicitly [57, 33, 28] and implicitly [25] in other analyses of multiblock (nonconvex) ADMM.
4.2.3. Assumption 1.3
This assumption posits that the entire objective function is coercive on the feasible region, and imposes several conditions on the term for the final block .
Let us first consider the conditions on . The block is composed of three sub-blocks , and decomposes as , where represents either or . There is a distinction between and : namely, may be coupled with the other variables in the nonlinear function , whereas appears only in the linear function which satisfies .
To understand the purpose of this assumption, consider the following ‘abstracted’ assumptions, which are implied by 1.3:
**M1: **
The objective is Lipschitz differentiable with respect to a ‘suitable’ subset of .
**M2: **
ADMM yields sufficient decrease [2] when updating . That is, for some ‘suitable’ subset of and some , we have .
A ‘suitable’ subset of is one whose associated images in the constraints satisfies 1.2. By design, our formulation uses the subset in this role. M1 follows from the fact that are Lipschitz differentiable, and the other conditions in 1.3 are intended to ensure that M2 holds. For instance, the strong convexity assumption in 1.3(2) ensures that M2 holds with respect to regardless of the properties of . The concept of sufficient decrease for descent methods is discussed in [2].
To connect this to the classical linearly-constrained problem, observe that an assumption corresponding to M1 is:
**AL: **
For the problem (see page 1), is Lipschitz differentiable.
Thus, in this sense alone corresponds to the final block in the linearly-constrained case. In the multiaffine setting, we can add a sub-block to the final block , a nonsmooth term to the objective function and a coupled constraint , but only to a limited extent: the interaction of the final block with these elements is limited to the variables .
As with 1.2, it would expand the scope of ADMM if AL, or the corresponding M1, could be relaxed. However, we find that for nonconvex problems, AL cannot readily be relaxed even in the linearly-constrained case, where AL is a standard assumption [57, 33, 28]. Furthermore, an example is given in [57, 36(a)] of a 2-block problem in which the function is nonsmooth, and it is shown that ADMM diverges for any when initialized at a given point. Thus, we suspect that AL/M1 is tight for general problems, though it may be possible to prove convergence for specific structured problems not satisfying M1.
M1 often has implications for modeling. When a constraint fails to have the required structure, one can introduce a new slack variable , and replace that constraint by , and add a term to the objective function to penalize . Because of M1, exact penalty functions such as or the indicator function of fail to satisfy 1.3, so this reformulation is not exact. Based on the above discussion, this may be a limitation inherent to ADMM (as opposed to merely an artifact of existing proof techniques).
We turn now to M2. Note that AL corresponds only to M1, which is why 1.3 is more complicated than AL. There are two main sub-assumptions within 1.3 that ensure M2: that is strongly convex in , and the map is injective. These assumptions are not tight888in the sense that this exact assumption is always necessary and cannot be replaced. since M2 may hold under alternative hypotheses. On the other hand, we are not aware of other assumptions that are as comparably simple and apply with the generality of 1.3; hence we have chosen to adopt the latter. For example, if we restrict the problem structure by assuming that the sub-block is not present, then the condition that is strongly convex can be relaxed to the weaker condition that for . However, even in the absence of 1.3, one might show that specific problems, or classes of structured problems, satisfy the sufficient decrease property, using the general principles of ADMM outlined in Section 6.
Property M2 often arises implicitly when analyzing ADMM. In some cases, such as [25, 47], it follows either from strong convexity of the objective function, or because (and is thus injective). Proximal and majorized versions of ADMM are considered in [28, 33] and add quadratic terms which force M2 to be satisfied. The approach in [57], by contrast, takes a different approach and uses an abstract assumption which relates to ; in our experience, it is difficult to verify this abstract assumption in general, except when other properties such as strong convexity or injectivity of hold.
Finally, we remark on the coercivity of over the feasible region. It is common to assume coercivity (see, e.g. [33, 57]) to ensure that the sequence of iterates is bounded, which implies that limit points exist. In many applications, such as (DL) (Section 3.1), is independent of some of the variables. However, can still be coercive over the feasible region. For the variable-splitting formulation (DL3), this holds because of the constraints and . The objective function is coercive in , , , and , and therefore and cannot diverge on the feasible region.
4.2.4. Assumption 2.1
The key element of this assumption is that may only be coupled by a Lipschitz differentiable function , and the (possibly nonsmooth) terms must be separable. This type of assumption is also used in previous works such as [12, 28, 57].
4.2.5. Assumption 2.2, 2.3
We have grouped 2.2, 2.3 together here because their motivation is the same. Our goal is to obtain conditions under which the convergence of the function differences implies that (and likewise for ). This can be viewed as a much weaker analogue of the sufficient decrease property M2. In 2.2 and 2.3, we have presented several alternatives under which this holds. Under 2.2(1) and 2.3(1), the strengthened convexity condition (5.13), it is straightforward to show that
[TABLE]
(and likewise for ), where is the [math]-forcing function arising from strengthened convexity. For 2.2(2) and 2.3(2), the inequality (4.4) holds with , which is the sufficient decrease condition of [2]. Note that having is important for proving convergence in the K-Ł setting, hence the additional hypotheses in Theorem 4.5.
As with 1.3, the assumptions in 2.2 and 2.3 are not tight, because (4.4) may occur under different conditions. We have chosen to use this particular set of assumptions because they are easily verifiable, and fairly general. The general results of Section 6 may be useful in analyzing ADMM for structured problems when the particular conditions of 2.2 are not satisfied.
4.2.6. Connection with proximal ADMM
When modeling, one may always ensure that 2.2(2a) is satisfied for by introducing a new variable and a new constraint . This may appear to be a trivial reformulation of the problem, but it in fact promotes regularity of the ADMM subproblem in the same way as introducing a positive semidefinite proximal term.
Generalizing this trick, let be positive semidefinite, with square root . Consider the constraint . The term of the augmented Lagrangian induced by this constraint is , where is the seminorm induced by . To see this, let be the Lagrange multiplier corresponding to this constraint.
Lemma 4.7**.**
If is initialized to [math], then for all , and . Consequently, the constraint is equivalent to adding a proximal term to the minimization problem for .
Note that proximal ADMM is often preferable to ADMM in practice [35, 19]. ADMM subproblems, which may have no closed-form solution because of the linear mapping in the quadratic penalty term, can often be transformed into a pure proximal mapping with a closed-form solution, by adding a suitable proximal term. Several applications of this approach are developed in [19]. Furthermore, for proximal ADMM, the conditions on in 2.2(2b) can be slightly weakened, by modifying Lemma 6.8 and Corollary 7.3 (see 6.10) to account for the proximal term as in [28].
5. Preliminaries
This section is a collection of definitions, terminology, and technical results which are not specific to ADMM. Proofs of the results in this section can be found in Appendix A, or in the provided references. The reader may wish to proceed directly to Section 6 and return here for details as needed.
5.1. General Subgradients and First-Order Conditions
In order to unify our treatment of first-order conditions, we use the notion of general subgradients, which generalize gradients and subgradients. When is smooth or convex, the set of general subgradients consists of the ordinary gradient or subgradients, respectively. Moreover, some useful functions that are neither smooth nor convex such as the indicator function of certain nonconvex sets possess general subgradients.
Definition 5.1**.**
Let be a closed and convex set. The tangent cone of at the point is the set of directions . The normal cone is the set .
Definition 5.2** ([45], 8.3).**
Let and . A vector is a regular subgradient of at , indicated by , if for all . A vector is a general subgradient, indicated by , if there exist sequences and with and . A vector is a horizon subgradient, indicated by , if there exist sequences , , and with and .
The properties of the general subgradient can be found in [45, §8].
Under the assumption that the objective function is proper and lower semicontinuous, the ADMM subproblems will satisfy a necessary first-order condition.
Lemma 5.3** ([45], 8.15).**
Let be proper and lower semicontinuous over a closed set . Let be a point at which the following constraint qualification is fulfilled: the set of horizon subgradients contains no vector such that . Then, for to be a local optimum of over , it is necessary that .
For our purposes, it suffices to note that when , the constraint qualification is trivially satisfied because . In the context of ADMM, this implies that the solution of each ADMM subproblem satisfies the first-order condition .
Problem has nonlinear constraints, and thus it is not guaranteed a priori that its minimizers satisfy first-order necessary conditions, unless a constraint qualification holds. However, Assumption 1 implies that the constant rank constraint qualification (CRCQ) [27, 42] is satisfied by , and minimizers of will therefore satisfy first-order necessary conditions as long as the objective function is suitably regular. This follows immediately from 1.2 and the following lemma.
Lemma 5.4**.**
Let , where is smooth and is a linear map with . Then for any points , and any vector , if and only if .
5.2. Multiaffine Maps
Every multiaffine map can be expressed as a sum of multilinear maps and a constant. This provides a useful concrete representation.
Lemma 5.5**.**
Let be a multiaffine map. Then, can be written in the form where is a constant, and each is a multilinear map of a subset .
Let be multiaffine, with a particular variable of interest, and the other variables. By Lemma 5.5, grouping the multilinear terms depending on whether is one of the arguments of , we have
[TABLE]
where each .
Definition 5.6**.**
Let have the structure (5.1). Let be the space of functions from . Let be the map999When , is a constant map of . given by . Here, we use the notation for , with taking the values in . Finally, let .
We call the -linear term of (evaluated at ).
To motivate this definition, observe that when is fixed, the map is affine, with the linear component given by and the constant term given by . When analyzing the ADMM subproblem in , a multiaffine constraint becomes the linear constraint .
The definition of multilinearity immediately shows the following.
Lemma 5.7**.**
* is a multilinear map of . For every , is a linear map of , and thus is a linear map of .*
Example**.**
Consider for square matrices . Taking as the variable of focus, and , we have , , , , and thus is the linear map .
Our general results in Section 6 require smooth constraints, which holds for multiaffine maps.
Lemma 5.8**.**
Multiaffine maps are smooth, and in particular, biaffine maps are Lipschitz differentiable.
5.3. Smoothness, Convexity, and Coercivity
Definition 5.9**.**
A function is -Lipschitz differentiable if is differentiable and its gradient is Lipschitz continuous with modulus , i.e. for all .
A function is -strongly convex if is convex, -Lipschitz differentiable, and satisfies for all and . The condition number of is .
Lemma 5.10**.**
If is -Lipschitz differentiable, then .
Lemma 5.11**.**
If is -Lipschitz differentiable, then for any fixed , the function is -Lipschitz differentiable. If is -strongly convex, then is -strongly convex.
Definition 5.12**.**
A function is said to be coercive on the set if for every sequence with , then .
Definition 5.13**.**
A function is 0-forcing if , and any sequence has only if . A function is said to satisfy a strengthened convexity condition if there exists a [math]-forcing function such that for any , and any , satisfies
[TABLE]
Remark 5.14**.**
The strengthened convexity condition is stronger than convexity, but weaker than strong convexity. An example is given by higher-order polynomials of degree composed with the Euclidean norm, which are not strongly convex for . An example is the function , which is not strongly convex but does satisfy the strengthened convexity condition. This function appears in the context of the cubic-regularized Newton method [59]. We note that ADMM can be applied to solve the nonconvex cubic-regularized Newton subproblem
[TABLE]
by performing the splitting for and .
Since we will subsequently show (Theorem 4.1) that the sequence of ADMM iterates is bounded, the strengthened convexity condition can be relaxed. It would be sufficient to assume that for every compact set , a 0-forcing function exists so that (5.2) holds with whenever .
5.4. Distances and Translations
Definition 5.15**.**
For a symmetric matrix , let be the minimum eigenvalue of , and let be the minimum positive eigenvalue of .
Lemma 5.16**.**
Let be a matrix and . Then .
Lemma 5.17**.**
Let be a matrix, and . There exists a constant with . Furthermore, we may take .
Lemma 5.18**.**
Let be a -strongly convex function with condition number , let be a closed and convex set with and being two translations of , let , and let and . Then, .
Lemma 5.19**.**
Let be a -strongly convex function, a linear map of , and a closed and convex set. Let , and consider the sets and , which we assume to be nonempty. Let and . Then, there exists a constant , depending on and but independent of , such that .
5.5. K-Ł Functions
Definition 5.20**.**
Let be proper and lower semicontinuous. The domain of the general subgradient mapping is the set .
Definition 5.21** ([2], 2.4).**
A function is said to have the Kurdyka-Łojasiewicz (K-Ł) property at if there exist , a neighborhood of , and a continuous concave function such that:
- (1)
** 2. (2)
* is smooth on * 3. (3)
For all , 4. (4)
For all , the Kurdyka-Łojasiewicz inequality holds:
[TABLE]
A proper, lower semicontinuous function that satisfies the K-Ł property at every point of is called a K-Ł function.
A large class of K-L functions is provided by the semialgebraic functions, which include many functions of importance in optimization.
Definition 5.22** ([2], 2.1).**
A subset of is (real) semialgebraic if there exists a finite number of real polynomial functions such that
[TABLE]
A function is semialgebraic if its graph is a real semialgebraic subset of .
The set of semialgebraic functions is closed under taking finite sums and products, scalar products, and composition. The indicator function of a semialgebraic set is a semialgebraic function, as is the generalized inverse of a semialgebraic function. More examples can be found in [1].
The key property of K-Ł functions is that if a sequence is a ‘descent sequence’ with respect to a K-Ł function, then limit points of are necessarily unique. This is formalized by the following;
Theorem 5.23** ([2], 2.9).**
Let be a proper and lower semicontinuous function. Consider a sequence satisfying the properties:
**H1: **
There exists such that for each , .
**H2: **
There exists such that for each , there exists with .
If is a K-Ł function, and is a limit point of with , then .
6. General Properties of ADMM
In this section, we will derive results that are inherent properties of ADMM, and require minimal conditions on the structure of the problem. We first work in the most general setting where in the constraint may be any smooth function, the objective function is proper and lower semicontinuous, and the variables may be coupled. We then specialize to the case where the constraint is multiaffine, which allows us to quantify the changes in the augmented Lagrangian using the subgradients of . Finally, we specialize to the case where the objective function splits into for a smooth coupling function , which allows finer quantification using the subgradients of the augmented Lagrangian.
The results given in this section hold under very weak conditions; hence, these results may be of independent interest, as tools for analyzing ADMM in other settings.
6.1. General Objective and Constraints
In this section, we consider
[TABLE]
The augmented Lagrangian is given by
[TABLE]
and ADMM performs the updates as in Algorithm 1. We assume only the following.
Assumption 3**.**
The following hold.
A 3.1**.**
For sufficiently large , every ADMM subproblem attains its optimal value.
A 3.2**.**
* is smooth.*
A 3.3**.**
* is proper and lower semicontinuous.*
This assumption ensures that the in Algorithm 1 is well-defined, and that the first-order condition in Lemma 5.3 holds at the optimal point. The results in this section are extensions of similar results for ADMM in the classical setting (linear constraints, separable objective function), so it is interesting that the ADMM algorithm retains many of the same properties under the generality of Assumption 3. We defer the proofs to the appendix.
Lemma 6.1**.**
Let denote the set of all variables. The ADMM update of the dual variable increases the augmented Lagrangian such that . If , then