Quantum linear systems algorithms: a primer
Danial Dervovic, Mark Herbster, Peter Mountney, Simone Severini,, Na\"iri Usher, Leonard Wossnig

TL;DR
This paper provides a detailed overview of the HHL quantum algorithm for solving linear systems, including its improvements, subroutines, and applications, highlighting its potential exponential speed-up over classical methods.
Contribution
It offers a comprehensive explanation of the HHL algorithm, its enhancements, and related quantum subroutines, serving as a foundational primer on quantum linear system solvers.
Findings
HHL achieves exponential speed-up over classical algorithms.
Improvements include variable-time amplitude amplification and Fourier/Chebyshev-based LCUs.
Discussion of quantum data loading and quantum singular value estimation.
Abstract
The Harrow-Hassidim-Lloyd (HHL) quantum algorithm for sampling from the solution of a linear system provides an exponential speed-up over its classical counterpart. The problem of solving a system of linear equations has a wide scope of applications, and thus HHL constitutes an important algorithmic primitive. In these notes, we present the HHL algorithm and its improved versions in detail, including explanations of the constituent sub- routines. More specifically, we discuss various quantum subroutines such as quantum phase estimation and amplitude amplification, as well as the important question of loading data into a quantum computer, via quantum RAM. The improvements to the original algorithm exploit variable-time amplitude amplification as well as a method for implementing linear combinations of unitary operations (LCUs) based on a decomposition of the operators using Fourier and…
Click any figure to enlarge with its caption.
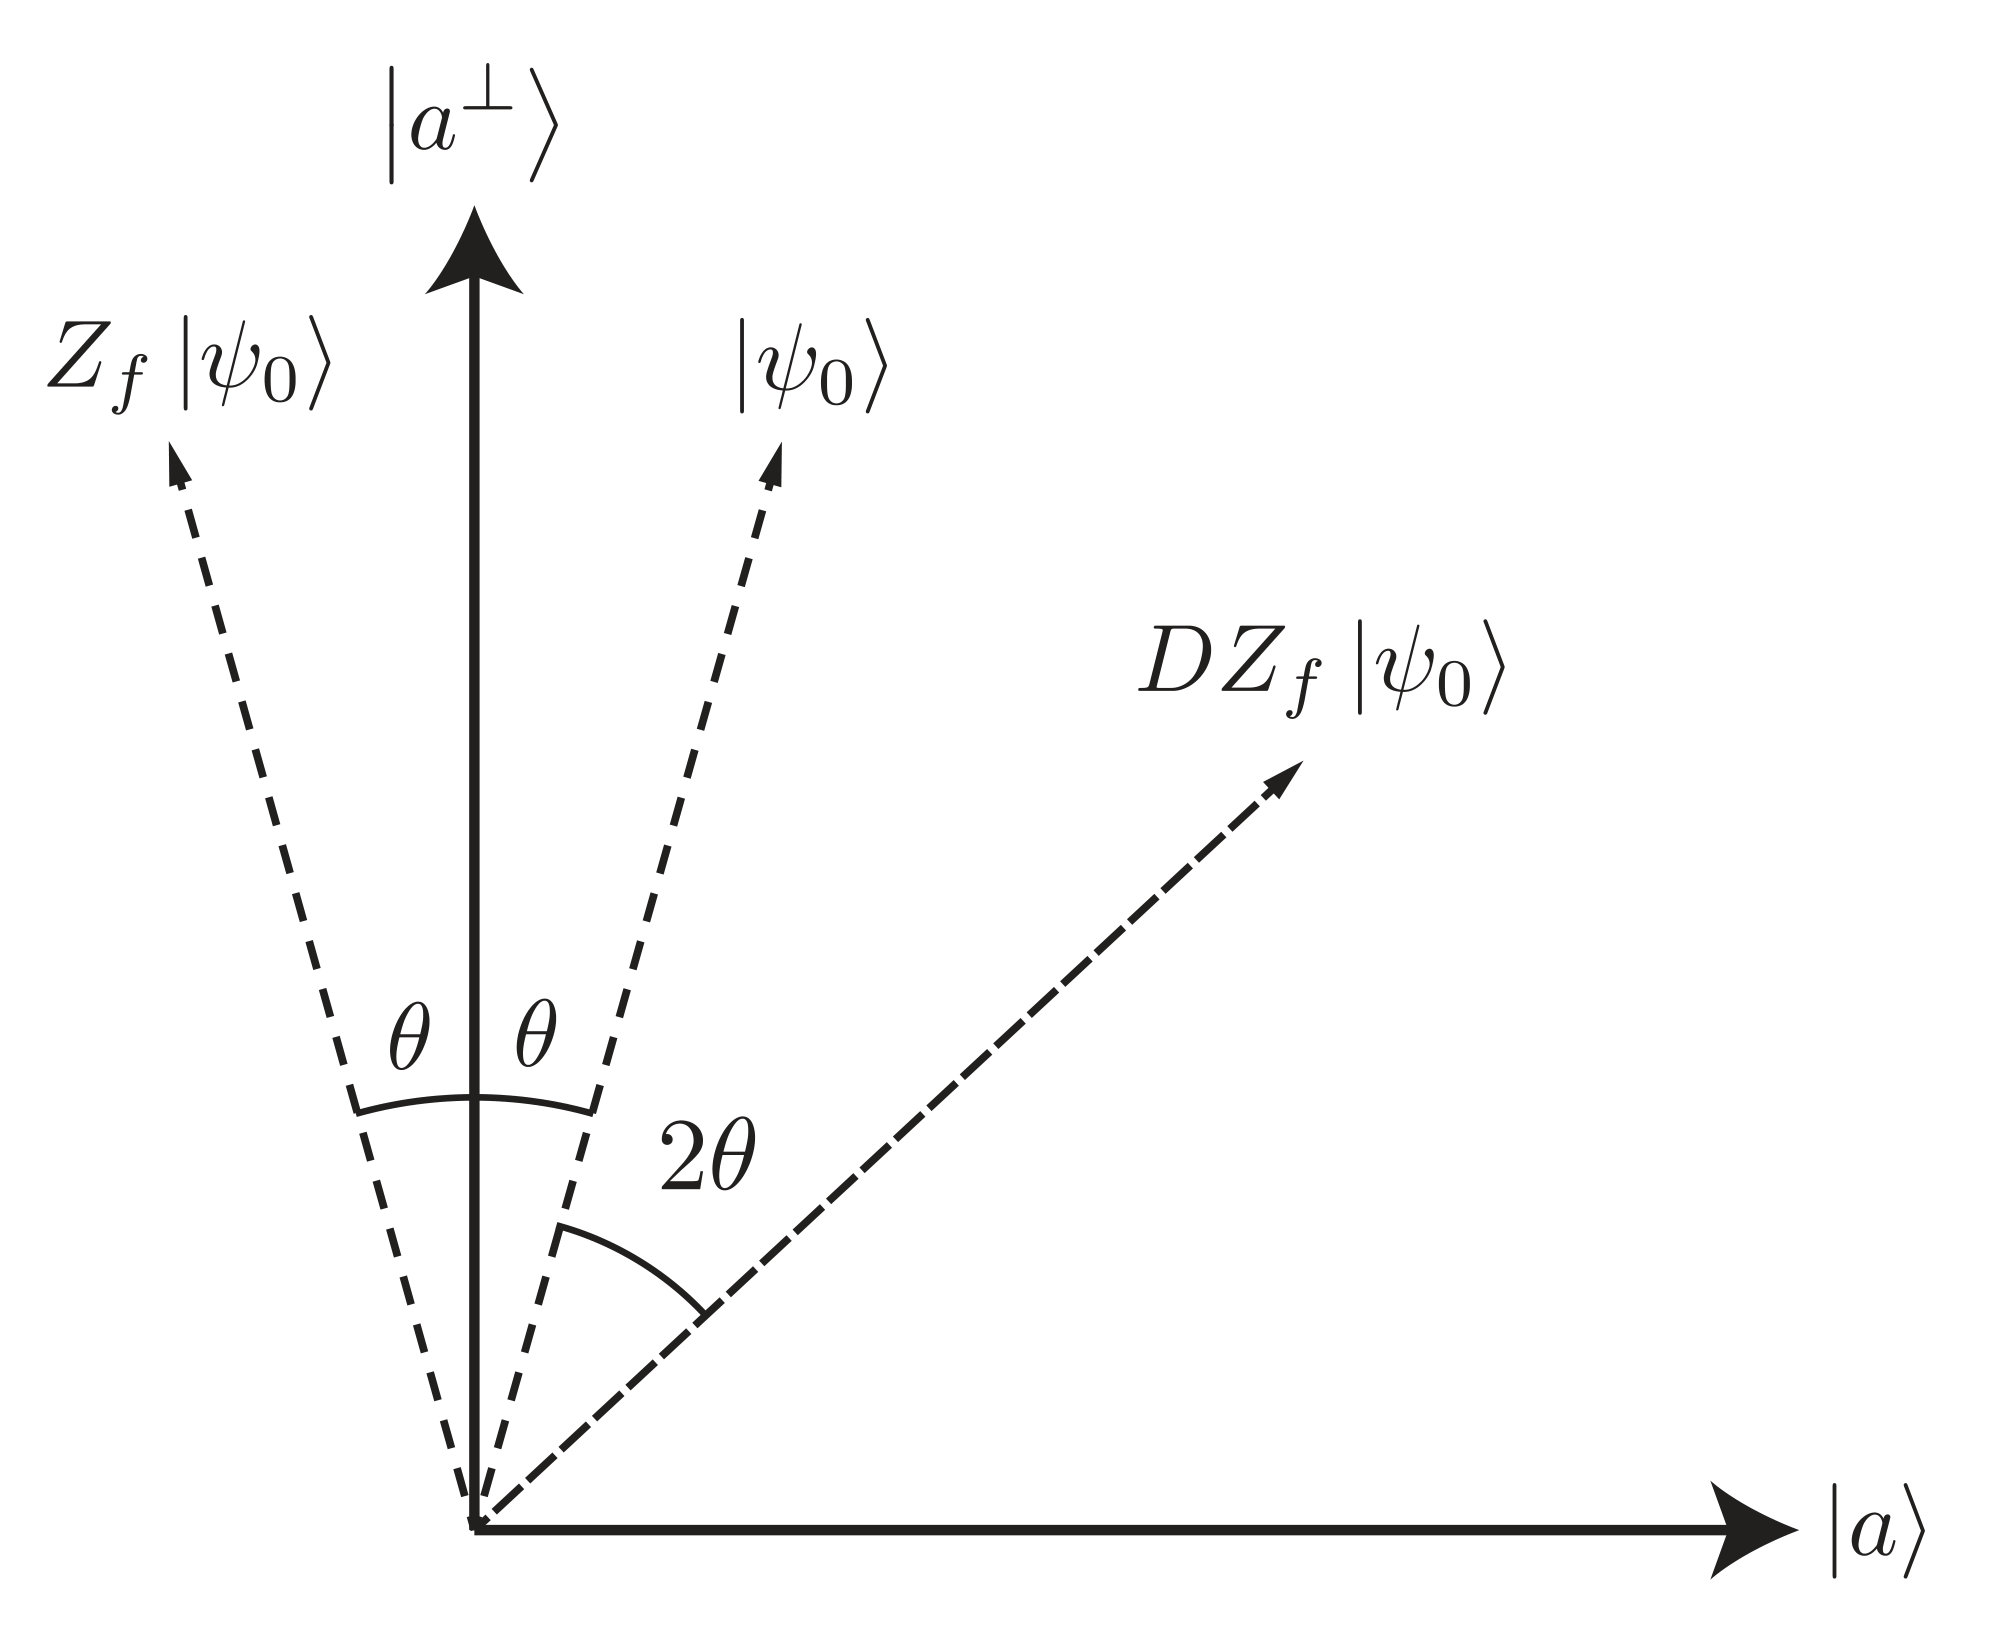 Figure 1
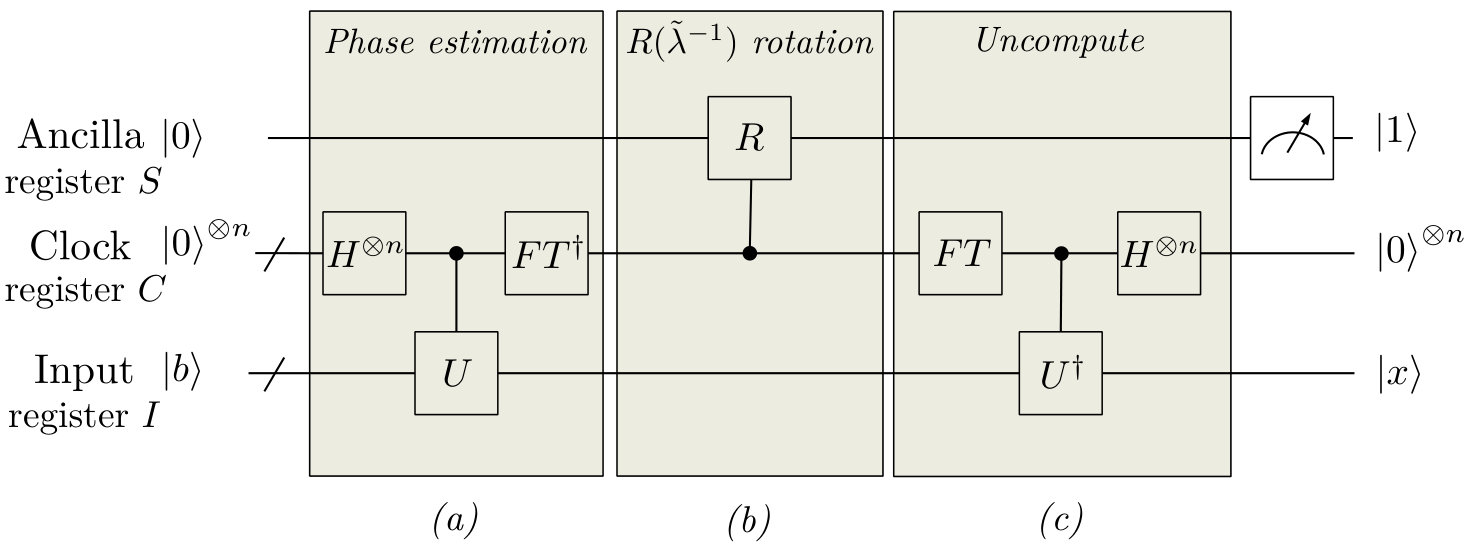 Figure 2
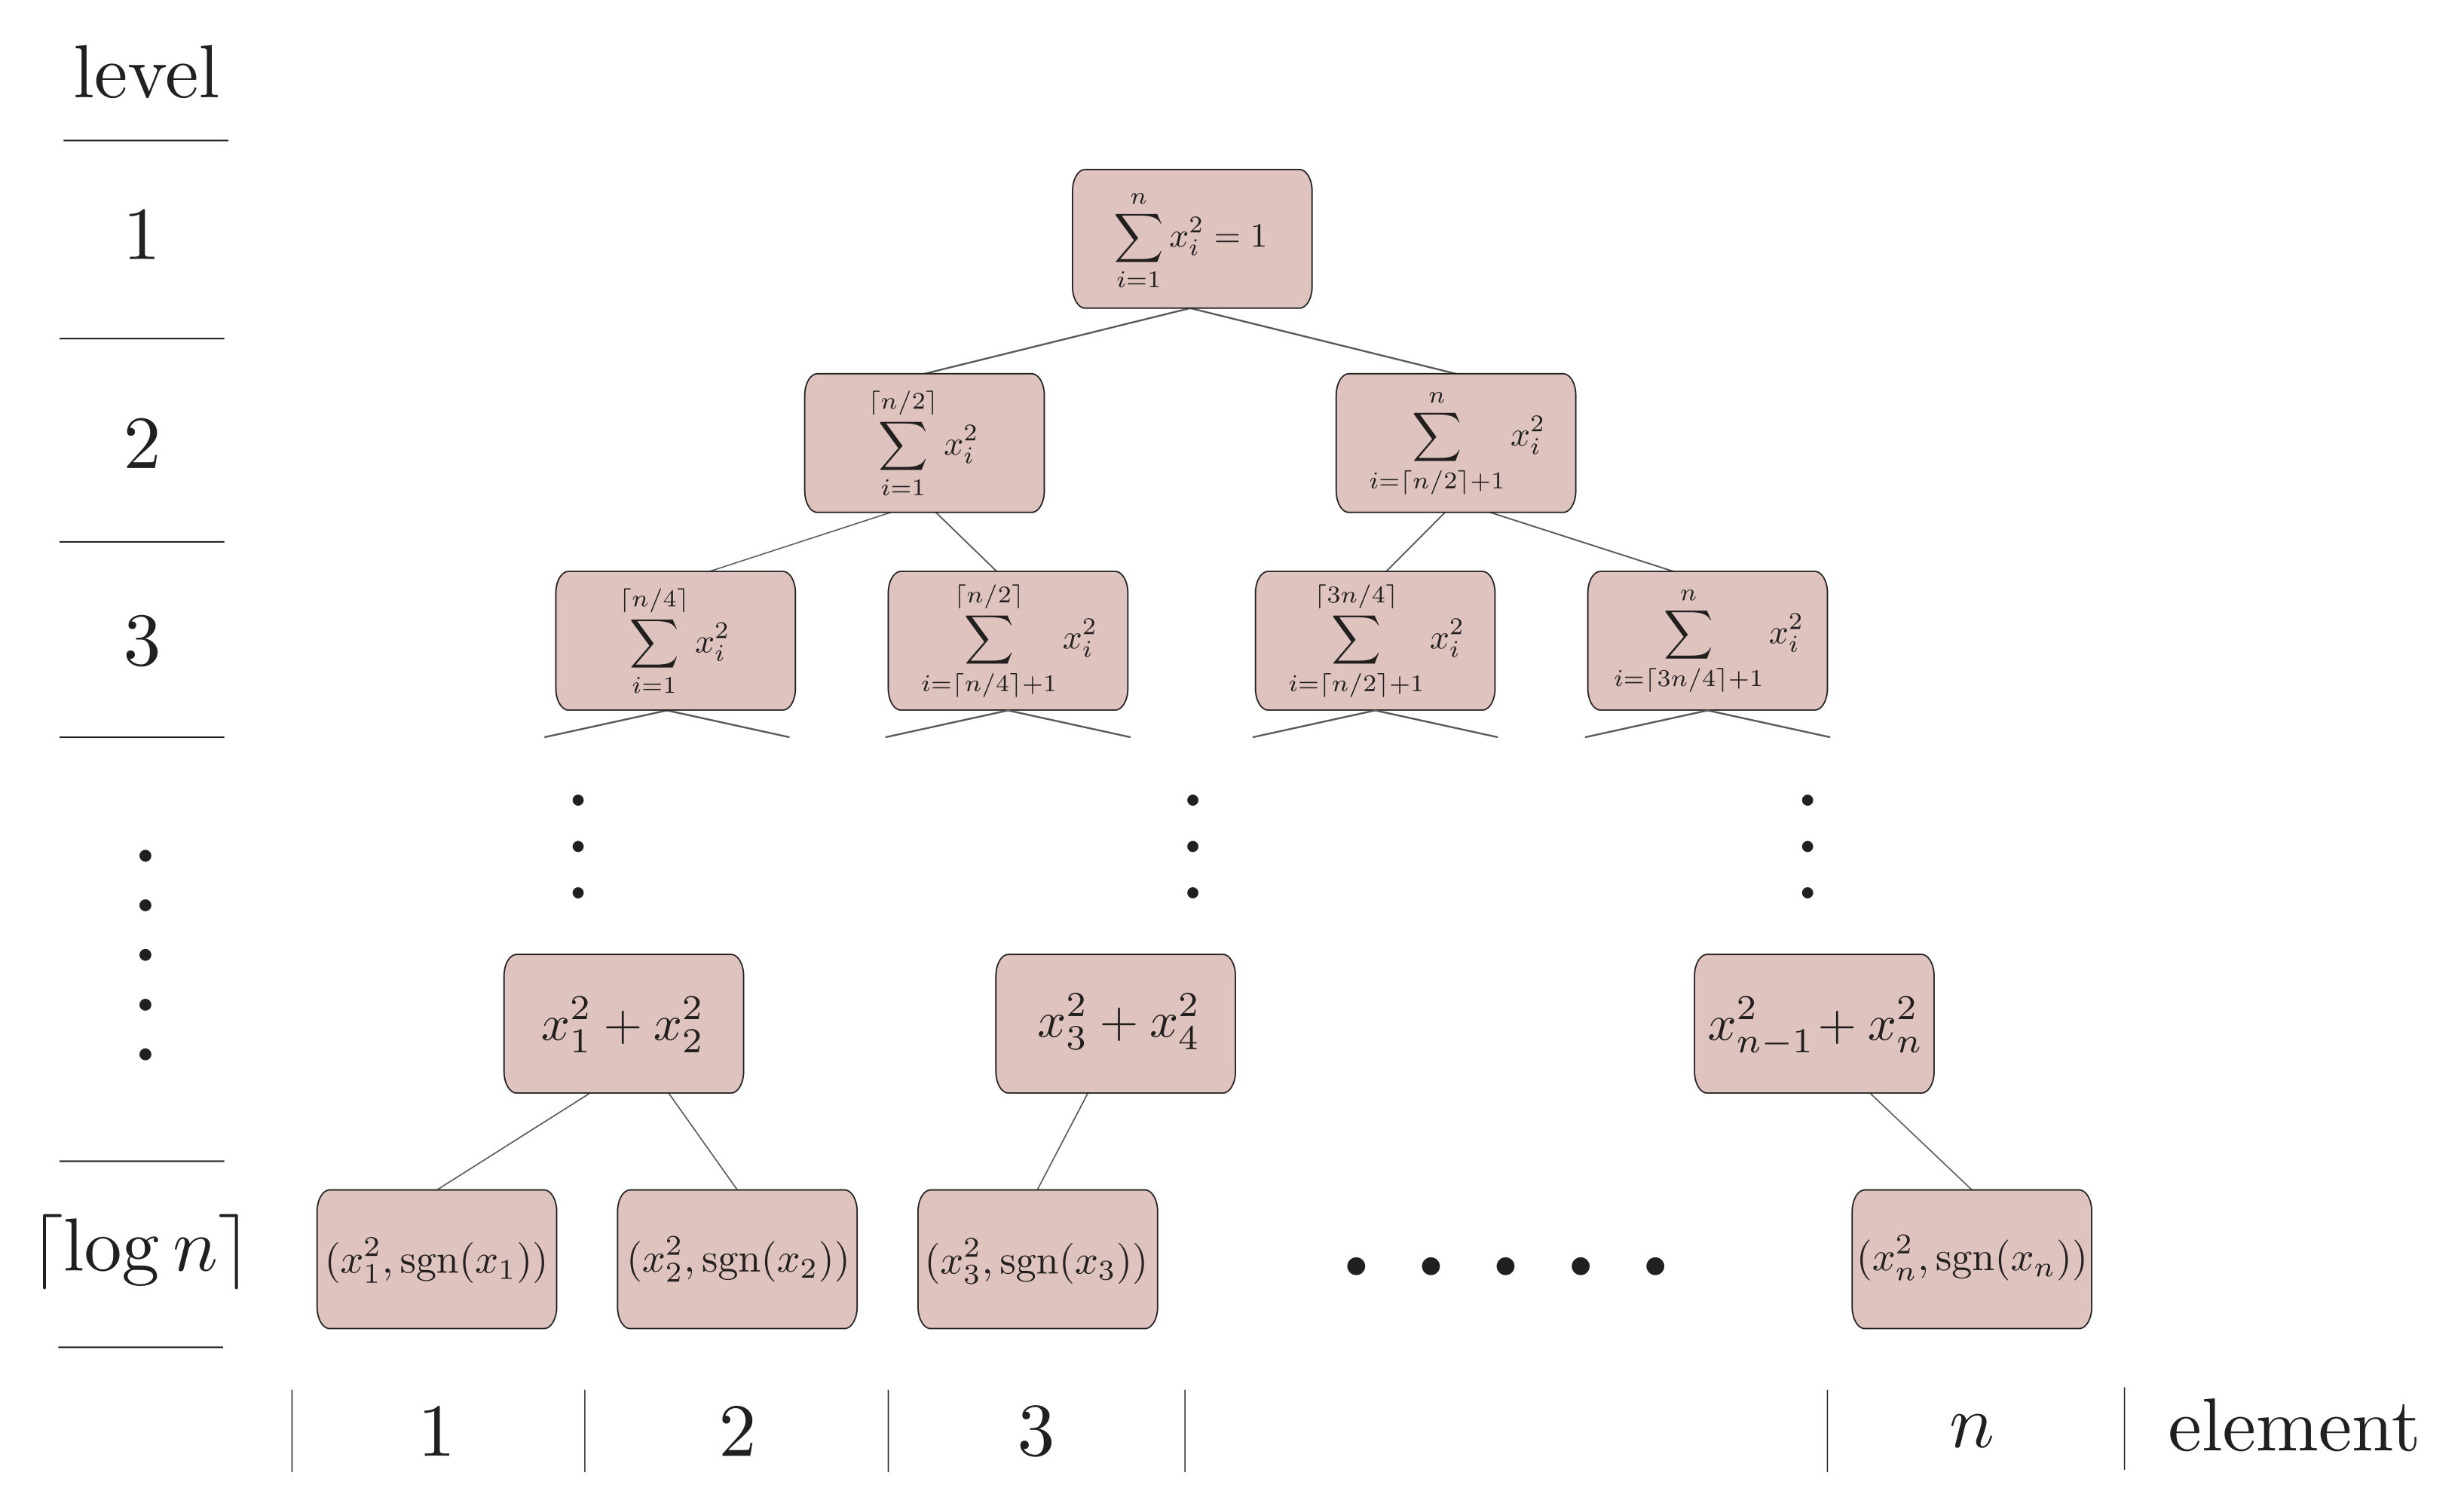 Figure 3
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Code & Models
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
Taxonomy
TopicsQuantum Computing Algorithms and Architecture · Quantum Information and Cryptography · Stochastic Gradient Optimization Techniques
Quantum linear systems algorithms: a primer
Danial Dervovic
Department of Computer Science, University College London, London, UK
Mark Herbster
Department of Computer Science, University College London, London, UK
Peter Mountney
Department of Computer Science, University College London, London, UK
Siemens Healthineers, Medical Imaging Technologies, Princeton, NJ, USA
Simone Severini
Department of Computer Science, University College London, London, UK
Naïri Usher
Department of Computer Science, University College London, London, UK
Leonard Wossnig
Department of Computer Science, University College London, London, UK
Abstract
The Harrow-Hassidim-Lloyd (HHL) quantum algorithm for sampling from the solution of a linear system provides an exponential speed-up over its classical counterpart. The problem of solving a system of linear equations has a wide scope of applications, and thus HHL constitutes an important algorithmic primitive. In these notes, we present the HHL algorithm and its improved versions in detail, including explanations of the constituent subroutines. More specifically, we discuss various quantum subroutines such as quantum phase estimation and amplitude amplification, as well as the important question of loading data into a quantum computer, via quantum RAM. The improvements to the original algorithm exploit variable-time amplitude amplification as well as a method for implementing linear combinations of unitary operations (LCUs) based on a decomposition of the operators using Fourier and Chebyshev series. Finally, we discuss a linear solver based on the quantum singular value estimation (QSVE) subroutine.
Contents
1 Introduction
1.1 Motivation
Quantum computing was introduced in the s as a novel paradigm of computation, whereby information is encoded within a quantum system, as opposed to a system governed by the laws of classical physics. Wider interest in quantum computation has been motivated by Shor’s quantum algorithm for integer factorisation [Sho99], which provides an exponential speed-up over the best known classical algorithm for the same task. If implemented at scale, this would have severe security consequences for the ubiquitous RSA cryptographic protocol. Since then, a number of quantum algorithms demonstrating advantage over classical methods have been developed for a substantial variety of tasks; for a detailed survey, the reader is directed to [Cle+98, Mon15].
Consistent advances on both theoretical and experimental research fronts have meant that the reality of a quantum computer has been edging ever closer. Quantum systems are extremely sensitive to noise, with a primary challenge being the development of error correction in order to achieve fault tolerance [ETC17]. Nonetheless, the current advances observed over recent years in the quest to build a scalable universal quantum computer from both academic and industrial groups raise the question of applications of such a device.
Although powerful quantum algorithms have been devised, their application is restricted to a few use cases. Indeed, the design of a quantum algorithm directly relies on exploiting the laws and features of quantum mechanics in order to achieve a speed-up. More precisely, in quantum computing, a quantum state is first prepared, to which quantum operations are applied before final measurements are performed, thus yielding classical data. As discussed in [Aar15], this model raises a number of challenges. In particular, careful consideration of how classical data can be input and obtained as output is crucial to maintaining the theoretical advantage afforded by quantum algorithms.
The question of solving a system of linear equations can be found at the heart of many problems with a wide scope of applications. An important result in recent years has been the Quantum Linear System algorithm (QLSA) [HHL09], also called Harrow-Hassidim-Lloyd (HHL) algorithm, which considers the quantum version of this problem. In particular, the HHL algorithm run on the quantum problem (that is, with quantum states as input and output) offers an exponential speed-up over the best known classical algorithm run on the classical problem. In the following, we present a complete review of the HHL algorithm and subsequent improvements for sampling from the solutions to linear systems. We have aimed to be as complete as possible, including relevant background where necessary. We assume knowledge of elementary linear algebra and some experience with analysis of classical algorithms.
1.2 Quantum linear systems algorithms
Solving a linear system is the task of taking a given matrix and vector and returning a vector satisfying . As a preview of what is coming up ahead, Table 1 shows the runtime of the best classical algorithm for solving linear systems, conjugate gradient (CG), compared with the quantum algorithms we shall introduce throughout these notes.
We note that CG solves a linear system completely, i.e. it returns the solution vector . The quantum algorithms allow one to sample from the solution efficiently, providing one has an efficient preparation method for the input state, i.e. a mapping from the vector to a quantum state .
We shall formally define the linear systems problem (LSP) and its quantum variant (QLSP) in section 3.1 and will discuss the differences between the two. We will discuss efficient state preparation in section 2.9.
1.3 Quantum computing
In this section, we introduce gate-model quantum computation, the computational model which will be used throughout. For a complete introduction to quantum computing we refer the reader to Nielsen and Chuang [NC02].
In classical computing, the input is a classical bit string which, through the application of a circuit, is transformed to an output bit string. This is achieved via the application of a finite number of classical gates picked from a universal gate set such as NAND. This framework is known as the classical circuit model of computation. In the case of quantum computing, there exist different yet equivalent frameworks in which the computation can be described: the quantum circuit model [NC02], measurement-based quantum computing (MBQC) [RBB03] and adiabatic quantum computing [Far+00]. In the following, we shall concentrate on the quantum circuit model, which is the closest quantum analogue of the classical circuit model as well as the model in which quantum algorithms are generally presented.
In classical computing the fundamental unit of information is the bit, which is either [math] or , whereas in quantum computing, it is the qubit, , such that and . This is represented by a two-dimensional column vector belonging to a complex Hilbert space . We shall denote by the conjugate-transpose of . The states and are basis vectors corresponding to a bit value of ‘0’ and ‘1’ respectively, and we can write and . Thus, we have that a qubit is a normalised complex superposition over these basis vectors. Multiple qubits are combined using the tensor product, that is, for two qubits , their joint state is given by . Thus, an -qubit quantum state can be expressed as
[TABLE]
where , and . Note that complex coefficients are required to describe a quantum state, a number growing exponentially with the system’s size. We call the basis the computational basis, as each basis vector is described by a string of bits.
There are two types of operations we can perform on a quantum state: unitary operators and measurements. A unitary operator has the property that , i.e. its inverse is given by the hermitian conjugate. Furthermore, this implies that the operator is norm-preserving, that is, unitary operators map quantum states to quantum states. A unitary operator on qubits can be expressed as matrix of dimension . Moreover, we have that unitary operators are closed under composition. A measurement is described by a collection of (not necessarily unitary) operators , where the index indicates a given measurement outcome. The operators act on the state’s Hilbert space and satisfy the completeness equation, . For a quantum state , the probability of measuring outcome is given by
[TABLE]
and the resulting quantum state is then
[TABLE]
The completeness equation encodes the fact that measurement probabilities over all outcomes sum to unity. A computational basis measurement, for consists of operators , the projectors onto the computational basis states.
In the circuit model of quantum computation, we are given an input , which is a classical bit string. The first step is to prepare an -qubit qubit quantum input state , where poly. A unitary operator is then applied to , and finally the output state is (customarily) measured in the computational basis – without loss of generality. The measurement outcome corresponds to a classical bit string , which is obtained with probability and which we refer to as the output of the computation.
In practice, a quantum computer will be built using a finite set of quantum gates which act on a finite number of qubits. Typically, we consider gates acting on either one or two qubits, leaving the others invariant. A set of quantum gates is said to be universal if any unitary operator can be approximated ‘well-enough’ using only gates from this set. More precisely, a set of gates is universal if any unitary operator can be decomposed into the sequence , such that , for any , where the . There are many such universal gate sets, such as for instance the Toffoli gate (which acts on three bit/qubits) and the Hadamard gate, or single-qubit rotations with a CNOT. Thus, any arbitrary unitary operator can be implemented given a universal set of gates.
This thus tells us that any arbitrary unitary operator can be approximated by the sequence to accuracy . But, how many gates are required to achieve a good accuracy? The Solovay-Kitaev theorem (see [NC02, Appendix 3]) states that L=\mathcal{O}\big{(}\log^{2}\frac{1}{\varepsilon}\big{)}, and thus exponential accuracy can be achieved using only a polynomial number of gates.
Finally, we discuss an important tool used in quantum computation, the oracle. Here, we are given a boolean function . The function is said to be queried via an oracle , if given the input (where and ), we can prepare the output , where denotes addition modulo . That is, the mapping
[TABLE]
can be implemented by a unitary circuit , which takes the form
[TABLE]
The effect of the oracle needs to be determined on all basis states, and the definition will always be given in terms of a state .
1.4 Quantum algorithms and machine learning
Quantum algorithms, in some cases, have the capacity to achieve significant speed-ups compared to classical algorithms. Most notably, classically, the prime factorization of an -bit integer using the general number field sieve is , where , and thus takes time exponential in the number of bits. In contrast, Shor’s factorization algorithm [Sho99] achieves an astonishing exponential speed-up with a polynomial runtime of . Another impressive result is the quadratic speed-up obtained by Grover’s algorithm for unstructured database search [Gro96, Gro97], which we discuss in detail in section 2.7. These are just some examples of the many quantum algorithms which have been devised over the past decades [Cle+98, Mon15].
Machine learning [AMMIL12] has had and continues to have a significant impact for artificial intelligence and more generally for the advancement of technology. Naturally, this raises the question of whether quantum computing could enhance and improve current results and techniques. The HHL algorithm [HHL09] considers the problem of solving a system of linear equations, which on a classical computer takes time polynomial in the system size . At its heart, the problem reduces to matrix inversion, and the HHL algorithm offers an exponential speed-up for this task, with a certain number of important caveats. This in turn raised the question of whether quantum algorithms could accelerate machine learning tasks, which is referred to as quantum machine learning (QML) – see the following reviews [ABG06, Cil+17].
An interesting example which illustrates how quantum computing might help with machine learning tasks is quantum recommendation systems [KP16]. Here, the netflix problem [KBV09, BK07] is considered, whereby we are given users and films, and the goal is to recommend a film to a user which they have not watched, that they would rate highly given their previous rating history. The users’ preferences can be represented by a matrix of dimension , where the entry corresponds to the user’s rating of the film. Of course, the elements of are not all known, and the question is to provide good recommendations to the user. Classical algorithms for this problem run in time polynomial with matrix dimension, that is \mathcal{O}\big{(}\text{poly}(MN)\big{)}. In contrast, there exists a quantum algorithm with runtime complexity scaling as \mathcal{O}\big{(}\text{poly}\log(MN)\big{)}, thus providing an exponential speed-up [KP16].
Another important example is the classical perceptron model, where we are given labeled data points which are linearly separable and the goal is to find the separating hyperplane. Classically, we have that the number of training updates scales as \mathcal{O}\big{(}\frac{1}{\gamma^{2}}\big{)}, where is the margin, i.e. the shortest distance between a training point and the separating hyperplane. In contrast, the quantum perceptron model [WKS16] exploits Grover’s search algorithm (see section 2.7), in order to achieve a quadratic speed-up \mathcal{O}\big{(}\frac{1}{\gamma}\big{)}.
Another important classical model for supervised learning is support vector machines (SVM), which are used for data classification and regression. For a special case of SVMs, known as least-squares SVMs, the classical runtime is polynomial in the number of training examples and their dimension , , where denotes the accuracy. In contrast, quantum SVM [RML14] offer an exponential speed-up in the dimensions and input number with a runtime of .
Finally, we note that quantum algorithms have also been developed for unsupervised learning, that is, in the case of unlabeled data [ABG13, WKS14], which also present a speed-up over their classical counterparts.
All of the algorithms mentioned here use the HHL – or some other quantum linear systems algorithm – as a subroutine.
1.5 Structure
We have aimed for a mostly modular presentation, so that a reader familiar with a particular subroutine of the HHL algorithm, say, phase estimation, can skip the relevant section if they wish. The structure of the text goes as follows.
First, in section 2, we review some of the key components used in quantum algorithms, namely notation conventions 2.1, the quantum Fourier transform 2.2, Hamiltonian simulation 2.3, quantum phase estimation 2.5, phase kickback 2.6, amplitude amplification 2.7, the uncompute trick 2.8 and finally quantum RAM 2.9. Next, in section 3, we present a detailed discussion of the HHL algorithm. We first formally define the problem in 3.1, before then discussing the algorithm in detail in 3.2, along with an error analysis in 3.3. In section 3.5 we consider the computational complexity of the problem, and in 3.5 its optimality. Then, in 3.6, the algorithm is extended to the case of non-Hermitian matrices.
Next, in section 4, we introduce modern updates to the algorithm, namely: improvements in the dependency on the condition number in 4.1; improvements on the precision number in 4.2 and in section 4.3, further improvements based on quantum singular value estimation giving an algorithm for dense matrices. More specifically, we discuss Jordan’s lemma and its consequences in LABEL:subsec:intersection_subspaces, before reviewing the singular value decomposition in 4.3.1 and finally presenting the quantum singular value estimation 4.3.2 and its application to linear systems in 4.3.3. This section deviates from the pedagogical style of the previous sections, giving an overview of the important ideas behind the results as opposed to all of the gory details.
2 Quantum algorithms: fundamental components
Here we review some of the fundamental ideas routinely used in the design of quantum algorithms, which will subsequently be applied in the HHL algorithm.
2.1 Notation and conventions
Any integer between [math] and , where may be expressed as an -bit string , i.e. . Furthermore, given an integer , it is easy to verify that .
The Hadamard matrix is defined as H:=\frac{1}{\sqrt{2}}\smallmatrixquantity[1&1\\ 1&-1]. Given a vector , the Euclidean norm of x is . For an matrix with elements , the operator norm is given by , i.e., it is the sum of the Euclidean norms of the column vectors of . Note that in both cases this is equivalent to -norm. Next, we present the QFT.
2.2 Quantum Fourier transform
The QFT is at the heart of many quantum algorithms. It is the quantum analogue of the discrete Fourier transform, see 2.2.1, and is presented in section 2.2.2. In section 2.2.3, we will see how the QFT may be implemented efficiently using a quantum computer.
2.2.1 The discrete Fourier transform
The Fourier transform is an important tool in classical physics and computer science, as it allows for a signal to be decomposed into its fundamental components, i.e. frequencies. The Fourier transform tells us what frequencies are present and to what degree.
In the discrete setting, we have that the DFT is a square invertible matrix of dimension , where and . It is easy to show that the columns of this matrix are orthogonal and have unit length, and thus the set of column vectors form an orthonormal basis which we refer to as the Fourier basis. If the DFT is applied to a vector using matrix multiplication, then the time complexity scales as . Crucially, by using a divide and conquer approach this can be improved to , which is referred to as the fast Fourier transform (FFT).
2.2.2 The quantum Fourier transform
In a similar way, the QFT is defined by mapping each computational basis state to a new quantum state |f_{j}\rangle=\frac{1}{\sqrt{N}}\sum_{k=0}^{N-1}\exp\Big(i\frac{2\pi jk}{N}\Big{missing})|k\rangle. The set of orthonormal states form an orthonormal basis set called the Fourier basis. The quantum Fourier transform with respect to an orthonormal basis is defined as the linear operator with the following action on the basis vectors:
[TABLE]
The inverse Fourier transform is then defined as
[TABLE]
But, what does this mean in terms of individual qubits? First, we represent the integer in binary notation, , and thus the Fourier basis states can be expressed as: |f_{j}\rangle=\frac{1}{\sqrt{N}}\sum_{k=0}^{N-1}\exp\Big(i2\pi j\sum_{l=1}^{n}k_{l}2^{-l}\Big{missing})|k\rangle. Expanding this expression, we have
[TABLE]
Expanding the summation gives
[TABLE]
Finally, the operation corresponds to the decimal expansion of up to bits, and we can thus write
[TABLE]
We initially applied the QFT to the computational basis state . From Eq. (10), we see that information pertaining to the input is disseminated throughout the relative phase on each individual qubit. Thus, given the final state , applying the inverse QFT would yield the input string . Equivalently, one could obtain by performing a measurement in the Fourier basis.
2.2.3 Implementation of the QFT
The goal is to obtain the quantum state after applying a quantum circuit to an all-zero input state. From Eq. (10) we see that the state corresponds to a state where each qubit is initialised in the state and subsequently acquires a relative phase of \exp\big(i2\pi j2^{-k}\big{missing}), where , and where we recall that .
We now consider the quantum circuit which can implement this state. First, it is easy to see that a state of the form \frac{1}{\sqrt{2}}\Big{(}|0\rangle+\exp\big(i2\pi 0.j_{n}\big{missing})|1\rangle\Big{)} corresponds to either the state or depending on the value of . This can be expressed as , and can thus be obtained by the application of a Hadamard gate to a qubit in the state . Next, the state of the second qubit is given by \frac{1}{\sqrt{2}}\Big{(}|0\rangle+\exp\big(i2\pi 0.j_{n-1}j_{n}\big{missing})|1\rangle\Big{)}, which can be re-expressed as \frac{1}{\sqrt{2}}\Big{(}|0\rangle+(-1)^{j_{n-1}}\exp\big(i2\pi\frac{j_{n}}{2^{2}}\big{missing})|1\rangle\Big{)}. Thus, this corresponds to first preparing the state , and then applying a controlled rotation to the qubit, where the control is the th qubit in the state . Thus, the state on the first two qubits can be obtained by preparing the state , applying the Hadamard gate to the th qubit, and then a controlled rotation with qubit as control, where we have that is given by:
[TABLE]
and controlled by qubit . Finally, SWAP operations are performed throughout for the qubits to be in the correct order. This approach can be extended to the qubits, where the number of gates scales as , and thus the QFT can be efficiently implemented in a quantum circuit.
2.3 Hamiltonian simulation
Most quantum algorithms for machine learning, and in particular the HHL algorithm, leverage quantum Hamiltonian simulation as a subroutine. Here, we are given a Hamiltonian operator , which is a Hermitian matrix, and the goal is to determine a quantum circuit which implements the unitary operator , up to given error. The evolution of a quantum state under a unitary operator is given, for simplicity, by the time-independent Schrödinger equation:
[TABLE]
the solution to which can be written as .
Depending on the input state and resources at hand, there exists many different techniques to achieve this [BC09, BCK15, LC17, LC17a, LC16]. We give a brief introduction to this large field of still ongoing research, and interested readers can find further details in the lecture notes of Childs [Chi17][Chapter V] and the seminal work [Chi+03].
The challenge is due to the fact that the application of matrix exponentials are computationally expensive. For instance, naive methods require time for a matrix, which is restrictive even in the case of small size matrices. In the quantum case, the dimension of the Hilbert space grows exponentially with the number of qubits, and thus any operator will be of exponential dimension. Applying such expensive matrix exponentials has been studied classically, and in particular the classical simulation of such time-evolutions is known to be hard for generic Hamiltonians . As a consequence, new more efficient methods need to be introduced. In particular, a quantum computer can be used to simulate the Hamiltonian operator, a task known as Hamiltonian simulation, which we wish to perform efficiently. More specifically, we can now define an efficient quantum simulation as follows:
Definition 1**.**
(Hamiltonian Simulation)* We say that a Hamiltonian that acts on qubits can be efficiently simulated if for any , there exists a quantum circuit consisting of gates such that . Since any quantum computation can be implemented by a sequence of Hamiltonian simulations, simulating Hamiltonians in general is -hard, where refers to the complexity class of decision problems efficiently solvable on a universal quantum computer [KSV02].*
Note that the dependency on is important and it can be shown that at least time is required to simulate for time , which is stated formally by the no fast-forwarding theorem [Ber+07]. There are, however, no nontrivial lower bounds on the error dependency . The hope to simulate an arbitrary Hamiltonian efficiently is diminished, since it NP-hard to find an approximate decomposition into elementary single- and two-qubit gates for a generic unitary and hence also for the evolution operator [SBM06, Ite+16, Kni95]. Even more so, the optimal circuit sythesis was even shown to be QMA-complete [JWB03]. However, we can still simulate efficiently certain classes of Hamiltonians, i.e. Hamiltonians with a particular structure. One such example is the case when only acts nontrivially on a constant number of qubits, as any unitary evolution on a constant number of qubits can be approximated with error at most using one- and two-qubit gates, on the basis of Solovay-Kitaev’s theorem. The origin of the hardness of Hamiltonian simulation stems from the fact that we need to find a decomposition of the unitary operator in terms of elementary gates, which in turn can be very hard for generic Hamiltonians. If can be efficiently simulated, then so can for any [Chi17]. In addition, since any computation is reversible, is also efficiently simulatable and this must hence also hold for .
Finally, we note that the definition of efficiently simulatable Hamiltonians further extends to unitary matrices, since every operator corresponds to a unitary operator, and furthermore every unitary operator can be written in the form for a Hermitian matrix . Hence, we can similarly speak of an efficiently simulatable unitary operator, which we will use in the following.
2.3.1 Trotter-Suzuki methods
For any efficiently simulatable unitary operator , we can always simulate the Hamiltonian in a transformed basis , since
[TABLE]
which follows from the fact that if is unitary, then we have that , which can easily be proven by induction. Another simple but useful trick is given by the fact that, given efficient access to any diagonal element of a Hamiltonian , we can simulate the diagonal Hamiltonian using the following sequence of operations. Let indicate a computational step, such that we can denote in the following a sequence of maps to a state:
[TABLE]
In words, we first load the entry into the second register, then apply a conditional-phase gate and then reverse the loading procedure to set the last qubit to zero again. Since we can apply this to a superposition and using linearity, we can simulate any efficiently diagonalisable Hamiltonian. More generally, any -local Hamiltonian, i.e. a sum of polynomially many terms in the number of qubits that each act on at most qubits, can be simulated efficiently. Indeed, since each of the terms in the sun acts only on a constant number of qubits, it can be efficiently diagonalised and thus simulated. In general, for any two Hamiltonian operators and that can be efficiently simulated, the sum of both can also be efficiently simulated, as we will argue below, first for the commuting case and then for the non-commuting case.
This is trivial if the two Hamiltonians commute. Indeed, we now omit the coefficient and consider for simplicity the operator . By applying a Taylor expansion, followed by the Binomial theorem and the Cauchy product formula (for the product of two infinite series), we have
[TABLE]
Note that this is only possible since for the Cauchy formula we can arrange the two terms accordingly and do not obtain commutator terms in it. However (recall the famous Baker-Campbell-Hausdorff formula, see e.g. [Ros02]), this is not so for the general case, i.e. when the operators don’t commute. Here we need to use the Lie-Product formula [Ros02]:
[TABLE]
If we want to restrict the simulation to a certain error , it is sufficient to truncate the above product formula after a certain number of iterations , which we will call the number of steps:
[TABLE]
which, as we will show, can be achieved by taking , where we require that for the evolution to be efficiently simulable. To see this, observe that, from the Taylor expansion,
[TABLE]
We need to expand a product of the form , where the operators and are non-commuting. Thus, we have that
[TABLE]
where and do not commute in general. Specifically we have and and the first order terms in have the form
[TABLE]
for . Next, we consider terms of order greater than one, where we have powers of for . Let us note that for , we have for . Thus, these first order and greater terms can be absorbed in the notation. Furthermore, in the following, we do not explicitly write the exponentials of the form as these will not play a role for bounding the error in the norm due to their unitarity. So, we continue to bound
[TABLE]
We can now finally consider the error of the simulation scheme, see Eq. (22), which using Eq. (27), yields
[TABLE]
In order to have this error less than , the number of steps must be .
This is a naive and non-optimal scheme. It can be shown that one can use higher-order approximation schemes, such that can be simulated for time in for any positive but arbitrarily small [Ber+07, BC09].
These so-called Trotter-Suzuki schemes can be generalized to an arbitrary sum of Hamiltonians which then leads to an approximation formula given by
[TABLE]
The following definitions are useful:
Definition 2**.**
(Sparsity)* An matrix is said to be -sparse if it has at most entries per row.*
Definition 3**.**
(Sparse matrix)* An matrix is said to be sparse if it has at most entries per row.*
Note that the sparsity depends on the basis in which the matrix is given. However, given an arbitrary matrix, we do not a priori know the basis which diagonalises it (and hence gives us a diagonal matrix with sparsity ), and so we need to deal with a potentially dense matrix, i.e. a matrix which has entries per row.
Definition 4**.**
(Row computability)* The entries of a matrix are efficiently row computable if, given the indices , we can obtain the entries efficiently, i.e. in time, where is the sparsity as defined above.*
2.3.2 Graph-colouring method
Crucially, the simulation techniques described above can allow us to efficiently simulate sparse Hamiltonians. Indeed, if for any index , we can efficiently determine all of the indices for which the term is nonzero, and furthermore efficiently obtain the values of the corresponding matrix elements, then we can simulate the Hamiltonian efficiently, as we will describe below.
This method of Hamiltonian simulation is based on ideas from graph theory, and we will now first briefly introduce a couple of key notions relevant in our discussion. For further information, we refer the reader to the existing literature [Wes+01]. An undirected graph is specified by a set of vertices and a set of edges, i.e., unordered pairs of vertices. When two vertices form an edge they are said to be connected. A graph can be represented by its adjacency matrix , where if the vertices and are connected, and , otherwise. The degree of a vertex is given by the number of vertices it is connected to. The maximum degree of a graph refers the maximum degree taken over the set of vertices. The problem of edge colouring considers if, given colours, each edge can be assigned a specific colour with the requirement that no two edges sharing a common vertex should be assigned the same colour. Vizing’s theorem tells us that, for a graph with maximum degree , an edge colouring exists with at most . Finally, a bipartite graph is a graph, where the set of vertices can be separated into two disjoint subsets and such that and no two vertices belonging to the same subset are connected, i.e., for every , we have , for .
Previously, we saw that a Hamiltonian operator can be represented by a square matrix. Thus, a graph can be associated with any Hamiltonian by considering the adjacency matrix with a at every non-zero entry of the Hamiltonian, and a [math] elsewhere, in the spirit of combinatorial matrix theory. For a matrix of dimension , this will thus correspond to a graph with vertices. Previously, we saw that sparse Hamiltonians have at most polylog entries per row, and thus , for entries in total. This will translate into a graph having a number of edges .
Childs [Chi+03] proposed an efficient implementation for the simulation of sparse Hamiltonians by using the Trotterization scheme presented above (c.f. section 2.3.1) and a local colouring algorithm of the graph associated with the -sparse Hamiltonian. The core idea is to colour the edges of the Hamiltonian . Then, the Hamiltonians corresponding to each subgraphs defined by a specific colour can be simulated, and finally the original Hamiltonian recovered via the Trotter-Suzuki method [Chi+03].
More precisely, the first step is to find an edge-colouring of the graph associated with the Hamiltonian . This will be achieved using colours, which in the case of a sparse Hamiltonian, will be at most polylog. Next, the graph can be decomposed by considering the subgraphs corresponding to a single colour. We thus obtain a decomposition of the original Hamiltonian in a sum of sparse Hamiltonians, containing at most polylog terms. It is easy to convince oneself that each of these terms consists of a direct sum of two-dimensional blocks. Indeed, each adjacency matrix corresponding to a subgraph will be symmetric, with at most one entry per row, meaning that the evolution on any one of these subgraphs takes place in isolated two-dimensional subspaces. Thus, each Hamiltonian term can be easily diagonalised and simulated using the diagonal Hamiltonian simulation procedure as given in Eq. (13).
A crucial step in this procedure is the classical algorithm for determining the edge colouring efficiently. Vizing’s theorem guarantees the existence of an edge colouring using colours. But, the question remains as to how this can be efficiently achieved. Indeed, even though we are given the adjacency matrix representation of the entire graph, we will now restrict ourselves to accessing only local information i.e. each vertex has only access to information regarding it nearest-neighbours. Finding an optimal colouring is an NP-complete problem. However, there are polynomial time algorithms that construct optimal colourings of bipartite graphs, and colourings of non-bipartite simple graphs that use at most colours. It is important to note that the general problem of finding an optimal edge colouring is NP-hard and the fastest known algorithms for it take exponential time.
We thus now present a local edge-colouring scheme achieving a -colouring (where we recall that is the maximum degree of the graph, i.e. the sparsity) for the case of a bipartite graph. This, using a reduction [Chi17], is sufficient for the simulation of an arbitrary Hamiltonian. Crucially, this scheme is efficient if the graph is sparse, i.e. if polylog. We note that better schemes exist [Ber+07, BC09, BCK15] and can allow for polynomial improvements of the simulation scheme in comparison to the one given here.
Lemma 1**.**
(Efficient bipartite graph colouring [Lin87, Lin92])*
Suppose we are given an undirected, bipartite graph with vertices and maximum degree (i.e. each vertex is connected to a maximum of other vertices - the so called neighbours - which is similar to sparsity ), and that we can efficiently compute the neighbours of any given vertex. Then there is an efficiently computable edge colouring of with at most colours.*
Proof.
The vertices of are ordered and numbered from through . For any vertex , let denote the index of vertex in the list of neighbours of , ordered in increasing number. For example, let have the neighbours with the list of neighbours neighbours of . Then, we have that index, and index. Then define the colour of the edge , where is from the left part of the bipartition and is from the right for all and which have an edge. The colouring of this edge is then assigned to be the ordered pair colourindex index. Recall that an edge colouring assigns a colour to each edge so that no two adjacent edges share the same colour. These assigned colours in form of the index-pairs give a valid colouring since if and have the same colour, then indexindex, so and similarly, if and have the same colour, then index index, so . ∎
Using this lemma we can then perform Hamiltonian simulation in the following manner. First we ensure that the associated graph is bipartite by simulating the evolution according to the Hamiltonian , a block-anti-diagonal matrix
[TABLE]
The graph associated to this will be bipartite, with the same sparsity as [Chi17]. Observe that simulating this reduces to simulating since
[TABLE]
Without loss of generality let us assume now that has only off diagonal entries. Indeed, any Hamiltonian can be decomposed as the sum of diagonal and off-diagonal terms , which can then be simulated the sum using the rule given in Eq. (21). We can then, for a specific vertex and a colour , compute the evolution by applying the following three steps:
First we compute the complete list of neighbours of (i.e. the neighbour list and the indices) and each of the colours associated to the edges connecting with its neighbours, using the above local algorithm for graph colouring from Lemma 1. 2. 2.
Let denote the vertex adjacent to via an edge with colour . We then, for a given , compute and retrieve the Hamiltonian matrix entry . We can then implement the following quantum state i.e. three qubit registers in which we load the elements in the first one, in the second and then load the matrix element into the last one. More specifically, we here prepare the quantum state and then using the state preparation oracle (e.g. qRAM, see section 2.9), we obtain which can be done efficiently, i.e. in time , which is the time required to access the data. 3. 3.
We then simulate the (-independent, i.e. only depending on the local entry of but not the general matrix) Hamiltonians , i.e. the at most polylog Hamiltonians we obtain from the graph colouring. Note that this is a sparse Hamiltonian which acts only on the neighbours as described in the colouring step. The simulation is efficient, since can be diagonalised in constant time, as it consists of a direct sum of two-dimensional blocks. Next, we apply a scheme, described below, whereby each complex matrix entry is decomposed into a real part and imaginary part and simulated separately. We can then simulate the diagonalised Hamiltonians such that we implement the following mapping
[TABLE]
where is a diagonal element of the diagonalised Hamiltonian . This can also be done in superposition.
The Hamiltonian to be simulated has complex entries, and can thus be decomposed in real and imaginary parts. Let denote the vertex connected to via an edge of colour . The original Hamiltonian had complex entries, and we can express the entry associated to vertex as a sum of a real part and imaginary part . If we assume that these can be loaded independently i.e. can be loaded separately, then we can introduce the oracles which allow for the following mappings to be implemented:
[TABLE]
and similarly the inverse operations, for which it holds that , , since we have bitwise adding modulo in the loading procedure.
In order to simulate the complex entries we need to implement a procedure which allows us to apply both parts individually and still end up in the same basis-element such that these sum up to the actual complex entry, i.e. that we can apply and separately to the same basis state. We use multiple steps to do so.
Given the above oracles, we can similarly simulate the following Hermitian operations (note that this is not a unitary operation):
[TABLE]
where we apply the Hermitian operators to multiply with (and ) and the swap operation to the registers, which can be implemented efficiently since the swap can be done efficiently. The operator is described in detail in [Chi+03] We then can implement the operator
[TABLE]
where the sum is about all colours . This acts then on as , since
[TABLE]
which can be confirmed using the fact that and since we have modulo addition, i.e. .
2.4 Erroneous Hamiltonian simulation
One might wonder what would happen with errors in the Hamiltonian simulator. For example, imagine that we simulate the target Hamiltonian with simulator such as a quantum computer, and this simulator introduces some random error terms. This will be an issue for as long as we do not have fully error corrected quantum computers, or if we use methods like quantum density matrix exponentiation which can have errors in the preparation of the state we want to exponentiate (see [LMR13, Kim+17]). For example, this is relevant for a method called sample-based Hamiltonian simulation [LMR13, Kim+17] where we perform the quantum simulation of a density matrix , i.e. trace- Hermitian matrix, which can have some errors.
For a more in depth introduction and analysis see for example [CMP17]. Errors in the Hamiltonian simulator have been investigated in depth and here, we only want to give the reader some tools to grasp how one could approach such a problem in this small section. For more elaborate work on this we refer the reader to [CMP17].
In the following we will use so called matrix Chernoff-type bounds. Let us recall some results from statistics:
Theorem 1** (Bernstein [Ber27]).**
Let be random variables and let , such that is the expectation value and , is bounded and are independent, identically distributed copies. Then, for all ,
[TABLE]
This fundamental theorem in statistics is making use of the independence of the sampling process in order to obtain a concentration of the result in high probability. In order to provide bounds for Hamiltonian simulation, we will need to use matrix versions of these Chernoff-style results. We will thereby make certain assumptions about the matrix, such as for instance that it is bounded in norm, and that the matrix variance statistic - a quantity that is a generalization of the variance - has a certain value. We now state first the result and then prove it.
Lemma 2**.**
(Faulty Hamiltonian simulator)* Hamiltonian simulation of a Hamiltonian operator with a faulty simulator that induces random error terms (random matrices) with expectation value with bounded norm for all and bounded matrix variance statistic in each term of the simulation can be simulated with an error less than using steps with probability of at least*
[TABLE]
Proof.
To prove this we will need a theorem that was developed independently in the two papers [Tro12, Oli09], which is a matrix extension of Bernstein’s inequality. Recall that the standard Bernstein inequality is a concentration bound for random variables with bounded norm, i.e. it tells us that a sum of random variables remains, with high probability, close to the expectation value. This can be extended to matrices which are drawn form a certain distribution and have a given upper bound to the norm. We call a random matrix independent and centered if each entry is independently drawn from the other entries and the expectation of the matrix is the zero matrix.
Theorem 2** (Matrix Bernstein).**
Let be independent, centered random matrices with dimensionality , and assume that each one is uniformly bounded
[TABLE]
We define the sum of these random matrices , with matrix variance statistic of the sum being
[TABLE]
where . Then
[TABLE]
Furthermore,
[TABLE]
Let us then recall the error in the Hamiltonian simulation scheme from above.
[TABLE]
We then use the assumption that the matrix variance statistic is bounded and that all the are bounded in norm by in order to be able to apply the above theorem. Using theorem 2 in order to probabilistically bound the first term, and observing that for we can bound the second term by , assuming that and using theorem 2 we achieve the proposed Lemma. ∎
For a more in depth analysis of Hamiltonian simulation and errors we refer the reader to [CMP17].
2.4.1 Modern methods for Hamiltonian simulation
Modern approaches like fractional-query model [Cle+09] are more complicated and we will not describe these here. However, these allow for tighter bounds and faster Hamiltonian simulation, with improved dependency on all parameters.
A conceptually different approach to Hamiltonian simulation based on Szegedy’s quantum walk [Sze04] uses the notion of a discrete-time quantum walk that is closely related to any given time-independent Hamiltonian and applies phase estimation in order to simulate the evolution. This approach has the best known performance as a function of the sparsity and evolution time but has a worse -dependency, i.e. in the error. This improved method for Hamiltonian simulation scales as for a fixed Hamiltonian.
Other recent results based on different methods approach optimality, i.e. linear dependency in the parameters. The fact that such exponentials of the Hamiltonian can be easily performed on a quantum computer is essential to the HHL algorithm because it allows us to perform eigenvalue estimation, which we will discuss below.
2.5 Quantum phase estimation
The goal of quantum phase estimation [Kit95] is to obtain a good approximation of an operator’s eigenvalue given the associated eigenstate. Here, we consider a unitary operator acting on an -qubit state, with a set of given eigenvectors and associated unknown eigenvalues . For simplicity, we will consider a particular given eigenvector with associated unknown eigenvalue . This eigenvalue is a complex number and we can thus write , where is referred to as the phase. Thus, we wish to determine a good -bit approximation of , which will thus allow for a good -bit approximation of . This will be achieved by requiring ancillary qubits. The intuition is to encode this approximation within relative phases of the qubits, as we previously saw with the QFT, see section 2.2.
In first instance, we note that . To start with, we are given qubits prepared in the state and an -qubit quantum state intialised in the state. Next, Hadamard gates are applied to the qubits in the first register, which results in the state , where .
Then, in order to obtain the -bit approximation of the eigenvalue, we will apply unitary operators to the state . More specifically, the controlled- operator is applied, where is the control qubit, with for the first up to for the last qubit, as illustrated in Figure 1. The sequence of controlled- operations used in phase estimation can be implemented efficiently using the technique of modular exponentiation, which is discussed in depth in [NC02][Box 5.2, Ch. 5.3.1]. This results in the state:
[TABLE]
In the following, we wish to consider to bits of accuracy, where the -bit approximation of is given by . In all generality, the phase can be expressed as:
[TABLE]
where we have that or alternatively . Substituting into 50 and dividing numerator and denominator by we have
[TABLE]
which it is easy to recognise is simply the QFT applied to the state . Thus, performing a measurement in the Fourier basis gives the bit string . In the case where , the measurement will yield the original state . If , then the measurement will have to be repeated, in which case an upper bound on the necessary number of repetitions can be obtained.
Thus, quantum phase estimation relies on preparing ancillary qubits in equal superposition, applying controlled unitary operators to the given eigenstate, and finally performing a measurement in the Fourier basis, as illustrated in Figure 2.
We can summarize the phase estimation procedure in the following Theorem:
Theorem 3** (Phase estimation [Kit95]).**
Let unitary with for . There is a quantum algorithm that transforms such that for all with probability in time , where is the time to implement .
Crucially, we do not need to be given access to the actual eigenvector , as this mapping can be applied to a superposition of the eigenvectors. Indeed, any quantum state can be decomposed in an arbitrary orthonormal basis, such as for instance in the operator eigenbasis :
[TABLE]
where . Hence the quantum phase estimation procedure can be applied to an arbitrary state , which, as it is just a matter of representation, be directly applied to the operator eigenbasis, apply this mapping in the specific (eigen-)basis without knowing the actual basis:
[TABLE]
Next, we consider the process of phase kickback, where we query an oracle and encode some information pertaining to it as a relative phase.
2.6 Phase kickback
In the following, we consider a Boolean function . The function is queried via an oracle , and so
[TABLE]
where is an input state and where is an ancillary register. This operation can be implemented by a unitary circuit .
If the ancillary qubit is in the state , then by applying the oracle we obtain the state:
[TABLE]
where denotes the negated bits. By considering the cases where the output is either a or a [math], it can easily be shown that this is equivalent to the state:
[TABLE]
Thus, inputs which evaluate to acquire a relative phase. This process is referred to as phase kickback. Finally, we note that we have assumed that the function can be classically computed in polynomial time, i.e. this is not an expensive step and no complexity is hidden in this call.
2.7 Amplitude amplification
Amplitude amplification [Bra+02] is an extension of Grover’s search algorithm [GR02]. Here, we shall present Grover’s search algorithm, then show how this leads to amplitude amplification.
We are given a set containing elements and the goal is to find a particular element of the set which is marked. This may be modeled by the function such that there exists uniquely one item satisfying . Otherwise we have that for all . Furthermore, we can evaluate using an oracle that can be queried in superposition with unit computational cost, see section 2.6. Grover’s algorithm is for our purposes more appropriately seen as an algorithm for finding the (unique) root of the Boolean function , i.e. replace our set with the bitstring representations of . Then is the bitstring such that , or the root of . We shall show later how Grover’s algorithm generalises to finding all roots of a Boolean function .
Classically, finding requires oracle queries, where in the worst case we evaluate on all elements in the set. In contrast, Grover’s algorithm achieves a quadratic speed-up requiring oracle queries. Furthermore, it has been shown that there is a lower bound on the number of queries, that is, this is the optimal scaling [DH01].
Grover’s algorithm uses the phase kickback technique previously discussed in section 2.6, which associates a relative phase with the marked item. In order to do this, qubits are prepared in the state, and by the application of the operator , the uniform superposition state is obtained. An ancillary qubit is prepared in the state. By applying the phase kickback protocol, from Eq. (55) and (56), we obtain . We now discard the second register. The basis state corresponding to the marked item has now acquired a relative phase, and we are interested in the remaining state . We denote by the unitary operator that queries the oracle and applies the phase to each computational basis state .
Ultimately, a measurement in the computational basis is to be performed. Ideally, this would yield the computational basis state corresponding to the marked item with high probability. How can this be achieved? The idea is to apply a unitary operator to the input which will dampen the coefficients associated with unmarked items, and strengthen the coefficients corresponding to the marked item. For this to be practically achievable, we need to check that this operator has an efficient implementation.
The Grover operator, to be defined shortly, does precisely this in an efficient manner. The state can be expressed as a linear combination of basis terms , each with a corresponding complex coefficient . One of these corresponds to the marked item . The idea is to strengthen the coefficient whilst simultaneously weakening coefficients , where and .
The unitary operator which achieves this is called the Grover operator and is given by , where is called the diffusion operator. It is not a priori obvious what this operator does or why one would wish to apply it. There are two arguments which can shed insight into this, one algebraic and one geometric, which we next introduce.
Algebraic argument. First, we consider an arbitrary state . It is easy to see that applying the diffusion operator results in the state , where is defined as the mean value of the coefficients. Thus the new coefficient corresponding to is given by . Before the first application of , the mean is given by . Here, we have that the positive coefficients will be dampened and approach to zero, whereas the negative coefficients will be magnified and become positive. This is inversion about the mean. Next, the item is marked with a negative sign by in order for the inversion about the mean to be applied in the next step. As this process repeats, the unmarked items’ coefficients will tend to zero, whereas the marked coefficient goes towards one [Wha09].
Geometric argument. Strengthening means bringing the initial state closer to the state , whilst preserving the norm. Visually, this can be seen as performing a rotation of angle towards in the plane defined by , where . Let be the orthogonal complement of the marked item state in this subspace. Then is the angle between the equal superposition state and the orthogonal complement .
A rotation by an angle can be implemented via two successive reflections: one through and one through . A reflection about an axis mean that any component of a particular vector orthogonal to the axis acquire a negative phase, and the component along the axis remains invariant. Let be the axis of reflection, and let be the state to reflect. After reflection, we should have . This can be expressed as , which corresponds to application of the operator , up to a global phase. Thus, this gives us the reflection operation. In the case when we reflect about the axis we recover the diffusion operator. In the case where we reflect about we recover . Thus, in order to implement the rotation by an angle , we first apply a reflection about , followed by a reflection about . We see an illustration of this in Figure 3.
We wish to have a number of rotations such that a measurement in the computational basis yields with high probability. This probability, after rotations, is given by . To have this close to one, we need , which we have when . We have that but also . Using the small angle approximation, we have that and so . So, and thus Grover’s algorithm scales as .
This idea can be generalized to the case where we there are now marked items out of a total of items, where . First, we construct the states and the state over unmarked items , where are the marked elements and are the unmarked elements. Once again, the goal will be to obtain a marked state with high probability when a computational basis measurement is performed. That is, the coefficients corresponding to the marked item will be boosted whereas those corresponding to unmarked items dampened. Here, we can think of this as splitting the total space into two subspaces, the good subspace and the bad subspace. The good subspace corresponds to the marked basis states, i.e. those containing relevant information, which we would wish to obtain upon performing a measurement, and thus boost their corresponding amplitudes. We have that , and thus we can write any arbitrary quantum state as
[TABLE]
where and are two orthogonal states, and where we have that . In the context of Grover search, we have , and , and thus we can write the complete state as
[TABLE]
i.e. and . The goal is to now, via the application of a unitary operator, amplify the coefficient whilst weakening . Geometrically, this means that the quantum state will be rotated towards the good subspace.
Amplitude amplification is the process of applying Grover’s algorithm to tasks where we have an oracle for a function and need to sample from the ‘good’ subset of strings, i.e. , more efficiently than with a classical algorithm. By querying the oracle times the amplitude of the ‘good’ subset of strings is then close to unity and the ‘bad’ amplitude is close to zero. Stated more generally, this gives us
Lemma 3**.**
(Amplitude Amplification)* Suppose we have an algorithm that succeeds with probability . Using amplitude amplification, we can take repetitions of to yield an algorithm with success probability arbitrarily close to one.*
Note that can be a classical or quantum algorithm and that we obtain the lemma by taking the ‘good’ subspace as successful bitstring outputs of and the ‘bad’ subspace as the unsuccessful outputs. One can do this by simply appending a bit at the end of the evaluation of the result of with ‘1’ for success and ‘0’ for failure.
2.8 The uncompute trick
The uncompute trick is a commonly used technique in quantum algorithms for carrying out a computation, then retrieving the initial state. For this subsection, we take much of the presentation from the discussion at [Unc]. Previously, in section 2.6, we saw that given a boolean function , there exists an oracle acting as , which allows for the mapping to be enacted. Yet, we did not discuss how this unitary operator could be efficiently implemented. In particular, from the no-deleting theorem [KB00] there is no single-qubit unitary operator that sets an arbitrary qubit state to . Indeed, for most algorithms we have the map , where is a garbage state in a working register we have used along the way. Here, we wish to return the garbage state to in the working register, so that it doesn’t disrupt future computations after we discard it. More precisely, we assume in general for any quantum algorithm that the working register is initialised in state . If a previous computation has left the working register state as the next algorithm to use the working register will output incorrect results. Even worse, in the case that the mapping isn’t perfect, the working register and output register are entangled. That is, we have some state and operations on the garbage register will affect the output register. Moreover, we wish to keep the input vector . Let us see how this is achieved.
Suppose we have a unitary operation that takes an input and produces as output the state , where is in the input register, is in the working space and is in the output register, and , the output of the computation. Ideally, we would have that , and in this case the output is given by the state , i.e. . If an additional computational register is added, and apply the CNOT gate controlled on the third register, giving . Then, if the inverse operator is applied to the first three registers, then the state evolves to . Finally, applying a SWAP operator111The SWAP operator, as the name suggests, swaps the state between two registers on the same number of qubits, i.e., . on the last two registers produces the state . We can now safely discard the working register as well as the ancillary register, leaving us as desired.
This action of applying , appending an additional register, applying the CNOT, then applying followed by a SWAP is known as the uncompute trick. It allows one to record the final state of a quantum computation and then reuse the working register for some other task.
By assuming in the discussion above, we assumed that the action of was error-free, which is a highly unrealistic scenario. We now assume an error probability of , that is,
[TABLE]
The output state after the uncompute operation, that is – applying the oracle, appending the ancillary register and applying the CNOT – is given by , which is different to the ideal final state . The inner product gives
[TABLE]
Finally, the inverse operator is applied, which preserves the inner product, and thus we have that . Thus, we have that if the unitary acts to within error , the mapping can be enacted to within error .
2.9 Quantum RAM
In the HHL algorithm, a real-valued vector has to be manipulated by the quantum computer. That is, it must be loaded into a computational register, where the elements of the vector will be encoded in the amplitudes of a quantum state. As quantum states are normalised, these amplitudes will be the elements of the vector scaled by the norm of the vector.
More precisely, let be the input vector and let be a quantum state on qubits. We would like to have an operation , that takes some finite precision representation of ,which we call , and outputs the state , along with i.e.
[TABLE]
where is a computational basis state encoding the value of to some finite precision (denoted by the tilde on top).
The operation is known as a quantum RAM (qRAM) and is non-trivial to implement. For instance, a linear system can be classically solved in polynomial time. Thus, a necessary condition to obtain a quantum exponential speed-up is for to run in time at most polylogarithmic in . This statement holds if we use a qRAM for any task that is polynomial-time computable classically.
Here, we present a memory structure used to implement it, taken from the PhD thesis of Prakash [Pra14] along with the state preparation procedure of Grover and Rudolph [GR02]. We shall say that this is a classical data structure with quantum access, in that, it stores classical information, but can be accessed in quantum superposition. This can be implemented with an ordinary quantum circuit.
First, we consider the following lemma:
Lemma 4**.**
(Controlled rotation)* Let and let be its -bit finite precision representation. Then there is a unitary, , that acts as*
[TABLE]
Proof.
Let
[TABLE]
where \sigma_{y}=\smallmatrixquantity(0&-i\\ i&0) is the Pauli matrix. The matrix is given by \exp(-i\theta\sigma_{y})=\smallmatrixquantity(\cos\theta&-\sin\theta\\ \sin\theta&\cos\theta). Finally, applying to yields the result in Eq. (62). ∎
We should note that the unitary can be implemented in