Random tensor theory: extending random matrix theory to random product states
Andris Ambainis, Aram W. Harrow, Matthew B. Hastings

TL;DR
This paper extends random matrix theory to analyze the spectral properties of sums of random product states in high-dimensional tensor spaces, with implications for quantum information and data-hiding schemes.
Contribution
It introduces three novel methods—diagrammatic, combinatorial, and recursive—for analyzing mixtures of random product states beyond traditional matrix ensembles.
Findings
Largest eigenvalue approximates (1+sqrt{p/d^k})^2 for k>1
Spectral density approaches Marcenko-Pastur law
Implications for quantum data-hiding schemes
Abstract
We consider a problem in random matrix theory that is inspired by quantum information theory: determining the largest eigenvalue of a sum of p random product states in (C^d)^{otimes k}, where k and p/d^k are fixed while d grows. When k=1, the Marcenko-Pastur law determines (up to small corrections) not only the largest eigenvalue ((1+sqrt{p/d^k})^2) but the smallest eigenvalue (min(0,1-sqrt{p/d^k})^2) and the spectral density in between. We use the method of moments to show that for k>1 the largest eigenvalue is still approximately (1+sqrt{p/d^k})^2 and the spectral density approaches that of the Marcenko-Pastur law, generalizing the random matrix theory result to the random tensor case. Our bound on the largest eigenvalue has implications both for sampling from a particular heavy-tailed distribution and for a recently proposed quantum data-hiding and correlation-locking scheme due to…
Click any figure to enlarge with its caption.
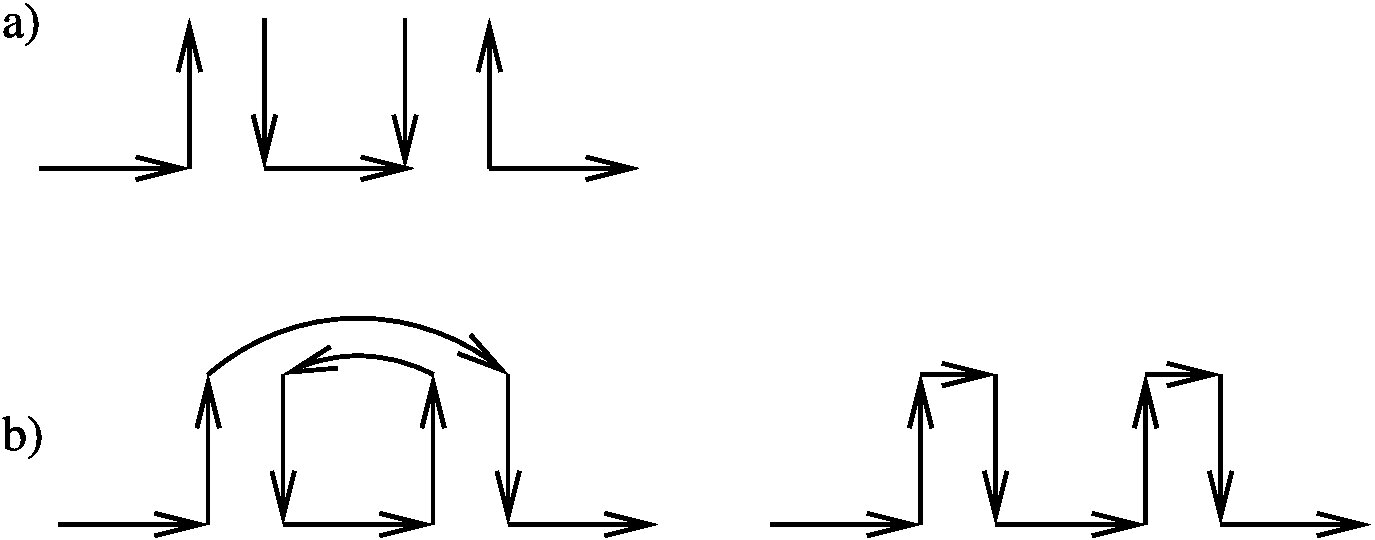 Figure 1
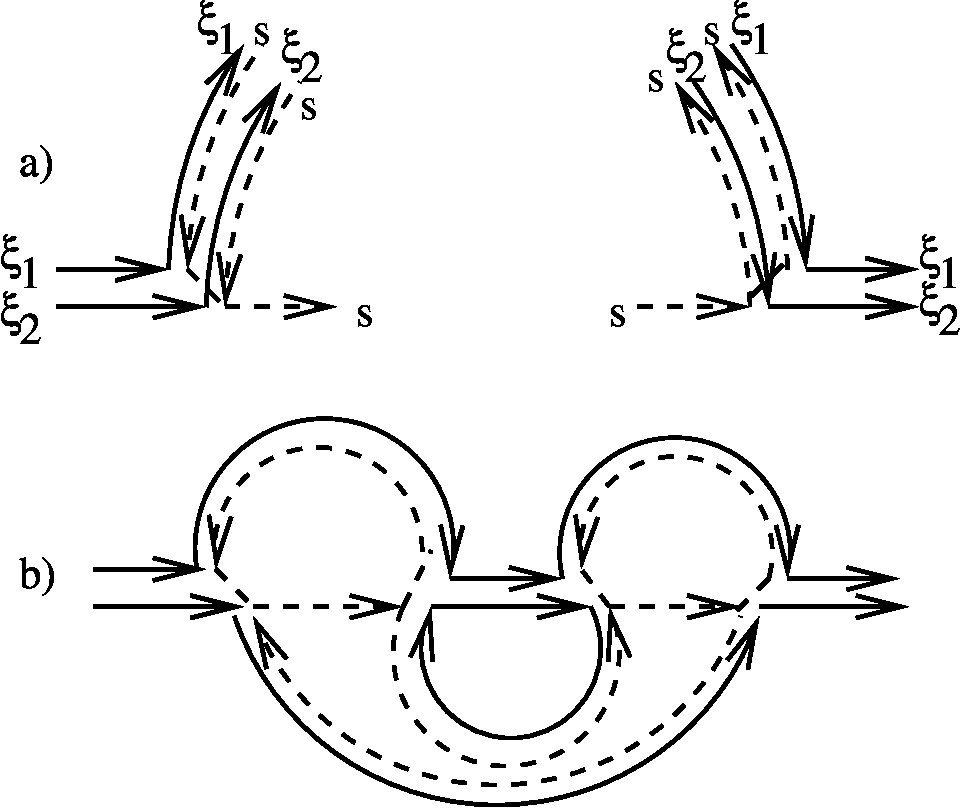 Figure 2
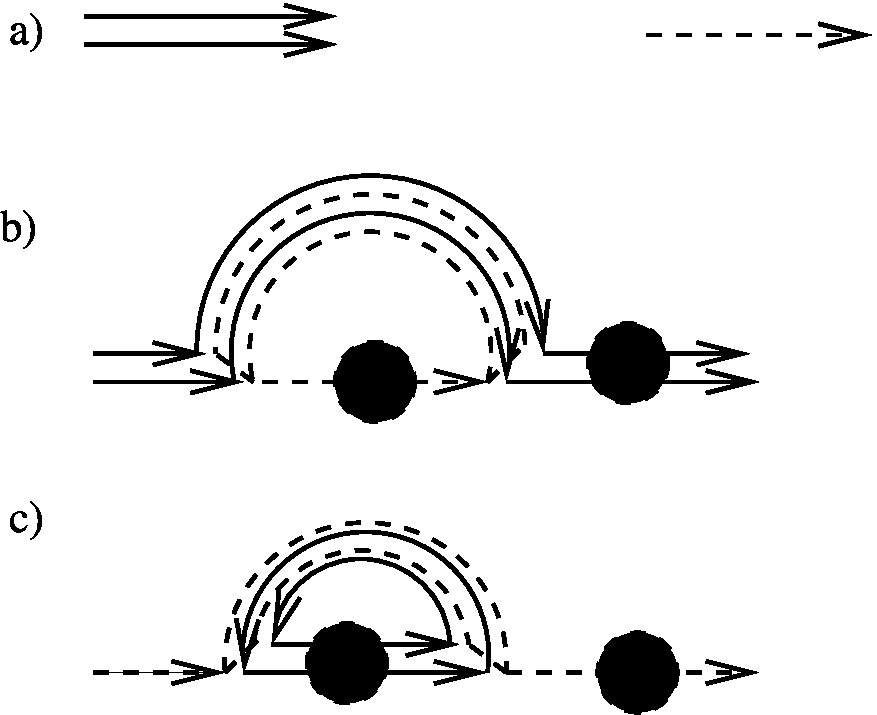 Figure 3
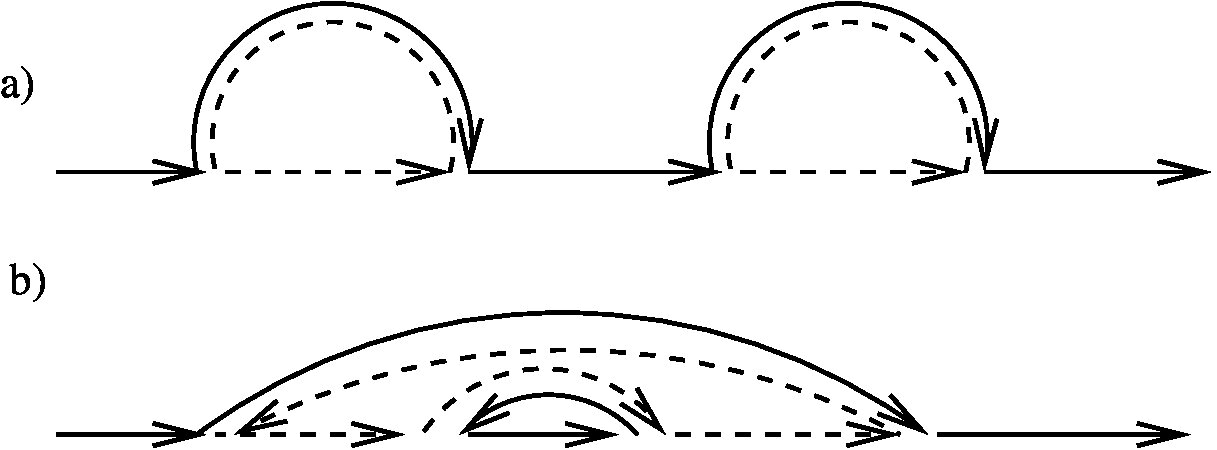 Figure 4
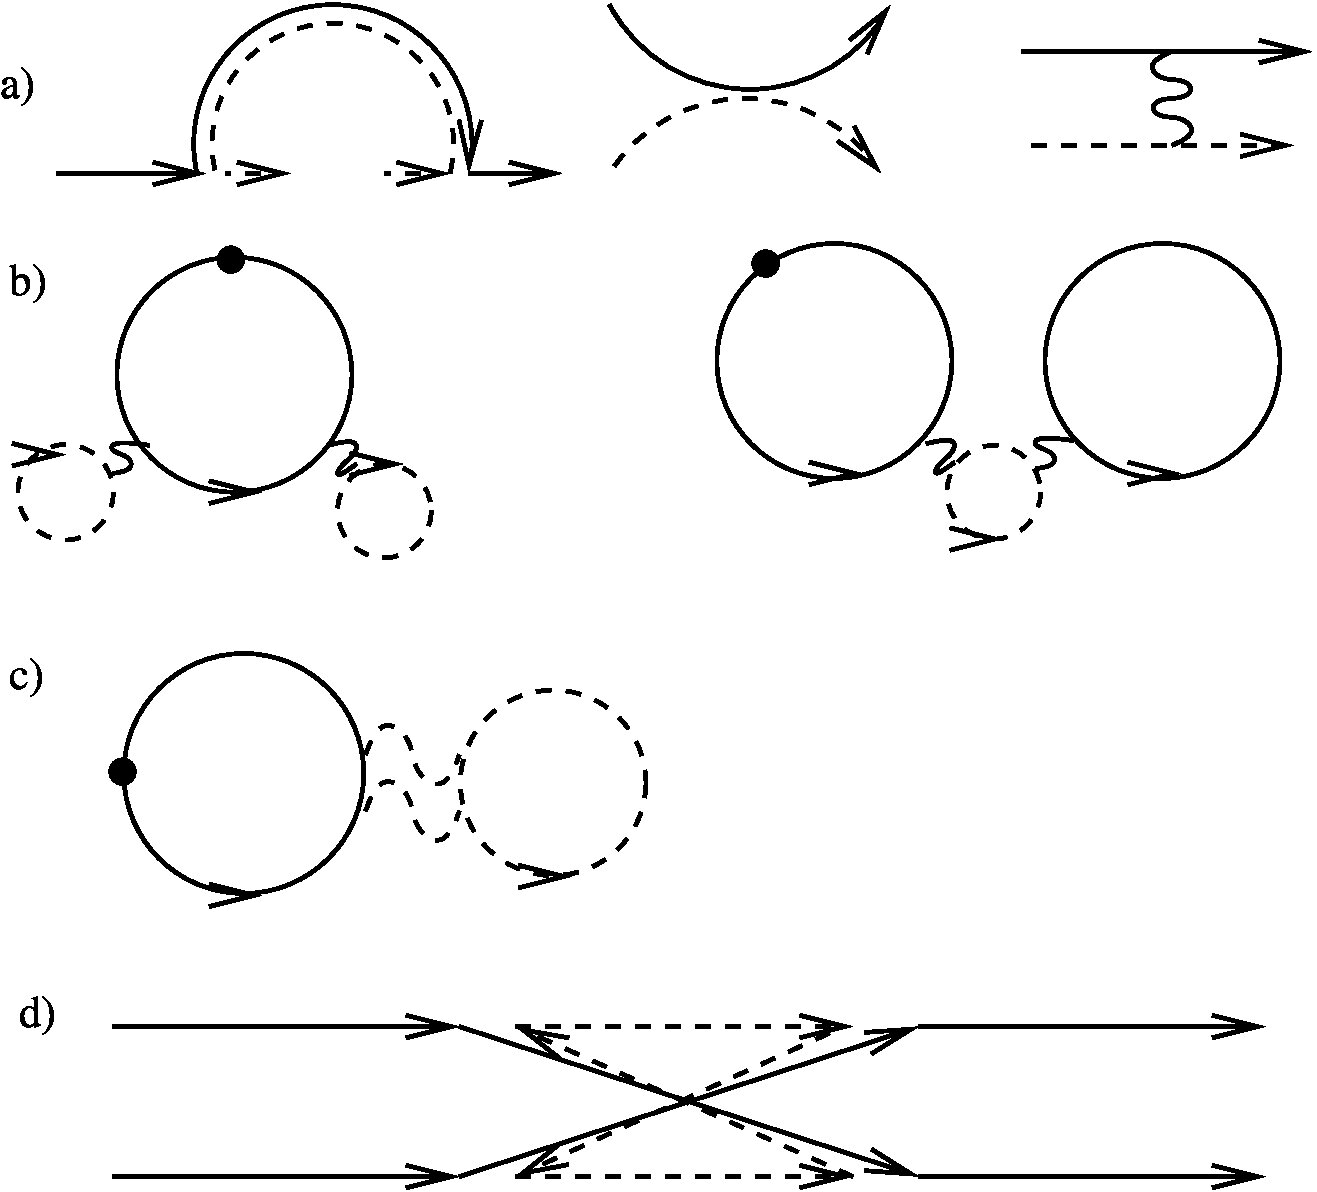 Figure 5
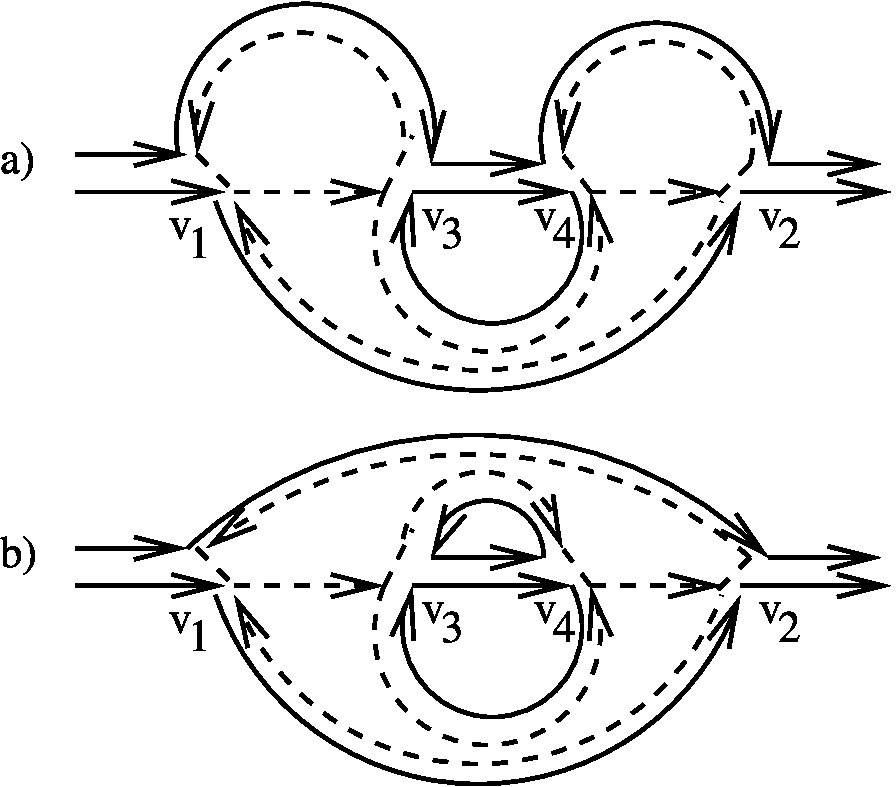 Figure 6
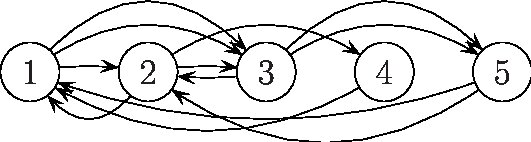 Figure 7
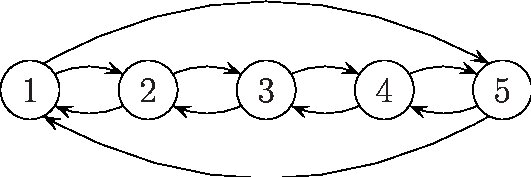 Figure 8
 Figure 9
 Figure 10
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
Random tensor theory: extending random matrix theory to
mixtures of random product states
A. Ambainis
Faculty of Computing, University of Latvia, Riga, Latvia
A. W. Harrow
Department of Mathematics, University of Bristol, Bristol, U.K.
M. B. Hastings
Microsoft Research, Station Q, CNSI Building, University of California, Santa Barbara, CA, 93106
Abstract
We consider a problem in random matrix theory that is inspired by quantum information theory: determining the largest eigenvalue of a sum of random product states in , where and are fixed while . When , the Marčenko-Pastur law determines (up to small corrections) not only the largest eigenvalue () but the smallest eigenvalue and the spectral density in between. We use the method of moments to show that for the largest eigenvalue is still approximately and the spectral density approaches that of the Marčenko-Pastur law, generalizing the random matrix theory result to the random tensor case. Our bound on the largest eigenvalue has implications both for sampling from a particular heavy-tailed distribution and for a recently proposed quantum data-hiding and correlation-locking scheme due to Leung and Winter.
Since the matrices we consider have neither independent entries nor unitary invariance, we need to develop new techniques for their analysis. The main contribution of this paper is to give three different methods for analyzing mixtures of random product states: a diagrammatic approach based on Gaussian integrals, a combinatorial method that looks at the cycle decompositions of permutations and a recursive method that uses a variant of the Schwinger-Dyson equations.
I Introduction and related work
I.1 Background
A classical problem in probability is to throw balls into bins and to observe the maximum occupancy of any bin. If we set the ratio to a constant and take large, this maximum occupancy is with high probability (in fact, this bound is tight, but we will not discuss that here). There are two natural ways to prove this, which we call the large deviation method and the trace method. First, we describe the large deviation method. If the occupancies of the bins are , then each is distributed approximately according to a Poisson distribution with parameter ; i.e. . Choosing implies that for each . Thus, the union bound implies that with high probability all of the are . More generally, the large deviation method proceeds by: (1) representing a bad event (here, maximum occupancy being too large) as the union of many simpler bad events (here, any one being too large), then (2) showing that each individual bad event is very unlikely, and (3) using the union bound to conclude that with high probability none of the bad events occur. This method has been used with great success throughout classical and quantum information theory HLSW04 ; HLW06 ; Ledoux .
This paper will discuss a problem in quantum information theory where the large deviation method fails. We will show how instead a technique called the trace method can be effectively used. For the problem of balls into bins, the trace method starts with the bound , where is a large positive integer. Next, we take the expectation of both sides and use convexity to show that
[TABLE]
Choosing to minimize the right-hand side can be shown to yield the optimal bound for the expected maximum occupancy. In general, this approach is tight up to the factor of .
The quantum analogue of balls-into-bins problem is to choose random unit vectors from and to consider the spectrum of the matrix
[TABLE]
where we use to denote . Again we are interested in the regime where is fixed and . We refer to this case as the “normalized ensemble.” We also consider a slightly modified version of the problem in which the states are drawn from a complex Gaussian distribution with unit variance, so that the expectation of is equal to one. Call the ensemble in the modified problem the “Gaussian ensemble” and define . Note that , where is a matrix where each entry is an i.i.d. complex Gaussian variable with variance . That is, , with i.i.d. real Gaussians each with mean zero and variance .
What we call the Gaussian ensemble is more conventionally known as the Wishart distribution, and has been extensively studied. Additionally, we will see in Section II.1 that the normalized ensemble is nearly the same as the Gaussian ensemble for large . In either version of the quantum problem, the larger space from which we draw vectors means fewer collisions than in the discrete classical case. The nonzero part of the spectrum of has been well studiedVerbaar94a ; Verbaar94b ; FZ97 , and it lies almost entirely between as . This can be proven using a variety of techniques. When is drawn according to the Gaussian ensemble, its spectrum is described by chiral random matrix theoryVerbaar94a ; Verbaar94b . This follows from the fact that the spectrum of has the same distribution as the spectrum of the square of the matrix
[TABLE]
where is defined above. A variety of techniques have been used to compute the spectrumFZ97 ; Anderson91a ; Anderson91b ; MP93 . The ability to use Dyson gas methods, or to perform exact integrals over the unitary group with a Kazakov technique, has allowed even the detailed structure of the eigenvalue spectrum near the edge to be worked out for this chiral random matrix problem.
A large-deviation approach for the case was given in (LW-locking, , appendix B). In order to bound the spectrum of , they instead studied the Gram matrix , which has the same spectrum as . Next they considered for a random choice of . This quantity has expectation 1 and, by Levy’s lemma, is within of its expectation with probability . On the other hand, , which can be covered by an -net of size . Thus the entire spectrum of (and equivalently ) will be contained in with high probability, where is a function of that approaches 0 as .
In this paper, we consider a variant of the above quantum problem in which none of the techniques described above is directly applicable. We choose our states to be product states in ; i.e.
[TABLE]
for . We choose the individual states again either uniformly from all unit vectors in (the normalized product ensemble) or as Gaussian-distributed vectors with (the Gaussian product ensemble). The corresponding matrices are and respectively. Note that corresponds to the case considered above; i.e. and . We are interested in the case when is fixed. As above, we also fix the parameter , while we take . And as above, we would like to show that the spectrum lies almost entirely within the region with high probability.
However, the Dyson gas and Kazakov techniquesFZ97 ; Anderson91a ; Anderson91b ; MP93 that were used for are not available for , which may be considered a problem of random tensor theory. The difficulty is that we have a matrix with non-i.i.d. entries and with unitary symmetry only within the subsystems. Furthermore, large-deviation techniques are known to work only in the limits. Here, Ref. Rudelson can prove that with high probability, which gives the right leading-order behavior only when