A Convergent Online Single Time Scale Actor Critic Algorithm
D. Di Castro, R. Meir

TL;DR
This paper introduces a novel online actor-critic reinforcement learning algorithm where both actor and critic operate on the same time scale, simplifying convergence analysis and potentially enhancing biological plausibility.
Contribution
It presents a convergent single time scale actor-critic algorithm using temporal difference learning, unlike previous methods requiring different time scales for convergence.
Findings
Converges to a neighborhood of a local maximum of average reward.
Uses the same temporal difference signal for both actor and critic.
Operates with both components on a similar time scale.
Abstract
Actor-Critic based approaches were among the first to address reinforcement learning in a general setting. Recently, these algorithms have gained renewed interest due to their generality, good convergence properties, and possible biological relevance. In this paper, we introduce an online temporal difference based actor-critic algorithm which is proved to converge to a neighborhood of a local maximum of the average reward. Linear function approximation is used by the critic in order estimate the value function, and the temporal difference signal, which is passed from the critic to the actor. The main distinguishing feature of the present convergence proof is that both the actor and the critic operate on a similar time scale, while in most current convergence proofs they are required to have very different time scales in order to converge. Moreover, the same temporal difference signal is…
Click any figure to enlarge with its caption.
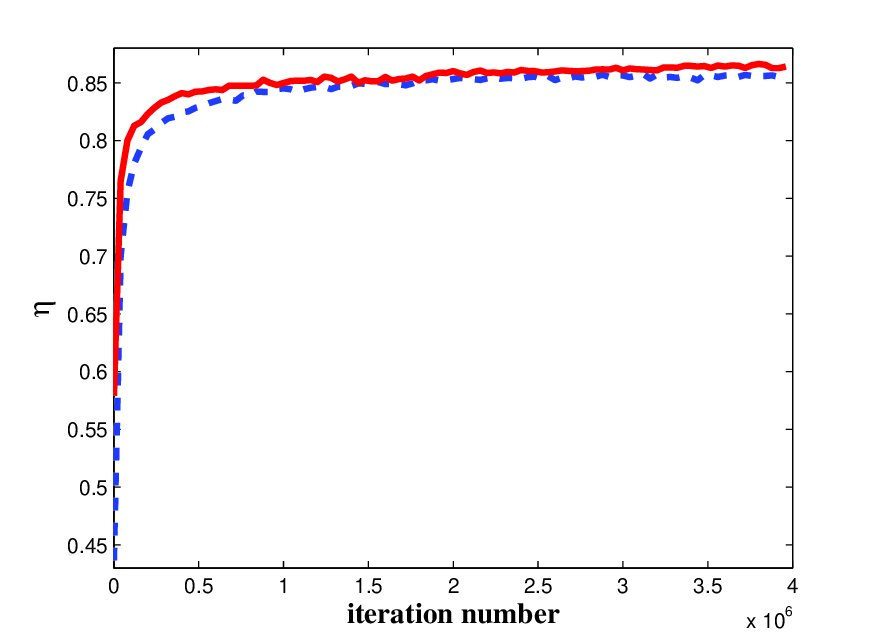 Figure 1
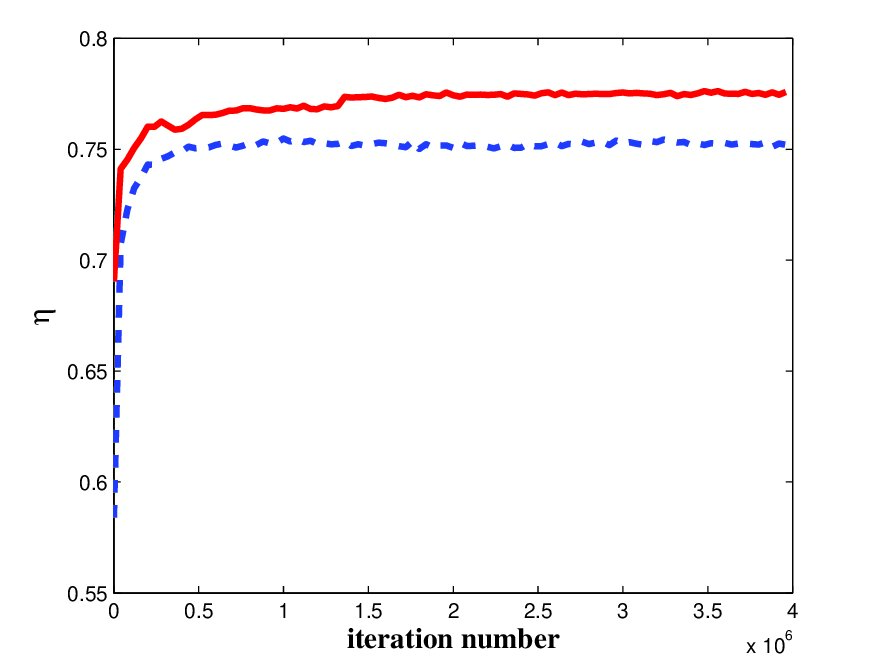 Figure 2
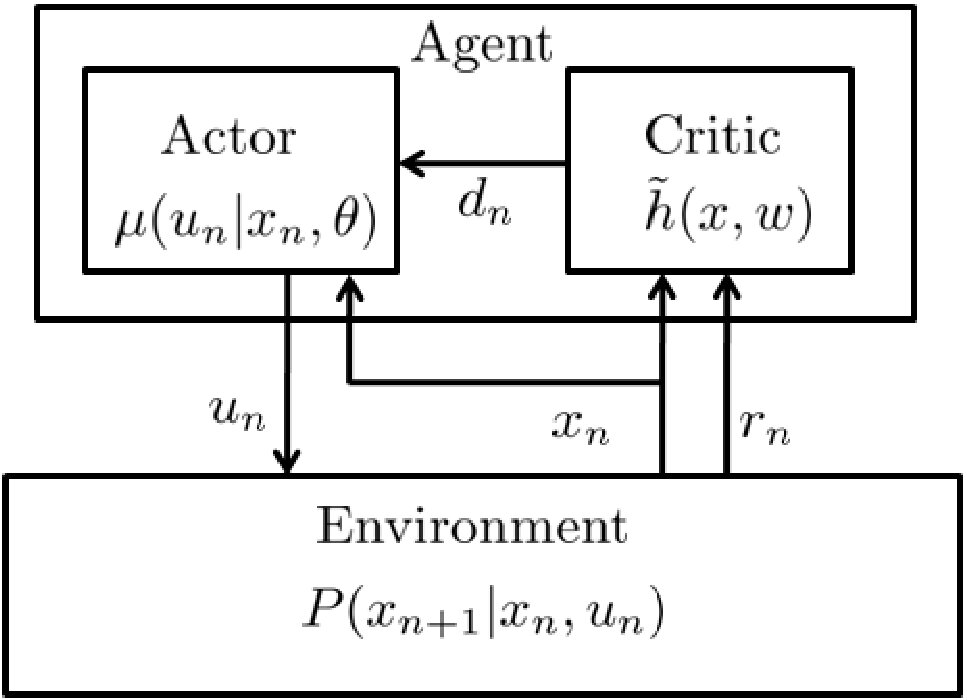 Figure 3
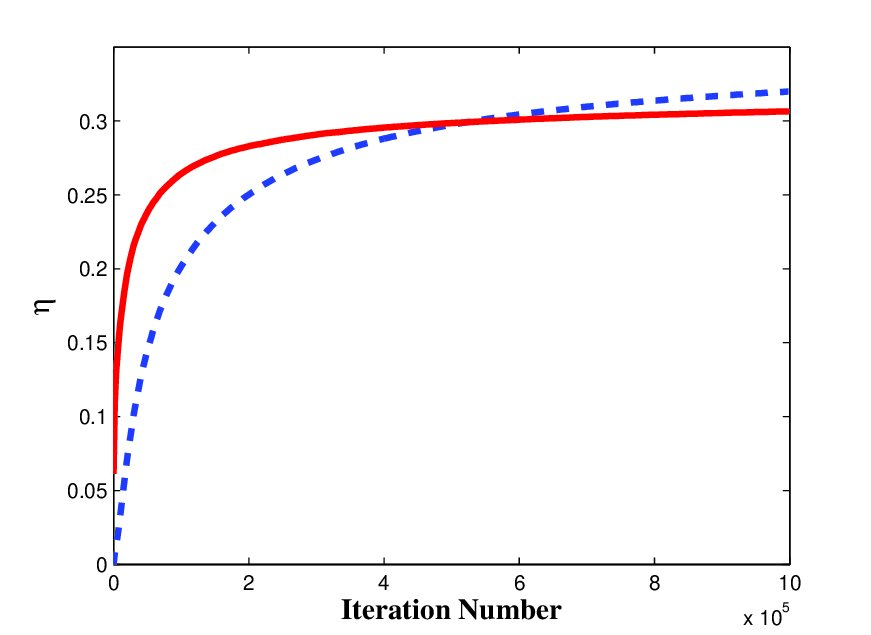 Figure 4
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
Taxonomy
TopicsMultimedia Communication and Technology · Online Learning and Analytics
A Convergent Online Single Time Scale Actor Critic Algorithm
\nameDotan Di Castro \[email protected] \name\AND\nameRon Meir \[email protected] \AND\name\addrDepartment of Electrical Engineering, Technion, Haifa 32000, Israel
Abstract
Actor-Critic based approaches were among the first to address reinforcement learning in a general setting. Recently, these algorithms have gained renewed interest due to their generality, good convergence properties, and possible biological relevance. In this paper, we introduce an online temporal difference based actor-critic algorithm which is proved to converge to a neighborhood of a local maximum of the average reward. Linear function approximation is used by the critic in order estimate the value function, and the temporal difference signal, which is passed from the critic to the actor. The main distinguishing feature of the present convergence proof is that both the actor and the critic operate on a similar time scale, while in most current convergence proofs they are required to have very different time scales in order to converge. Moreover, the same temporal difference signal is used to update the parameters of both the actor and the critic. A limitation of the proposed approach, compared to results available for two time scale convergence, is that convergence is guaranteed only to a neighborhood of an optimal value, rather to an optimal value itself. The single time scale and identical temporal difference signal used by the actor and the critic, may provide a step towards constructing more biologically realistic models of reinforcement learning in the brain.
1 Introduction
In Reinforcement Learning (RL) an agent attempts to improve its performance over time at a given task, based on continual interaction with the (usually unknown) environment (Bertsekas and Tsitsiklis (1996); Sutton and Barto (1998)). Formally, it is the problem of mapping situations to actions in order to maximize a given average reward signal. The interaction between the agent and the environment is modeled mathematically as a Markov Decision Process (MDP). Approaches based on a direct interaction with the environment, are referred to as simulation based algorithms, and will form the major focus of this paper.
A well known subclass of RL approaches consists of the so called actor-critic (AC) algorithms (e.g., Sutton and Barto (1998)), where the agent is divided into two components, an actor and a critic. The critic functions as a value estimator, whereas the actor attempts to select actions based on the value estimated by the critic. These two components solve their own problems separately but interactively. Many methods for solving the critic’s value estimation problem, for a fixed policy, have been proposed, but, arguably, the most widely used is temporal difference (TD) learning. TD learning was demonstrated to accelerate convergence by trading bias for variance effectively Singh and Dayan (1998), and is often used as a component of AC algorithms.
In general, policy selection may be randomized. When facing problems with a large number of states or actions (or even continuous state-action problems), effective policy selection may suffer from several problems, such as slow convergence rate or an inefficient representation of the policy. A possible approach to policy learning is the so-called policy gradient method (Baxter and Bartlett (2001); Cao (2007); Cao and Chen (1997); Konda and Tsitsiklis (2003); Marbach and Tsitsiklis (1998)). Instead of maintaining a separate estimate for the value for each state (or state-action pair), the agent maintains a parametrized policy function. The policy function is taken to be a differentiable function of a parameter vector and of the state. Given the performance measure, depending on the agent’s policy parameters, these parameters are updated using a sampling-based estimate of the gradient of the average reward. While such approaches can be proved to converge under certain conditions (e.g., Baxter and Bartlett (2001)), they often lead to slow convergence, due to very high variance. A more general approach based on sensitivity analysis, which includes policy gradient methods as well as non-parametric average reward functions, has been discussed in depth in the recent manuscript by Cao (2007).
Several AC algorithms with associated convergence proofs have been proposed recently (a short review is given in section 2.2). As far as we are aware, all the convergence results for these algorithms are based on two time scales, specifically, the actor is assumed to update its internal parameters on a much slower time scale than the one used by the critic. The intuitive reason for this time scale separation is clear, since the actor improves its policy based on the critic’s estimates. It can be expected that rapid change of the policy parameters may not allow the critic to effectively evaluate the value function, which may lead to instability when used by the actor in order to re-update its parameters.
The objective of this paper is to propose an online AC algorithm and establish its convergence under conditions which do not require the separation into two time scales. There is clear theoretical motivation for such an approach, as it can potentially lead to faster convergence rates, although this is not a an issue we stress in this work. In fact, our motivation for the current direction was based on the possible relevance of AC algorithms in a biological context (e.g, Daw et al. (2006)), where it would be difficult to justify two very different time scales operating within the same anatomical structure. We refer the reader to DiCastro et al. (2008) for some preliminary ideas and references related to these issues. Given the weaker conditions assumed on the time scales, our convergence result is, not surprisingly, somewhat weaker than that provided recently in (e.g., Bhatnagar et al. (2008a, b)), as we are not ensured to converge to a local optimum, but only to a neighborhood of such an optimum. Nevertheless, it is shown that the neighborhood size can be algorithmically controlled. Further comparative discussion can be found in section 2.
This paper is organized as follows. In section 2 we briefly recapitulate current AC algorithms for which convergence proofs are available. In section 3, we formally introduce the problem setup. We begin section 4 by relating the TD signal to the gradient of the average reward, and then move on to motivate and derive the main AC algorithm, concluding the section with a convergence proof. A comparative discussion of the main features of our approach is presented in section 5, followed by some simulation results in section 6. Finally, in section 7, we discuss the results and point out possible future work. In order to facilitate the readability of the paper, we have relegated all technical proofs to appendices.
2 Previous Work
In this section we briefly review some previous work in RL which bears direct relevance to our work. While many AC algorithms have been introduced over the years, we focus only on those for which a convergence proof is available, since the main focus of this work is on convergence issues, rather than on establishing the most practically effective algorithms (see, for example, Peters and Schaal (2008), for promising applications of AC algorithms in a robotic setting).
2.1 Direct policy gradient algorithms
Direct policy gradient algorithms, employing agents which consist of an actor only, typically estimate a noisy gradient of the average reward, and are relatively close in their characteristics to AC algorithms. The main difference from the latter is that the agent does not maintain a separate value estimator for each state, but rather interacts with the environment directly, and in a sense maintains its value estimate implicitly through a mapping which signifies which path the agent should take in order to maximize its average reward per stage.
Marbach and Tsitsiklis (1998) suggested an algorithm for non-discounted environments. The gradient estimate is based on an estimate of the state values which the actor estimates while interacting with the environment. If the actor returns to a sequence of previously visited states, it re-estimates the states value, not taking into account its previous visits. This approach often results in large estimation variance.
Baxter and Bartlett (2001) proposed an online algorithm for partially observable MDPs. In this algorithm, the agent estimates the expected average reward for the non-discounted problems through an estimate of the value function of a related discounted problem. It was shown that when the discount factor approaches , the related discounted problem approximates the average reward per stage. Similar to the algorithms in (Marbach and Tsitsiklis (1998)), it suffers from relatively large estimation variance. In (Baxter et al. (2004)), a method was proposed for coping with the large variance by adding a baseline to the value function estimation.
2.2 Actor Critic Algorithms
As stated in section 1, the convergence proofs of which we are aware for AC algorithms are based on two time scale stochastic approximation (Borkar (1997)), where the actor is assumed to operate on a time scale which is much slower than that used by the critic.
Konda and Borkar (1999) suggested a set of AC algorithms. In two of their algorithms (Algorithms 3 and 6), parametrized policy based actors were used while the critic was based on a lookup table. Those algorithms and their convergence proofs were specific to the Gibbs policy function in the actor.
As far as we are aware, Konda and Tsitsiklis (2003) provided the first convergence proof for an AC algorithm based on function approximation. The information passed from the critic to the actor is the critic’s action-value function, and the critic’s basis functions, which are explicitly used by the actor. They provided a convergence proof of their TD() algorithm where approaches . A drawback of the algorithm is that the actor and the critic must share the information regarding the actor’s parameters. This detailed information sharing is a clear handicap in a biological context, which was one of the driving forces for the present work.
Finally, Bhatnagar et al. (2008a, b) recently proposed an AC algorithm which closely resembles our proposed algorithm, and which was developed independently of ours. In this work the actor uses a parametrized policy function while the critic uses a function approximation for the state evaluation. The critic passes to the actor the TD(0) signal and based on it the actor estimates the average reward gradient. A detailed comparison will be provided in section 5. As pointed out in Bhatnagar et al. (2008a, b), their work is the first to provide a convergence proof for an AC algorithm incorporating bootstrapping Sutton and Barto (1998), where bootstrapping refers to a situation where estimates are updated based on other estimates, rather than on direct measurements (as in Monte Carlo approaches). This feature applies to our work as well. We also note that Bhatnagar et al. (2008a, b) extend their approach to the so-called natural gradient estimator, which has been shown to lead to improved convergence in supervised learning as well as RL. The present study focuses on the standard gradient estimate, leaving the extension to natural gradients to future work.
3 The Problem Setup
In this section we describe the formal problem setup, and present a sequence of assumptions and lemmas which will be used in order to prove convergence of Algorithm 1 in section 4. These assumptions and lemmas mainly concern the properties of the controlled Markov chain, which represents the environment, and the properties of the actor’s parametrized policy function.
3.1 The Dynamics of the Environment and of the Actor
We consider an agent, composed of an actor and a critic, interacting with an environment. We model the environment as a Markov Decision Process (MDP) Puterman (1994) in discrete time with a finite state set and an action set , which may be uncountable. We denote by the size of the set . Each selected action determines a stochastic matrix where is the transition probability from a state to a state given the control . For each state the agent receives a corresponding reward , which may be deterministic or random. In the present study we assume for simplicity that the reward is deterministic, a benign assumption which can be easily generalized.
Assumption 3.1
The rewards, , are uniformly bounded by a finite constant .
The actor maintains a parametrized policy function. A parametrized policy function is a conditional probability function, denoted by , which maps an observation into a control given a parameter . The agent’s goal is to adjust the parameter in order to attain maximum average reward over time. For each , we have a Markov Chain (MC) induced by and . The state transitions of the MC are obtained by first generating an action according to , and then generating the next state according to . Thus, the MC has a transition matrix which is given by
[TABLE]
We denote the space of these transition probabilities by , and its closure by . The following assumption is needed in the sequel in order to prove the main results (see Brémaud (1999) for definitions).
Assumption 3.2
Each MC, , is aperiodic, recurrent, and irreducible.
As a result of Assumption 3.2, we have the following lemma regarding the stationary distribution and a common recurrent state.
Lemma 3.3
Under Assumption 3.2 we have:
Each MC, , has a unique stationary distribution, denoted by , satisfying . 2. 2.
There exists a state, denoted by , which is recurrent for all .
**Proof ** For the first part see Corollary 4.1 in (Gallager, 1995). The second part follows trivially from Assumption 3.2.
The next technical assumption states that the first and second derivatives of the parametrized policy function are bounded, and is needed to prove Lemma 3.6 below.
Assumption 3.4
The conditional probability function is twice differentiable. Moreover, there exist positive constants, and , such that for all , , and we have
[TABLE]
A notational comment concerning bounds Throughout the paper we denote upper bounds on different variables by the letter , with a subscript corresponding to the variable itself. An additional numerical subscript, or , denotes a bound on the first or second derivative of the variable. For example, , , and denote the bounds on the function and its first and second derivatives respectively.
3.2 Performance Measures
Next, we define a performance measure for an agent in an environment. The average reward per stage of an agent which traverses a MC starting from an initial state is defined by
[TABLE]
where denotes the expectation under the probability measure , and is the state at time . The agent’s goal is to find which maximizes . The following lemma shows that under Assumption 3.2, the average reward per stage does not depend on the initial state (Bertsekas (2006), vol. II, section 4.1).
Lemma 3.5
Under Assumption 3.2 and based on Lemma 3.3, the average reward per stage, , is independent of the starting state, is denoted by , and satisfies .
Based on Lemma 3.5, the agent’s goal is to find a parameter vector , which maximizes the average reward per stage . In the sequel we show how this maximization can be performed by optimizing , using . A consequence of Assumption 3.4 and the definition of is the following lemma.
Lemma 3.6
**
For each , , and , the functions and are uniformly bounded by and respectively.
- (a)
For each , , and , the functions and are uniformly bounded by , and respectively. 2. (b)
For all , and , the functions , and