Low Density Lattice Codes
Naftali Sommer, Meir Feder, Ofir Shalvi

TL;DR
Low density lattice codes (LDLC) are a new class of lattice codes with sparse inverse generator matrices, enabling efficient decoding and near-capacity performance on the AWGN channel, demonstrated through large-scale simulations.
Contribution
This paper introduces LDLC, a novel lattice coding scheme with sparse inverse matrices, allowing linear-time decoding and near-capacity error performance.
Findings
Decoding scheme achieves near-capacity performance within ~0.5dB.
Efficient linear-time iterative decoding demonstrated.
Good error performance at block length of 100,000 symbols.
Abstract
Low density lattice codes (LDLC) are novel lattice codes that can be decoded efficiently and approach the capacity of the additive white Gaussian noise (AWGN) channel. In LDLC a codeword x is generated directly at the n-dimensional Euclidean space as a linear transformation of a corresponding integer message vector b, i.e., x = Gb, where H, the inverse of G, is restricted to be sparse. The fact that H is sparse is utilized to develop a linear-time iterative decoding scheme which attains, as demonstrated by simulations, good error performance within ~0.5dB from capacity at block length of n = 100,000 symbols. The paper also discusses convergence results and implementation considerations.
Click any figure to enlarge with its caption.
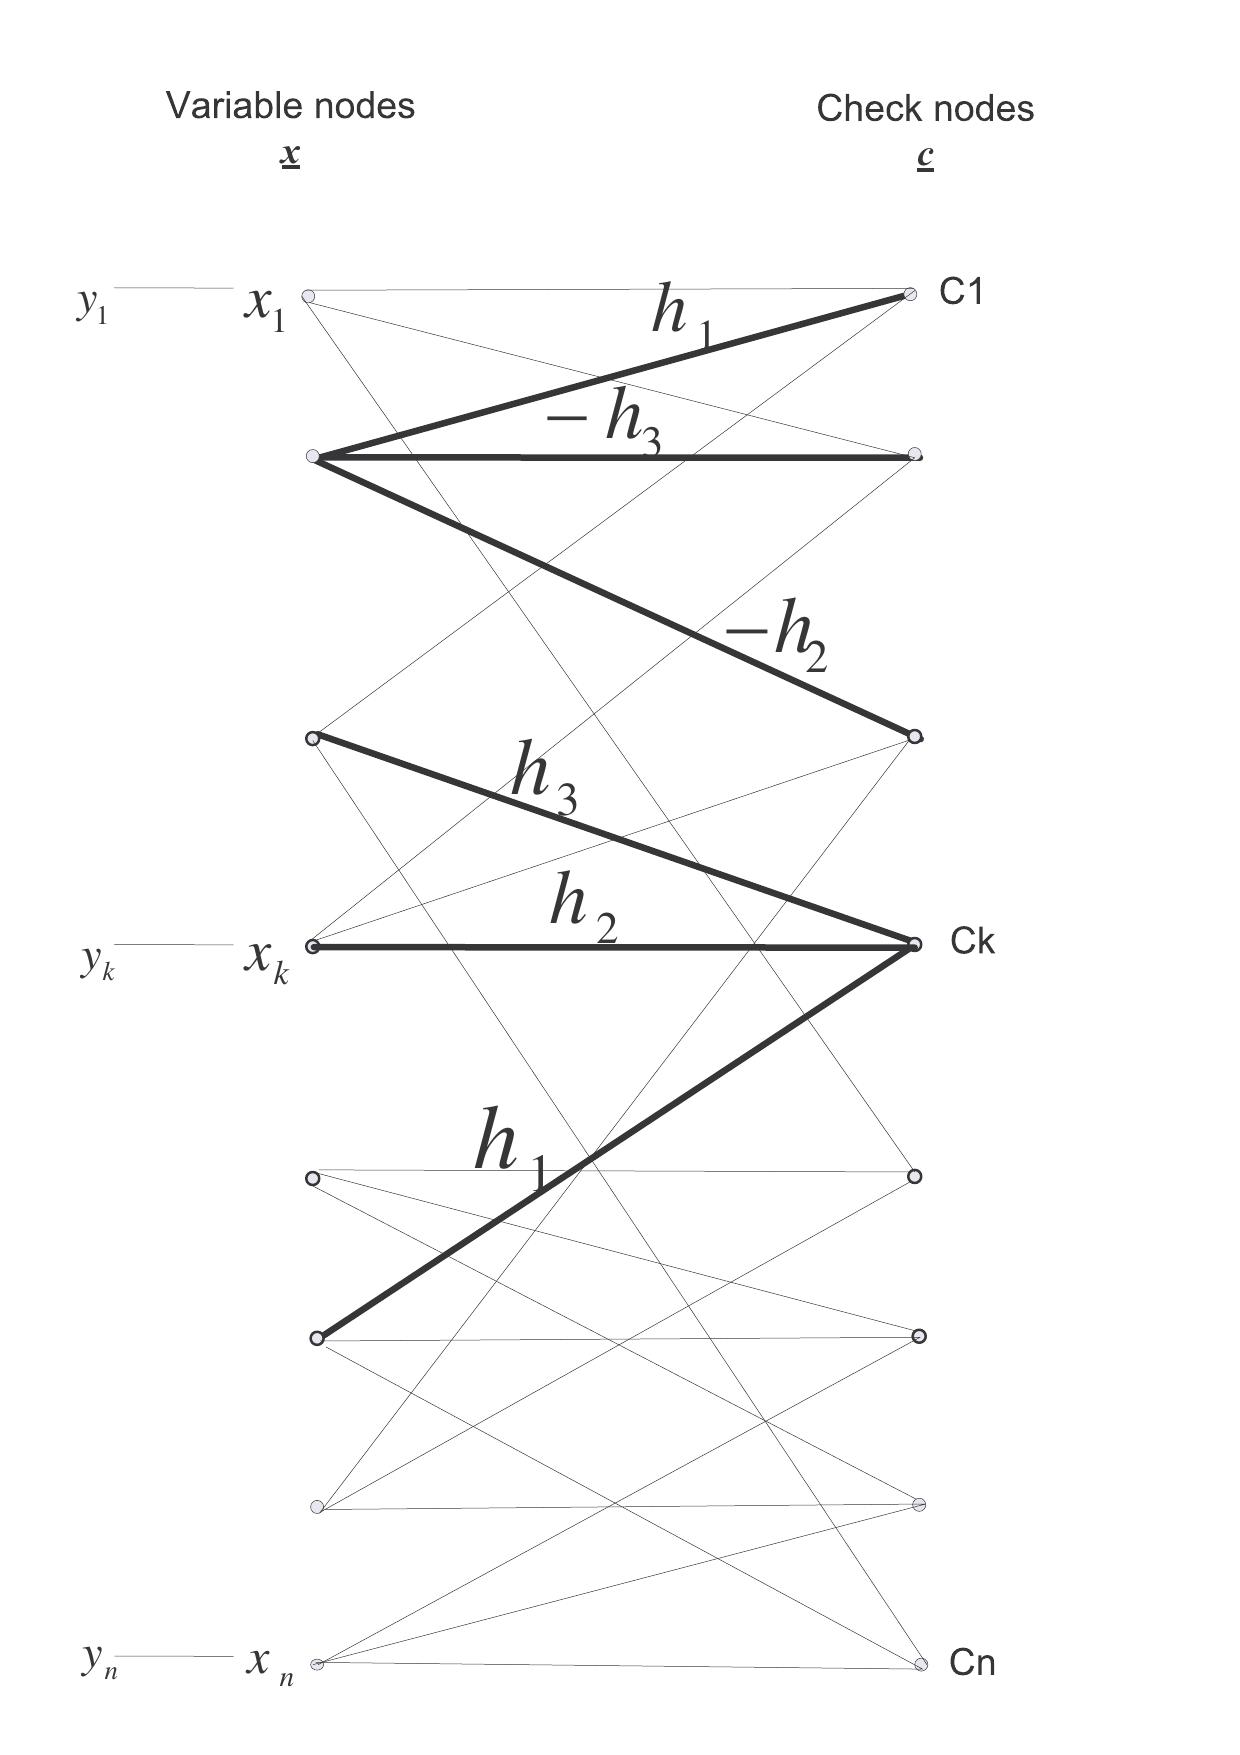 Figure 1
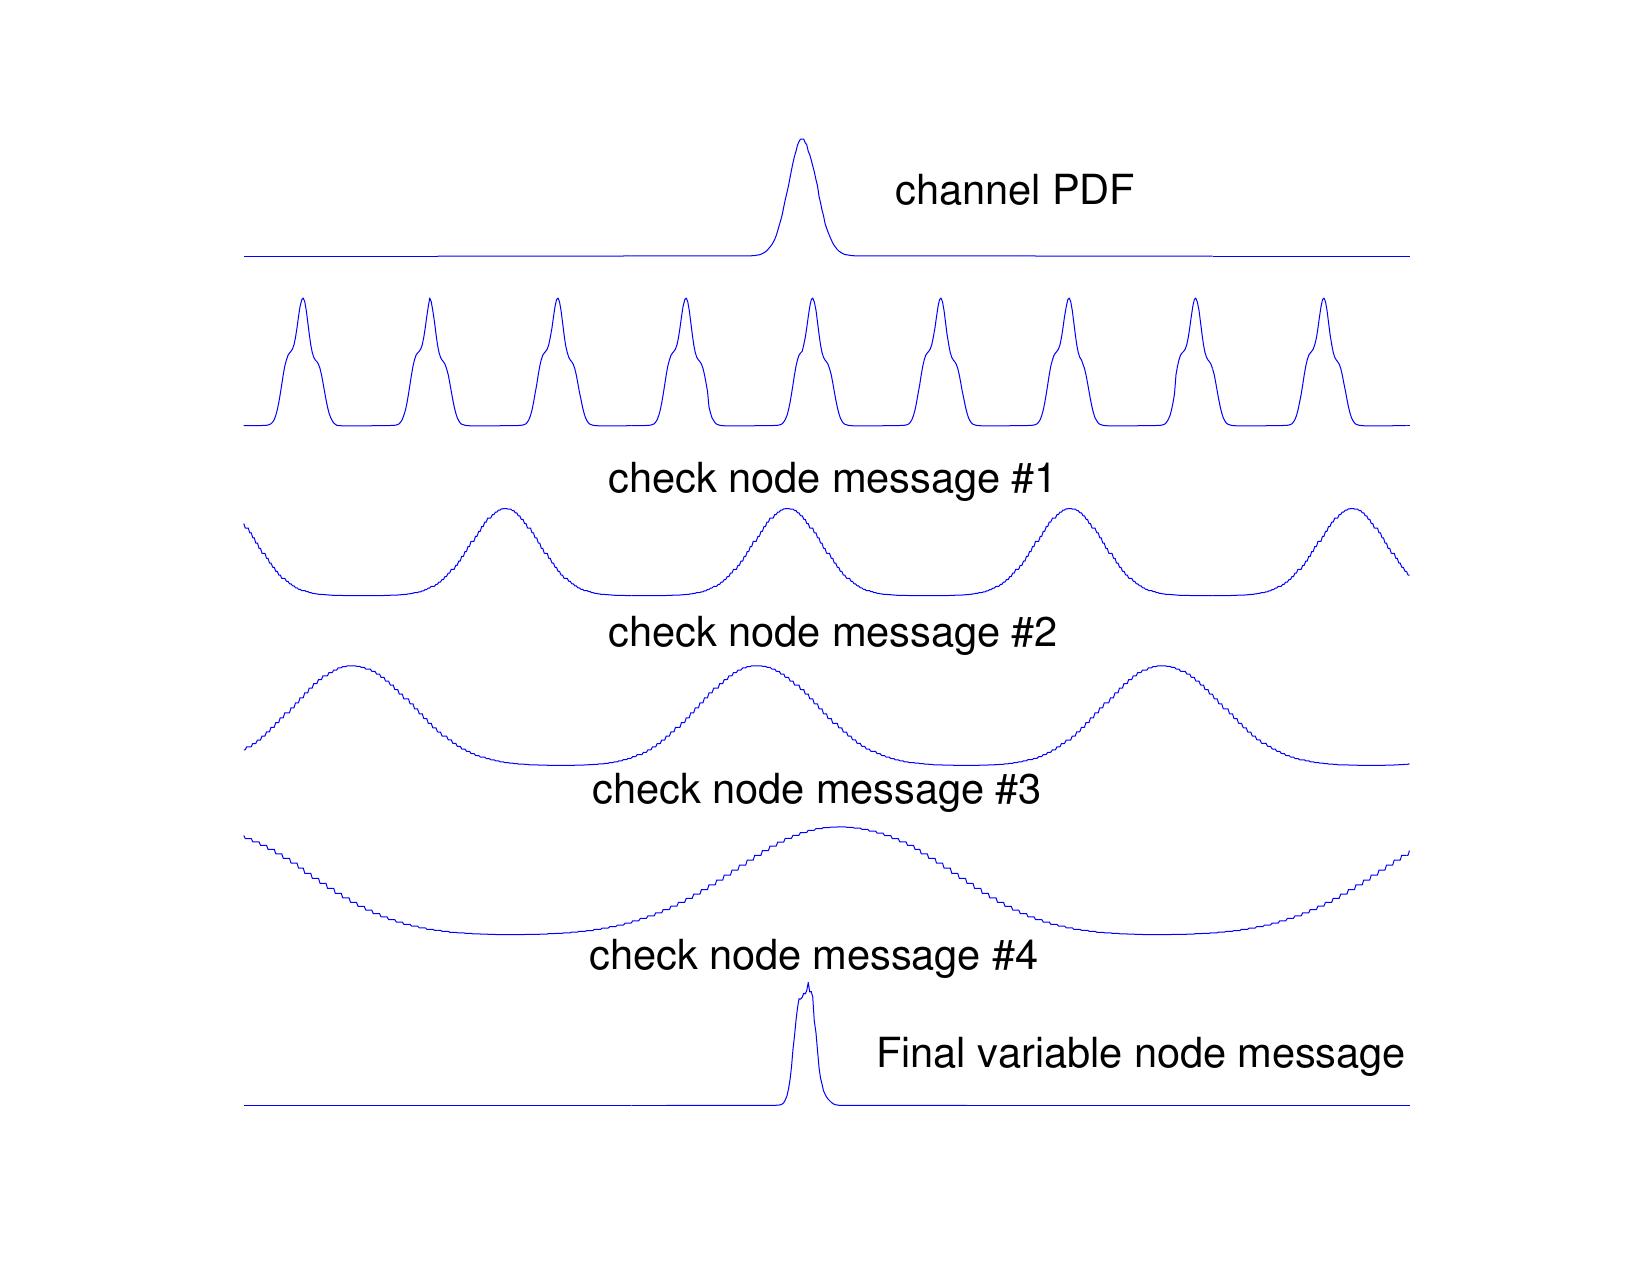 Figure 2
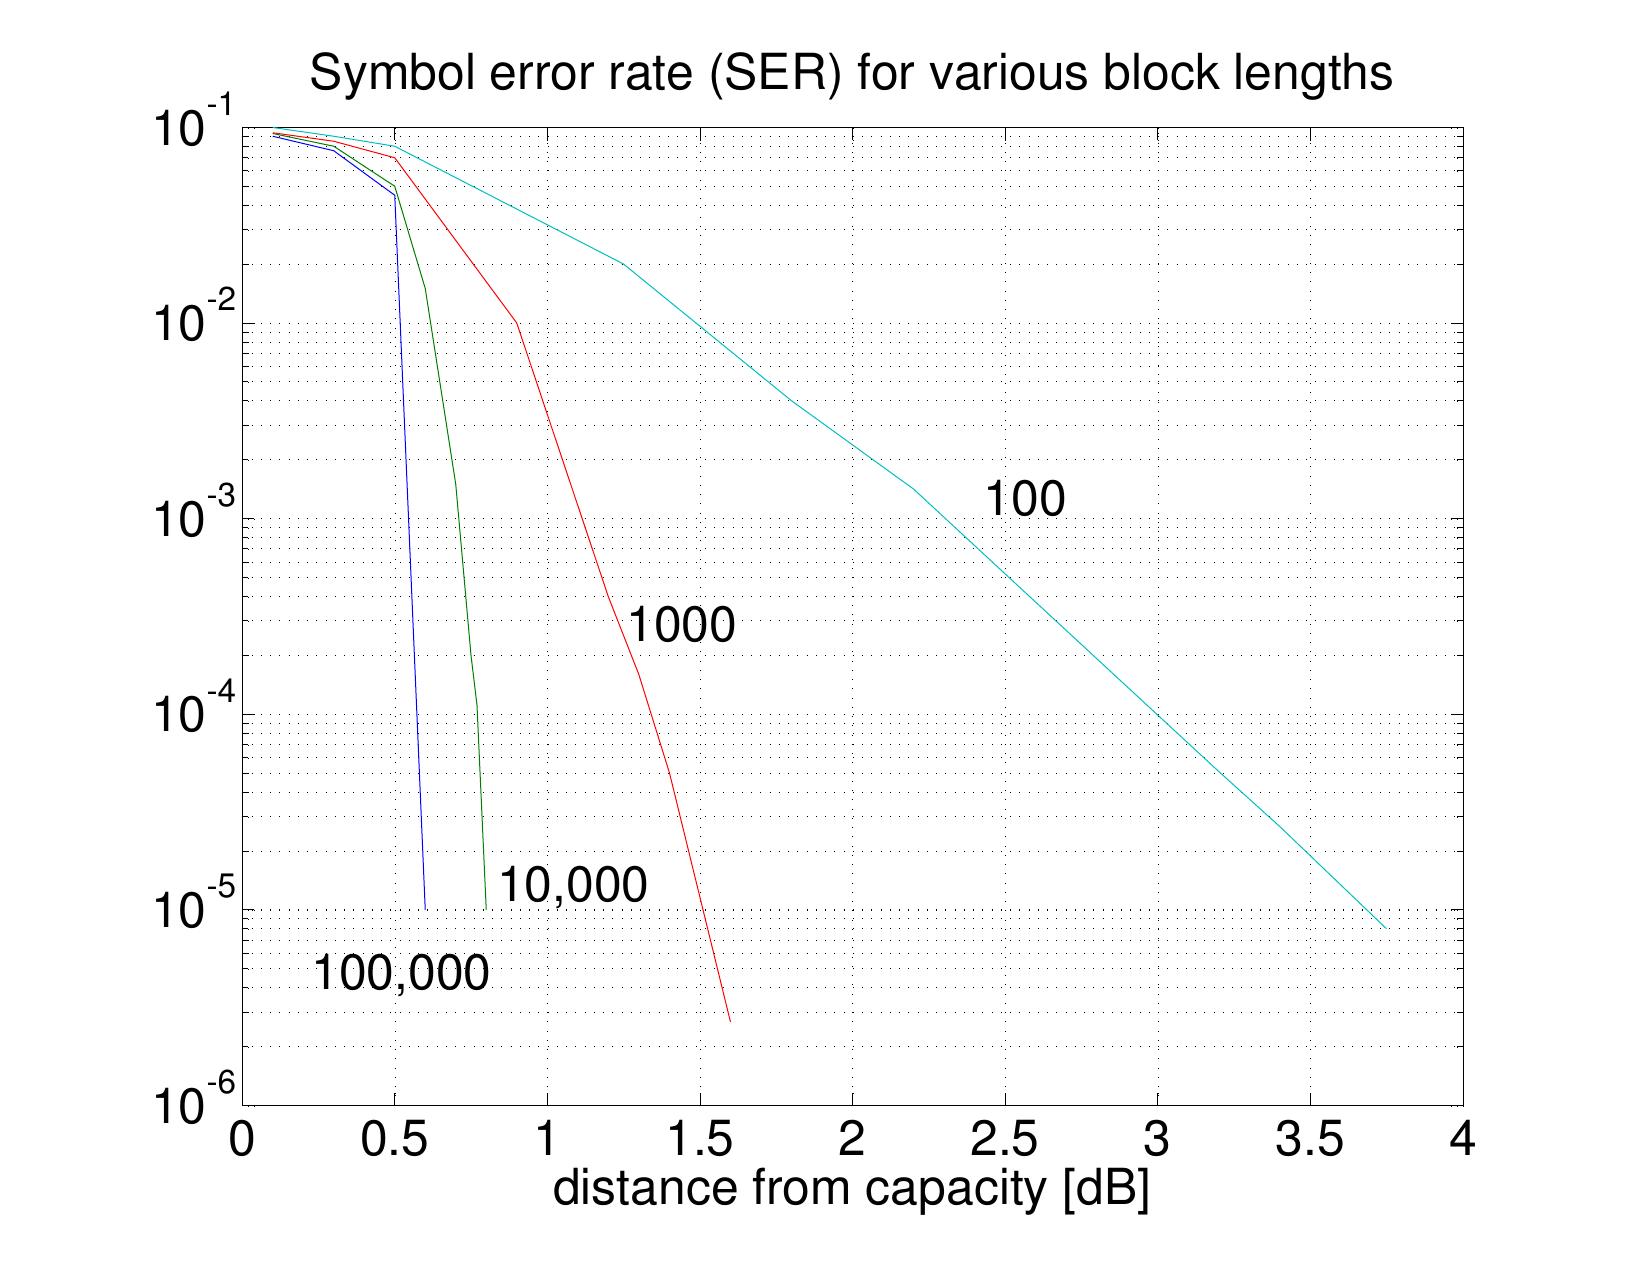 Figure 3
 Figure 4
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
Taxonomy
TopicsCoding theory and cryptography · Error Correcting Code Techniques · Cellular Automata and Applications
Low Density Lattice Codes
Naftali Sommer, Meir Feder, and Ofir Shalvi The material in this paper was presented in part in the IEEE International Symposium on Information Theory, Seattle, July 2006, and in part in the Inauguration of the UCSD Information Theory and Applications Center, San Diego, Feb. 2006.
Abstract
Low density lattice codes (LDLC) are novel lattice codes that can be decoded efficiently and approach the capacity of the additive white Gaussian noise (AWGN) channel. In LDLC a codeword is generated directly at the -dimensional Euclidean space as a linear transformation of a corresponding integer message vector , i.e., , where is restricted to be sparse. The fact that is sparse is utilized to develop a linear-time iterative decoding scheme which attains, as demonstrated by simulations, good error performance within dB from capacity at block length of symbols. The paper also discusses convergence results and implementation considerations.
Index Terms:
Lattices, lattice codes, iterative decoding, LDPC.
I Introduction
If we take a look at the evolution of codes for binary or finite alphabet channels, it was first shown [1] that channel capacity can be achieved with long random codewords. Then, it was found out [2] that capacity can be achieved via a simpler structure of linear codes. Then, specific families of linear codes were found that are practical and have good minimum Hamming distance (e.g. convolutional codes, cyclic block codes, specific cyclic codes such as BCH and Reed-Solomon codes [4]). Later, capacity achieving schemes were found, which have special structures that allow efficient iterative decoding, such as low-density parity-check (LDPC) codes [5] or turbo codes [6].
If we now take a similar look at continuous alphabet codes for the additive white Gaussian noise (AWGN) channel, it was first shown [3] that codes with long random Gaussian codewords can achieve capacity. Later, it was shown that lattice codes can also achieve capacity ([7] – [12]). Lattice codes are clearly the Euclidean space analogue of linear codes. Similarly to binary codes, we could expect that specific practical lattice codes will then be developed. However, there was almost no further progress from that point. Specific lattice codes that were found were based on fixed dimensional classical lattices [19] or based on algebraic error correcting codes [13][14], but no significant effort was made in designing lattice codes directly in the Euclidean space or in finding specific capacity achieving lattice codes. Practical coding schemes for the AWGN channel were based on finite alphabet codes.
In [15], “signal codes” were introduced. These are lattice codes, designed directly in the Euclidean space, where the information sequence of integers , is encoded by convolving it with a fixed signal pattern , . Signal codes are clearly analogous to convolutional codes, and in particular can work at the AWGN channel cutoff rate with simple sequential decoders. In [16] it is also demonstrated that signal codes can work near the AWGN channel capacity with more elaborated bi-directional decoders. Thus, signal codes provided the first step toward finding effective lattice codes with practical decoders.
Inspired by LDPC codes and in the quest of finding practical capacity achieving lattice codes, we propose in this work “Low Density Lattice Codes” (LDLC). We show that these codes can approach the AWGN channel capacity with iterative decoders whose complexity is linear in block length. In recent years several schemes were proposed for using LDPC over continuous valued channels by either multilevel coding [18] or by non-binary alphabet (e.g. [17]). Unlike these LDPC based schemes, in LDLC both the encoder and the channel use the same real algebra which is natural for the continuous-valued AWGN channel. This feature also simplifies the convergence analysis of the iterative decoder.
The outline of this paper is as follows. Low density lattice codes are first defined in Section II. The iterative decoder is then presented in Section III, followed by convergence analysis of the decoder in Section IV. Then, Section V describes how to choose the LDLC code parameters, and Section VI discusses implementation considerations. The computational complexity of the decoder is then discussed in Section VII, followed by a brief description of encoding and shaping in Section VIII. Simulation results are finally presented in Section IX.
II Basic Definitions and Properties
II-A Lattices and Lattice Codes
An dimensional lattice in is defined as the set of all linear combinations of a given basis of linearly independent vectors in with integer coefficients. The matrix , whose columns are the basis vectors, is called a generator matrix of the lattice. Every lattice point is therefore of the form , where is an -dimensional vector of integers. The Voronoi cell of a lattice point is defined as the set of all points that are closer to this point than to any other lattice point. The Voronoi cells of all lattice points are congruent, and for square the volume of the Voronoi cell is equal to . In the sequel will be used to denote both the lattice and its generator matrix.
A lattice code of dimension is defined by a (possibly shifted) lattice in and a shaping region , where the codewords are all the lattice points that lie within the shaping region . Denote the number of these codewords by . The average transmitted power (per channel use, or per symbol) is the average energy of all codewords, divided by the codeword length . The information rate (in bits/symbol) is .
When using a lattice code for the AWGN channel with power limit and noise variance , the maximal information rate is limited by the capacity . Poltyrev [20] considered the AWGN channel without restrictions. If there is no power restriction, code rate is a meaningless measure, since it can be increased without limit. Instead, it was suggested in [20] to use the measure of constellation density, leading to a generalized definition of the capacity as the maximal possible codeword density that can be recovered reliably. When applied to lattices, the generalized capacity implies that there exists a lattice of high enough dimension that enables transmission with arbitrary small error probability, if and only if . A lattice that achieves the generalized capacity of the AWGN channel without restrictions, also achieves the channel capacity of the power constrained AWGN channel, with a properly chosen spherical shaping region (see also [12]).
In the rest of this work we shall concentrate on the lattice design and the lattice decoding algorithm, and not on the shaping region or shaping algorithms. We shall use lattices with , where analysis and simulations will be carried for the AWGN channel without restrictions. A capacity achieving lattice will have small error probability for noise variance which is close to the theoretical limit .
II-B Syndrome and Parity Check Matrix for Lattice Codes
A binary error correcting code is defined by its binary generator matrix . A binary information vector with dimension is encoded by , where calculations are performed in the finite field GF(2). The parity check matrix is an matrix such that is a codeword if and only if . The input to the decoder is the noisy codeword , where is the error sequence and addition is done in the finite field. The decoder typically starts by calculating the syndrome which depends only on the noise sequence and not on the transmitted codeword.
We would now like to extend the definitions of the parity check matrix and the syndrome to lattice codes. An -dimensional lattice code is defined by its lattice generator matrix (throughout this paper we assume that is square, but the results are easily extended to the non-square case). Every codeword is of the form , where is a vector of integers. Therefore, is a vector of integers for every codeword . We define the parity check matrix for the lattice code as . Given a noisy codeword (where is the additive noise vector, e.g. AWGN, added by real arithmetic), we can then define the syndrome as , where is the fractional part of , defined as , where denotes the nearest integer to . The syndrome will be zero if and only if is a lattice point, since will then be a vector of integers with zero fractional part. For a noisy codeword, the syndrome will equal and therefore will depend only on the noise sequence and not on the transmitted codeword, as desired.
Note that the above definitions of the syndrome and parity check matrix for lattice codes are consistent with the definitions of the dual lattice and the dual code[19]: the dual lattice of a lattice is defined as the lattice with generator matrix , where for binary codes, the dual code of is defined as the code whose generator matrix is , the parity check matrix of .
II-C Low Density Lattice Codes
We shall now turn to the definition of the codes proposed in this paper - low density lattice codes (LDLC).
Definition 1** (LDLC)**
An dimensional LDLC is an -dimensional lattice code with a non-singular lattice generator matrix satisfying , for which the parity check matrix is sparse. The ’th row degree , is defined as the number of nonzero elements in row of , and the ’th column degree , is defined as the number of nonzero elements in column of .
Note that in binary LDPC codes, the code is completely defined by the locations of the nonzero elements of . In LDLC there is another degree of freedom since we also have to choose the values of the nonzero elements of .
Definition 2** (regular LDLC)**
An dimensional LDLC is regular if all the row degrees and column degrees of the parity check matrix are equal to a common degree .
Definition 3** (magic square LDLC)**
An dimensional regular LDLC with degree is called “magic square LDLC” if every row and column of the parity check matrix has the same nonzero values, except for a possible change of order and random signs. The sorted sequence of these values will be referred to as the generating sequence of the magic square LDLC.
For example, the matrix
[TABLE]
is a parity check matrix of a magic square LDLC with lattice dimension , degree and generating sequence . This should be further normalized by the constant in order to have , as required by Definition 1.
The bipartite graph of an LDLC is defined similarly to LDPC codes: it is a graph with variable nodes at one side and check nodes at the other side. Each variable node corresponds to a single element of the codeword . Each check node corresponds to a check equation (a row of ). A check equation is of the form , where denotes the locations of the nonzero elements at the appropriate row of , are the values of at these locations and the integer at the right hand side is unknown. An edge connects check node and variable node if and only if . This edge is assigned the value . Figure 1 illustrates the bi-partite graph of a magic square LDLC with degree 3. In the figure, every variable node is also associated with its noisy channel observation .
Finally, a -loop is defined as a loop in the bipartite graph that consists of edges. A bipartite graph, in general, can only contain loops with even length. Also, a 2-loop, which consists of two parallel edges that originate from the same variable node to the same check node, is not possible by the definition of the graph. However, longer loops are certainly possible. For example, a 4-loop exists when two variable nodes are both connected to the same pair of check nodes.
III Iterative Decoding for the AWGN Channel
Assume that the codeword was transmitted, where is a vector of integers. We observe the noisy codeword , where is a vector of i.i.d Gaussian noise samples with common variance , and we need to estimate the integer valued vector . The maximum likelihood (ML) estimator is then .
Our decoder will not estimate directly the integer vector . Instead, it will estimate the probability density function (PDF) of the codeword vector . Furthermore, instead of calculating the -dimensional PDF of the whole vector , we shall calculate the one-dimensional PDF’s for each of the components of this vector (conditioned on the whole observation vector ). In appendix A it is shown that is a weighted sum of Dirac delta functions:
[TABLE]
where is a lattice point (vector), is its -th component, is a constant independent of and is the Euclidean distance between and . Direct evaluation of (1) is not practical, so our decoder will try to estimate (or at least approximate it) in an iterative manner.
Our decoder will decode to the infinite lattice, thus ignoring the shaping region boundaries. This approximate decoding method is no longer exact maximum likelihood decoding, and is usually denoted “lattice decoding” [12].
The calculation of is involved since the components are not independent random variables (RV’s), because is restricted to be a lattice point. Following [5] we use a “trick” - we assume that the ’s are independent, but add a condition that assures that is a lattice point. Specifically, define . Restricting to be a lattice point is equivalent to restricting . Therefore, instead of calculating under the assumption that is a lattice point, we can calculate and assume that the are independent and identically distributed (i.i.d) with a continuous PDF (that does not include Dirac delta functions). It still remains to set , the PDF of . Under the i.i.d assumption, the PDF of the codeword is . As shown in Appendix B, the value of is not important at values of which are not lattice points, but at a lattice point it should be proportional to the probability of using this lattice point. Since we assume that all lattice points are used equally likely, must have the same value at all lattice points. A reasonable choice for is then to use a uniform distribution such that will be uniformly distributed in an -dimensional cube. For an exact ML decoder (that takes into account the boundaries of the shaping region), it is enough to choose the range of such that this cube will contain the shaping region. For our decoder, that performs lattice decoding, we should set the range of large enough such that the resulting cube will include all the lattice points which are likely to be decoded. The derivation of the iterative decoder shows that this range can be set as large as needed without affecting the complexity of the decoder.
The derivation in [5] further imposed the tree assumption. In order to understand the tree assumption, it is useful to define the tier diagram, which is shown in Figure 2 for a regular LDLC with degree 3. Each vertical line corresponds to a check equation. The tier 1 nodes of are all the elements that take place in a check equation with . The tier 2 nodes of are all the elements that take place in check equations with the tier 1 elements of , and so on. The tree assumption assumes that all the tree elements are distinct (i.e. no element appears in different tiers or twice in the same tier). This assumption simplifies the derivation, but in general, does not hold in practice, so our iterative algorithm is not guaranteed to converge to the exact solution (1) (see Section IV).
The detailed derivation of the iterative decoder (using the above “trick” and the tree assumption) is given in Appendix C. In Section III-A below we present the final resulting algorithm. This iterative algorithm can also be explained by intuitive arguments, described after the algorithm specification.
III-A The Iterative Decoding Algorithm
The iterative algorithm is most conveniently represented by using a message passing scheme over the bipartite graph of the code, similarly to LDPC codes. The basic difference is that in LDPC codes the messages are scalar values (e.g. the log likelihood ratio of a bit), where for LDLC the messages are real functions over the interval . As in LDPC, in each iteration the check nodes send messages to the variable nodes along the edges of the bipartite graph and vice versa. The messages sent by the check nodes are periodic extensions of PDF’s. The messages sent by the variable nodes are PDF’s.
LDLC iterative decoding algorithm:
Denote the variable nodes by and the check nodes by .
- •
Initialization: each variable node sends to all its check nodes the message .
- •
Basic iteration - check node message: Each check node sends a (different) message to each of the variable nodes that are connected to it. For a specific check node denote (without loss of generality) the appropriate check equation by , where , are the variable nodes that are connected to this check node (and is the appropriate row degree of ). Denote by , , the message that was sent to this check node by variable node in the previous half-iteration. The message that the check node transmits back to variable node is calculated in three basic steps.
The convolution step - all messages, except , are convolved (after expanding each by ):
[TABLE] 2. 2.
The stretching step - The result is stretched by to 3. 3.
The periodic extension step - The result is extended to a periodic function with period :
[TABLE]
The function is the message that is finally sent to variable node .
- •
Basic iteration - variable node message: Each variable node sends a (different) message to each of the check nodes that are connected to it. For a specific variable node , assume that it is connected to check nodes , where is the appropriate column degree of . Denote by , , the message that was sent from check node to this variable node in the previous half-iteration. The message that is sent back to check node is calculated in two basic steps:
The product step: 2. 2.
The normalization step:
This basic iteration is repeated for the desired number of iterations.
- •
Final decision: After finishing the iterations, we want to estimate the integer information vector . First, we estimate the final PDF’s of the codeword elements , , by calculating the variable node messages at the last iteration without omitting any check node message in the product step: . Then, we estimate each by finding the peak of its PDF: . Finally, we estimate as .
The operation of the iterative algorithm can be intuitively explained as follows. The check node operation is equivalent to calculating the PDF of from the PDF’s of , , given that , and assuming that are independent. Extracting from the check equation, we get . Since the PDF of a sum of independent random variables is the convolution of the corresponding PDF’s, equation (1) and the stretching step that follows it simply calculate the PDF of , assuming that the integer at the right hand side of the check equation is zero. The result is then periodically extended such that a properly shifted copy exists for every possible value of this (unknown) integer. The variable node gets such a message from all the check equations that involve the corresponding variable. The check node messages and the channel PDF are treated as independent sources of information on the variable, so they are multiplied all together.
Note that the periodic extension step at the check nodes is equivalent to a convolution with an infinite impulse train. With this observation, the operation of the variable nodes is completely analogous to that of the check nodes: the variable nodes multiply the incoming messages by the channel PDF, where the check nodes convolve the incoming messages with an impulse train, which can be regarded as a generalized “integer PDF”.
In the above formulation, the integer information vector is recovered from the PDF’s of the codeword elements . An alternative approach is to calculate the PDF of each integer element directly as the PDF of the left hand side of the appropriate check equation. Using the tree assumption, this can be done by simply calculating the convolution as in (1), but this time without omitting any PDF, i.e. all the received variable node messages are convolved. Then, the integer is determined by .
Figure 3 shows an example for a regular LDLC with degree . The figure shows all the signals that are involved in generating a variable node message for a certain variable node. The top signal is the channel Gaussian, centered around the noisy observation of the variable. The next 4 signals are the periodically extended PDF’s that arrived from the check nodes, and the bottom signal is the product of all the 5 signals. It can be seen that each periodic signal has a different period, according to the relevant coefficient of . Also, the signals with larger period have larger variance. This diversity resolves all the ambiguities such that the multiplication result (bottom plot) remains with a single peak. We expect the iterative algorithm to converge to a solution where a single peak will remain at each PDF, located at the desired value and narrow enough to estimate the information.
IV Convergence
IV-A The Gaussian Mixture Model
Interestingly, for LDLC we can come up with a convergence analysis that in many respects is more specific than the similar analysis for LDPC.
We start by introducing basic claims about Gaussian PDF’s. Denote .
Claim 1** (convolution of Gaussians)**
The convolution of Gaussians with mean values and variances , respectively, is a Gaussian with mean and variance .
Proof:
See [21]. ∎
Claim 2** (product of Gaussians)**
Let , ,…, be Gaussians with mean values and variances respectively. Then, the product of these Gaussians is a scaled Gaussian: , where , , and .
Proof:
By straightforward mathematical manipulations. ∎
The reason that we are interested in the properties of Gaussian PDF’s lies in the following lemma.
Lemma 1
Each message that is exchanged between the check nodes and variable nodes in the LDLC decoding algorithm (i.e. and ), at every iteration, can be expressed as a Gaussian mixture of the form .
Proof:
By induction: The initial messages are Gaussians, and the basic operations of the iterative decoder preserve the Gaussian mixture nature of Gaussian mixture inputs (convolution and multiplication preserve the Gaussian nature according to claims 1 and 2, stretching, expanding and shifting preserve it by the definition of a Gaussian, and periodic extension transforms a single Gaussian to a mixture and a mixture to a mixture). ∎
Convergence analysis should therefore analyze the convergence of the variances, mean values and amplitudes of the Gaussians in each mixture.
IV-B Convergence of the Variances
We shall now analyze the behavior of the variances, and start with the following lemma.
Lemma 2
For both variable node messages and check node messages, all the Gaussians that take place in the same mixture have the same variance.
Proof:
By induction. The initial variable node messages are single element mixtures so the claim obviously holds. Assume now that all the variable node messages at iteration are mixtures where all the Gaussians that take place in the same mixture have the same variance. In the convolution step (1), each variable node message is first expanded. All Gaussians in the expanded mixture will still have the same variance, since the whole mixture is expanded together. Then, expanded Gaussian mixtures are convolved. In the resulting mixture, each Gaussian will be the result of convolving single Gaussians, one from each mixture. According to claim 1, all the Gaussians in the convolution result will have the same variance, which will equal the sum of the variances of the expanded messages. The stretching and periodic extension (3) do not change the equal variance property, so it holds for the final check node messages. The variable nodes multiply check node messages. Each Gaussian in the resulting mixture is a product of single Gaussians, one from each mixture, and the channel noise Gaussian. According to claim 2, they will all have the same variance. The final normalization step does not change the variances so the equal variance property is kept for the final variable node messages at iteration . ∎
Until this point we did not impose any restrictions on the LDLC. From now on, we shall restrict ourselves to magic square regular LDLC (see Definition 3). The basic iterative equations that relate the variances at iteration to the variances at iteration are summarized in the following two lemmas.
Lemma 3
For magic square LDLC, variable node messages that are sent at the same iteration along edges with the same absolute value have the same variance.
Proof:
See Appendix D. ∎
Lemma 4
For magic square LDLC with degree , denote the variance of the messages that are sent at iteration along edges with weight by . The variance values obey the following recursion:
[TABLE]
for , with initial conditions .
Proof:
See Appendix D. ∎
For illustration, the recursion for the case is:
[TABLE]
[TABLE]
[TABLE]
The lemmas above are used to prove the following theorem regarding the convergence of the variances.
Theorem 1
For a magic square LDLC with degree and generating sequence , define . Assume that . Then:
The first variance approaches a constant value of , where is the channel noise variance:
[TABLE] 2. 2.
The other variances approach zero:
[TABLE]
for . 3. 3.
The asymptotic convergence rate of all variances is exponential:
[TABLE]
for . 4. 4.
The zero approaching variances are upper bounded by the decaying exponential :
[TABLE]
for and .
Proof:
See Appendix D. ∎
If , the variances may still converge, but convergence rate may be as slow as , as illustrated in Appendix D.
Convergence of the variances to zero implies that the Gaussians approach impulses. This is a desired property of the decoder, since the exact PDF that we want to calculate is indeed a weighted sum of impulses (see (1)). It can be seen that by designing a code with , i.e. , one variance approaches a constant (and not zero). However, all the other variances approach zero, where all variances converge in an exponential rate. This will be the preferred mode because the information can be recovered even if a single variance does not decay to zero, where exponential convergence is certainly preferred over slow convergence. Therefore, from now on we shall restrict our analysis to magic square LDLC with .
Theorem 1 shows that every iteration, each variable node will generate messages with variances that approach zero, and a single message with variance that approaches a constant. The message with nonzero variance will be transmitted along the edge with largest weight (i.e. ). However, from the derivation of Appendix D it can be seen that the opposite happens for the check nodes: each check node will generate messages with variances that approach a constant, and a single message with variance that approaches zero. The check node message with zero approaching variance will be transmitted along the edge with largest weight.
IV-C Convergence of the Mean Values
The reason that the messages are mixtures and not single Gaussians lies in the periodic extension step (3) at the check nodes, and every Gaussian at the output of this step can be related to a single index of the infinite sum. Therefore, we can label each Gaussian at iteration with a list of all the indices that were used in (3) during its creation process in iterations .
Definition 4** (label of a Gaussian)**
The label of a Gaussian consists of a sequence of triplets of the form , where is an iteration index, is a check node index and is an integer. The labels are initialized to the empty sequence. Then, the labels are updated along each iteration according to the following update rules:
In the periodic extension step (3), each Gaussian in the output periodic mixture is assigned the label of the specific Gaussian of that generated it, concatenated with a single triplet , where is the current iteration index, is the check node index and is the index in the infinite sum of (3) that corresponds to this Gaussian. 2. 2.
In the convolution step and the product step, each Gaussian in the output mixture is assigned a label that equals the concatenation of all the labels of the specific Gaussians in the input messages that formed this Gaussian. 3. 3.
The stretching and normalization steps do not alter the label of each Gaussian: Each Gaussian in the stretched/normalized mixture inherits the label of the appropriate Gaussian in the original mixture.
Definition 5** (a consistent Gaussian)**
A Gaussian in a mixture is called “[, ] consistent” if its label contains no contradictions for iterations to , i.e. for every pair of triplets , such that , if then . A [[math], ] consistent Gaussian will be simply called a consistent Gaussian.
We can relate every consistent Gaussian to a unique integer vector , which holds the integers used in the check nodes. Since in the periodic extension step (3) the sum is taken over all integers, a consistent Gaussian exists in each variable node message for every possible integer valued vector . We shall see later that this consistent Gaussian corresponds to the lattice point .
According to Theorem 1, if we choose the nonzero values of such that , every variable node generates messages with variances approaching zero and a single message with variance that approaches a constant. We shall refer to these messages as “narrow” messages and “wide” messages, respectively. For a given integer valued vector , we shall concentrate on the consistent Gaussians that relate to in all the variable node messages that are generated in each iteration (a single Gaussian in each message). The following lemmas summarize the asymptotic behavior of the mean values of these consistent Gaussians for the narrow messages.
Lemma 5
For a magic square LDLC with degree and , consider the narrow messages that are sent from a specific variable node. Consider further a single Gaussian in each message, which is the consistent Gaussian that relates to a given integer vector . Asymptotically, the mean values of these Gaussians become equal.
Proof:
See Appendix E. ∎
Lemma 6
For a magic square LDLC with dimension , degree and , consider only consistent Gaussians that relate to a given integer vector and belong to narrow messages. Denote the common mean value of the such Gaussians that are sent from variable node at iteration by , and arrange all these mean values in a column vector of dimension . Define the error vector , where is the lattice point that corresponds to . Then, for large , satisfies:
[TABLE]
where is derived from by permuting the rows such that the elements will be placed on the diagonal, dividing each row by the appropriate diagonal element ( or ), and then nullifying the diagonal.
Proof:
See Appendix E. ∎
We can now state the following theorem, which describes the conditions for convergence and the steady state value of the mean values of the consistent Gaussians of the narrow variable node messages.
Theorem 2
For a magic square LDLC with , the mean values of the consistent Gaussians of the narrow variable node messages that relate to a given integer vector are assured to converge if and only if all the eigenvalues of have magnitude less than , where is defined in Lemma 6. When this condition is fulfilled, the mean values converge to the coordinates of the appropriate lattice point: .
Proof:
Immediate from Lemma 6. ∎
Note that without adding random signs to the LDLC nonzero values, the all-ones vector will be an eigenvector of with eigenvalue , which may exceed .
Interestingly, recursion (6) is also obeyed by the error of the Jacobi method for solving systems of sparse linear equations [22] (see also Section VIII-A), when it is used to solve (with solution ). Therefore, the LDLC decoder can be viewed as a superposition of Jacobi solvers, one for each possible value of the integer valued vector .
We shall now turn to the convergence of the mean values of the wide messages. The asymptotic behavior is summarized in the following lemma.
Lemma 7
For a magic square LDLC with dimension and , consider only consistent Gaussians that relate to a given integer vector and belong to wide messages. Denote the mean value of such a Gaussian that is sent from variable node at iteration by , and arrange all these mean values in a column vector of dimension . Define the error vector . Then, for large , satisfies:
[TABLE]
where is the noisy codeword and is an matrix defined by:
[TABLE]
Proof:
See Appendix E, where an alternative way to construct from is also presented. ∎
The conditions for convergence and steady state solution for the wide messages are described in the following theorem.
Theorem 3
For a magic square LDLC with , the mean values of the consistent Gaussians of the wide variable node messages that relate to a given integer vector are assured to converge if and only if all the eigenvalues of have magnitude less than , where is defined in Lemma 7. When this condition is fulfilled, the steady state solution is .
Proof:
Immediate from Lemma 7. ∎
Unlike the narrow messages, the mean values of the wide messages do not converge to the appropriate lattice point coordinates. The steady state error depends on the difference between the noisy observation and the lattice point, as well as on , and it decreases to zero as . Note that the final PDF of a variable is generated by multiplying all the check node messages that arrive to the appropriate variable node. of these messages are wide, and therefore their mean values have a steady state error. One message is narrow, so it converges to an impulse at the lattice point coordinate. Therefore, the final product will be an impulse at the correct location, where the wide messages will only affect the magnitude of this impulse. As long as the mean values errors are not too large (relative to the width of the wide messages), this should not cause an impulse that corresponds to a wrong lattice point to have larger amplitude than the correct one. However, for large noise, these steady state errors may cause the decoder to deviate from the ML solution (As explained in Section IV-D).
To summarize the results for the mean values, we considered the mean values of all the consistent Gaussians that correspond to a given integer vector . A single Gaussian of this form exists in each of the variable node messages that are generated in each iteration. For each variable node, messages are narrow (have variance that approaches zero) and a single message is wide (variance approaches a constant). Under certain conditions on , the mean values of all the narrow messages converge to the appropriate coordinate of the lattice point . Under additional conditions on , the mean values of the wide messages converge, but the steady state values contain an error term.
We analyzed the behavior of consistent Gaussian. It should be noted that there are many more non-consistent Gaussians. Furthermore non-consistent Gaussians are generated in each iteration for any existing consistent Gaussian. We conjecture that unless a Gaussian is consistent, or becomes consistent along the iterations, it fades out, at least at noise conditions where the algorithm converges. The reason is that non-consistency in the integer values leads to mismatch in the corresponding PDF’s, and so the amplitude of that Gaussian is attenuated.
We considered consistent Gaussians which correspond to a specific integer vector , but such a set of Gaussians exists for every possible choice of , i.e. for every lattice point. Therefore, the narrow messages will converge to a solution that has an impulse at the appropriate coordinate of every lattice point. This resembles the exact solution (1), so the key for proper convergence lies in the amplitudes: we would like the consistent Gaussians of the ML lattice point to have the largest amplitude for each message.
IV-D Convergence of the Amplitudes
We shall now analyze the behavior of the amplitudes of consistent Gaussians (as discussed later, this is not enough for complete convergence analysis, but it certainly gives insight to the nature of the convergence process and its properties). The behavior of the amplitudes of consistent Gaussians is summarized in the following lemma.
Lemma 8
For a magic square LDLC with dimension , degree and , consider the consistent Gaussians that relate to a given integer vector in the variable node messages that are sent at iteration (one consistent Gaussian per message). Denote the amplitudes of these Gaussians by , , and define the log-amplitude as . Arrange these log-amplitudes in a column vector , such that element corresponds to the message that is sent from variable node along an edge with weight . Assume further that the bipartite graph of the LDLC contains no 4-loops. Then, the log-amplitudes satisfy the following recursion:
[TABLE]
with initialization . is an matrix which is all zeros except exactly ’’s in each row and each column. The element of the excitation vector at location (where and ) equals:
[TABLE]
[TABLE]
where and denote the mean value and variance of the consistent Gaussian that relates to the integer vector in the check node message that arrives to variable node at iteration along an edge with weight . is the noisy channel observation of variable node , and . Finally, is a constant excitation term that is independent of the integer vector (i.e. is the same for all consistent Gaussians). Note that an iteration is defined as sending variable node messages, followed by sending check node messages. The first iteration (where the variable nodes send the initialization PDF) is regarded as iteration [math].
Proof:
At the check node, the amplitude of a Gaussian at the convolution output is the product of the amplitudes of the corresponding Gaussians in the appropriate variable node messages. At the variable node, the amplitude of a Gaussian at the product output is the product of the amplitudes of the corresponding Gaussians in the appropriate check node messages, multiplied by the Gaussian scaling term, according to claim 2. Since we assume that the bipartite graph of the LDLC contains no 4-loops, an amplitude of a variable node message at iteration will therefore equal the product of amplitudes of Gaussians of variable node messages from iteration , multiplied by the Gaussian scaling term. This proves (12) and shows that has ’1’s in every row. However, since each variable node message affects exactly variable node messages of the next iteration, must also have ’1’s in every column. The total excitation term corresponds to the logarithm of the Gaussian scaling term. Each element of this scaling term results from the product of check node Gaussians and the channel Gaussian, according to claim 2. This scaling term sums over all the pairs of Gaussians, and in (13) the sum is separated to pairs that include the channel Gaussian and pairs that do not. The total excitation is divided between (13), which depends on the choice of the integer vector , and , which includes all the constant terms that are independent on (including the normalization operation which is performed at the variable node). ∎
Since there are exactly ’’s in each column of the matrix , it is easy to see that the all-ones vector is an eigenvector of , with eigenvalue . If , this eigenvalue is larger than , meaning that the recursion (12) is non-stable.
It can be seen that the excitation term has two components. The first term sums the squared differences between the mean values of all the possible pairs of received check node messages (weighted by the inverse product of the appropriate variances). It therefore measures the mismatch between the incoming messages. This mismatch will be small if the mean values of the consistent Gaussians converge to the coordinates of a lattice point (any lattice point). The second term sums the squared differences between the mean values of the incoming messages and the noisy channel output . This term measures the mismatch between the incoming messages and the channel measurement. It will be smallest if the mean values of the consistent Gaussians converge to the coordinates of the ML lattice point.
The following lemma summarizes some properties of the excitation term .
Lemma 9
For a magic square LDLC with dimension , degree , and no 4-loops, consider the consistent Gaussians that correspond to a given integer vector . According to Lemma 8, their amplitudes satisfy recursion (12). The excitation term of (12), which is defined by (13), satisfies the following properties:
, the ’th element of , is non-negative, finite and bounded for every and every . Moreover, converges to a finite non-negative steady state value as . 2. 2.
, where is the noisy received codeword and is a positive definite matrix defined by:
[TABLE]
[TABLE]
where is defined in Lemma 7. 3. 3.
For an LDLC with degree , the weighted infinite sum converges to a finite value.
Proof:
See Appendix F. ∎
The following theorem addresses the question of which consistent Gaussian will have the maximal asymptotic amplitude. We shall first consider the case of an LDLC with degree , and then consider the special case of in a separate theorem.
Theorem 4
For a magic square LDLC with dimension , degree , and no 4-loops, consider the consistent Gaussians that relate to a given integer vector in the variable node messages that are sent at iteration (one consistent Gaussian per message). Denote the amplitudes of these Gaussians by , , and define the product-of-amplitudes as . Define further , where is defined by (13) ( is well defined according to Lemma 9). Then:
The integer vector for which the consistent Gaussians will have the largest asymptotic product-of-amplitudes is the one for which is minimized. 2. 2.
The product-of-amplitudes for the consistent Gaussians that correspond to all other integer vectors will decay to zero in a super-exponential rate.
Proof:
As in Lemma 8, define the log-amplitudes . Define further . Taking the element-wise sum of (12), we get:
[TABLE]
with initialization . Note that we ignored the term . As shown below, we are looking for the vector that maximizes . Since (15) is a linear difference equation, and the term is independent of , its effect on is common to all and is therefore not interesting.
Define now . Substituting in (15), we get:
[TABLE]
with initialization , which can be solved to get:
[TABLE]
We would now like to compare the amplitudes of consistent Gaussians with various values of the corresponding integer vector in order to find the lattice point whose consistent Gaussians will have largest product-of-amplitudes. From the definitions of and we then have:
[TABLE]
Consider two integer vectors that relate to two lattice points. Denote the corresponding product-of-amplitudes by and , respectively, and assume that for these two vectors converges to the values and , respectively. Then, taking into account that , the asymptotic ratio of the product-of-amplitudes for these lattice points will be:
[TABLE]
It can be seen that if , the ratio decreases to zero in a super exponential rate. This shows that the lattice point for which is minimized will have the largest product-of-amplitudes, where for all other lattice points, the product-of-amplitudes will decay to zero in a super-exponential rate (recall that the normalization operation at the variable node keeps the sum of all amplitudes in a message to be 1). This completes the proof of the theorem. ∎
We now have to find which integer valued vector minimizes . The analysis is difficult because the weighting factor inside the sum of (17) performs exponential weighting of the excitation terms, where the dominant terms are those of the first iterations. Therefore, we can not use the asymptotic results of Lemma 9, but have to analyze the transient behavior. However, the analysis is simpler for the case of an LDLC with row and column degree of , so we shall first turn to this simple case (note that for this case, both the convolution in the check nodes and the product at the variable nodes involve only a single message).
Theorem 5
For a magic square LDLC with dimension , degree , and no 4-loops, consider the consistent Gaussians that relate to a given integer vector in the variable node messages that are sent at iteration (one consistent Gaussian per message). Denote the amplitudes of these Gaussians by , , and define the product-of-amplitudes as . Then:
The integer vector for which the consistent Gaussians will have the largest asymptotic product-of-amplitudes is the one for which is minimized, where is defined by (14) and is the noisy received codeword. 2. 2.
The product-of-amplitudes for the consistent Gaussians that correspond to all other integer vectors will decay to zero in an exponential rate.
Proof:
For (15) becomes:
[TABLE]
With solution:
[TABLE]
Denote . is well defined according to Lemma 9. For large , we then have . Therefore, for two lattice points with excitation sum terms which approach , respectively, the ratio of the corresponding product-of-amplitudes will approach
[TABLE]
If , the ratio decreases to zero exponentially (unlike the case of where the rate was super-exponential, as in (19)). This shows that the lattice point for which is minimized will have the largest product-of-amplitudes, where for all other lattice points, the product-of-amplitudes will decay to zero in an exponential rate (recall that the normalization operation at the variable node keeps the sum of all amplitudes in a message to be 1). This completes the proof of the second part of the theorem.
We still have to find the vector that minimizes . The basic difference between the case of and the case of is that for we need to analyze the transient behavior of the excitation terms, where for we only need to analyze the asymptotic behavior, which is much easier to handle.
According to Lemma 9, we have:
[TABLE]
where is defined by (14) and is the noisy received codeword. Therefore, for , the lattice points whose consistent Gaussians will have largest product-of-amplitudes is the point for which is minimized. This completes the proof of the theorem. ∎
For we could find an explicit expression for the “winning” lattice point. As discussed above, we could not find an explicit expression for , since the result depends on the transient behavior of the excitation sum term, and not only on the steady state value. However, a reasonable conjecture is to assume that that maximizes the steady state excitation will also maximize the term that depends on the transient behavior. This means that a reasonable conjecture is to assume that the “winning” lattice point for will also minimize an expression of the form (23).
Note that for we can still show that for “weak” noise, the ML point will have the minimal . To see that, it comes out from (13) that for zero noise, the ML lattice point will have for every and , where all other lattice points will have for at least some and . Therefore, the ML point will have a minimal excitation term along the transient behavior so it will surely have the minimal and the best product-of-amplitudes. As the noise increases, it is difficult to analyze the transient behavior of , as discussed above.
Note that the ML solution minimizes , where the above analysis yields minimization of . Obviously, for zero noise (i.e. ) both minimizations will give the correct solution with zero score. As the noise increases, the solutions may deviate from one another. Therefore, both minimizations will give the same solution for “weak” noise but may give different solutions for “strong” noise.
An example for another decoder that performs this form of minimization is the linear detector, which calculates (where denotes the nearest integer to ). This is equivalent to minimizing with . The linear detector fails to yield the ML solution if the noise is too strong, due to its inherent noise amplification.
For the LDLC iterative decoder, we would like that the deviation from the ML decoder due to the matrix would be negligible in the expected range of noise variance. Experimental results (see Section IX) show that the iterative decoder indeed converges to the ML solution for noise variance values that approach channel capacity. However, for quantization or shaping applications (see Section VIII-B), where the effective noise is uniformly distributed along the Voronoi cell of the lattice (and is much stronger than the noise variance at channel capacity) the iterative decoder fails, and this can be explained by the influence of the matrix on the minimization, as described above. Note from (14) that as , approaches a scaled identity matrix, which means that the minimization criterion approaches the ML criterion. However, the variances converge as , so as convergence time approaches infinity.
Until this point, we concentrated only on consistent Gaussians, and checked what lattice point maximizes the product-of-amplitudes of all the corresponding consistent Gaussians. However, this approach does not necessarily lead to the lattice point that will be finally chosen by the decoder, due to 3 main reasons:
It comes out experimentally that the strongest Gaussian in each message is not necessarily a consistent Gaussian, but a Gaussian that started as non-consistent and became consistent at a certain iteration. Such a Gaussian will finally converge to the appropriate lattice point, since the convergence of the mean values is independent of initial conditions. The non-consistency at the first several iterations, where the mean values are still very noisy, allows these Gaussians to accumulate stronger amplitudes than the consistent Gaussians (recall that the exponential weighting in (17) for results in strong dependency on the behavior at the first iterations). 2. 2.
There is an exponential number of Gaussians that start as non-consistent and become consistent (with the same integer vector ) at a certain iteration, and the final amplitude of the Gaussians at the lattice point coordinates will be determined by the sum of all these Gaussians. 3. 3.
We ignored non-consistent Gaussians that endlessly remain non-consistent. We have not shown it analytically, but it is reasonable to assume that the excitation terms for such Gaussians will be weaker than for Gaussians that become consistent at some point, so their amplitude will fade away to zero. However, non-consistent Gaussians are born every iteration, even at steady state. The “newly-born” non-consistent Gaussians may appear as sidelobes to the main impulse, since it may take several iterations until they are attenuated. Proper choice of the coefficients of may minimize this effect, as discussed in Sections III-A and V-A. However, these Gaussians may be a problem for small (e.g. ) where the product step at the variable node does not include enough messages to suppress them.
Note that the first two issues are not a problem for , where the winning lattice point depends only on the asymptotic behavior. The amplitude of a sum of Gaussians that converged to the same coordinates will still be governed by (21) and the winning lattice point will still minimize (23). The third issue is a problem for small , but less problematic for large , as described above.
As a result, we can not regard the convergence analysis of the consistent Gaussians’ amplitudes as a complete convergence analysis. However, it can certainly be used as a qualitative analysis that gives certain insights to the convergence process. Two main observations are:
The narrow variable node messages tend to converge to single impulses at the coordinates of a single lattice point. This results from (19), (22), which show that the “non-winning” consistent Gaussians will have amplitudes that decrease to zero relative to the amplitude of the “winning” consistent Gaussian. This result remains valid for the sum of non-consistent Gaussians that became consistent at a certain point, because it results from the non-stable nature of the recursion (12), which makes strong Gaussians stronger in an exponential manner. The single impulse might be accompanied by weak “sidelobes” due to newly-born non-consistent Gaussians.
Interestingly, this form of solution is different from the exact solution (1), where every lattice point is represented by an impulse at the appropriate coordinate, with amplitude that depends on the Euclidean distance of the lattice point from the observation. The iterative decoder’s solution has a single impulse that corresponds to a single lattice point, where all other impulses have amplitudes that decay to zero. This should not be a problem, as long as the ML point is the remaining point (see discussion above). 2. 2.
We have shown that for the strongest consistent Gaussians relate to that minimizes an expression of the form . We proposed a conjecture that this is also true for . We can further widen the conjecture to say that the finally decoded (and not only the that relates to strongest consistent Gaussians) minimizes such an expression. Such a conjecture can explain why the iterative decoder works well for decoding near channel capacity, but fails for quantization or shaping, where the effective noise variance is much larger.
IV-E Summary of Convergence Results
To summarize the convergence analysis, it was first shown that the variable node messages are Gaussian mixtures. Therefore, it is sufficient to analyze the sequences of variances, mean values and relative amplitudes of the Gaussians in each mixture. Starting with the variances, it was shown that with proper choice of the magic square LDLC generating sequence, each variable node generates “narrow” messages, whose variance decreases exponentially to zero, and a single “wide” message, whose variance reaches a finite value. Consistent Gaussians were then defined as Gaussians that their generation process always involved the same integer at the same check node. Consistent Gaussians can then be related to an integer vector or equivalently to the lattice point . It was then shown that under appropriate conditions on , the mean values of consistent Gaussians that belong to narrow messages converge to the coordinates of the appropriate lattice point. The mean values of wide messages also converge to these coordinates, but with a steady state error. Then, the amplitudes of consistent Gaussians were analyzed. For it was shown that the consistent Gaussians with maximal product-of-amplitudes (over all messages) are those that correspond to an integer vector than minimizes , where is a positive definite matrix that depends only on . The product-of-amplitudes for all other consistent Gaussians decays to zero. For the analysis is complex and depends on the transient behavior of the mean values and variances (and not only on their steady state values), but a reasonable conjecture is to assume that a same form of criterion is also minimized for . The result is different from the ML lattice point, which minimizes , where both criteria give the same point for weak noise but may give different solutions for strong noise. This may explain the experiments where the iterative decoder is successful in decoding the ML point for the AWGN channel near channel capacity, but fails in quantization or shaping applications where the effective noise is much stronger. These results also show that the iterative decoder converges to impulses at the coordinates of a single lattice point. It was then explained that analyzing the amplitudes of consistent Gaussians is not sufficient, so these results can not be regarded as a complete convergence analysis. However, the analysis gave a set of necessary conditions on , and also led to useful insights to the convergence process.
V Code Design
V-A Choosing the Generating Sequence
We shall concentrate on magic square LDLC, since they have inherent diversity of the nonzero elements in each row and column, which was shown above to be beneficial. It still remains to choose the LDLC generating sequence . Assume that the algorithm converged, and each PDF has a peak at the desired value. When the periodic functions are multiplied at a variable node, the correct peaks will then align. We would like that all the other peaks will be strongly attenuated, i.e. there will be no other point where the peaks align. This resembles the definition of the least common multiple (LCM) of integers: if the periods were integers, we would like to have their LCM as large as possible. This argument suggests the sequence , i.e. the reciprocals of the smallest prime numbers. Since the periods are , we will get the desired property. Simulations have shown that increasing beyond with this choice gave negligible improvement. Also, performance was improved by adding some “dither” to the sequence, resulting in . For , the first elements are used.
An alternative approach is a sequence of the form , where . For this case, every variable node will receive a single message with period and messages with period . For small , the period of these messages will be large and multiplication by the channel Gaussian will attenuate all the unwanted replicas. The single remaining replica will attenuate all the unwanted replicas of the message with period 1. A convenient choice is , which ensures that , as required by Theorem 1. As an example, for the sequence will be .
V-B Necessary Conditions on
The magic square LDLC definition and convergence analysis imply four necessary conditions on :
. This condition is part of the LDLC definition, which ensures proper density of the lattice points in . If , it can be easily normalized by dividing by . Note that practically we can allow as long as , since is the gain factor of the transmitted codeword. For example, if , having is acceptable, since we have , which means that the codeword has to be further amplified by dB, which is negligible.
Note that normalizing is applicable only if is non-singular. If is singular, a row and a column should be sequentially omitted until becomes full rank. This process may result in slightly reducing and a slightly different row and column degrees than originally planned. 2. 2.
, where . This guarantees exponential convergence rate for the variances (Theorem 1). Choosing a smaller results in faster convergence, but we should not take too small since the steady state variance of the wide variable node messages, as well as the steady state error of the mean values of these messages, increases when decreases, as discussed in Section IV-C. This may result in deviation of the decoded codeword from the ML codeword, as discussed in Section IV-D. For the first LDLC generating sequence of the previous subsection, we have and for and , respectively, which is a reasonable trade off. For the second sequence type we have . 3. 3.
All the eigenvalues of must have magnitude less than , where is defined in Theorem 2. This is a necessary condition for convergence of the mean values of the narrow messages. Note that adding random signs to the nonzero elements is essential to fulfill this necessary condition, as explained in Section IV-C. 4. 4.
All the eigenvalues of must have magnitude less than , where is defined in Theorem 3. This is a necessary condition for convergence of the mean values of the wide messages.
Interestingly, it comes out experimentally that for large codeword length and relatively small degree (e.g. and ), a magic square LDLC with generating sequence that satisfies and results in that satisfies all these four conditions: is nonsingular without any need to omit rows and columns, without any need for normalization, and all eigenvalues of and have magnitude less than 1 (typically, the largest eigenvalue of or has magnitude of , almost independently of and the choice of nonzero locations). Therefore, by simply dividing the first generating sequence of the previous subsection by its first element, the constructed meets all the necessary conditions, where the second type of sequence meets the conditions without any need for modifications.
V-C Construction of for Magic Square LDLC
We shall now present a simple algorithm for constructing a parity check matrix for a magic square LDLC. If we look at the bipartite graph, each variable node and each check node has edges connected to it, one with every possible weight . All the edges that have the same weight form a permutation from the variable nodes to the check nodes (or vice versa). The proposed algorithm generates random permutations and then searches sequentially and cyclically for 2-loops (two parallel edges from a variable node to a check node) and 4-loops (two variable nodes that both are connected to a pair of check nodes). When such a loop is found, a pair is swapped in one of the permutations such that the loop is removed. A detailed pseudo-code for this algorithm is given in Appendix G.
VI Decoder Implementation
Each PDF should be approximated with a discrete vector with resolution and finite range. According to the Gaussian Q-function, choosing a range of, say, to both sides of the noisy channel observation will ensure that the error probability due to PDF truncation will be . Near capacity, , so . Simulation showed that resolution errors became negligible for . Each PDF was then stored in a elements vector, corresponding to a range of size .
At the check node, the PDF that arrives from variable node is first expanded by (the appropriate coefficient of ) to get . In a discrete implementation with resolution the PDF is a vector of values , . As described in Section V, we shall usually use so the expanded PDF will be shorter than the original PDF. If the expand factor was an integer, we could simply decimate by . However, in general it is not an integer so we should use some kind of interpolation. The PDF is certainly not band limited, and as the iterations go on it approaches an impulse, so simple interpolation methods (e.g. linear) are not suitable. Suppose that we need to calculate , where . A simple interpolation method which showed to be effective is to average around the desired point, where the averaging window length is chosen to ensure that every sample of is used in the interpolation of at least one output point. This ensures that an impulse can not be missed. The interpolation result is then , where .
The most computationally extensive step at the check nodes is the calculation the convolution of expanded PDF’s. An efficient method is to calculate the fast Fourier transforms (FFTs) of all the PDF’s, multiply the results and then perform inverse FFT (IFFT). The resolution of the FFT should be larger than the expected convolution length, which is roughly , where denotes the original PDF length. Appendix H shows a way to use FFTs of size , where is the resolution of the PDF. Usually so FFT complexity is significantly reduced. Practical values are and , which give an improvement factor of at least in complexity.
Each variable node receives check node messages. The output variable node message is calculated by generating the product of input messages and the channel Gaussian. As the iterations go on, the messages get narrow and may become impulses, with only a single nonzero sample. Quantization effects may cause impulses in two messages to be shifted by one sample. This will result in a zero output (instead of an impulse). Therefore, it was found useful to widen each check node message prior to multiplication, such that , i.e. the message is added to its right shifted and left shifted (by one sample) versions.
VII Computational Complexity and Storage Requirements
Most of the computational effort is invested in the FFT’s and IFFT’s (of length ) that each check node performs each iteration. The total number of multiplications for iterations is . As in binary LDPC codes, the computational complexity has the attractive property of being linear with block length. However, the constant that precedes the linear term is significantly higher, mainly due to the FFT operations.
The memory requirements are governed by the storage of the check node and variable node messages, with total memory of . Compared to binary LDPC, the factor of significantly increases the required memory. For example, for , and , the number of storage elements is of the order of .
VIII Encoding and Shaping
VIII-A Encoding
The LDLC encoder has to calculate , where is an integer message vector. Note that unlike , is not sparse, in general, so the calculation requires computational complexity and storage of . This is not a desirable property because the decoder’s computational complexity is only . A possible solution is to use the Jacobi method [22] to solve , which is a system of sparse linear equations. Using this method, a magic square LDLC encoder calculates several iterations of the form:
[TABLE]
with initialization . The matrix is defined in Lemma 6 of Section IV-C. The vector is a permuted and scaled version of the integer vector , such that the ’th element of equals the element of for which the appropriate row of has its largest magnitude value at the ’th location. This element is further divided by this largest magnitude element.
A necessary and sufficient condition for convergence to is that all the eigenvalues of have magnitude less than [22]. However, it was shown that this is also a necessary condition for convergence of the LDLC iterative decoder (see Sections IV-C, V-B), so it is guaranteed to be fulfilled for a properly designed magic square LDLC. Since is sparse, this is an algorithm, both in complexity and storage.
VIII-B Shaping
For practical use with the power constrained AWGN channel, the encoding operation must be accompanied by shaping, in order to prevent the transmitted codeword’s power from being too large. Therefore, instead of mapping the information vector to the lattice point , it should be mapped to some other lattice point , such that the lattice points that are used as codewords belong to a shaping region (e.g. an -dimensional sphere). The shaping operation is the mapping of the integer vector to the integer vector .
As explained in Section II-A, this work concentrates on the lattice design and the lattice decoding algorithm, and not on the shaping region or shaping algorithms. Therefore, this section will only highlight some basic shaping principles and ideas.
A natural shaping scheme for lattice codes is nested lattice coding [12]. In this scheme, shaping is done by quantizing the lattice point onto a coarse lattice , where the transmitted codeword is the quantization error, which is uniformly distributed along the Voronoi cell of the coarse lattice. If the second moment of this Voronoi cell is close to that of an -dimensional sphere, the scheme will attain close-to-optimal shaping gain. Specifically, assume that the information vector assumes integer values in the range for some constant integer . Then, we can choose the coarse lattice to be . The volume of the Voronoi cell for this lattice is , since we assume (see Section II-A). If the shape of the Voronoi cell resembles an -dimensional sphere (as expected from a capacity approaching lattice code), it will attain optimal shaping gain (compared to uncoded transmission of the original integer sequence ).
The shaping operation will find the coarse lattice point , , which is closest to the fine lattice point . The transmitted codeword will be:
[TABLE]
where (note that the “inverse shaping” at the decoder, i.e. transforming from to , is a simple modulo calculation: ). Finding the closest coarse lattice point to is equivalent to finding the closest fine lattice point to the vector . This is exactly the operation of the iterative LDLC decoder, so we could expect that is could be used for shaping. However, simulations show that the iterative decoding finds a vector with poor shaping gain. The reason is that for shaping, the effective noise is much stronger than for decoding, and the iterative decoder fails to find the nearest lattice point if the noise is too large (see Section IV-D).
Therefore, an alternative algorithm has to be used for finding the nearest coarse lattice point. The complexity of finding the nearest lattice point grows exponentially with the lattice dimension and is not feasible for large dimensions [23]. However, unlike decoding, for shaping applications it is not critical to find the exact nearest lattice point, and approximate algorithms may be considered (see [15]). A possible method [24] is to perform QR decomposition on in order to transform to a lattice with upper triangular generator matrix, and then use sequential decoding algorithms (such as the Fano algorithm) to search the resulting tree. The main disadvantage of this approach is computational complexity and storage of at least . Finding an efficient shaping scheme for LDLC is certainly a topic for further research.
IX Simulation Results
Magic square LDLC with the first generating sequence of Section V-A (i.e. ) were simulated for the AWGN channel at various block lengths. The degree was for and for all other . For the matrix was further normalized to get . For all other , normalizing the generating sequence such that the largest element has magnitude also gave the desired determinant normalization (see Section V-B). The matrices were generated using the algorithm of Section V-C. PDF resolution was set to with a total range of , i.e. each PDF was represented by a vector of elements. High resolution was used since our main target is to prove the LDLC concept and eliminate degradation due to implementation considerations. For this reason, the decoder was used with 200 iterations (though most of the time, a much smaller number was sufficient).
In all simulations the all-zero codeword was used. Approaching channel capacity is equivalent to (see Section II-A), so performance is measured in symbol error rate (SER), vs. the distance of the noise variance from capacity (in dB). The results are shown in Figure 4. At SER of , for , , , we can work as close as dB, dB, dB and dB from capacity, respectively.
Similar results were obtained for with the second type of generating sequence of Section V-A, i.e. . Results were slightly worse than for the first generating sequence (by less than 0.1 dB). Increasing did not give any visible improvement.
X Conclusion
Low density lattice codes (LDLC) were introduced. LDLC are novel lattice codes that can approach capacity and be decoded efficiently. Good error performance within dB from capacity at block length of 100,000 symbols was demonstrated. Convergence analysis was presented for the iterative decoder, which is not complete, but yields necessary conditions on and significant insight to the convergence process. Code parameters were chosen from intuitive arguments, so it is reasonable to assume that when the code structure will be more understood, better parameters could be found, and channel capacity could be approached even closer.
Multi-input, multi-output (MIMO) communication systems have become popular in recent years. Lattice codes have been proposed in this context as space-time codes (LAST) [25]. The concatenation of the lattice encoder and the MIMO channel generates a lattice. If LDLC are used as lattice codes and the MIMO configuration is small, the inverse generator matrix of this concatenated lattice can be assumed to be sparse. Therefore, the MIMO channel and the LDLC can be jointly decoded using an LDLC-like decoder. However, even if a magic square LDLC is used as the lattice code, the concatenated lattice is not guaranteed to be equivalent to a magic square LDLC, and the necessary conditions for convergence are not guaranteed to be fulfilled. Therefore, the usage of LDLC for MIMO systems is a topic for further research.
Appendix A Exact PDF Calculations
Given the -dimensional noisy observation of the transmitted codeword , we would like to calculate the probability density function (PDF) . We shall start by calculating . Denote the shaping region by ( will be used to denote both the lattice and its generator matrix). is a sum of -dimensional Dirac delta functions, since has nonzero probability only for the lattice points that lie inside the shaping region. Assuming further that all codewords are used with equal probability, all these delta functions have equal weight of . The expression for