The on-line shortest path problem under partial monitoring
Andras Gyorgy, Tamas Linder, Gabor Lugosi, Gyorgy Ottucsak

TL;DR
This paper introduces an online algorithm for the shortest path problem under partial monitoring, achieving near-optimal regret bounds with efficient implementation, and extends it to various settings including label-efficient and tracking scenarios.
Contribution
It presents a new online learning algorithm for shortest path under partial feedback with polynomial complexity and extends it to label-efficient and dynamic path tracking settings.
Findings
Achieves regret proportional to 1/√n with polynomial complexity.
Extends to label-efficient settings with limited feedback.
Demonstrates effectiveness in routing applications with simulation results.
Abstract
The on-line shortest path problem is considered under various models of partial monitoring. Given a weighted directed acyclic graph whose edge weights can change in an arbitrary (adversarial) way, a decision maker has to choose in each round of a game a path between two distinguished vertices such that the loss of the chosen path (defined as the sum of the weights of its composing edges) be as small as possible. In a setting generalizing the multi-armed bandit problem, after choosing a path, the decision maker learns only the weights of those edges that belong to the chosen path. For this problem, an algorithm is given whose average cumulative loss in n rounds exceeds that of the best path, matched off-line to the entire sequence of the edge weights, by a quantity that is proportional to 1/\sqrt{n} and depends only polynomially on the number of edges of the graph. The algorithm can be…
Click any figure to enlarge with its caption.
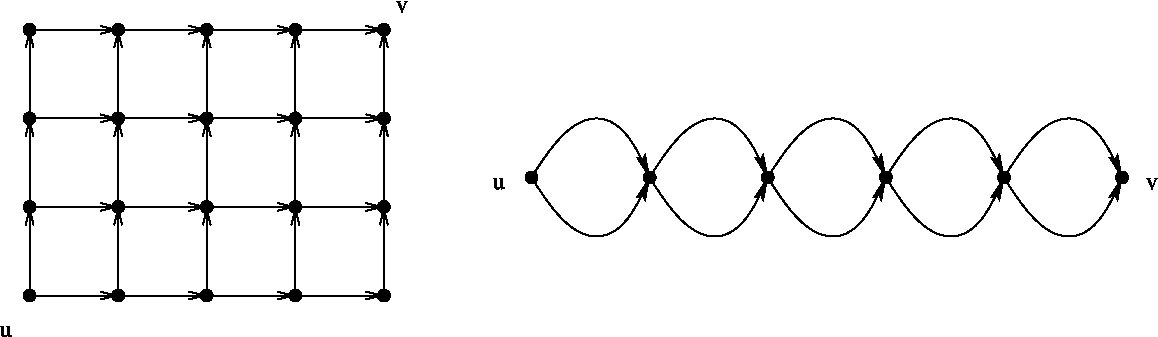 Figure 1
Peer Reviews
No public reviews on file for this paper yet. If you reviewed it on a platform where reviews are public (OpenReview, ICLR, NeurIPS, ICML), you can paste yours below so the community can read it here.
Videos
No videos yet. Explain this paper in a talk, walkthrough, or lecture? Add one.
Taxonomy
TopicsAdvanced Bandit Algorithms Research · Optimization and Search Problems · Machine Learning and Algorithms
The on-line shortest path problem under partial monitoring
András György Tamás Linder Gábor Lugosi
György Ottucsák A. György is with the Machine Learning Research Group, Computer and Automation Research Institute of the Hungarian Academy of Sciences, Kende u. 11-13, Budapest, Hungary, H-1111 (email: [email protected]). T. Linder is with the Department of Mathematics and Statistics, Queen’s University, Kingston, Ontario, Canada K7L 3N6 (email: [email protected]). G. Lugosi is with ICREA and Department of Economics, Universitat Pompeu Fabra, Ramon Trias Fargas 25-27, 08005 Barcelona, Spain (email: [email protected]). Gy. Ottucsák is with Department of Computer Science and Information Theory, Budapest University of Technology and Economics, Magyar Tudósok Körútja 2., Budapest, Hungary, H-1117. He is also with the Machine Learning Research Group, Computer and Automation Research Institute of the Hungarian Academy of Sciences (email: [email protected]).
This research was supported in part by the János Bolyai Research Scholarship of the Hungarian Academy of Sciences, the Mobile Innovation Center of Hungary, by the Natural Sciences and Engineering Research Council (NSERC) of Canada, by the Spanish Ministry of Science and Technology grant MTM2006-05650, by the PASCAL Network of Excellence under EC grant no. 506778 and by the High Speed Networks Laboratory, Department of Telecommunications and Media Informatics, Budapest University of Technology and Economics. Parts of this paper have been presented at COLT’06.
Abstract
The on-line shortest path problem is considered under various models of partial monitoring. Given a weighted directed acyclic graph whose edge weights can change in an arbitrary (adversarial) way, a decision maker has to choose in each round of a game a path between two distinguished vertices such that the loss of the chosen path (defined as the sum of the weights of its composing edges) be as small as possible. In a setting generalizing the multi-armed bandit problem, after choosing a path, the decision maker learns only the weights of those edges that belong to the chosen path. For this problem, an algorithm is given whose average cumulative loss in rounds exceeds that of the best path, matched off-line to the entire sequence of the edge weights, by a quantity that is proportional to and depends only polynomially on the number of edges of the graph. The algorithm can be implemented with linear complexity in the number of rounds and in the number of edges. An extension to the so-called label efficient setting is also given, in which the decision maker is informed about the weights of the edges corresponding to the chosen path at a total of time instances. Another extension is shown where the decision maker competes against a time-varying path, a generalization of the problem of tracking the best expert. A version of the multi-armed bandit setting for shortest path is also discussed where the decision maker learns only the total weight of the chosen path but not the weights of the individual edges on the path. Applications to routing in packet switched networks along with simulation results are also presented.
Index Terms: On-line learning, shortest path problem, multi-armed bandit problem.
1 Introduction
In a sequential decision problem, a decision maker (or forecaster) performs a sequence of actions. After each action the decision maker suffers some loss, depending on the response (or state) of the environment, and its goal is to minimize its cumulative loss over a certain period of time. In the setting considered here, no probabilistic assumption is made on how the losses corresponding to different actions are generated. In particular, the losses may depend on the previous actions of the decision maker, whose goal is to perform well relative to a set of reference forecasters (the so-called “experts”) for any possible behavior of the environment. More precisely, the aim of the decision maker is to achieve asymptotically the same average (per round) loss as the best expert.
Research into this problem started in the 1950s (see, for example, Blackwell [5] and Hannan [18] for some of the basic results) and gained new life in the 1990s following the work of Vovk [29], Littlestone and Warmuth [24], and Cesa-Bianchi et al. [7]. These results show that for any bounded loss function, if the decision maker has access to the past losses of all experts, then it is possible to construct on-line algorithms that perform, for any possible behavior of the environment, almost as well as the best of experts. More precisely, the per round cumulative loss of these algorithms is at most as large as that of the best expert plus a quantity proportional to for any bounded loss function, where is the number of rounds in the decision game. The logarithmic dependence on the number of experts makes it possible to obtain meaningful bounds even if the pool of experts is very large.
In certain situations the decision maker has only limited knowledge about the losses of all possible actions. For example, it is often natural to assume that the decision maker gets to know only the loss corresponding to the action it has made, and has no information about the loss it would have suffered had it made a different decision. This setup is referred to as the multi-armed bandit problem, and was considered, in the adversarial setting, by Auer et al. [1] who gave an algorithm whose normalized regret (the difference of the algorithm’s average loss and that of the best expert) is upper bounded by a quantity which is proportional to . Note that, compared to the full information case described above where the losses of all possible actions are revealed to the decision maker, there is an extra factor in the performance bound, which seriously limits the usefulness of the bound if the number of experts is large.
Another interesting example for the limited information case is the so-called label efficient decision problem (see Helmbold and Panizza [22]) in which it is too costly to observe the state of the environment, and so the decision maker can query the losses of all possible actions for only a limited number of times. A recent result of Cesa-Bianchi, Lugosi, and Stoltz [9] shows that in this case, if the decision maker can query the losses times during a period of length , then it can achieve average excess loss relative to the best expert.
In many applications the set of experts has a certain structure that may be exploited to construct efficient on-line decision algorithms. The construction of such algorithms has been of great interest in computational learning theory. A partial list of works dealing with this problem includes Herbster and Warmuth [19], Vovk [30], Bousquet and Warmuth [6], Helmbold and Schapire [27], Takimoto and Warmuth [28], Kalai and Vempala [23], György at al. [13, 14, 15]. For a more complete survey, we refer to Cesa-Bianchi and Lugosi [8, Chapter 5].
In this paper we study the on-line shortest path problem, a representative example of structured expert classes that has received attention in the literature for its many applications, including, among others, routing in communication networks; see, e.g., Takimoto and Warmuth [28], Awerbuch et al. [3], or György and Ottucsák [17], and adaptive quantizer design in zero-delay lossy source coding; see, György et al. [13, 14, 16]. In this problem, a weighted directed (acyclic) graph is given whose edge weights can change in an arbitrary manner, and the decision maker has to pick in each round a path between two given vertices, such that the weight of this path (the sum of the weights of its composing edges) be as small as possible.
Efficient solutions, with time and space complexity proportional to the number of edges rather than to the number of paths (the latter typically being exponential in the number of edges), have been given in the full information case, where in each round the weights of all the edges are revealed after a path has been chosen; see, for example, Mohri [26], Takimoto and Warmuth [28], Kalai and Vempala [23], and György et al. [15].
In the bandit setting only the weights of the edges or just the sum of the weights of the edges composing the chosen path are revealed to the decision maker. If one applies the general bandit algorithm of Auer et al. [1], the resulting bound will be too large to be of practical use because of its square-root-type dependence on the number of paths . On the other hand, using the special graph structure in the problem, Awerbuch and Kleinberg [4] and McMahan and Blum [25] managed to get rid of the exponential dependence on the number of edges in the performance bound. They achieved this by extending the exponentially weighted average predictor and the follow-the-perturbed-leader algorithm of Hannan [18] to the generalization of the multi-armed bandit setting for shortest paths, when only the sum of the weights of the edges is available for the algorithm. However, the dependence of the bounds obtained in [4] and [25] on the number of rounds is significantly worse than the bound of Auer et al. [1]. Awerbuch and Kleinberg [4] consider the model of “non-oblivious” adversaries for shortest path (i.e., the losses assigned to the edges can depend on the previous actions of the forecaster) and prove an bound for the expected per-round regret. McMahan and Blum [25] give a simpler algorithm than in [4] however obtain a bound of the order of for the expected regret.
In this paper we provide an extension of the bandit algorithm of Auer et al. [1] unifying the advantages of the above approaches, with a performance bound that is polynomial in the number of edges, and converges to zero at the right rate as the number of rounds increases. We achieve this bound in a model which assumes that the losses of all edges on the path chosen by the forecaster are available separately after making the decision. We also discuss the case (considered by [4] and [25]) in which only the total loss (i.e., the sum of the losses on the chosen path) is known to the decision maker. We exhibit a simple algorithm which achieves an per-round regret with high probability against “non-oblivious” adversary. In this case it remains an open problem to find an algorithm whose cumulative loss is polynomial in the number of edges of the graph and decreases as with the number of rounds.
In Section 2 we formally define the on-line shortest path problem, which is extended to the multi-armed bandit setting in Section 3. Our new algorithm for the shortest path problem in the bandit setting is given in Section 4 together with its performance analysis. The algorithm is extended to solve the shortest path problem in a combined label efficient multi-armed bandit setting in Section 5. Another extension, when the algorithm competes against a time-varying path is studied in Section 6. An algorithm for the “restricted” multi-armed bandit setting (when only the sums of the losses of the edges are available) is given in Section 7. Simulation results are presented in Section 8.
2 The shortest path problem
Consider a network represented by a set of vertices connected by edges, and assume that we have to send a stream of packets from a distinguished vertex, called source, to another distinguished vertex, called destination. At each time slot a packet is sent along a chosen route connecting source and destination. Depending on the traffic, each edge in the network may have a different delay, and the total delay the packet suffers on the chosen route is the sum of delays of the edges composing the route. The delays may change from one time slot to the next one in an arbitrary way, and our goal is to find a way of choosing the route in each time slot such that the sum of the total delays over time is not significantly more than that of the best fixed route in the network. This adversarial version of the routing problem is most useful when the delays on the edges can change dynamically, even depending on our previous routing decisions. This is the situation in the case of ad-hoc networks, where the network topology can change rapidly, or in certain secure networks, where the algorithm has to be prepared to handle denial of service attacks, that is, situations where willingly malfunctioning vertices and links increase the delay; see, e.g., Awerbuch et al. [3].
This problem can be cast naturally as a sequential decision problem in which each possible route is represented by an action. However, the number of routes is typically exponentially large in the number of edges, and therefore computationally efficient algorithms are called for. Two solutions of different flavor have been proposed. One of them is based on a follow-the-perturbed-leader forecaster, see Kalai and Vempala [23], while the other is based on an efficient computation of the exponentially weighted average forecaster, see, for example, Takimoto and Warmuth [28]. Both solutions have different advantages and may be generalized in different directions.
To formalize the problem, consider a (finite) directed acyclic graph with a set of edges and a set of vertices . Thus, each edge is an ordered pair of vertices . Let and be two distinguished vertices in . A path from to is a sequence of edges such that , for all , and . Let denote the set of all such paths. For simplicity, we assume that every edge in is on some path from to and every vertex in is an endpoint of an edge (see Figure 1 for examples).
In each round of the decision game, the decision maker chooses a path among all paths from to . Then a loss is assigned to each edge . We write if the edge belongs to the path , and with a slight abuse of notation the loss of a path at time slot is also represented by . Then is given as
[TABLE]
and therefore the cumulative loss up to time of each path takes the additive form
[TABLE]
where the inner sum on the right-hand side is the loss accumulated by edge during the first rounds of the game. The cumulative loss of the algorithm is
[TABLE]
It is well known that for a general loss sequence, the decision maker must be allowed to use randomization to be able to approximate the performance of the best expert (see, e.g., Cesa-Bianchi and Lugosi [8]). Therefore, the path is chosen randomly according to some distribution over all paths from to . We study the normalized regret over rounds of the game
[TABLE]
where the minimum is taken over all paths from to .
For example, the exponentially weighted average forecaster ([29], [24], [7]), calculated over all possible paths, has regret
[TABLE]
with probability at least , where is the total number of paths from to in the graph and is the length of the longest path.
3 The multi-armed bandit setting
In this section we discuss the “bandit” version of the shortest path problem. In this setup, which is more realistic in many applications, the decision maker has only access to the losses corresponding to the paths it has chosen. For example, in the routing problem this means that information is available on the delay of the route the packet is sent on, and not on other routes in the network.
We distinguish between two types of bandit problems, both of which are natural generalizations of the simple bandit problem to the shortest path problem. In the first variant, the decision maker has access to the losses of those edges that are on the path it has chosen. That is, after choosing a path at time , the value of the loss is revealed to the decision maker if and only if . We study this case and its extensions in Sections 4, 5, and 6.
The second variant is a more restricted version in which the loss of the chosen path is observed, but no information is available on the individual losses of the edges belonging to the path. That is, after choosing a path at time , only the value of the loss of the path is revealed to the decision maker. Further on we call this setting as the restricted bandit problem for shortest path. We consider this restricted problem in Section 7.
Formally, the on-line shortest path problem in the multi-armed bandit setting is described as follows: at each time instance , the decision maker picks a path from to . Then the environment assigns loss to each edge , and the decision maker suffers loss . In the unrestricted case the losses are revealed for all , while in the restricted case only is revealed. Note that in both cases may depend on , the earlier choices of the decision maker.
For the basic multi-armed bandit problem, Auer et al. [1] gave an algorithm, based on exponential weighting with a biased estimate of the gains (defined, in our case, as ), combined with uniform exploration. Applying their algorithm to the on-line shortest path problem in the bandit setting results in a performance that can be bounded, for any and fixed time horizon , with probability at least , by
[TABLE]
(The constants follow from a slightly improved version; see Cesa-Bianchi and Lugosi [8].)
However, for the shortest path problem this bound is unacceptably large because, unlike in the full information case, here the dependence on the number of all paths is not merely logarithmic, while is typically exponentially large in the size of the graph (as in the two simple examples of Figure 1). In order to achieve a bound that does not grow exponentially with the number of edges of the graph, it is imperative to make use of the dependence structure of the losses of the different actions (i.e., paths). Awerbuch and Kleinberg [4] and McMahan and Blum [25] do this by extending low complexity predictors, such as the follow-the-perturbed-leader forecaster [18], [23] to the restricted bandit setting. However, in both cases the price to pay for the polynomial dependence on the number of edges is a worse dependence on the length of the game.
4 A bandit algorithm for shortest paths
In this section we describe a variant of the bandit algorithm of [1] which achieves the desired performance for the shortest path problem. The new algorithm uses the fact that when the losses of the edges of the chosen path are revealed, then this also provides some information about the losses of each path sharing common edges with the chosen path.
For each edge , and , introduce the gain , and for each path , let the gain be the sum of the gains of the edges on the path, that is,
[TABLE]
The conversion from losses to gains is done in order to facilitate the subsequent performance analysis. To simplify the conversion, we assume that each path is of the same length for some . Note that although this assumption may seem to be restrictive at the first glance, from each acyclic directed graph one can construct a new graph by adding at most vertices and edges (with constant weight zero) to the graph without modifying the weights of the paths such that each path from to will be of length , where denotes the length of the longest path of the original graph. If the number of edges is quadratic in the number of vertices, the size of the graph is not increased substantially.
A main feature of the algorithm below is that the gains are estimated for each edge and not for each path. This modification results in an improved upper bound on the performance with the number of edges in place of the number of paths. Moreover, using dynamic programming as in Takimoto and Warmuth [28], the algorithm can be computed efficiently. Another important ingredient of the algorithm is that one needs to make sure that every edge is sampled sufficiently often. To this end, we introduce a set of covering paths with the property that for each edge there is a path such that . Observe that one can always find such a covering set of cardinality .
We note that the algorithm of [1] is a special case of the algorithm below: For any multi-armed bandit problem with experts, one can define a graph with two vertices and , and directed edges from to with weights corresponding to the losses of the experts. The solution of the shortest path problem in this case is equivalent to that of the original bandit problem with choosing expert if the corresponding edge is chosen. For this graph, our algorithm reduces to the original algorithm of [1].
A BANDIT ALGORITHM FOR SHORTEST PATHS
Parameters: real numbers , .
Initialization: Set for each , for each , and . For each round
(a)
Choose a path at random according to the distribution on , defined by
p_{\boldsymbol{i},t}=\begin{cases}(1-\gamma)\frac{\overline{w}_{\boldsymbol{i},t-1}}{\overline{W}_{t-1}}+\frac{\gamma}{|\mathcal{C}|}&\text{ if \boldsymbol{i}\in\mathcal{C}}\\ (1-\gamma)\frac{\overline{w}_{\boldsymbol{i},t-1}}{\overline{W}_{t-1}}&\text{ if \boldsymbol{i}\not\in\mathcal{C}.}\end{cases}
(b)
Compute the probability of choosing each edge as
(c)
Calculate the estimated gains
g^{\prime}_{e,t}=\begin{cases}\frac{g_{e,t}+\beta}{q_{e,t}}&\text{ if e\in\boldsymbol{I}_{t}}\\ \frac{\beta}{q_{e,t}}&\text{ otherwise.}\end{cases}
(d)
Compute the updated weights
where , and the sum of the total weights of the paths
The main result of the paper is the following performance bound for the shortest-path bandit algorithm. It states that the per round regret of the algorithm, after rounds of play, is, roughly, of the order of where is the number of edges of the graph, is the length of the paths, and is the total number of paths.
Theorem 1
For any and parameters , , and satisfying , the performance of the algorithm defined above can be bounded, with probability at least , as
[TABLE]
In particular, choosing , , and yields for all ,
[TABLE]
The proof of the theorem is based on the analysis of the original algorithm of [1] with necessary modifications required to transform parts of the argument from paths to edges, and to use the connection between the gains of paths sharing common edges.
For the analysis we introduce some notation:
[TABLE]
for each and
[TABLE]
for each , and
[TABLE]
The following lemma, shows that the deviation of the true cumulative gain from the estimated cumulative gain is of the order of . The proof is a modification of [8, Lemma 6.7].
Lemma 1
For any , and we have
[TABLE]
Proof. Fix . For any and , by the Chernoff bound we have
[TABLE]
Letting and , we get
[TABLE]
so it suffices to prove that for all . To this end, introduce
[TABLE]
Below we show that for where denotes the conditional expectation . Clearly,
[TABLE]
Taking conditional expectations, we obtain
[TABLE]
Here (2) holds since , and for . (4) follows from . Finally, (4) holds by the inequality . Taking expectations on both sides proves . A similar argument shows that , implying as desired.
Proof of Theorem 1. As usual in the analysis of exponentially weighted average forecasters, we start with bounding the quantity . On the one hand, we have the lower bound
[TABLE]
To derive a suitable upper bound, first notice that the condition implies for all and , since
[TABLE]
where the second inequality follows because for each .
Therefore, using the fact that for all , for all we have
[TABLE]
where (4) follows form the definition of , and (7) holds by the inequality for all .
Next we bound the sums in (7). On the one hand,
[TABLE]
On the other hand,
[TABLE]
where the first inequality is due to the inequality between the arithmetic and quadratic mean, and the second one holds because . Therefore,
[TABLE]
Summing for , we obtain
[TABLE]
where the second inequality follows since . Combining the upper bound with the lower bound (5), we obtain
[TABLE]
Now using Lemma 1 and applying the union bound, for any we have that, with probability at least ,
[TABLE]
where we used which follows from the assumptions of the theorem.
Since and for all , we have
[TABLE]
with probability at least . This implies
[TABLE]
with probability at least , which is the first statement of the theorem. Setting
[TABLE]
results in the inequality
[TABLE]
which holds with probability at least if (to ensure ). Finally, setting
[TABLE]
yields the last statement of the theorem ( is required to ensure ).
Next we analyze the computational complexity of the algorithm. The next result shows that the algorithm is feasible as its complexity is linear in the size (number of edges) of the graph.
Theorem 2
The proposed algorithm can be implemented efficiently with time complexity and space complexity .
Proof. The two complex steps of the algorithm are steps (a) and (b), both of which can be computed, similarly to Takimoto and Warmuth [28], using dynamic programming. To perform these steps efficiently, first we order the vertices of the graph. Since we have an acyclic directed graph, its vertices can be labeled (in time) from to such that , , and if , then . For any pair of vertices let denote the set of paths from to , and for any vertex , let
[TABLE]
and
[TABLE]
Given the edge weights , can be computed recursively for , and can be computed recursively for in time (letting by definition). In step (a), first one has to decide with probability whether is generated according to the graph weights, or it is chosen uniformly from . If is to be drawn according to the graph weights, it can be shown that its vertices can be chosen one by one such that if the first vertices of are , then the next vertex of can be chosen to be any , satisfying , with probability . The other computationally demanding step, namely step (b), can be performed easily by noting that for any edge ,
[TABLE]
as desired.
5 A combination of the label efficient and bandit settings
In this section we investigate a combination of the multi-armed bandit and the label efficient problems. This means that the decision maker only has access to the loss of the chosen path upon request and the total number of requests must be bounded by a constant . This combination is motivated by some applications, in which feedback information is costly to obtain.
In the general label efficient decision problem, after taking an action, the decision maker has the option to query the losses of all possible actions. For this problem, Cesa-Bianchi et al. [9] proved an upper bound on the normalized regret of order which holds with probability at least .
Our model of the label-efficient bandit problem for shortest paths is motivated by an application to a particular packet switched network model. This model, called the cognitive packet network, was introduced by Gelenbe et al. [11, 12]. In these networks a particular type of packets, called smart packets, are used to explore the network (e.g., the delay of the chosen path). These packets do not carry any useful data; they are merely used for exploring the network. The other type of packets are the data packets, which do not collect any information about their paths. The task of the decision maker is to send packets from the source to the destination over routes with minimum average transmission delay (or packet loss). In this scenario, smart packets are used to query the delay (or loss) of the chosen path. However, as these packets do not transport information, there is a tradeoff between the number of queries and the usage of the network. If data packets are on the average times larger than smart packets (note that typically ) and is the proportion of time instances when smart packets are used to explore the network, then is the proportion of the bandwidth sacrificed for well informed routing decisions.
We study a combined algorithm which, at each time slot , queries the loss of the chosen path with probability (as in the solution of the label efficient problem proposed in [9]), and, similarly to the multi-armed bandit case, computes biased estimates of the true gains . Just as in the previous section, it is assumed that each path of the graph is of the same length .
The algorithm differs from our bandit algorithm of the previous section only in step (c), which is modified in the spirit of [9]. The modified step is given below:
MODIFIED STEP FOR THE LABEL EFFICIENT BANDIT ALGORITHM FOR SHORTEST PATHS
(c’)
Draw a Bernoulli random variable with , and compute the estimated gains
g^{\prime}_{e,t}=\begin{cases}\frac{g_{e,t}+\beta}{\epsilon q_{e,t}}S_{t}&\text{ if e\in\boldsymbol{I}{t}}\\ \frac{\beta}{\epsilon q_{e,t}}S_{t}&\text{ ife\notin\boldsymbol{I}{t} }~{}.\end{cases}
The performance of the algorithm is analyzed in the next theorem, which can be viewed as a combination of Theorem 1 in the preceding section and Theorem 2 of [9].
Theorem 3
For any , , parameters , , and , and for all
[TABLE]
the performance of the algorithm defined above can be bounded, with probability at least , as
[TABLE]
If is chosen as then, with probability at least , the total number of queries is bounded by (see [8, Lemma 6.1]) and the performance bound above is of the order of .
Similarly to Theorem 1, we need a lemma which reveals the connection between the true and the estimated cumulative losses. However, here we need a more careful analysis because the “shifting term” , is a random variable.
Lemma 2
For any , , for any
[TABLE]
parameters
[TABLE]
and , we have
[TABLE]
Proof. Fix . Using (1) with and , it suffices to prove for all that
[TABLE]
Similarly to Lemma 1 we introduce and we show that is a supermartingale, that is for where denotes . Taking conditional expectations, we obtain
[TABLE]
Since
[TABLE]
and
[TABLE]
we get from (10) that
[TABLE]
Since we have
[TABLE]
where (12) follows from and (13) holds by
[TABLE]
and the last inequality is ensured by , the assumption of the lemma.
Combining (11) and (13) we get that . Taking expectations on both sides of the inequality, we get and since , we obtain as desired.
Proof of Theorem 3. The proof of the theorem is a generalization of that of Theorem 1, and follows the same lines with some extra technicalities to handle the effects of the modified step (c’). Therefore, in the following we emphasize only the differences. First note that (5) and (7) also hold in this case. Bounding the sums in (7), one obtains
[TABLE]
and
[TABLE]
Plugging these bounds into (7) and summing for , we obtain
[TABLE]
Combining the upper bound with the lower bound (5), we obtain
[TABLE]
To relate the left-hand side of the above inequality to the real gain , notice that
[TABLE]
is a martingale difference sequence with respect to . Now for all , we have the bound
[TABLE]
where (15) holds by (to ensure ). We know that
[TABLE]
for all . Now apply Bernstein’s inequality for martingale differences (see Lemma 9 in the Appendix) to obtain
[TABLE]
where
[TABLE]
From (16) we get
[TABLE]
Now Lemma 2, the union bound, and (17) combined with (14) yield, with probability at least ,
[TABLE]
since the coefficient of is greater than zero by the assumptions of the theorem.
Since and , we have
[TABLE]
where we used the fact that .
Substituting the value of , and , we have
[TABLE]
as desired.
6 A bandit algorithm for tracking the shortest path
Our goal in this section is to extend the bandit algorithm so that it is able to compete with time-varying paths under small computational complexity. This is a variant of the problem known as tracking the best expert; see, for example, Herbster and Warmuth [19], Vovk [30], Auer and Warmuth [2], Bousquet and Warmuth [6], Herbster and Warmuth [20].
To describe the loss the decision maker is compared to, consider the following “-partition” prediction scheme: the sequence of paths is partitioned into contiguous segments, and on each segment the scheme assigns exactly one of the paths. Formally, an -partition of the paths is given by an -tuple such that , and an -vector where . At each time instant , , path is used to predict the best path. The cumulative loss of a partition is
[TABLE]
The goal of the decision maker is to perform as well as the best time-varying path (partition), that is, to keep the normalized regret
[TABLE]
as small as possible (with high probability) for all possible outcome sequences.
In the “classical” tracking problem there is a relatively small number of “base” experts and the goal of the decision maker is to predict as well as the best “compound” expert (i.e., time-varying expert). However in our case, base experts correspond to all paths of the graph between source and destination whose number is typically exponentially large in the number of edges, and therefore we cannot directly apply the computationally efficient methods for tracking the best expert. György, Linder, and Lugosi [15] develop efficient algorithms for tracking the best expert for certain large and structured classes of base experts, including the shortest path problem. The purpose of the following algorithm is to extend the methods of [15] to the bandit setting when the forecaster only observes the losses of the edges on the chosen path.
A BANDIT ALGORITHM FOR TRACKING SHORTEST PATHS
Parameters: real numbers , , .
Initialization: Set for each , for each , and . For each round
(a)
Choose a path according to the distribution defined by
p_{\boldsymbol{i},t}=\begin{cases}(1-\gamma)\frac{\overline{w}_{\boldsymbol{i},t-1}}{\overline{W}_{t-1}}+\frac{\gamma}{|\mathcal{C}|}&\text{ if \boldsymbol{i}\in\mathcal{C};}\\ (1-\gamma)\frac{\overline{w}_{\boldsymbol{i},t-1}}{\overline{W}_{t-1}}&\text{ if \boldsymbol{i}\not\in\mathcal{C}.}\end{cases}
(b)
Compute the probability of choosing each edge as
(c)
Calculate the estimated gains
g^{\prime}_{e,t}=\begin{cases}\frac{g_{e,t}+\beta}{q_{e,t}}&\text{ if e\in\boldsymbol{I}_{t};}\\ \frac{\beta}{q_{e,t}}&\text{ otherwise.}\end{cases}
(d)
Compute the updated weights
where and is the sum of the total weights of the paths, that is,
The following performance bounds shows that the normalized regret with respect to the best time-varying path which is allowed to switch paths times is roughly of the order of .
Theorem 4
For any and parameters , , and satisfying , the performance of the algorithm defined above can be bounded, with probability at least , as
[TABLE]
In particular, choosing
[TABLE]
and
[TABLE]
we have, for all ,
[TABLE]
where
[TABLE]
The proof of the theorem is a combination of that of our Theorem 1 and Theorem 1 of [15]. We will need the following three lemmas.
Lemma 3
For any and any ,
[TABLE]
where .
Proof. The proof is a straightforward modification of the one in Herbster and Warmuth [19]. From the definitions of and (see step (d) of the algorithm) it is clear that for any ,
[TABLE]
Applying this equation iteratively for , and the definition of (step (d)) for , we obtain
[TABLE]
which implies the statement of the lemma.
Lemma 4
For any and , we have
[TABLE]
Proof. By the definition of we have
[TABLE]
This completes the proof of the lemma.
The next lemma is a simple corollary of Lemma 1.
Lemma 5
For any , , and we have
[TABLE]
Proof of Theorem 4. The theorem is proved the same way as Theorem 1 until (8), that is,
[TABLE]
Let be an arbitrary partition. Then the lower bound is obtained as
[TABLE]
(recall that denotes the path used in the last segment of the partition). Now can be rewritten in the form of the following telescoping product
[TABLE]
Therefore, applying Lemmas 3 and 4, we have
[TABLE]
Combining the lower bound with the upper bound (18), we have
[TABLE]
where we used the fact that is an arbitrary partition. After rearranging and using we get
[TABLE]
Now since , by the assumptions of the theorem and from Lemma 5 with an application of the union bound we obtain that, with probability at least ,
[TABLE]
Since and , we have
[TABLE]
This implies that, with probability at least ,
[TABLE]
To prove the second statement, let and . Optimizing the value of in the last term of (20) gives
[TABLE]
where . For we obtain
[TABLE]
where the inequality follows since for . Therefore
[TABLE]
which is the first statement of the theorem. Setting
[TABLE]
results in the second statement of the theorem, that is,
[TABLE]
Similarly to [15], the proposed algorithm has an alternative version, which is efficiently computable:
AN ALTERNATIVE BANDIT ALGORITHM FOR TRACKING SHORTEST PATHS
For , choose uniformly from the set . For ,
(a)
Draw a Bernoulli random variable with .
(b)
If , then choose uniformly from .
(c)
If ,
(c1)
choose randomly according to the distribution
\mathbb{P}\{\tau_{t}=t^{\prime}\}=\begin{cases}\frac{(1-\alpha)^{t-1}Z_{1,t-1}}{W_{t-1}}&\text{for t^{\prime}=1}\\ \frac{\alpha(1-\alpha)^{t-t^{\prime}}W_{t^{\prime}}Z_{t^{\prime},t-1}}{NW_{t}}&\text{for t^{\prime}=2,\ldots,t}\end{cases}
where for , and ;
(c2)
given , choose randomly according to the probabilities
\mathbb{P}\{I_{t}=\boldsymbol{i}|\tau_{t}=t^{\prime}\}=\begin{cases}\frac{e^{\eta G^{\prime}_{\boldsymbol{i},[t^{\prime},t-1]}}}{Z_{t^{\prime},t-1}}&\text{for t^{\prime}=1,\ldots,t-1}\\ \frac{1}{N}&\text{for t^{\prime}=t}.\end{cases}
In a way completely analogous to [15], in this alternative formulation of the algorithm one can compute the probabilities and the normalization factors efficiently. Using the fact that the baseline bandit algorithm for shortest paths has an time complexity by Theorem 2, it follows from Theorem 3 of [15] that the time complexity of the alternative bandit algorithm for tracking the shortest path is .
7 An algorithm for the restricted multi-armed bandit problem
In this section we consider the situation where the decision maker receives information only about the performance of the whole chosen path, but the individual edge losses are not available. That is, the forecaster has access to the sum of losses over the chosen path but not to the losses of the edges belonging to .
This is the problem formulation considered by McMahan and Blum [25] and Awerbuch and Kleinberg [4]. McMahan and Blum provided a relatively simple algorithm whose regret is at most of the order of , while Awerbuch and Kleinberg gave a more complex algorithm to achieve regret. In this section we combine the strengths of these papers, and propose a simple algorithm with regret at most of the order of . Moreover, our bound holds with high probability, while the above-mentioned papers prove bounds for the expected regret only. The proposed algorithm uses ideas very similar to those of McMahan and Blum [25]. The algorithm alternates between choosing a path from a “basis” to obtain unbiased estimates of the loss (exploration step), and choosing a path according to exponential weighting based on these estimates.
A simple way to describe a path is a binary row vector with components which are indexed by the edges of the graph such that, for each , the th entry of the vector is if and [math] otherwise. With a slight abuse of notation we will also denote by the binary row vector representing path . In the previous sections, where the loss of each edge along the chosen path is available to the decision maker, the complexity stemming from the large number of paths was reduced by representing all information in terms of the edges, as the set of edges spans the set of paths. That is, the vector corresponding to a given path can be expressed as the linear combination of the unit vectors associated with the edges (the th component of the unit vector representing edge is , while the other components are [math]). While the losses corresponding to such a spanning set are not observable in the restricted setting of this section, one can choose a subset of that forms a basis, that is, a collection of paths which are linearly independent and each path in can be expressed as a linear combination of the paths in the basis. We denote by the matrix whose rows represent the paths in the basis. Note that is equal to the maximum number of linearly independent vectors in , so .
Let denote the (column) vector of the edge losses at time , and let be a -dimensional column vector whose components are the losses of the paths in the basis at time . If are the coefficients in the linear combination of the basis paths expressing path , that is, , then the loss of path at time is given by
[TABLE]
where denotes the standard inner product in . In the algorithm we obtain estimates of the losses of the basis paths and use (21) to estimate the loss of any as
[TABLE]
It is algorithmically advantageous to calculate the estimated path losses from an intermediate estimate of the individual edge losses. Let denote the the Moore-Penrose inverse of defined by , where denotes the transpose of and is invertible since the rows of are linearly independent. (Note that if ). Then letting and
[TABLE]
it is easy to see that in (22) can be obtained as , or equivalently
[TABLE]
This form of the path losses allows for an efficient implementation of exponential weighting via dynamic programming [28].
To analyze the algorithm we need an upper bound on the magnitude of the coefficients . For this, we invoke the definition of a barycentric spanner from [4]: the basis is called a -barycentric spanner if for all and . Awerbuch and Kleinberg [4] show that a -barycentric spanner exists if is a square matrix (i.e., ) and give a low-complexity algorithm which finds a -barycentric spanner for . We use their technique to show that a 1-barycentric spanner also exists in case of a non-square , when the basis is chosen to maximize the absolute value of the determinant of . As before, denotes the maximum number of linearly independent vectors (paths) in .
Lemma 6
For a directed acyclic graph, the set of paths between two dedicated nodes has a -barycentric spanner. Moreover, let be a matrix with rows from such that . If is the matrix obtained from by replacing its th row by and
[TABLE]
for all and , then is a -barycentric spanner.
Proof. Let be a basis of with rows that maximizes . Then, for any path , we have for some coefficients . Now for the matrix we have
[TABLE]
where last equality follows by the same argument the penultimate equality was obtained. Repeating the same argument for , we obtain
[TABLE]
Thus the maximal property of implies for all . The second statement follows trivially from (23) and (24).
Awerbuch and Kleinberg [4] also present an iterative algorithm to find a -barycentric spanner if is a square matrix. Starting from the identity matrix, their algorithm replaces a row of the matrix in each step by maximizing the determinant with respect to the given row. This is done by calling an oracle function, and it is shown that the oracle is called times. In case is not a square matrix, the algorithm carries over if we have access to an alternative oracle that can maximize : Starting from an arbitrary basis we can iteratively replace one row in each step, using the oracle, to maximize the determinant until (23) is satisfied for all and . By Lemma 6, this results in a -barycentric spanner. Similarly to [4], it can be shown that the oracle is called times for .
For simplicity (to avoid carrying the constant ), assume that we have a 2-barycentric spanner . Based on the ideas of label efficient prediction, the next algorithm gives a simple solution to the restricted shortest path problem. The algorithm is very similar to that of the algorithm in the label efficient case, but here we cannot estimate the edge losses directly. Therefore, we query the loss of a (random) basis vector from time to time, and create unbiased estimates of the losses of basis paths , which are then transformed into edge-loss estimates.
A BANDIT ALGORITHM FOR THE RESTRICTED SHORTEST PATH PROBLEM
Parameters: .
Initialization: Set for each , for each , . Fix a basis , which is a 2-barycentric spanner. For each round
(a)
Draw a Bernoulli random variable such that ;
(b)
If , then choose the path uniformly from the basis . If , then choose according to the distribution , defined by
(c)
Calculate the estimated loss of all edges according to
where , and is the vector of the estimated losses
for .
(d)
Compute the updated weights
and the sum of the total weights of the paths
The performance of the algorithm is analyzed in the next theorem. The proof follows the argument of Cesa-Bianchi et al. [9], but we also have to deal with some additional technical difficulties. Note that in the theorem we do not assume that all paths between and have equal length.
Theorem 5
Let denote the length of the longest path in the graph. For any , parameters and satisfying , and , the performance of the algorithm defined above can be bounded, with probability at least , as
[TABLE]
In particular, choosing
[TABLE]
we obtain
[TABLE]
The theorem is proved using the following two lemmas. The first one is an easy consequence of Bernstein’s inequality:
Lemma 7
Under the assumptions of Theorem 5, the probability that the algorithm queries the basis more than times is at most .
Using the estimated loss of a path given in (22), we can estimate the cumulative loss of up to time as
[TABLE]
The next lemma demonstrates the quality of these estimates.
Lemma 8
Let and assume . For any , with probability at least ,
[TABLE]
Furthermore, with probability at least ,
[TABLE]
Proof. We may write
[TABLE]
Note that for any , , is a martingale difference sequence with respect to , as . Also,
[TABLE]
and
[TABLE]
where the last inequalities in both cases follow from the fact that is a -barycentric spanner. Then, using Bernstein’s inequality for martingale differences (Lemma 9), we have, for any fixed ,
[TABLE]
where we used (26), (27) and the assumption of the lemma on . The proof of the first statement is finished with an application of the union bound and its combination with (25).
For the second statement we use a similar argument, that is,
[TABLE]
Now applying Lemma 9 for a fixed we get
[TABLE]
because of and . The proof is completed by applying the union bound to (30) and combining the result with (29).
Proof of Theorem 5. Similarly to earlier proofs, we follow the evolution of the term . In the same way as we obtained (5) and (7), we have
[TABLE]
and
[TABLE]
Combining these bounds, we obtain
[TABLE]
because . Applying the results of Lemma 8 and the union bound, we have, with probability ,
[TABLE]
Introduce the sets
[TABLE]
of “exploitation” and “exploration” steps, respectively. Then, by the Hoeffding-Azuma inequality [21] we obtain that, with probability at least ,
[TABLE]
Note that for the exploration steps , as the algorithm plays according to a uniform distribution instead of , we can only use the trivial lower bound zero on the losses, that is,
[TABLE]
The last two inequalities imply
[TABLE]
Then, by (31), (32) and Lemma 7 we obtain, with probability at least ,
[TABLE]
where we used and . Substituting the values of and gives
[TABLE]
where we used , , , and (from the assumptions of the theorem).
8 Simulation results
To further investigate our new algorithms, we have conducted some simple simulations. As the main motivation of this work is to improve earlier algorithms in case the number of paths is exponentially large in the number of edges, we tested the algorithms on the small graph shown in Figure 1 (b), which has one of the simplest structures with exponentially many (namely ) paths.
The losses on the edges were generated by a sequence of independent and uniform random variables, with values from on the upper edges, and from on the lower edges, resulting in a (long-term) optimal path consisting of the upper edges. We ran the tests for steps, with confidence value . To establish baseline performance, we also tested the EXP3 algorithm of Auer et al. [1] (note that this algorithm does not need edge losses, only the loss of the chosen path). For the version of our bandit algorithm that is informed of the individual edge losses (edge-bandit), we used the simple 2-element cover set of the paths consisting of the upper and lower edges, respectively (other 2-element cover sets give similar performance). For our restricted shortest path algorithm (path-bandit) the basis was used, where (resp. ) in the th position denotes the upper (resp. lower) edge connecting and . In this example the performance of the algorithm appeared to be independent of the actual choice of the basis; however, in general we do not expect this behavior. Two versions of the algorithm of Awerbuch and Kleinberg [4] were also simulated. With its original parameter setting (AwKl), the algorithm did not perform well. However, after optimizing its parameters off-line (AwKl tuned), substantially better performance was achieved. The normalized regret of the above algorithms, averaged over 30 runs, as well as the regret of the fixed paths in the graph are shown in Figure 2.
Although all algorithms showed better performance than the bound for the edge-bandit algorithm, the latter showed the expected superior performance in the simulations. Furthermore, our algorithm for the restricted shortest path problem outperformed Awerbuch and Kleinberg’s (AwKl) algorithm, while being inferior to its off-line tuned version (AwKl tuned). It must be noted that similar parameter optimization did not improve the performance of our path-bandit algorithm, which showed robust behavior with respect to parameter tuning.
9 Conclusions
We considered different versions of the on-line shortest path problem with limited feedback. These problems are motivated by realistic scenarios, such as routing in communication networks, where the vertices do not have all the information about the state of the network. We have addressed the problem in the adversarial setting where the edge losses may vary in an arbitrary way; in particular, they may depend on previous routing decisions of the algorithm. Although this assumption may neglect natural correlation in the loss sequence, it suits applications in mobile ad-hoc networks, where the network topology changes dynamically in time, and also in certain secure networks that has to be able to handle denial of service attacks.
Efficient algorithms have been provided for the multi-armed bandit setting and in a combined label efficient multi-armed bandit setting, provided the individual edge losses along the chosen path are revealed to the algorithms. The normalized regrets of the algorithms, compared to the performance of the best fixed path, converge to zero at an rate as the time horizon grows to infinity, and increases only polynomially in the number of edges (and vertices) of the graph. Earlier methods for the multi-armed bandit problem either do not have the right convergence rate, or their regret increase exponentially in the number of edges for typical graphs. The algorithm has also been extended so that it can compete with time varying paths, that is, to handle situations when the best path can change from time to time (for consistency, the number of changes must be sublinear in ).
In the restricted version of the shortest path problem, where only the losses of the whole paths are revealed, an algorithm with a worse normalized regret was provided. This algorithm has comparable performance to that of the best earlier algorithm for this problem [4], however, our algorithm is significantly simpler. Simulation results are also given to assess the practical performance and compare it to the theoretical bounds as well as other competing algorithms.
It should be noted that the results are not entirely satisfactory in the restricted version of the problem, as it remains an open question whether the regret can be achieved without the exponential dependence on the size of the graph. Although we expect that this is the case, we have not been able to construct an algorithm with such a proven performance bound.
10 Appendix
Lemma 9
(Bernstein’s inequality for martingale differences [10].) Let be a martingale difference sequence such that with probability one (). Assume that, for all ,
[TABLE]
Then, for all ,
[TABLE]
and therefore
[TABLE]
The reference list from the paper itself. Each links out to its DOI / PubMed record.
- 1[1] P. Auer, N. Cesa-Bianchi, Y. Freund, and R. Schapire. The non-stochastic multi-armed bandit problem. SIAM Journal on Computing , 32(1):48–77, 2002.
- 2[2] P. Auer and M. K. Warmuth, “Tracking the best disjunction,” Machine Learning , vol. 32, no. 2, pp. 127–150, 1998.
- 3[3] B. Awerbuch, D. Holmer, H. Rubens, and R. Kleinberg. Provably competitive adaptive routing. In Proceedings of IEEE INFOCOM 2005 , volume 1, pages 631–641, March 2005.
- 4[4] B. Awerbuch and R. D. Kleinberg. Adaptive routing with end-to-end feedback: distributed learning and geometric approaches. In Proceedings of the 36th Annual ACM Symposium on the Theory of Computing, STOC 2004 , pages 45–53, Chicago, IL, USA, Jun. 2004. ACM Press.
- 5[5] D. Blackwell. An analog of the minimax theorem for vector payoffs. Pacific Journal of Mathematics , 6:1–8, 1956.
- 6[6] O. Bousquet and M. K. Warmuth. Tracking a small set of experts by mixing past posteriors. Journal of Machine Learning Research , 3:363–396, Nov. 2002.
- 7[7] N. Cesa-Bianchi, Y. Freund, D. P. Helmbold, D. Haussler, R. Schapire, and M. K. Warmuth. How to use expert advice. Journal of the ACM , 44(3):427–485, 1997.
- 8[8] N. Cesa-Bianchi and G. Lugosi. Prediction, Learning, and Games . Cambridge University Press, Cambridge, 2006.